How to Actually Pull Useful Data From Google Trends Without Wasting a Day
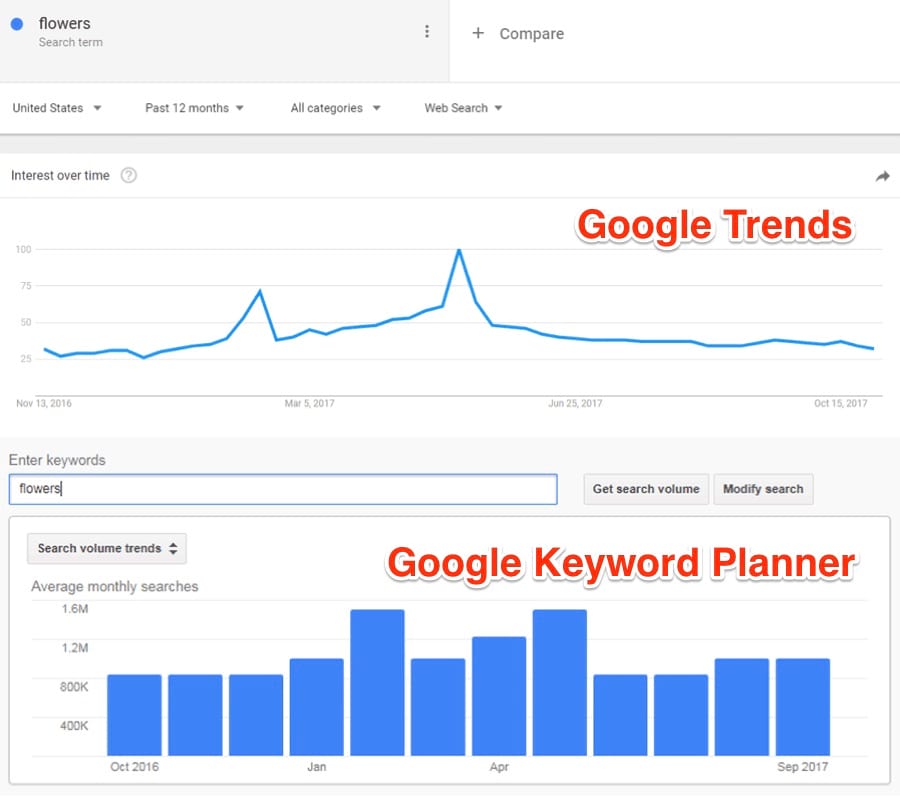
Google Trends is free. That is also its biggest problem. The interface looks simple, but the data comes with a lot of caveats that most people ignore until they build a strategy on top of it. I spent about three weeks last year trying to correlate trends data with actual search volume for a client in the home renovation space. It did not go well at first. The numbers are relative, not absolute. A spike to 100 does not mean one hundred searches. It means the highest point in your selected window. The process itself is straightforward once you understand what you are looking at. You go to trends.google.com, type in a term, and set your filters. The tricky part is the filters. Most people leave the default categories and time ranges alone. That guarantees garbage output if your topic is niche. If you are researching something like sustainable packaging, keeping the default category of "All categories" dilutes the signal with people who searched it in completely unrelated contexts. You need to narrow it down.
Getting Started With Ideas Statistics On Google Trends
Start by entering your seed keyword. Let us say you picked "electric vehicle charging stations." After you hit search, Google Trends shows you a relative interest graph over time. Below that, you get related queries and related topics. This is where the ideas statistics live. The related queries section breaks down into top and rising. Top shows the most searched terms. Rising shows the ones with the biggest percentage increase. I usually set the time range to the past twelve months minimum. Anything shorter gives you noise from recent news cycles. If you are doing seasonal analysis, go back five years. Google Trends lets you go as far back as 2004, though data before roughly 2012 gets sketchy because the dataset was smaller. I skip the early years unless I specifically need historical context for a long-running term. One thing beginners miss is the geo-targeting detail. If you select United States as your location, the breakdown will show you states. Within each state, the data is aggregated. You cannot see city-level trends unless you narrow your search to that metro area. I ran into this exact problem when a client wanted to compare interest in tiny homes between Austin, Nashville, and Boise. Selecting those cities individually in the location field gave me separate trend lines. But the sample size for individual cities drops fast, and Google sometimes suppresses data when queries fall below a threshold. My workaround was to expand the region to the state level, then cross-reference with another tool for city-specific data. Not ideal, but it got the job done.
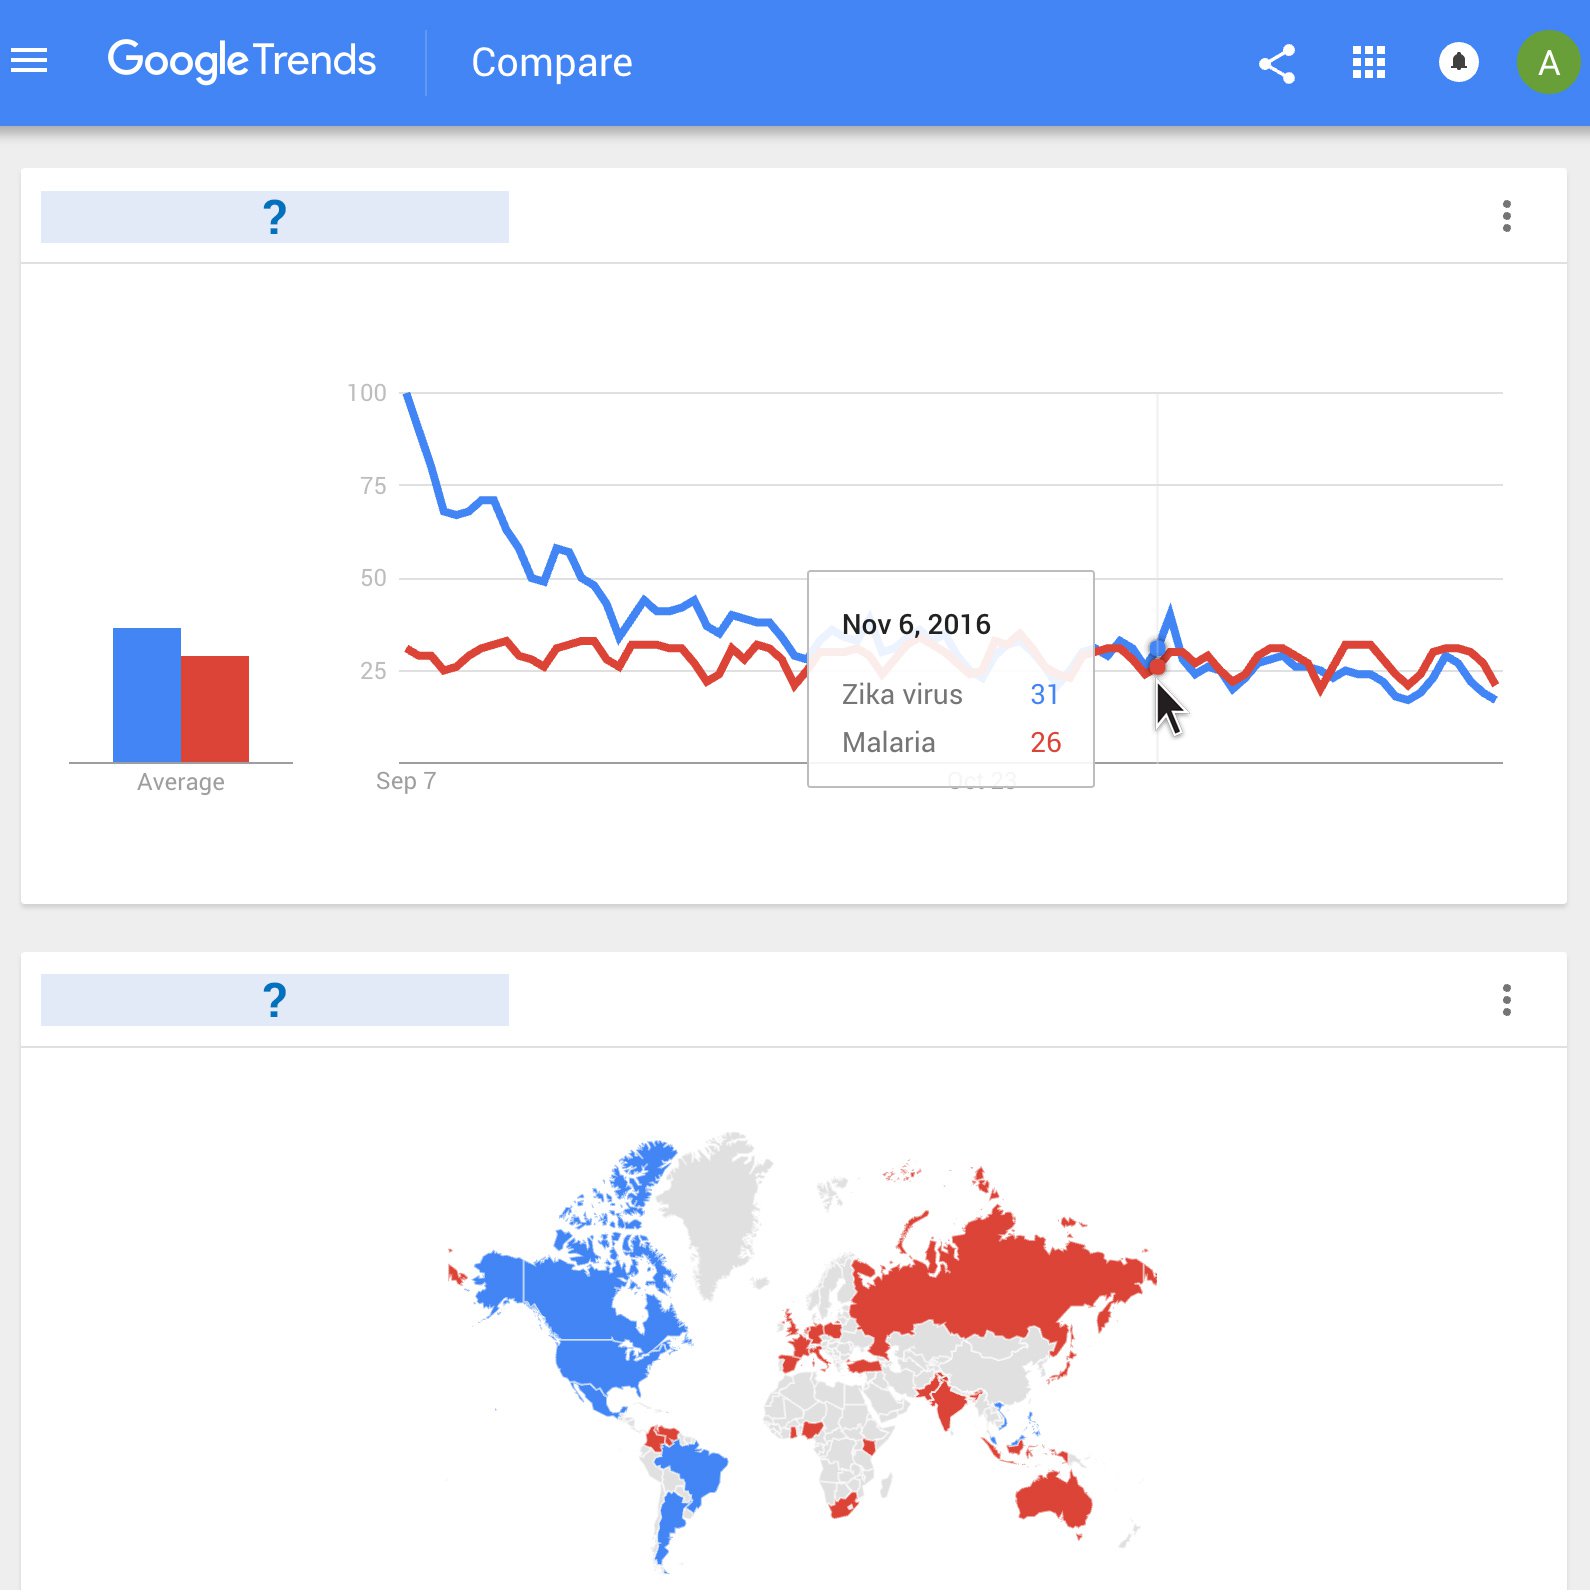
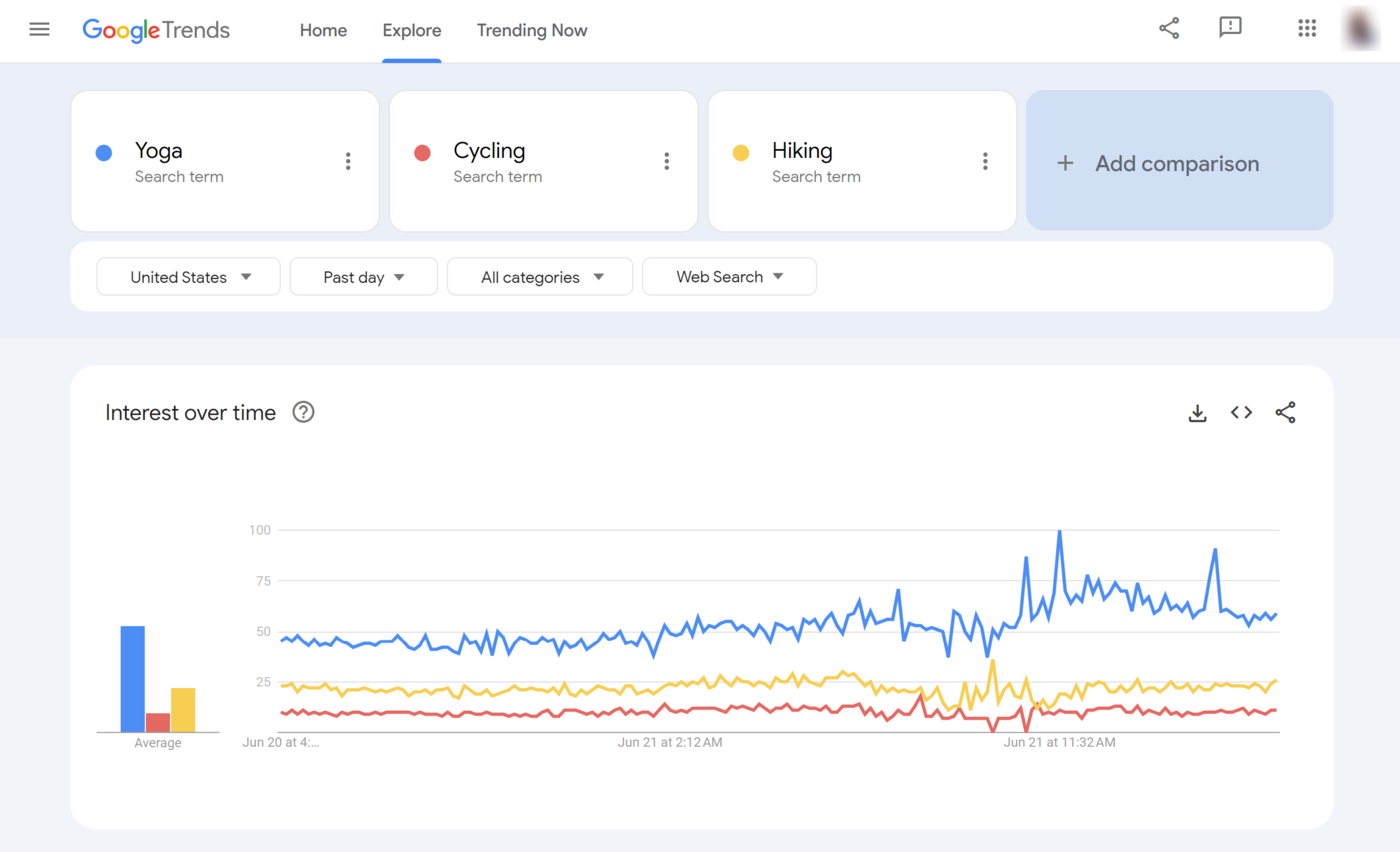
Another overlooked feature is the comparison function. You can stack up to five search terms and see how they perform against each other over the same window. I used this to compare "remote work," "work from home," and "telecommuting" across the last decade. The shifting dominance between those terms tells you something about language evolution that raw search volume tools do not capture. Google Trends normalizes each term independently, so even if one term has ten times the absolute searches, the normalized line makes them comparable. This is useful for tracking sentiment shifts around a topic, but it can also mislead you if you interpret the graph as actual popularity. The rising queries metric deserves a closer look. It is calculated as a percentage breakout from the previous period. A label of Breakout means the term grew by more than 5000 percent. That sounds impressive, but it also means the absolute volume was tiny to begin with. A query going from two searches a month to one hundred is still Breakout, but it is not actionable for anything beyond niche content ideas. I always filter the rising queries by minimum search volume when possible. Unfortunately, Google Trends does not give you the raw numbers. You have to infer the real impact by looking at the absolute interest score on the main graph for that related term. Here is another quirk that costs people time. The "News" tab filters results to news articles only. If you are tracking evergreen topics, you probably do not want this. But if you are researching a viral event or breaking industry story, it isolates the signal from the steady-state background noise. I use this when a competitor launches a product and I need to see how the conversation evolved in real time rather than mixed with years of unrelated queries.
Get the Full Details
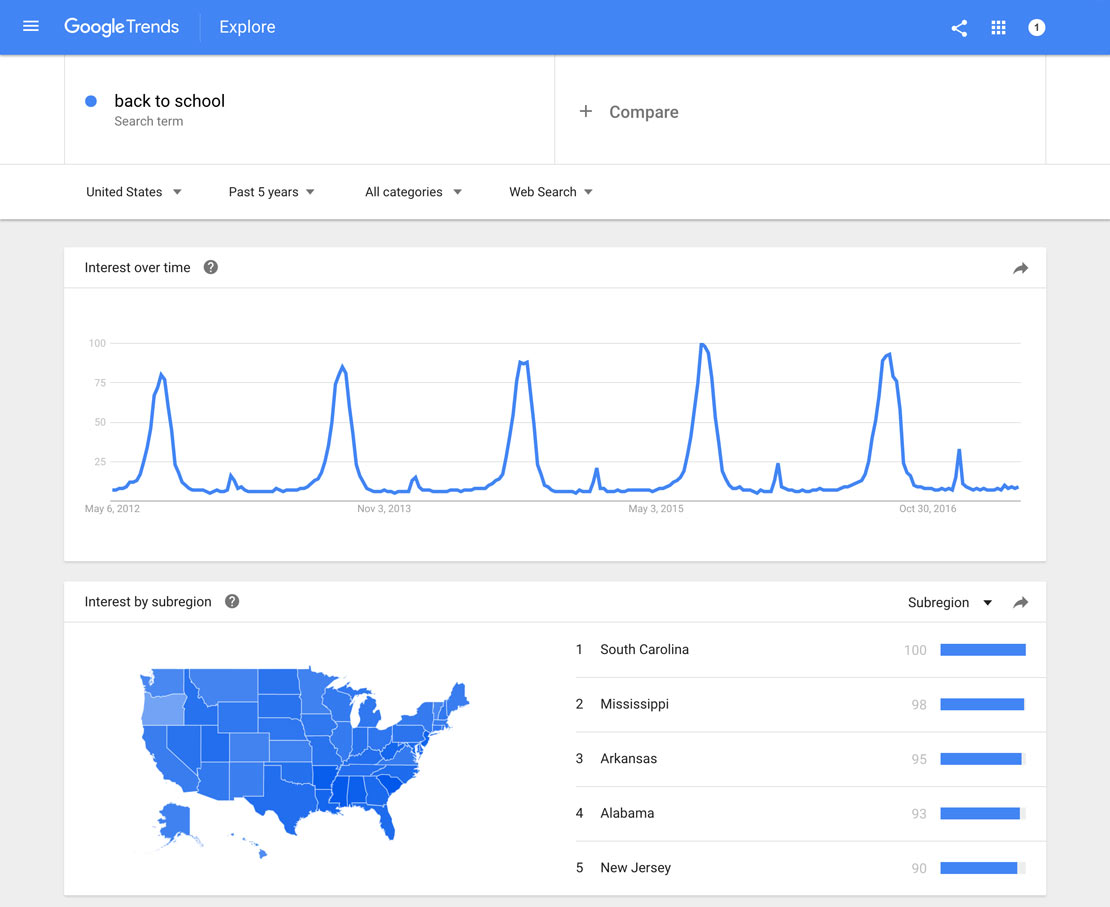
Exporting data is another area where expectations clash with reality. Google Trends does not provide a direct CSV download in the free interface. You have to screenshot or copy the visible data, which is tedious if you are comparing multiple terms. I wrote a small Python script using Selenium that scrapes the related queries table and exports it to a spreadsheet. It takes about ten minutes to set up and saves me roughly forty minutes per research session. If you do not code, there are browser extensions like "Trends Export" that claim to handle this, but they tend to break when Google updates their front end. The script approach is more reliable long term because you control the scraping logic. There is a significant limitation people rarely account for. Google Trends data is sampled. They take a subset of searches, not the full dataset. This means the relative scores are approximations. For broad terms like "shoes" or "Amazon," the sampling error is small because the volume is massive. For very specific long-tail keywords, the sample can be thin enough that the trend line jumps around unpredictably. I learned this the hard way when a client was tracking a very specific technical term in the renewable energy sector. The trend looked volatile week to week. After cross-checking with Google Ads Keyword Planner, I found the underlying absolute volume was consistently low and stable. The volatility was an artifact of the sampling, not actual interest swings. Another practical issue is the lag in data freshness. Google Trends updates are not real time. The most recent data point is usually one to three days behind the current date. If you are tracking a developing story and need today's numbers, this tool will not serve you. I use it for weekly or monthly reporting cycles, not day-to-day monitoring. For near real-time tracking, I rely on Google Search Console or third-party platforms that pull from different data sources.
When I run a full research cycle, I typically spend about twenty minutes setting up the initial queries and filters, another fifteen minutes reviewing the related topics and queries, and maybe ten minutes compiling the findings into a report. Compared to pulling data from paid platforms that charge per report, the time savings are real even accounting for the manual work. The tradeoff is accuracy and granularity. You are getting a directional tool, not a precision instrument. If you need harder numbers, you can combine Google Trends with Google Ads data. The Ads platform gives you actual click counts and impression shares. Using Trends to identify which terms are gaining momentum and then validating those with Ads data gives you a more complete picture. I usually run both in parallel. Trends tells me what to investigate. Ads tells me what to bid on. They complement each other well, though the integration is manual on your end since Google does not offer a native bridge between the two. The bottom line is that Ideas Statistics On Google Trends works best when you treat it as a discovery and validation tool rather than a measurement tool. It answers "is something growing or shrinking" and "what are people searching alongside this" with reasonable reliability. It does not answer "how many people are actually searching this" or "what is the exact search volume this week." Knowing that boundary saves you from building plans on shaky ground.