How to Actually Use an Identifying Bias Worksheet Without Wasting Everyone's Time
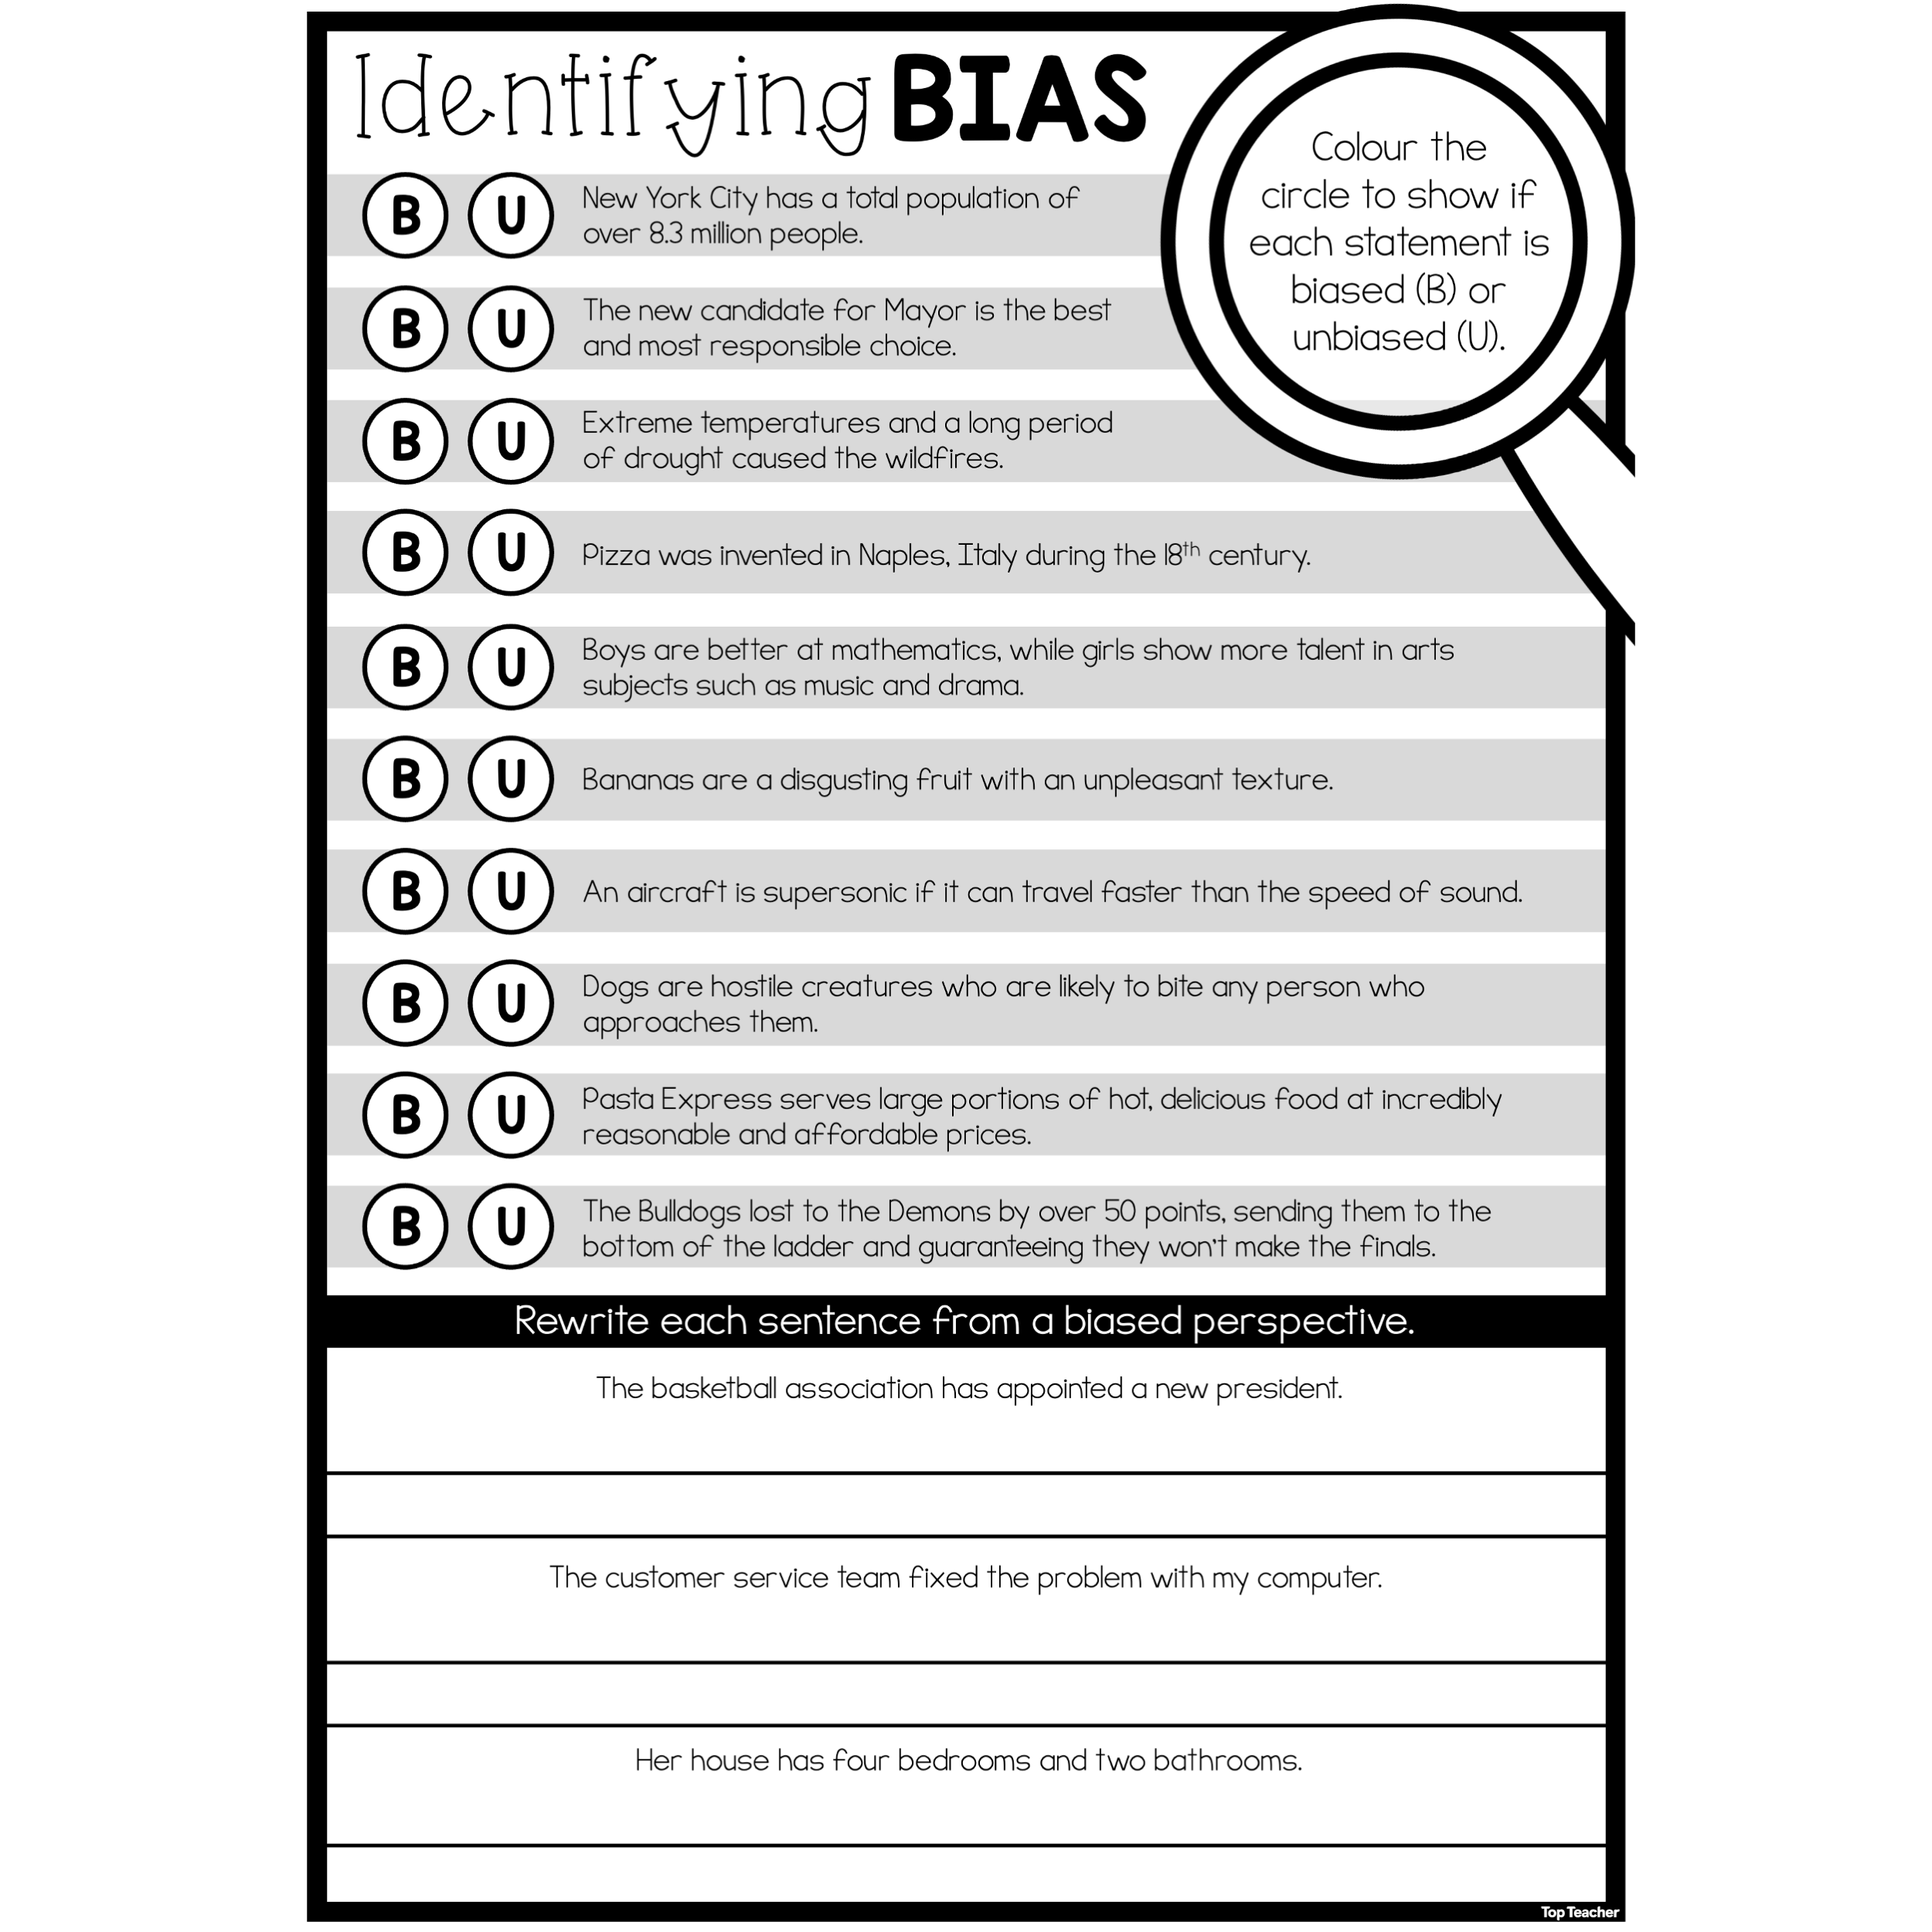
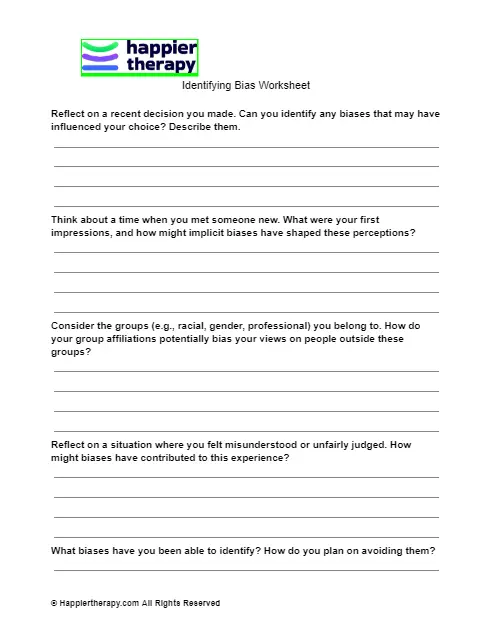
Most people I see using these worksheets treat them like a checkbox exercise. They fill in the header fields, scribble a couple of generic notes, and call it audit-compliant. That's why the process usually takes three hours for a team of four and produces exactly nothing you could defend in a review meeting. The way this should work is a lot more tedious than the templates suggest. You sit down with your dataset or your model pipeline and you go line by line through each dimension, writing down the actual evidence, not your assumptions. An Identifying Bias Worksheet is just a structured form that forces you to state your reasoning explicitly so someone else can poke holes in it. That's it. The value isn't in filling it out quickly; it's in making sure the form catches things you would have otherwise hand-waved away. I ran into a specific case last year where our bias audit looked clean across the board until I cross-referenced column one of the worksheet with the actual sampling methodology document. The training data had a 40% overrepresentation of one demographic group, but the sampling sheet used a classification system that merged two subgroups together. Our worksheet had flagged "demographic representation" as adequate because we were looking at the merged categories. The fix was to add a cross-reference column to the Identifying Bias Worksheet that required you to cite the exact field mapping you used for each bias dimension. That one change caught three separate issues we'd walked past in previous audits.
Where to Download a Working Identifying Bias Worksheet
There are a few sources that actually produce usable templates rather than decorative ones. The NIST AI Risk Management Framework has a set of audit artifacts you can adapt. The EU AI Office also publishes supplementary guidance with template structures. For a standalone file you can open and modify immediately, I keep a Google Sheets version that I reference internally, and I'm putting a copy linked below. It's rough around the edges, but it has the cross-reference column I mentioned and the edge-case handling for mixed-data-source audits that most free templates skip. Identifying Bias Worksheet (Google Sheets)
What the Worksheet Actually Does in Practice
Here's how the structure works when you use it properly. Each row targets one bias category. The columns ask for: the specific data or model component being examined, the bias type you're checking for, the evidence you found, the source of that evidence, and the severity rating with justification. The severity rating is the part most people get wrong. It shouldn't be a gut feeling. You assign it based on measurable impact thresholds, not on whether the bias "feels significant." I use a three-tier severity scale with explicit criteria. High severity means the bias directly affects decision outcomes for a protected or vulnerable group and the direction of the effect is quantifiable. Medium severity means the bias creates uneven treatment across groups but doesn't cleanly map to a downstream decision. Low severity means there's a pattern worth noting but no clear mechanism connecting it to harm. These thresholds are boring and debatable, but having them written down prevents the team from arguing about whether something matters in every review cycle. Counter-intuitive insight that took me two years to learn: the biggest source of bias in my work wasn't in the features or the labels. It was in the sampling frame. The data existed, the annotations were careful, and the model performed evenly across groups. But the population the data actually represented was narrower than the population the model was being deployed against. The Identifying Bias Worksheet caught this, but only after I added a dedicated section for sampling-frame validity that required a citation of the deployment context versus the collection context. Most templates don't include this because they assume your data and your deployment target are the same thing. They aren't.
Get the Full Details

Common Pitfalls That Make the Worksheet Useless
The most destructive mistake is letting one person fill out the entire thing. Bias identification requires at least two perspectives on the data pipeline. If the same person who built the model fills out the worksheet alone, they will either miss structural issues or interpret evidence through their own framework without challenge. I require at least two reviewers for each worksheet, and they work independently before comparing notes. This usually doubles the time required, but it cuts false confidence by roughly the same amount. Another trap is conflating correlation with bias. Just because two groups show different outcome distributions doesn't mean bias exists. It might mean the underlying population differs. The worksheet forces you to separate "difference in outcomes" from "evidence of systematic unfairness." I've seen teams flag harmless distributional differences as bias and then spend weeks trying to fix something that wasn't broken. The worksheet column labeled "mechanism" is where you document the causal link, or admit you don't have one yet. The worksheet also doesn't help when your data simply doesn't exist for certain groups. If a demographic segment is entirely absent from your dataset, no amount of worksheet discipline will generate the information you need. In those cases, the output should be a documented gap, not a false sense of coverage. I treat missing-data bias as high severity by default because the risk of deploying against an unseen population is unquantifiable, and unquantifiable risk is the kind that causes problems later.
When to Stop Using This Approach
An Identifying Bias Worksheet is not a comprehensive fairness evaluation. It's a documentation and discovery tool. It won't replace statistical parity tests, equal opportunity difference calculations, or individual fairness checks. It also doesn't handle intersectional bias well unless you build that into the structure yourself, which most standard templates don't. If your deployment involves multiple protected attributes interacting in non-linear ways, you'll need to supplement the worksheet with targeted analytical methods rather than expecting the form to surface those patterns on its own. For quick internal reviews where the stakes are low, the worksheet might be overkill. A lightweight checklist takes five minutes and covers the obvious cases. The structured worksheet becomes necessary when you're preparing documentation for external review, regulatory compliance, or any situation where someone else will hold you accountable for what you checked and what you missed. The worksheet I linked below includes a severity criteria reference and the sampling-frame cross-reference column. It's designed for datasets between fifty thousand and two million records. Beyond that size, the row-by-row manual approach becomes impractical, and you'd need to pair it with automated bias scanning tools rather than relying on the form alone.
Identifying Bias Worksheet (Google Sheets)