Identity Proofing Is A Messy Pipeline, Not A Single Tool
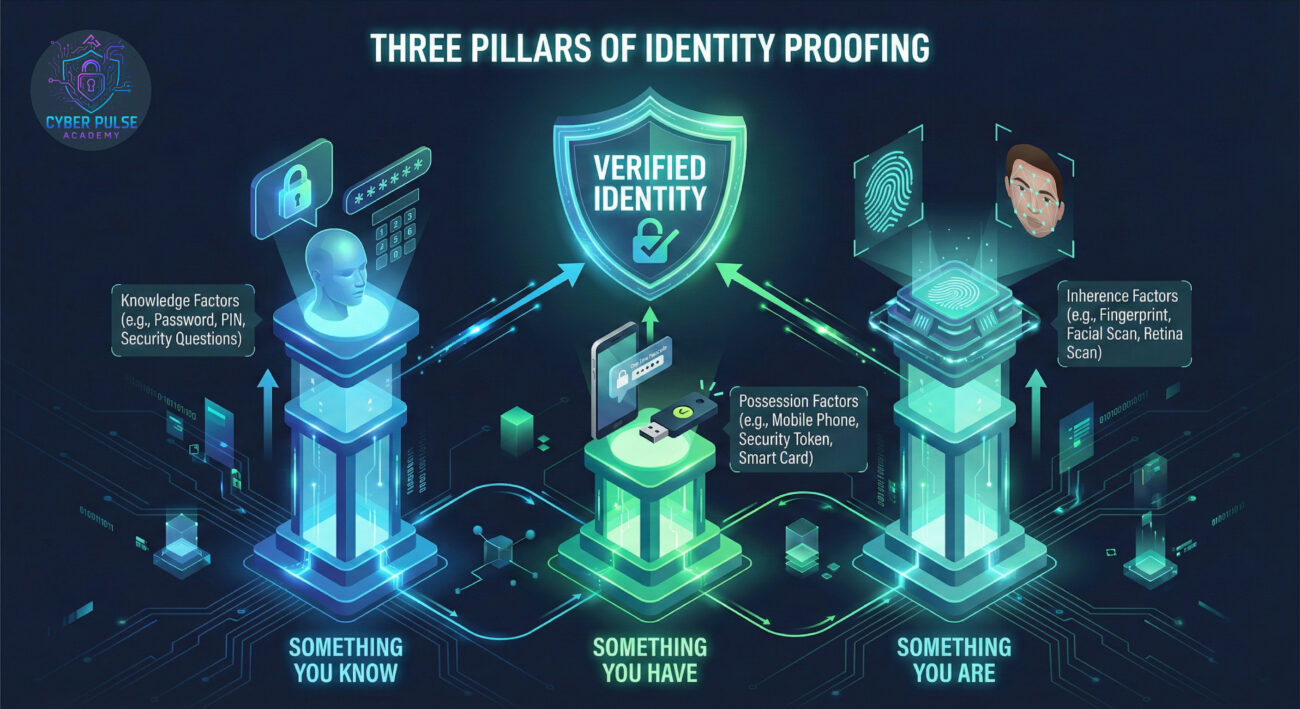
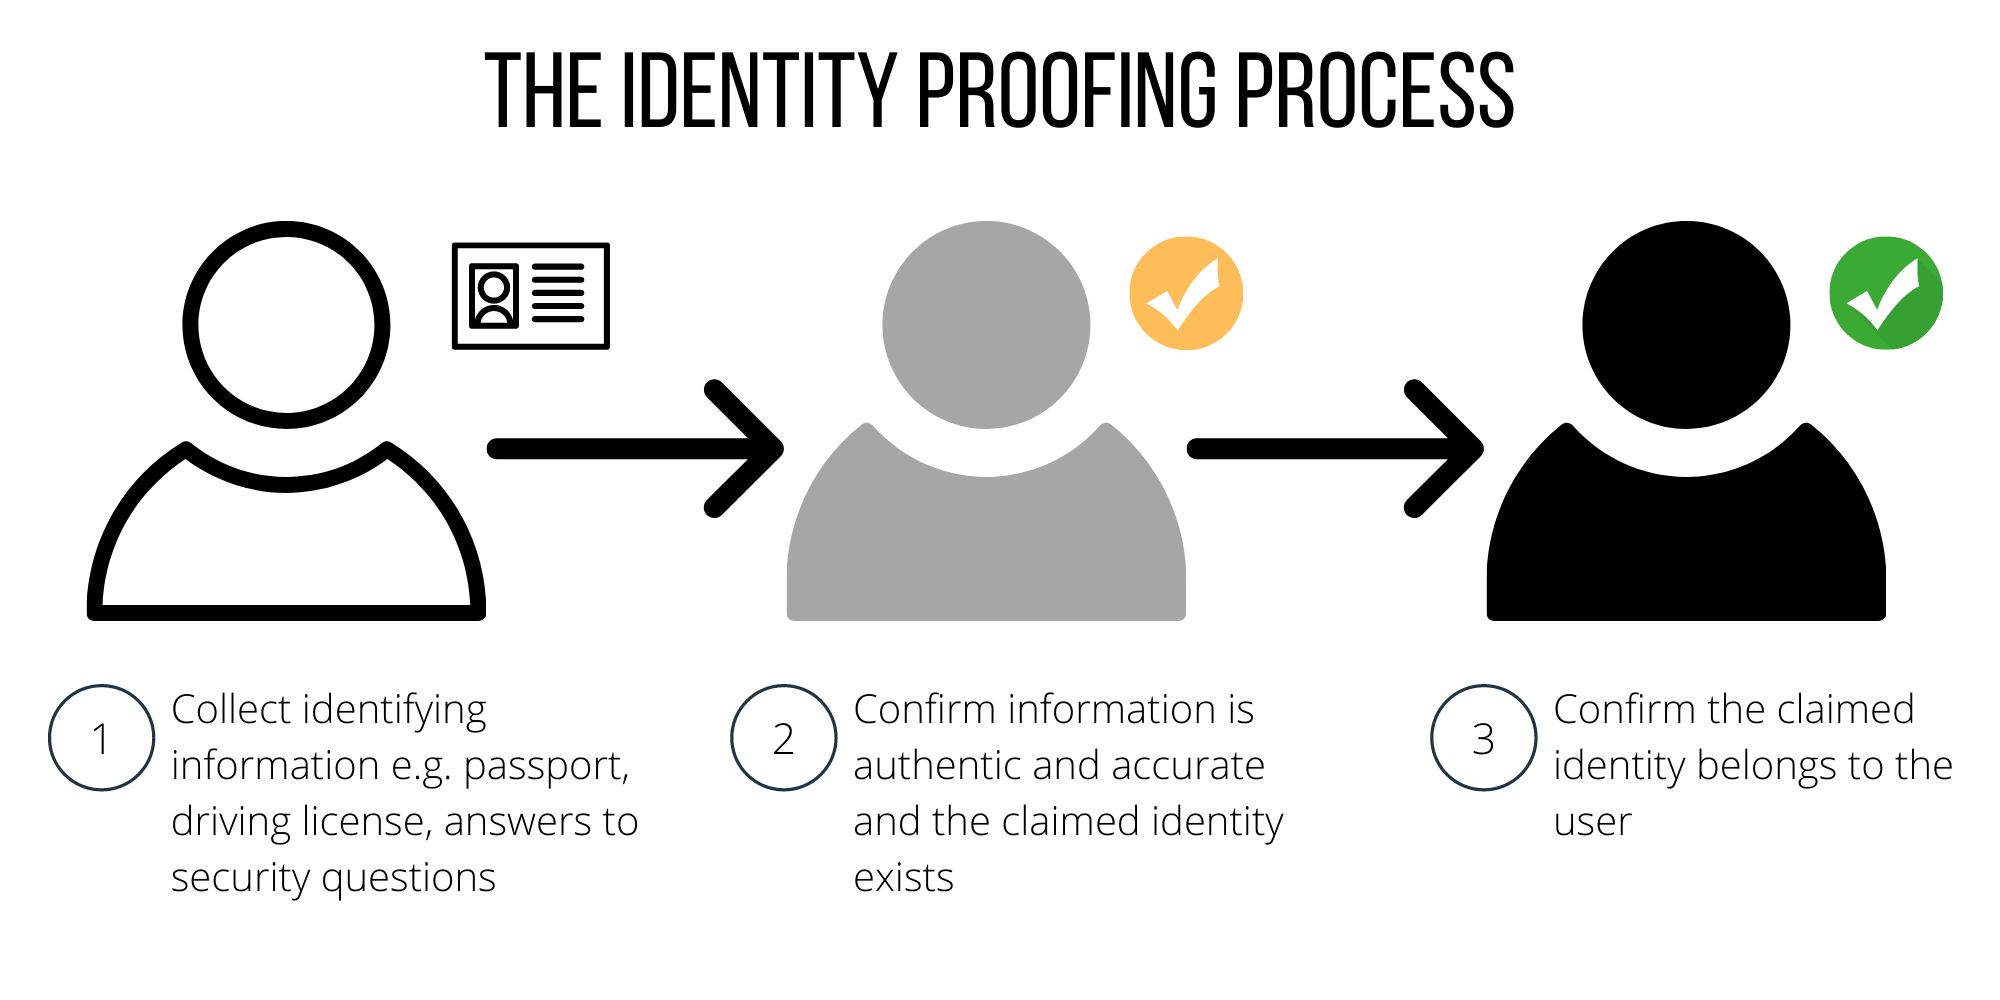
Most people think identity proofing is one button you press and a yes/no drops out. It isn't. It's a sequence of independent checks that each have their own failure modes, and they compound. If you're building or buying into a workflow, you need to understand where the pipeline actually breaks. The basic flow goes like this. A subject presents a government-issued document and a live biometric sample — usually a selfie. You extract the document data using OCR or a structured field parser. You compare the portrait on the document against the live capture. You run document-level authenticity checks. You run database or watchlist queries. You return a risk score or a decision. Each step can pass, fail, or fall into a gray zone that requires manual review.
Identity Proofing And Credential Analysis: What Actually Happens Under The Hood
Credential analysis sits at the document stage. You're not just reading text off an ID. You're checking for signs of alteration. That includes looking at the MRZ (machine-readable zone) on passports and ID cards and validating it against the printed fields. A mismatch between MRZ and optical character recognition output is one of the most common fraud signals, and it's the cheapest check in the pipeline. Then there are visual security features. Holograms, microtext, ultraviolet ink patterns, guilloché patterns, ghost images. Modern systems use computer vision models trained on these features. Older systems used rule-based image processing. Both work, and both have blind spots. Rule-based systems miss sophisticated forgeries. ML models can be fooled by high-quality photos of real documents held up to a camera, which brings me to presentation attack detection. PAD, or liveness detection, is where most vendors oversell their product. There are two types. Active liveness requires the subject to perform actions — blink, turn head, say a number. Passive liveness uses image statistics and deep learning to detect screen artifacts, moiré patterns, and other replay signals. Passive is faster and more user-friendly but less reliable against determined attackers with high-resolution displays. I've seen passive-only pipelines flagged as pass by printed photos of real IDs in controlled lab conditions. In the wild, it's worse because people experiment.
Database checks are the other half. You query internal databases, government records, credit bureaus, watchlists, and electoral rolls depending on your jurisdiction. In the US, you might pull from SSN validators and address history. In the EU, national ID schemes vary wildly. Some countries have real-time verification APIs. Most don't. I worked on a project where we were proofing German ID cards and the local registry only updated data in weekly batch files. That means someone can change their address and your verification query won't reflect it for six days. There's no workaround other than flagging that latency window as a risk factor and requiring re-verification for high-value actions.
Get the Full Details
Building A Practical Workflow
Start by defining your assurance level. IDNA (Identity Document Number Assurance) and NIST SP 800-62-2 are the frameworks most people reference. NIST AL1 is basic identity verification with minimal checks. AL2 requires documentary and non-documentary evidence. AL3 is the highest, used for federal access. Your workflow should match the assurance tier you're targeting. Don't buy a Tier 3 solution for a Tier 1 use case. The cost difference is significant and the false reject rate climbs with each added step. For a standard commercial KYC flow targeting AL2 equivalent, here's what I'd recommend structurally: First, capture. Use a native mobile SDK if you're on mobile. Web-based capture introduces compression artifacts that degrade both OCR accuracy and PAD performance. I've seen document text confidence drop by 12 to 18 percent when a web upload path is used instead of a native camera integration. That's not theoretical. It happened on a production system during a peak traffic period when we switched from a custom camera implementation to a third-party web widget to save time. We lost a chunk of successful verifications and spent three weeks tuning the model thresholds to compensate.
Second, document forensic analysis. Run multiple checks in parallel: MRZ validation, font analysis, template validation against known document designs for the issuing country, and consistency checks across fields. A French CNI (Carte Nationale d'Identité) from 2021 has a completely different layout and security feature set than a 2019 version. Your system needs to handle document versioning or it will flag legitimate documents as suspicious. I learned this the hard way when our system started rejecting every French ID issued after September 2020 because the template database hadn't been updated. Third, biometric comparison. Face matching between the document portrait and the live selfie. Use a model trained on verification, not recognition. Verification means 1:1 comparison against the document photo. Recognition means 1:N matching against a database. Mixing these up is a common mistake. A verification model gives you a similarity score. You set a threshold. Below the threshold is a reject. The threshold depends on your acceptable false accept and false reject rates. For financial services, you'll typically aim for an equal error rate around 1 percent or lower. For low-risk onboarding, 3 to 5 percent EER might be acceptable. Fourth, database queries. Run whatever authoritative sources are available in your jurisdiction. Cross-reference name, date of birth, document number, and address. When data is available across multiple sources, consistency matters more than any single source. If the SSN validator says the number is valid but the address history shows no record at the provided address, that's a red flag even though both checks individually passed.
Fifth, decisioning. Combine the results. A simple scoring model might weight document authentication at 30 percent, biometric match at 30 percent, database results at 25 percent, and behavioral signals at 15 percent. The weights are arbitrary to start with. You calibrate them based on your historical data and your risk tolerance. Don't skip this calibration step. Out-of-the-box weights from a vendor are tuned for their average customer, not yours.

Edge Cases That Will Burn You
Naturalized citizens often have documents issued under a previous name. The database check will fail because the name on the ID doesn't match the name on the government record. The workaround is to accept legal name change documentation — a certificate of naturalization, a court order, or equivalent — and link the identities manually. Automated systems rarely handle this well. Transgender applicants face a similar problem. Government IDs may reflect a preferred name or a legally changed name while database records haven't been updated. I had a case where an applicant's passport had been updated but their national ID card hadn't, and the verification system rejected the mismatch. The fix was to allow document-to-database reconciliation with human review rather than auto-reject on field mismatches. Expired documents. Some jurisdictions allow ID verification with expired documents if the expiry is within a certain window. Others don't. Check your regulatory requirements before you build logic around document validity. A US driver's license verification through state DMV APIs often returns a valid status even when the card is expired, but the expiration date is still part of the response. Your system needs to decide what to do with that information.
Names with diacritics and special characters. The MRZ standardizes these to ASCII equivalents. An MRZ check will pass even when the visual zone contains characters like ä or é. This is by design. But your matching logic needs to handle the normalization correctly. I've seen systems where an applicant named Müller failed verification because the database stored the name as "Mueller" and the string comparison was case-sensitive and accent-sensitive. Normalize everything to a standard form before comparing. Passport cards and travel documents that aren't national IDs. In the US, a passport card is a valid travel document but not a full identity credential in the same way a passport book is. Some verification systems treat them interchangeably. They shouldn't be. The passport card has different security features and a different data structure. Verify the document type and apply the appropriate checks.
Common Pitfalls
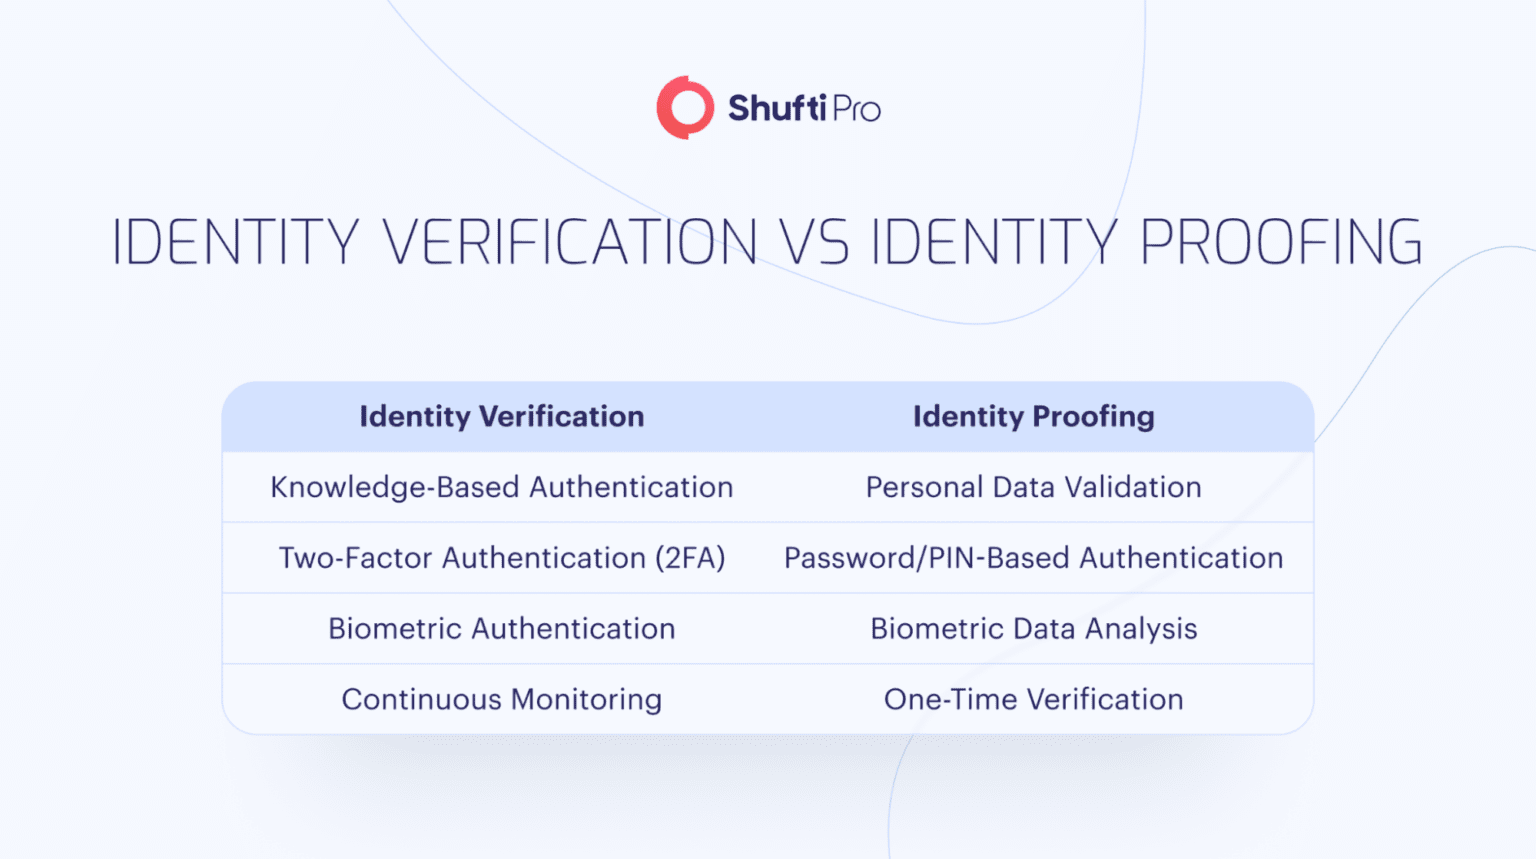
The biggest one is treating identity proofing as a one-time event. It isn't. People change names, addresses, and appearances. Documents expire. Fraudsters adapt. Ongoing monitoring — periodic re-verification, watchlist screening refreshes, and behavioral anomaly detection — is where most organizations fail. They verify once at onboarding and then forget about it until something goes wrong. Another pitfall is over-reliance on a single vendor. Every vendor has strengths and weaknesses. A system that's excellent at document forensic analysis might be weak on database coverage in certain jurisdictions. I've seen teams run two verification pipelines in parallel — one from Vendor A and one from Vendor B — and only flag cases where they disagreed for manual review. It costs more but catches a significant number of edge cases that a single pipeline would miss. Threshold tuning is a third pitfall. Setting thresholds too aggressively increases false rejections and hurts your conversion rate. Setting them too loosely lets fraud through. The right threshold depends on your transaction volume, your fraud loss tolerance, and your customer experience goals. Run A/B tests. Monitor your false accept and false reject rates monthly. Adjust based on actual outcomes, not theoretical models.
What Works In Practice
If you're building this from scratch, start with a managed service for the heavy lifting — document OCR, PAD, face matching — and layer your own logic on top for database queries and decisioning. Companies like Jumio, Onfido, and IDnow offer SDKs that handle most of the hard parts. The tradeoff is cost and less control over the pipeline. If you're building in-house, you'll need computer vision expertise, access to document template databases, and a substantial labeled dataset for model training. For the credential analysis piece specifically, look at systems that support format-aware parsing. A generic OCR engine will read the text on an ID but won't understand that field 7 on a Chinese ID card is the address and field 10 is the issuing authority. Format-aware parsers know the structure of each document type and extract fields accordingly. This matters more than you'd think. Generic OCR can produce correct text in the wrong fields, which breaks downstream validation. Keep your manual review queue small. The goal is automated resolution for the vast majority of cases. Flag only the ambiguous ones — low-confidence document checks, biometric matches near the threshold, database mismatches, expired documents, name inconsistencies. A good system should auto-approve 80 to 90 percent of legitimate applicants. If your auto-approval rate is below 70 percent, your thresholds are too conservative or your data sources are insufficient. If it's above 95 percent, you're probably letting too much through.
Track your fraud loss rate alongside your approval rate. The metric that matters isn't how many people you approve. It's how many bad actors you let through relative to the cost of verification. A system that approves 99 percent of people but lets 2 percent of fraudsters through is worse than a system that approves 95 percent of people and lets 0.1 percent of fraudsters through. Know your numbers. Regulatory compliance should drive your architecture, not the other way around. GDPR, CCPA, PSD2, and various national KYC/AML frameworks all have different requirements for data retention, consent, and audit trails. Build your system to log every decision, every data point queried, and every threshold applied. When a regulator asks why an applicant was rejected, you should be able to produce a complete audit trail without reconstructing it from memory. I've been in meetings where we couldn't explain a rejection because the system didn't log which specific check triggered the fail. It was embarrassing and it cost us a compliance review.