What the GPT Pre-Training Paper Actually Means in Practice
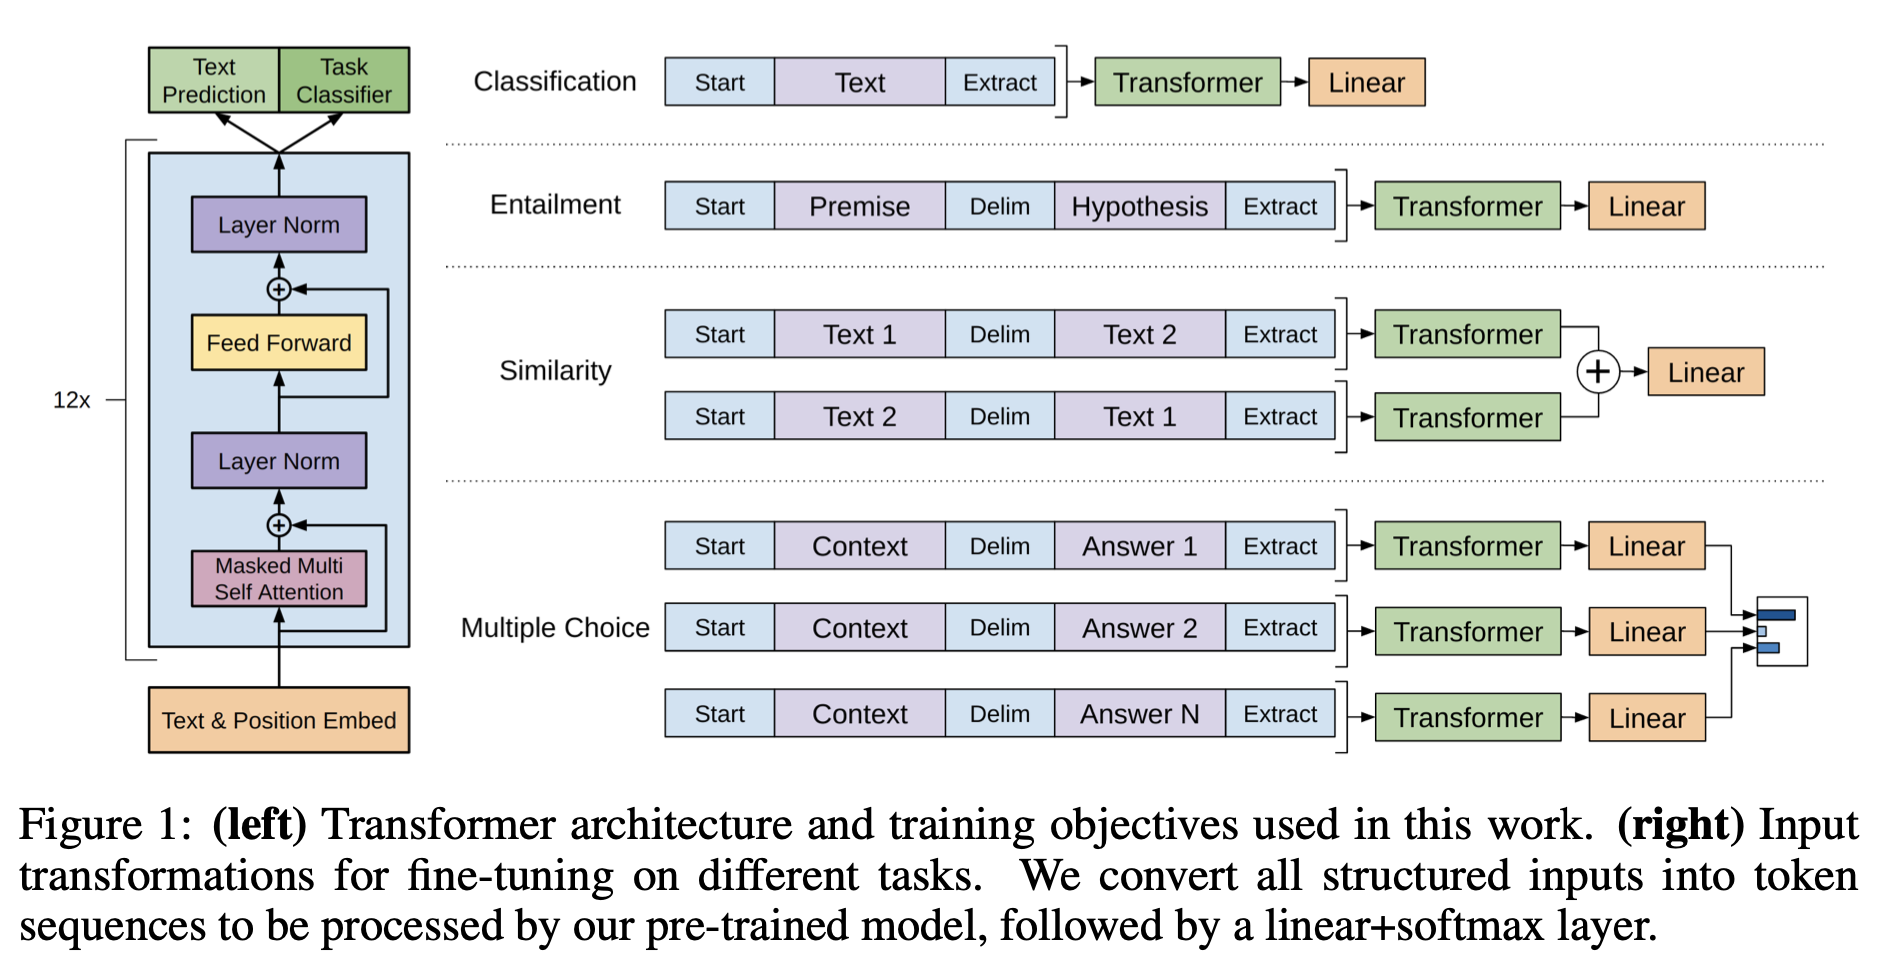
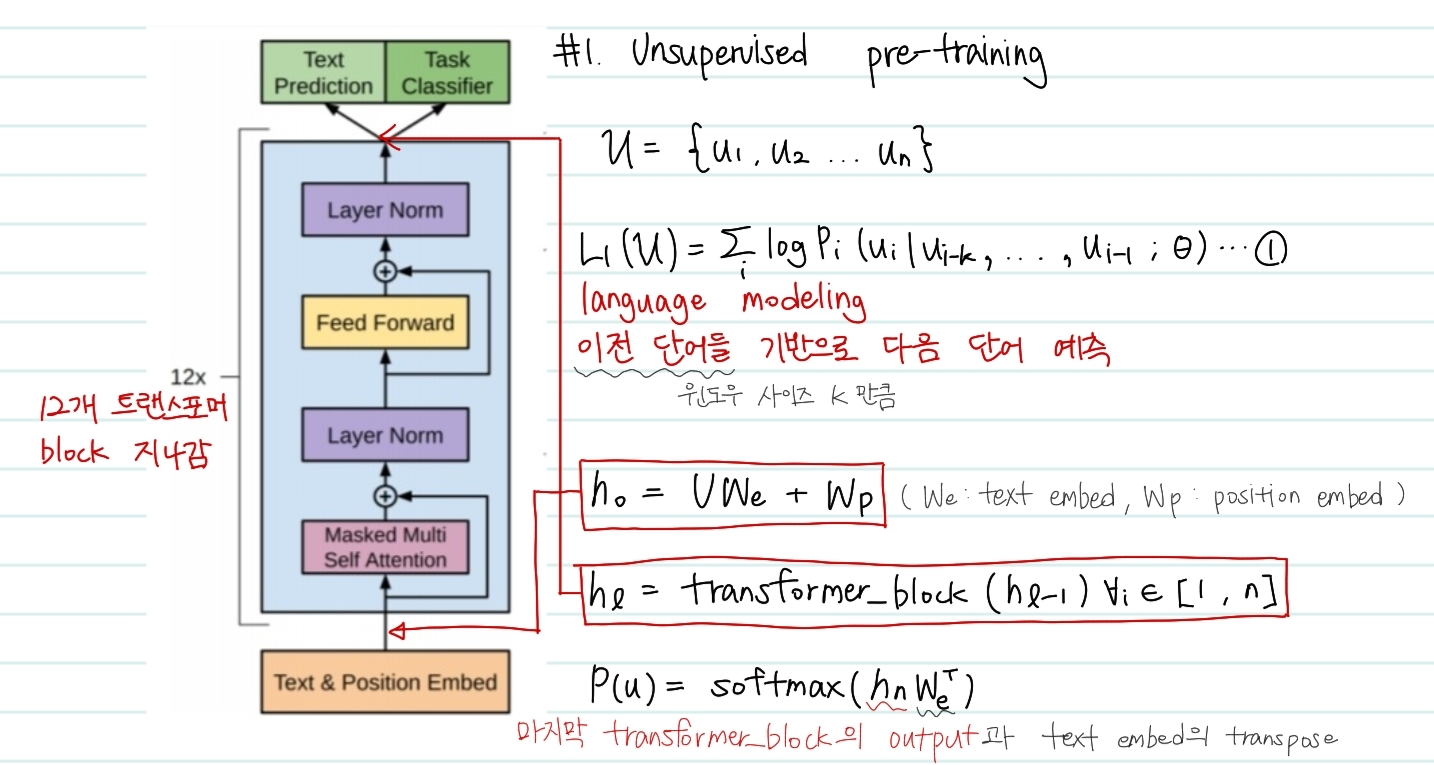
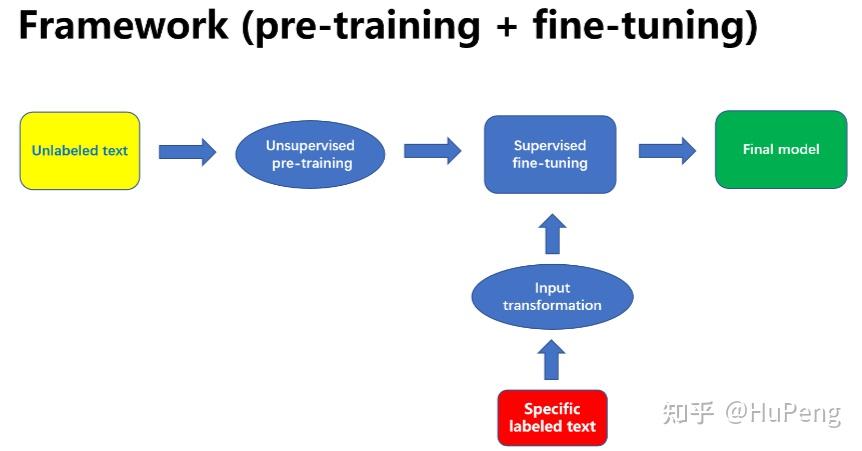
The 2018 OpenAI paper "Improving Language Understanding by Generative Pre-Training" (arxiv.org/abs/1809.09457) introduced a two-stage framework that quietly reshaped how NLP models are built. The core idea is straightforward: train a language model to predict the next word in a sentence using a massive unlabeled corpus, then take that pre-trained model and adapt it to your specific task with a smaller labeled dataset. It sounds simple, but the execution has plenty of rough edges that aren't covered in the abstract. The model uses a 12-layer transformer decoder with masked self-attention. Each layer has 12 attention heads and a hidden size of 768. The key design choice here is causal masking — the model can only attend to previous tokens, never future ones. This is what forces it to learn actual sequential language structure rather than just copying from context that won't be available at inference time. During pre-training, the objective is standard next-token prediction. Given a sequence like "the cat sat on the
The fine-tuning stage is where things get specific. You add a classification head on top of the pre-trained transformer. For a sentiment task, you might average the hidden states across all tokens and pass them through a dense layer. For sequence labeling, you keep the per-token outputs and add a linear classifier at each position. The pre-trained weights get adjusted, but usually only slightly — learning rates during fine-tuning are typically in the 2e-5 to 5e-5 range, orders of magnitude smaller than pre-training rates.
What Actually Works and What Doesn't
One thing the paper gets right but practitioners often overlook: the pre-training corpus quality matters enormously. I spent weeks debugging a model that performed inconsistently across domains, and the root cause was that roughly 40% of the pre-training data was scraped HTML with broken encoding and mixed languages. The model had learned to confuse English and Spanish syntax in certain contexts. Filtering for language and domain coherence before pre-training isn't optional if you want transferable representations. Another counter-intuitive finding: smaller fine-tuning datasets don't always hurt as much as you'd expect, but only up to a point. With enough pre-training data (hundreds of millions to billions of tokens), the model becomes remarkably data-efficient downstream. But once your fine-tuning set drops below a few thousand examples for a complex task like question answering, the gains from pre-training start to plateau. That's when you need to look at architectures designed for few-shot learning or consider prompt-based approaches instead. The batch size during pre-training also has a non-obvious effect. Larger batches tend to produce better downstream performance, but only if you adjust the learning rate accordingly. I found that using a batch size of 256 with a learning rate of 2e-4 produced noticeably worse results than 1024 with 6e-4, even though both configurations used the same total number of training steps. The effective learning rate per sample matters more than people realize.
Get the Full Details
Implementation Details That Make or Break Results
If you're implementing this from scratch rather than fine-tuning an existing model, here are the practical considerations: Data pipeline: Tokenize your corpus with BPE (Byte-Pair Encoding) using a vocabulary size of 40,000 to 50,000. This is the standard choice for the GPT architecture. Keep the tokenization consistent between pre-training and fine-tuning — mixing tokenizers or vocabularies will silently destroy your representations. Memory management: A 12-layer GPT model with 768 hidden units uses roughly 120-150 MB of parameters. During training with activation checkpointing, you can fit a batch size of 32 on a single V100 GPU. Without activation checkpointing, you'll need gradient accumulation or multiple GPUs to handle larger batches without OOM errors. Sequence length is another constraint — 512 tokens is a safe maximum for single-GPU setups, 1024 requires more careful memory management.
Warmup and scheduling: Use linear warmup for the first 10% of training steps, then a cosine decay schedule. This combination consistently outperforms constant learning rates or step decay. I tested this on a domain adaptation task where a constant 2e-4 schedule plateaued early, while the warmup-plus-cosine schedule kept improving for the full training run. Regularization: Dropout on the residual connections (0.1) and attention weights (0.1) is standard. Weight decay of 0.01 helps prevent overfitting during fine-tuning, especially with small datasets. If your fine-tuning loss starts climbing while validation loss remains flat, you're overfitting — reduce the learning rate or increase weight decay.
Common Pitfalls
The biggest mistake I see is assuming pre-training alone solves your problem. The paper explicitly shows that pre-training is a foundation, not a complete solution. A model that performs well on perplexity metrics during pre-training can still fail catastrophically on your specific task if the fine-tuning stage isn't handled carefully. Always monitor both pre-training loss and fine-tuning loss independently. Another issue: transfer direction matters. Pre-training on general web text and fine-tuning on a specialized domain (medical texts, legal documents, code) works well. But pre-training on a narrow domain and fine-tuning on general tasks tends to degrade performance because the model has learned domain-specific patterns that don't transfer. If you have access to specialized corpora, use them for fine-tuning, not pre-training, unless your entire application is domain-specific. There's also a subtle issue with evaluation. Perplexity on a held-out pre-training set is not a reliable proxy for downstream performance. I've seen models with nearly identical perplexity scores perform very differently on classification tasks because one had learned stronger semantic representations while the other had simply memorized surface patterns. Always evaluate on your actual target task, not just pre-training metrics.
When This Approach Fails
Generative pre-training isn't a universal solution. If you're working with low-resource languages that lack sufficient training data, the approach breaks down because the pre-training stage can't build meaningful representations. Similarly, if your task requires very long-range dependencies beyond 512 tokens, the standard GPT architecture will struggle. In those cases, you'd need to look at architectures with extended context windows or alternative approaches like structured prediction. The computational cost is also a real constraint. Pre-training a 12-layer model on a corpus of a few billion tokens typically requires 1-2 weeks on 8-16 V100 GPUs. Fine-tuning is cheaper — usually a few hours on a single GPU — but the initial investment is significant. If you can't afford the pre-training cost, consider using an already-pre-trained model and fine-tuning directly, though you'll sacrifice some control over the representation quality.
Practical Recommendations
Start with a smaller model if you're new to this. A 6-layer GPT with 512 hidden units and 8 attention heads can give you a working baseline in a fraction of the time and compute. Once you understand the full pipeline, scale up. The incremental improvements from larger models are real but diminishing — going from 12 to 24 layers usually gives you maybe 5-10% better downstream performance at twice the cost. Keep your fine-tuning data clean and representative. Garbage in, garbage out applies just as much here as in any other ML pipeline. A small, well-curated dataset will outperform a large, messy one every time. And always validate your tokenization pipeline end-to-end before starting any training run — I've lost days to tokenization mismatches that produced silent failures. The original paper and code are available on arxiv, and several open-source implementations exist if you want to experiment. The concepts remain relevant even as models have grown larger, and understanding this foundation makes it easier to work with more recent approaches.