How Merit Actually Works in Science Research
When I started doing lab work in the mid-90s, nobody talked much about merit systems. You just published papers, got cited, and moved up. That was it. The concept of In Defense Of Merit In Science wasn't some hot button topic back then because the mechanisms were simpler and more transparent than they are now. Now I watch grad students spend more time navigating institutional requirements than actually doing experiments. There is a real difference between what we call merit and what passes for merit in modern research ecosystems.
The Practical Definition Nobody Admits To
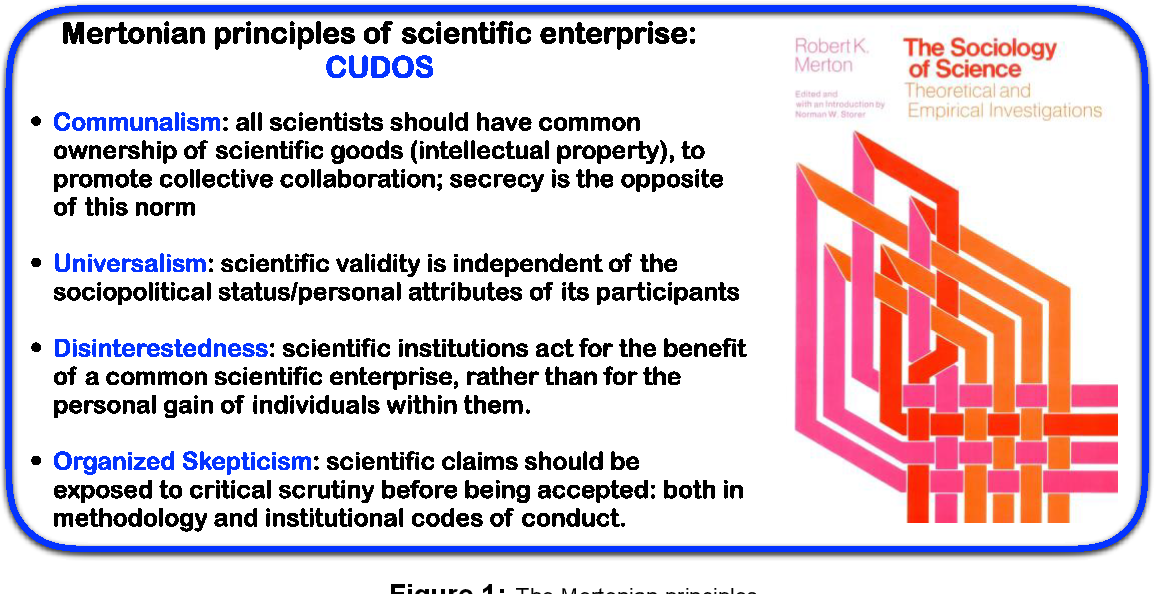
Merit in science means your contribution stands on its own technical merit. Reproducible results. Proper methodology. Honest reporting of negative findings. That kind of thing. The problem is that modern academia has built a parallel that rewards citation count, impact factors, and grant money over actual rigorous work. I had a colleague once who spent three years trying to replicate a high-profile paper from a top journal. The original study had been cited over 400 times. We reproduced the exact methods described in the supplementary material. The results came back completely different. When we tried to publish the replication, reviewers questioned our technique rather than the original finding. That is not how merit systems are supposed to work.
What Actually Counts as Merit
Reproducibility is the baseline. If someone else cannot follow your methods and get the same result, you have not done merit-based science. Period. This sounds obvious but most papers in my field do not provide enough methodological detail for proper replication. Honest reporting of negative results matters too. I remember spending six months on a project that showed absolutely nothing. The hypothesis was wrong, the model failed, the data was noise. I still wrote it up honestly and submitted it. My PI told me nobody would publish that. He was right. The paper never came out. Meanwhile, someone else published a similar study with p-hacking that got into a decent journal. That is the reality of the current system. Methodological rigor is another pillar. Proper controls, adequate sample sizes, appropriate statistical tests. Too many papers skip this. I once reviewed a manuscript that claimed statistical significance with a sample size of eight. Eight. The effect size was tiny. It was pure luck. I recommended rejection on those grounds alone.
Get the Full Details
Common Misunderstandings About Scientific Merit
People often confuse citation count with merit. These are not the same thing. A highly cited paper might be famous because it challenged established dogma or made bold claims. It might also be heavily cited because it provided a standard method that everyone uses as a reference. Neither factor necessarily indicates the work represents the highest quality science. Impact factors measure journals, not individual research. I have seen excellent work rejected by high-impact journals because the findings were too subtle or incremental. The same work got accepted by a smaller specialist journal where it actually influenced the field. The citations came. The recognition followed. The impact factor never mattered. Another confusion involves funding amounts. Big grants do not equal big merit. Some of the most important discoveries in my career came from minimal funding. Small-scale studies with careful design often outperform massive projects with sloppy execution. Money helps, but it is not a proxy for quality.
How to Evaluate Merit in Practice
Start by reading the methods section carefully. If you cannot understand how they got their results, that is a red flag. Good science is transparent. Anyone should be able to follow the chain from question to conclusion. Check whether negative results are acknowledged. Papers that only report positive findings while ignoring contradictory data are less credible. I look for discussions of limitations and alternative explanations. Those show intellectual honesty. Look at the replication record. Has anyone tested the findings independently? A single study is interesting. Multiple independent confirmations are compelling. I trust research that has survived repeated attempts to disprove it.
Examine the statistical analysis. Are the tests appropriate for the data type? Is multiple testing corrected? Are effect sizes reported alongside p-values? Simple things like this separate careful work from sloppy work.

The Hard Truths About Merit Systems
Merit in science does not work perfectly. Bias exists. Personal relationships matter. Funding sources influence priorities. Gender and ethnic disparities persist in many fields. Ignoring these problems does not make them disappear. The peer review system has fundamental limitations. Reviewers are often overworked, undercompensated, and sometimes incompetent at evaluating specialized work. I have seen papers rejected by reviewers who did not understand the methodology. I have also seen poor papers accepted because reviewers were too polite to criticize. Publication bias favors novel positive results. Null findings get filed away in drawer drawers. This skews the literature and makes replication harder. The problem is structural, not individual. Fixing it requires institutional change, not just better individual practices.
Sometimes merit simply does not win. I know researchers with brilliant ideas who lack connections, institutional support, or the personality for self-promotion. Their work goes unnoticed while less rigorous studies from well-connected labs get attention. This is unfortunate but real.
Why This Still Matters
Despite these problems, merit remains the best standard we have. Alternative systems based solely on reputation, funding, or institutional prestige tend to reproduce existing inequalities rather than identify genuine excellence. Merit systems are imperfect but they provide a framework for evaluating work on its actual merits rather than external factors. The key is to apply merit criteria consistently and transparently. Define what you mean by merit before you start judging. Make those criteria public. Apply them uniformly across all submissions. Acknowledge when the system fails to identify true quality. I still believe in this approach. The alternative is worse. Without merit-based evaluation, science becomes politics. Resources flow to the connected rather than the competent. Important work gets ignored. Bad work gets amplified. That is not how we discover truth.

A Few Practical Takeaways
If you are evaluating others work, read the methods carefully before judging the conclusions. Check whether the data supports what they claim. Look for alternative explanations they did not consider. Ask whether you would reach the same conclusion from the same data. If you are doing the work yourself, report everything honestly. Include negative results. Document your limitations. Share your data and code when possible. These practices build credibility over time. If you are reviewing grants or papers, apply consistent criteria. Do not let reputation substitute for evaluation. Take the time to understand the work thoroughly. Provide constructive criticism even when you reject something.
The system will not fix itself. Individual researchers need to hold themselves and each other accountable. That is how merit in science actually works. Not through declarations or policies but through daily practice and honest evaluation.


