What In H Mart Analysis Actually Looks Like in Practice
The In H Mart Analysis framework is a way of breaking down store-level performance by comparing traffic patterns, basket composition, and margin contribution across different product categories within a single retailer. Most people treat it like a revenue exercise. It isn't. It is fundamentally a cost-to-serve calculation dressed up in sales language. I built my first working model around 2019 for a regional grocery chain trying to understand why certain locations were flagged as profitable on paper while quietly bleeding cash. The model itself was straightforward, but the data layer was where things fell apart. Transaction-level detail had to be joined with shelf-level allocation data, and half the records were missing category codes entirely. I spent three weeks cleaning SKUs before the model would even run.
How the In H Mart Analysis Model Works
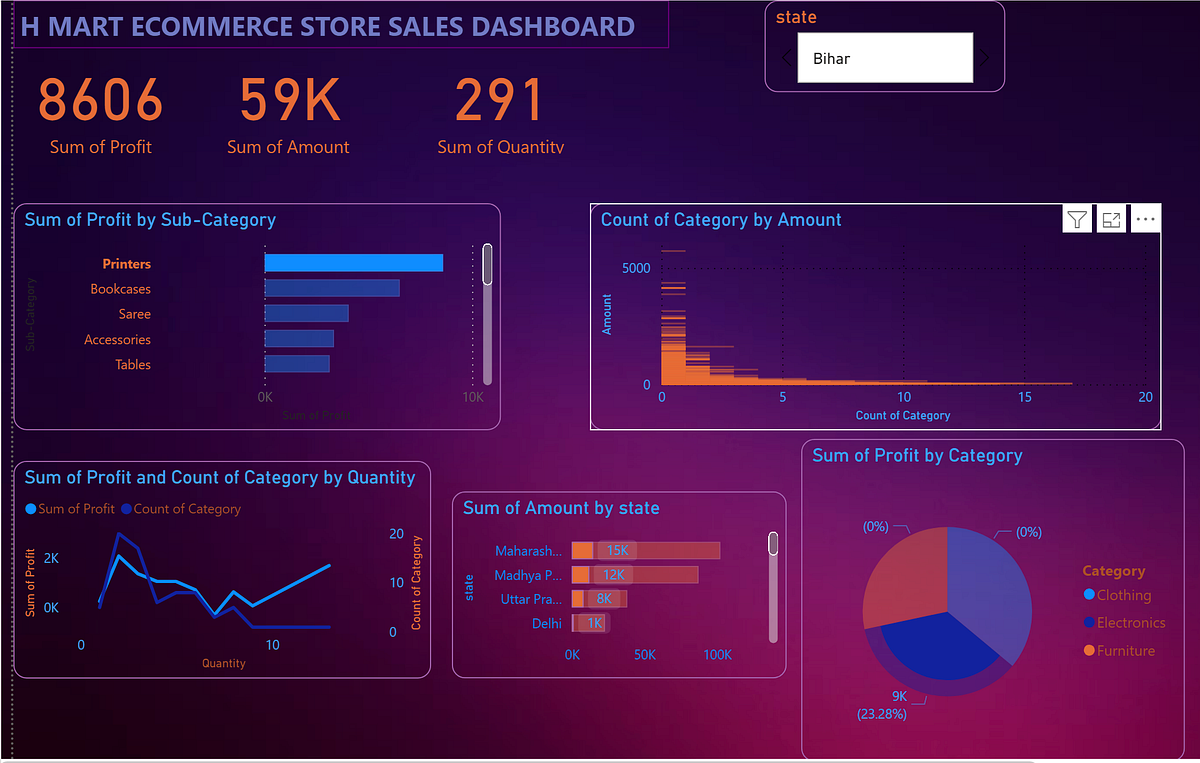
The core of the method rests on three inputs: hourly or daily footfall counts, average transaction value segmented by category, and gross margin per SKU or category block. You then map those against the fixed and variable costs attributable to each department. Space utilization comes into play as well, because a category that generates decent margin but consumes disproportionate square footage is often dragging the overall unit economics down. Here is how I set up the basic calculation pipeline. First, pull POS data at the SKU or category level for the period you are analyzing. Second, overlay traffic data from door counters or loyalty card check-ins so you have a conversion rate per department. Third, apply margin percentages net of returns and shrink. Finally, allocate overhead costs based on either square footage or labor hours, depending on what your accounting team will actually support. I keep the model in SQL with a Python post-processing step. The SQL handles the joins and aggregations, and Python does the normalization and visualization. Raw Excel models tend to choke once you push past fifty thousand rows, and that is before you start layering in multiple store comparisons.
Where People Mess This Up
The most common mistake is treating average transaction value as a stable metric across categories. It is not. A shopper buying produce has a completely different basket profile than one in electronics or prepared foods. When you normalize across categories without accounting for this, you end up overvaluing low-frequency high-ticket departments and undervaluing high-frequency low-margin ones. Another issue I see constantly is ignoring promotional interference. A category might look like it is underperforming in a given month, but that could be entirely driven by a manufacturer rebate that shifted margin to the supplier side. Without reconciling trade spend at the category level, your conclusions will be wrong. I learned this the hard way on a project for a mid-sized mart chain in the southeastern US. The initial analysis showed that their bakery department was the worst performer by square-foot margin, so the recommendation was to reduce floor space. After digging into the transaction data, I found that the bakery was driving a significant portion of cross-category traffic. Customers who came in for bread were also buying dairy, deli, and ready-to-eat items. Cutting bakery would have taken a hidden revenue driver with it. The fixed cost allocation model couldn't capture that spillover effect on its own. I ended up building a supplementary attribution layer that tracked multi-category baskets and weighted the bakery accordingly.
Get the Full Details
Practical Edge Cases and Workarounds
When store layouts change, historical comparisons break. I ran into this with a client that relocated their dairy section midway through a twelve-month analysis window. The footfall pattern for that department dropped artificially in the second half of the period because the new location was less visible. I solved it by creating a location-adjusted baseline and reweighting the pre-relocation months to match the post-relocation traffic profile. It took about two days of manual verification, but it kept the analysis honest. Data quality is another persistent problem. Some retailers still use manual price tagging or have inconsistent category hierarchies across stores. I recommend running a data completeness audit before you invest time in modeling. If more than ten percent of transactions lack a valid category code, the results will be unreliable regardless of how elegant your approach is.
When This Method Fails Completely
Do not use In H Mart Analysis for businesses that operate primarily online, where foot traffic is nonexistent and basket analysis must come from digital analytics instead. It also struggles with highly seasonal operations like holiday pop-up stores, where fixed cost allocation across a short operating window skews the numbers heavily toward any category with a brief demand spike. In those situations, a simpler contribution margin per square foot model usually gives you cleaner answers faster. The biggest limitation is that this framework assumes category performance is independent enough to compare. In reality, departments influence each other constantly. A well-stocked meat counter drives fish sales. A prominent snack display affects beverage purchases. If your store does not capture basket-level linkage data, you are working blind on those interactions. For retailers that want a practical entry point, start with just two or three categories and a single store. Get the data pipeline working end to end before expanding. A lean model that runs reliably beats a sprawling one that produces suspiciously perfect results every time.