Figuring Out Which Variable Is Which
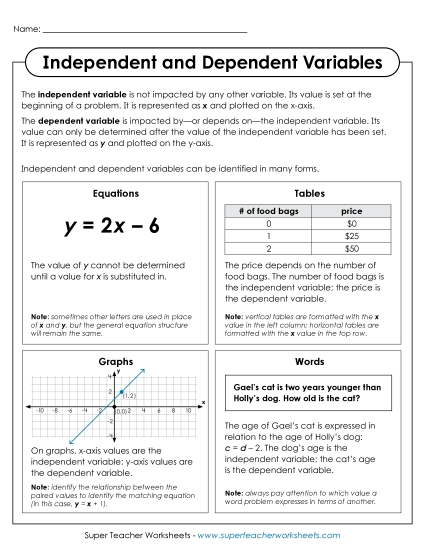
I see people struggle with this in intro stats classes, and honestly, it trips up professionals too when they're rushing through a model build. The basic idea is simple enough. An independent variable is what you change or control. A dependent variable is what happens as a result. But the moment you step outside a textbook problem, things get messier. Here is how I actually approach it in practice. Start by asking what question you are trying to answer. Then identify what is being measured versus what is being manipulated or observed as the cause. That distinction matters because mislabeling them will make your entire analysis come back wrong. I spent an afternoon last year re-running a regression because I had initially coded a lagged outcome variable as independent when it should have been dependent. The coefficients flipped direction and the model fit looked reasonable enough that I almost missed the mistake. Caught it only after I cross-referenced the data collection timeline against the model specification. Lesson learned. Always map the temporal sequence before you assign roles to variables.
Independent And Dependant Variables Math
Let me walk through a practical example. You are building a model to predict sales based on advertising spend, season, and competitor pricing. Advertising spend is your independent variable. Sales is your dependent variable. But here is where it gets tricky. Competitor pricing could be treated as independent if you are controlling for market conditions. Or it could be endogenous if competitors are also reacting to your own pricing moves. In that case, you are looking at simultaneous equations, not a straightforward OLS setup. I usually sketch a causal diagram first. Draw arrows from things that might influence other things. Your dependent variable sits at the end of the arrows. Everything feeding into it is independent. This takes about five minutes and saves me from specification errors that would otherwise surface later as nonsensical coefficient signs or variance inflation factors around twelve or thirteen. There is a common mistake people make. They treat correlated variables as interchangeable causes and effects. Just because two variables move together does not mean one drives the other. I ran into this with a client who thought website traffic caused purchase conversions when really it was a third factor, a marketing campaign, driving both. The correlation coefficient was 0.87. Misleading without context. Running a Granger causality test or checking for instrumental variables would have revealed the problem faster than staring at scatter plots.
Another thing nobody warns beginners about. Discrete dependent variables break ordinary least squares assumptions. If you are modeling whether someone clicks an ad or not, that is binary. Using linear regression will give you predicted probabilities outside the zero to one range. Switch to logistic regression or a generalized linear model with a logit link. The math changes but the variable roles stay the same. Independent variables still feed into the model. The dependent variable just follows a different distribution.
Get the Full Details
Working Through Real Data Problems
When I pull raw data, the first thing I check is measurement level. Nominal, ordinal, interval, ratio. This determines what kind of math you can legitimately apply. Treating an ordinal scale like interval data is a fast track to garbage results. I once analyzed survey satisfaction scores as if they were continuous. The mean looked fine. The standard deviation told a different story. The distribution was heavily skewed with most responses clustered at the top. Re-treating the data as ordinal and using appropriate tests shifted the conclusions entirely. Multicollinearity is another headache. When independent variables correlate with each other above 0.7, your coefficient estimates become unstable. Standard errors blow up. A one-unit change in one predictor means nothing on its own because it moves in lockstep with another. The fix is usually variance inflation factor analysis or dropping redundant predictors. Sometimes you collect more data. Sometimes you accept that the variables cannot be separated statistically and report the joint effect instead of individual effects. Here is an edge case that costs people hours. Time series data with autocorrelation. If your dependent variable at time t depends on its value at time t-minus-one, standard error estimates are biased downward. You get false significance. The workaround is either differencing the data or using autoregressive models like ARIMA or Newey-West corrections. I use the latter when I need to keep the original scale for presentation purposes. It is slower computationally but the results are easier to explain to stakeholders who do not care about the underlying assumptions.
Missing data compounds every problem I just mentioned. Listwise deletion can shrink your sample by thirty percent or more depending on the field. I usually try multiple imputation with chained equations first. It preserves sample size and accounts for uncertainty in the missing values. It adds maybe twenty minutes to the workflow on a moderate dataset. Well worth it compared to publishing results based on a quarter of your observations.
When The Simple Model Fails
Not every relationship is linear. I encountered a dataset last month where the dependent variable dropped sharply after crossing a threshold on the independent variable. Linear models smoothed that right out. Switched to a piecewise regression with a knot at the identified breakpoint and the fit improved dramatically. R-squared went from 0.31 to 0.68. The insight the stakeholder needed was that effect, which the linear model completely obscured. Sometimes the problem is on the dependent variable side. Count data, survival data, proportional data. Each has its own family of distributions and link functions. Using Gaussian assumptions on count data produces negative predicted values. Using them on proportions creates predictions above one. These are not theoretical concerns. They happened to me repeatedly in the first two years of doing this work. Now I classify the data type before I touch any software. Confounding variables deserve a separate mention. A confounder affects both the independent and dependent variable and creates a spurious association. Adjusting for it in the model is essential. But over-adjusting is equally dangerous. If you control for a mediator, you block the causal pathway and estimate the wrong effect. I use directed acyclic graphs when the causal structure is unclear. They force you to commit to assumptions instead of hiding behind black-box software output.

Practical Steps That Actually Work
Run diagnostic plots early. Residuals versus fitted values, Q-Q plots, scale-location graphs. Do this before you present anything. Five minutes of plotting saves you from making claims that fall apart under peer review. Most statistical packages generate these automatically. Use that feature. Document your variable coding decisions. Write down why each variable is independent or dependent. Include the reasoning. Future you, or a reviewer, will thank you when you come back to the project six months later and cannot remember whether you centered a predictor or not. Validate your model on holdout data if the sample size allows it. Split your data, train on seventy percent, test on thirty. This catches overfitting that cross-validation alone sometimes misses. For small datasets, use leave-one-out or bootstrapping instead. The computational cost is higher but the estimate of out-of-sample performance is more honest.
I usually recommend starting simple and adding complexity only when diagnostics demand it. A well-specified basic model beats a poorly specified complex one every time. The temptation to throw in every available predictor is strong. Resist it. Parsimony is not just an aesthetic preference. It is a requirement for interpretable results. If you want a quick reference sheet I use, I maintain a one-page checklist on variable identification and model selection at my site. It covers the decision tree from data type through to diagnostic checks. Takes about an hour to read through carefully. The PDF format is easiest to keep open while you work.