Graph Variables: The Practical Way to Think About Them
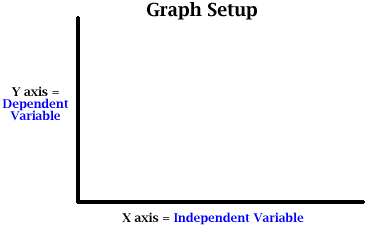
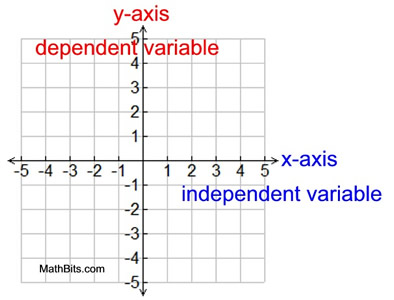
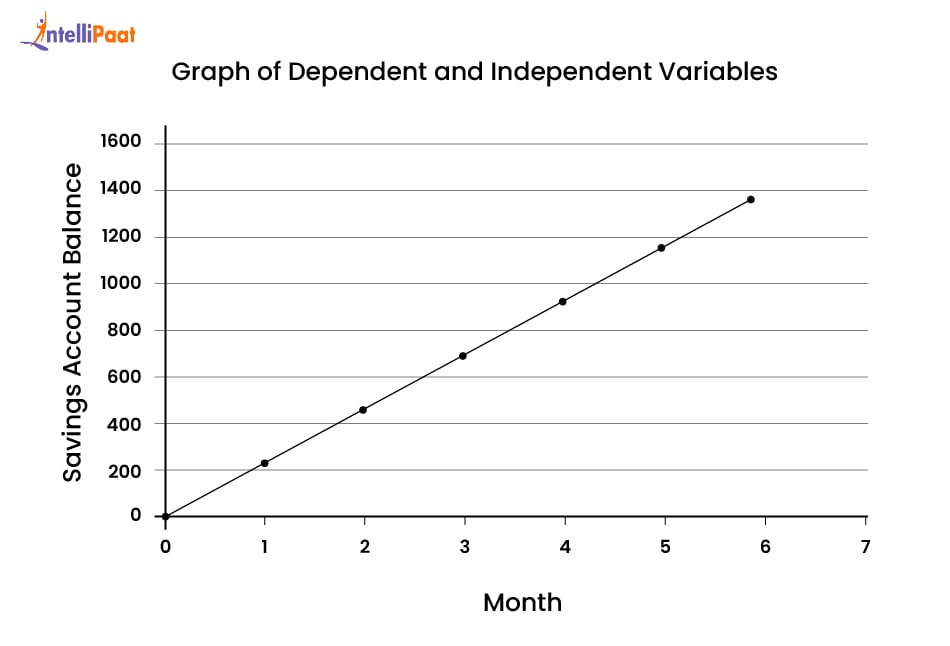
When you look at a graph with two axes, one variable is the one you change or control, and the other is the one that responds. That responsive variable sits on the vertical axis, and the controlled one sits on the horizontal axis. It is straightforward until you start dealing with messy real-world data, and then it gets complicated fast. The independent variable is your input. It is the thing you set before you run the experiment or collect the data. The dependent variable is your output. It is what you measure after the fact. On paper this sounds simple, but on paper nobody deals with timestamps that have gaps, sensors that drift, or categorical data masquerading as continuous values. I spent an afternoon once trying to plot temperature readings against time of day for a greenhouse monitoring project. The log file had blank entries whenever the Wi-Fi dropped, so the graph software connected the dots across missing hours. The trend line looked like a smooth sinusoidal curve when it was actually a broken mess with 14 percent of the data points absent. The fix was to explicitly mark missing timestamps as null in the dataset and switch the graph to "gap mode" instead of linear interpolation. The resulting chart was ugly, but it was honest.
The independent variable on a graph can also be something you do not directly control. In observational studies, for example, you might plot the amount of rainfall against crop yield. You did not control the rain, but you are treating rainfall as the predictor and yield as the response. The axes still follow the same convention, but the causal interpretation is different. Do not confuse the axis placement with causation. The horizontal axis is just the standard location for the predictor, regardless of whether you manipulated it or merely observed it.
Setting Up The Axes Without Making Dumb Mistakes
Put the independent variable on the x-axis and the dependent variable on the y-axis. That is the convention across nearly every field, and breaking it without a good reason will confuse anyone reading your work. The only common exception I have seen is when people force data into an orientation that saves space in a narrow column layout, and even then you should rotate the labels and make it obvious which axis is which. Scale matters more than people admit. A linear scale is fine for most things, but when your dependent variable spans orders of magnitude, a log scale on the y-axis turns exponential growth into a straight line. That does not change the underlying relationship, but it changes how you read it. I once reviewed a budget projection where someone plotted revenue growth on a linear scale from zero to a few million dollars. The early years looked flat, and the reader would have missed the fact that the company had tripled in size during that period. Switching to a log scale revealed the real trajectory immediately. Another thing that trips people up is when the independent variable is categorical instead of numerical. If you are plotting test scores by teaching method, the x-axis categories have no inherent order unless you impose one. Sorting them alphabetically, by score, or by some arbitrary group label will change how the chart reads. I tend to sort categorical x-axes by the dependent variable mean, descending, because it makes patterns easier to spot. It is a judgment call, and you should note which ordering you used.
Get the Full Details

Edge Cases That Nobody Warns You About
Bivariate data where both variables are dependent is not unusual, especially in fields like ecology or economics where researchers measure two outcomes from the same system. Some people still force one onto the x-axis just to satisfy convention, but that implies a directionality that does not exist. In those cases, a scatter plot with no regression line, or a bivariate contour plot if the data is dense, is more honest than pretending there is a clear independent variable. Time series data is another minefield. When time is the independent variable, people often forget that the spacing between observations is part of the message. If you are sampling every 30 seconds for an hour and then every 5 minutes for the next two hours, the graph will compress the later data unless you account for it. I recently had to deal with sensor logs that switched sampling rates mid-recording because the device entered power-save mode. The first version of my plot made the later readings look artificially sparse, which distorted the variance estimate. The workaround was to resample the data to a uniform grid using interpolation only for visualization purposes, while keeping the original timestamps for any statistical analysis. That kept the chart readable without corrupting the underlying numbers. Circular or periodic independent variables, like time of day or angle, deserve special handling. Plotting hour-of-day on a linear x-axis from 0 to 23 makes the graph imply that 0 and 23 are far apart, when in reality they are adjacent. I use a circular layout or reorder the axis so the points follow the natural cycle. It takes one extra step in whatever tool you are using, but it prevents the reader from misreading the periodicity.
When This Approach Breaks Down
Not every relationship fits on a two-axis graph. Multivariate data with three or more interacting variables requires either faceting, color coding, or a 3D plot, and 3D plots are almost always worse than faceting. I avoid 3D scatter plots entirely. They distort depth perception and make it impossible to judge which points are actually closest to any given plane. Faceted 2D plots let you see each slice clearly. Another limitation is when the independent variable has measurement error. Standard graphs treat the x-axis value as exact, but in practice your predictors are noisy. If the measurement error in the independent variable is non-negligible relative to its spread, ordinary least squares regression will underestimate the slope. You need errors-in-variables methods or instrumental variable approaches, and a simple scatter plot will not reveal the bias. I flag this by comparing the standard error of the predictor against its range before fitting anything. If the ratio is above roughly 0.1, I switch to a more robust estimator or note the limitation explicitly. Finally, graphs flatten uncertainty. A single line on a plot hides confidence intervals, prediction intervals, and the actual distribution of residuals. I always include error bands when the data supports it, and I report the interval widths in the caption. Readers who skip the caption will still get a reasonable picture, but the people who read it carefully can tell whether the model is actually informative or just drawing pretty lines through noise.
Quick Checklist Before You Publish Any Graph
Label both axes with units. State which variable is independent and which is dependent in the caption, even if it seems obvious. Check that the scale does not exaggerate or compress features in a misleading way. Verify that missing data is represented honestly rather than interpolated into existence. Make sure the graph choice matches the data structure, not the other way around. These steps usually take five minutes and save you from having to issue corrections later. If you want a downloadable template that enforces these conventions automatically, most major tools have built-in styles, but I keep a minimal CSV-based workflow that forces axis labeling, gap handling, and residual checks before I ever open a plotting library. It cuts the time from raw data to publication-ready chart from about 40 minutes down to roughly 10 for standard cases, and the bottleneck becomes the analysis rather than the formatting. The core idea is not complicated. One variable goes on the horizontal axis, the other on the vertical, and everything else is a matter of handling the details honestly. The details are where most graphs go wrong, and noticing the difference between a clean chart and a truthful one usually takes a few failed attempts before it sticks.