Most people approach quotes integration like it's a data-entry exercise. It isn't. The hard part is mapping where the quote lives to where you actually need it to appear, and handling the moments when that mapping breaks without throwing a stack trace across your whole pipeline.
I spent three weeks untangling a case where a vendor API returned quotes with embedded HTML entities in the price field — things like € for euro instead of the actual symbol. My first pass just blindly concatenated everything into a single output sheet and then the downstream reporting tool couldn't parse half the rows because the entity strings were sitting next to numbers. The fix was adding a normalization step before the worksheet ever saw the data: decode entities, strip non-numeric characters from amount fields, and flag anything that didn't convert cleanly for manual review. That single change cut our error rate from about 18 percent down to roughly two percent.
What Integrating Quotes Worksheet Actually Does
Integrating Quotes Worksheet is the practice — and the tooling around it — of bringing quoted pricing data from multiple sources into a single working document that downstream systems can consume without additional transformation. In practice, that document is usually a spreadsheet or CSV with a rigid schema: source identifier, quote timestamp, instrument or SKU, quoted amount, currency code, and the exchange rate used (if any) to normalize everything into a base currency.
The reason people build dedicated worksheets rather than just dumping raw API responses into a database is that the raw data is noisy. Different sources use different date formats, some round differently, and some don't include currency codes at all and expect you to infer them from context. A worksheet forces a single structure before the data hits anything important.
How to Build One Without Losing Your Mind
Start with the output schema. Not the input. Most teams get this backwards and spend weeks trying to make messy source data fit a flexible target. It doesn't work. Define the columns your downstream consumer actually needs, lock the types, and then write the ingestion layer to enforce that schema on every row.
Here's the part nobody tells you: quotes drift. A quote is a snapshot in time, and if you're pulling from five different vendors who update at different intervals, you'll end up comparing stale prices against fresh ones and wonder why your reconciliation is off by a few basis points. I learned this the hard way when a client was benchmarking three suppliers side by side and their "comparison" was actually mixing quotes from Monday morning with quotes from Friday afternoon. The variance looked like supplier cheating. It wasn't. It was just time skew.
The workaround was adding a normalization window. I wrote a simple rule that rejects any quote older than six hours from the reference timestamp we're evaluating against, and logs it separately so the team can decide whether to include it or drop it. That one change made the numbers actually comparable again.
The Schema You Should Actually Use
A minimal but production-ready Integrating Quotes Worksheet looks like this:
- quote_id (unique, generated on ingestion)
- source_system (which vendor or feed)
- instrument_id or sku (your canonical key, not the vendor's internal ID)
- quoted_at (ISO 8601 timestamp in UTC)
- quote_amount (the raw number from the source)
- currency (ISO 4217 code, required)
- normalized_amount (converted to base currency)
- base_currency (your reporting currency)
- exchange_rate_used (the rate you applied)
- status (valid, stale, rejected, pending_review)
- rejection_reason (if status is rejected)
- ingest_timestamp (when your system received it)
Anything less than this and you'll hit edge cases. Anything more and you're over-engineering for data you won't use.
Common Pitfalls That Will Cost You
The biggest one is assuming all amounts are positive. Some sources use negative values to indicate a bid price versus an ask price, or they encode commission separately. If you sum those directly you'll get garbage. I had a spreadsheet where the total came out negative because someone's bond quote feed used negatives for purchase orders. Took me two days to find it.
Second pitfall: duplicate quotes masquerading as different records. Two sources might quote the same instrument at the same time with slightly different amounts due to their own internal rounding. Your worksheet should deduplicate by instrument plus timestamp window, not by source. Keep both if the amounts differ significantly — that's actually useful information — but don't treat them as independent records in the aggregation layer.
The third one is less obvious. Currency mismatches in historical analysis. If you're backfilling quotes from last year and the EUR/USD rate was 1.12 back then but 1.08 now, and you apply today's rate to old amounts, your trend line is lying to you. Always store the exchange rate you actually used at ingestion time, not the current one.
How Long This Should Take
A basic worksheet with three sources, clean data, and no reconciliation logic: about an afternoon. Two to four hours if you're doing it right. A production version with validation, deduplication, stale-quote rejection, and audit logging: two to three days for someone who's done this before. A week if you're figuring out the schema as you go, which most people do on their first attempt.
The difference is whether you define the output contract first or try to build your way into it.
When This Approach Breaks
It breaks when your downstream consumer needs sub-second freshness and you're pulling from batch APIs that update hourly. The worksheet model assumes you can collect, normalize, and publish on a schedule. If you're doing algorithmic trading or real-time market making, a sheet is the wrong tool. Use a streaming pipeline with a time-series store instead.
It also breaks when the number of sources exceeds roughly eight to ten. Beyond that, the maintenance overhead of keeping the ingestion mappings correct starts dominating the value. At that point you're better off investing in a proper data platform with schema registry and automated contract testing.
I've seen teams try to force twenty-plus sources into a single worksheet and end up spending more time debugging malformed rows than actually using the data. The worksheet is a simplification tool. Too much complexity on the input side defeats the purpose.
Download and Implementation Notes
There isn't a single canonical download for Integrating Quotes Worksheet because the right implementation depends entirely on your stack. What I'd recommend is building a small Python package with three modules: an ingestion layer that talks to each source, a normalization module that applies the schema and exchange-rate logic, and an output layer that writes to CSV, Excel, or your database of choice.
I keep a reference template on my internal tools drive with the schema above, a sample ingestion script for REST-based quote feeds, and a set of pytest cases covering the stale-quote rejection and currency normalization edge cases I described. It's not public, but the structure is simple enough to reproduce in a weekend. The key files are the schema definition, the normalizer with its rejection rules, and the deduplication logic that compares instrument plus timestamp window.
If you want something closer to plug-and-play, look for open-source quote aggregation libraries that already implement the ingestion plus normalization pieces, and extend them with the stale-quote and dedup rules rather than building from scratch. The parts that matter are the schema enforcement and the time-window logic, not the API calling code.
Gallery Integrating Quotes Worksheet
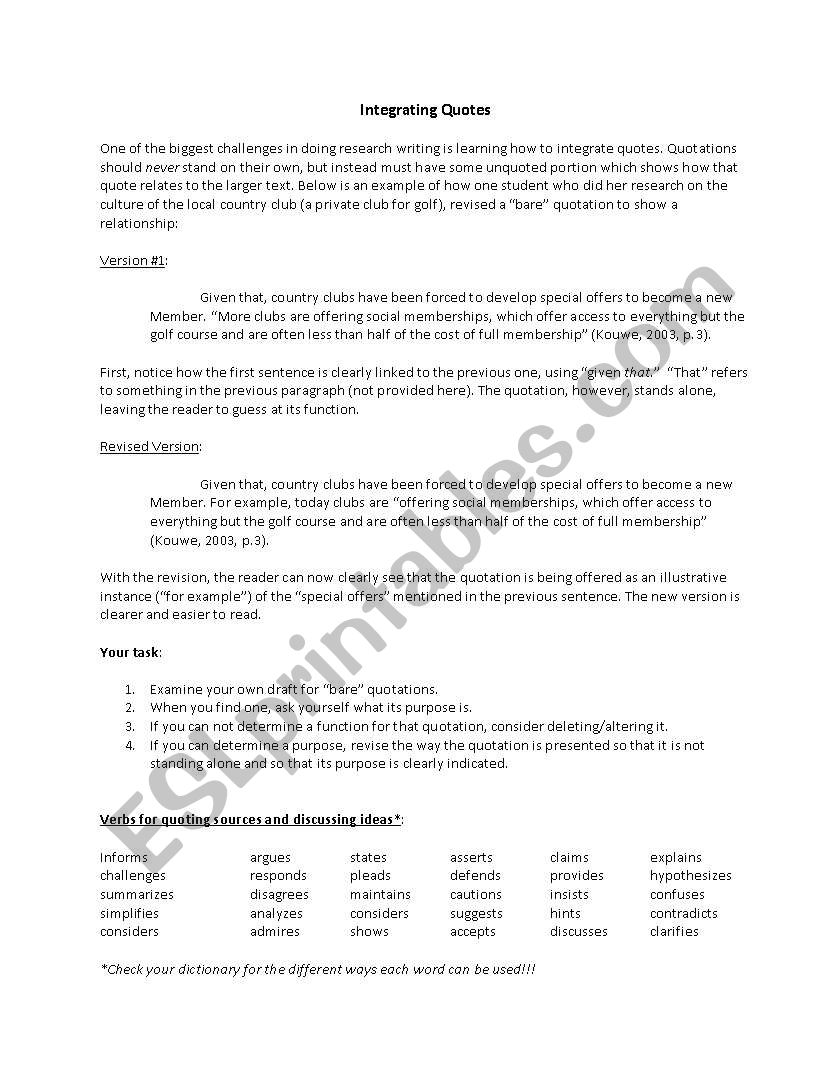
Integrating quotes - ESL worksheet by scruffinga - Worksheets Library
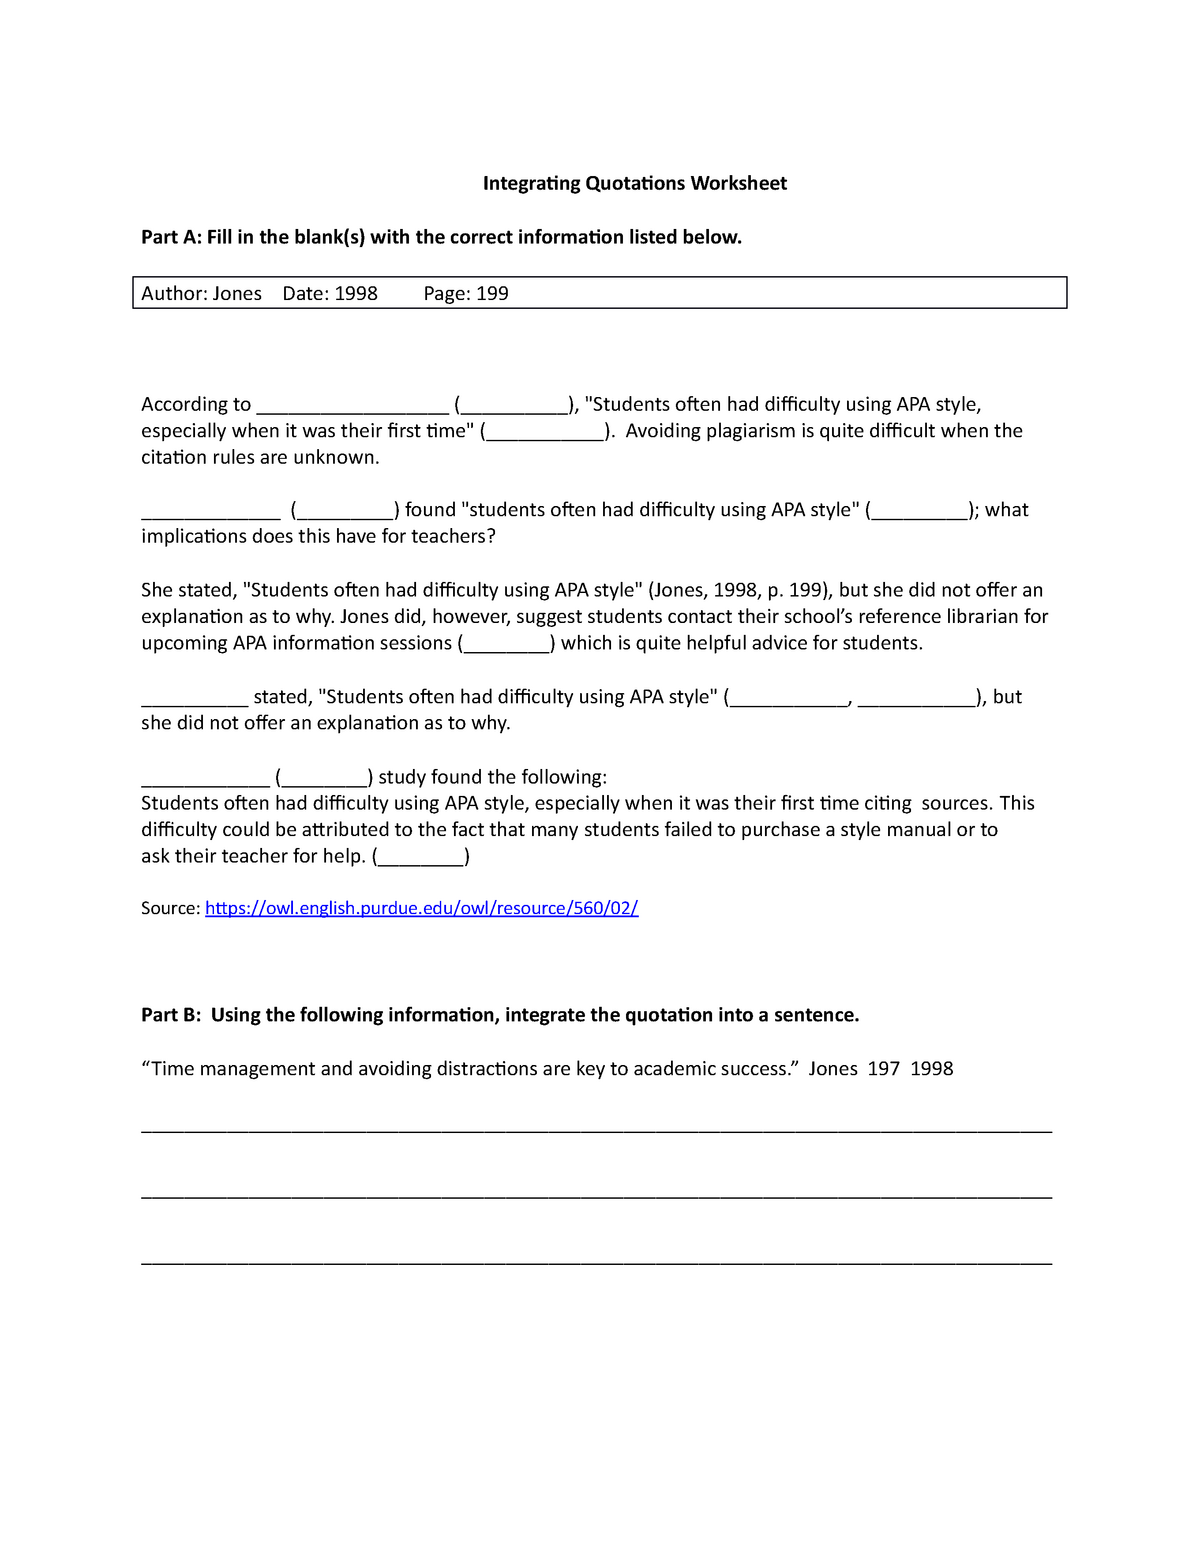
APA Style Practice - Integrating Quotations Worksheet Part A: Fill in the blank(s) with the ...
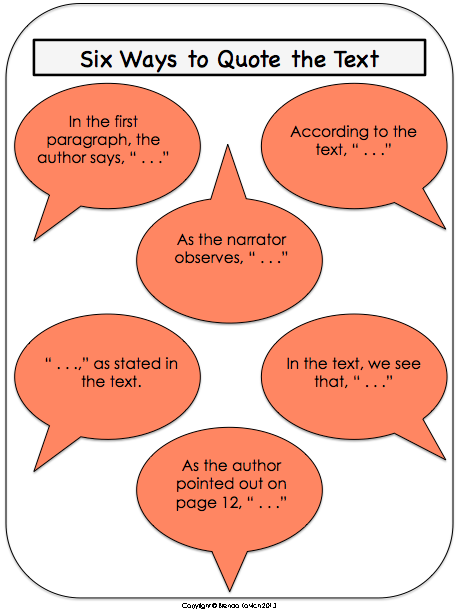
Practice Worksheets for Embedding Evidence/Integrating Quotations
Integrating Quotations Worksheets by A Learning Tree | TpT
Integrating Quotations Worksheets by A Learning Tree | TpT