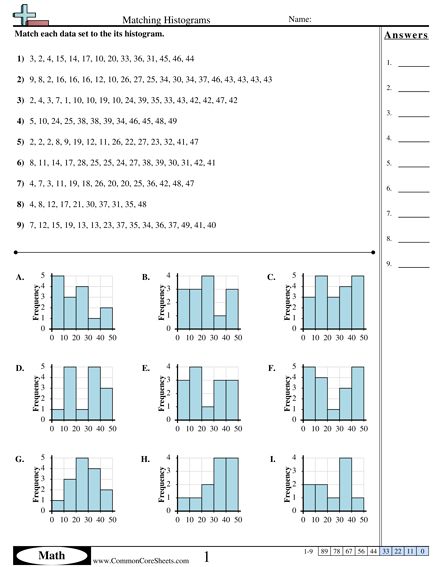
Reading Histograms Without Losing Your Mind
Histograms look deceptively simple. You see bars, you count them, you call it a day. Most people stop there and miss everything that actually matters. The difference between a useful histogram and a misleading one usually comes down to how the data was binned before it ever reached your screen. I have spent far too many hours explaining to students and colleagues that the shape they're staring at is partly an artifact of the bin width choice, not purely a feature of the underlying distribution. When you work through an Interpreting A Histogram Worksheet, you are not just matching shapes to names. You are learning to read the story the data is telling, and more importantly, learning to spot when the storyteller is lying to you.
Interpreting A Histogram Worksheet: What You Actually Need to Do
Here is the method I use when grading or reviewing histogram work, and it is worth applying before you write anything down: Step 1: Check the axes first. The x-axis shows your variable and the y-axis shows frequency or relative frequency. If the y-axis is labeled density instead of count, the area of each bar represents proportion, not height. Confusing these two is the single most common error I see. It flips your entire interpretation of a skewed distribution. Step 2: Identify the center, spread, and shape independently. Center is not always the mean. For heavily right-skewed data like income or response times, the median gives you a more honest sense of where most observations sit. Spread is your range or interquartile range, depending on what the data demands. Shape has four components: symmetry, skew direction, modality, and outliers.
Step 3: Call out gaps, clusters, and unusual features before you label the distribution. A gap in the middle of a histogram might mean two separate populations got mixed together. A cluster could indicate a subgroup. If you skip this step, your summary will be wrong even if your labels are technically correct. I once had a dataset where a histogram of patient wait times showed a bimodal shape. My first instinct was to call it bimodal and move on. Then I checked the raw data and realized the second mode appeared because the bin edges cut right through a natural boundary between two shifts. The fix was to adjust the bin width by a few minutes and replot. The second mode disappeared and the distribution became clearly unimodal with a long right tail. Bin sensitivity is real, and it will bite you if you do not check it.
Get the Full Details

The Details That Separate Adequate Work From Good Work
Most worksheets and textbooks treat histograms as static images. They are not. Changing the number of bins can make the same dataset look symmetric, skewed, uniform, or bimodal. This is not a trick question. It is the fundamental tension of histogram interpretation, and it is why your analysis should always include a note about bin width. Sturges' rule gives a quick default: k equals 1 plus log base 2 of n, where k is the number of bins. It works fine for small datasets around 100 observations, but it tends to oversmooth larger datasets. The Freedman-Diaconis rule is more robust because it uses the interquartile range to determine bin width, making it resistant to outliers. Use Freedman-Diaconis when your data has heavy tails or extreme values. Use Sturges when your sample is small and clean. Both are starting points, not final answers. Here is a counter-intuitive point that does not make it into most worksheets: a uniform histogram does not necessarily mean the data is uniformly distributed. It can mean your bins are too wide and you are averaging out real variation. If your histogram looks flat, narrow the bins and check again before you conclude the underlying process is uniform.
Another thing beginners consistently miss is how to interpret relative frequency histograms alongside raw frequency ones. When sample sizes differ between groups, a raw frequency comparison is meaningless. A relative frequency histogram normalizes each group to the same scale, which lets you compare shapes directly. I have seen too many people compare bar heights across groups with different totals and draw conclusions that vanish the moment you convert to relative frequency. Outliers in a histogram are not always visible. A single extreme value might inflate one bar and make the rest of the distribution look tighter than it is. Always back up your histogram reading with a box plot or a list of extreme values if the dataset is available. The histogram shows the bulk; the box plot shows the edges.
Common Mistakes to Avoid
Mistake 1: Calling any peak a mode without checking bin sensitivity. If you change the bin width by 10 percent and the number of modes changes, you do not have a genuine multimodal distribution. You have a binning artifact. Mistake 2: Ignoring the scale on the y-axis. A histogram with a y-axis from 0 to 10 looks dramatically different from the same data with a y-axis from 0 to 100. Always note the scale. It changes how you perceive gaps and relative frequencies. Mistake 3: Using histograms for small categorical datasets. Histograms are for continuous or discrete numerical data with enough observations to form meaningful bins. If you have fewer than 30 values and they are mostly unique, a dot plot or stem-and-leaf display will communicate the distribution better. A histogram with so few data points just looks sparse and confusing.
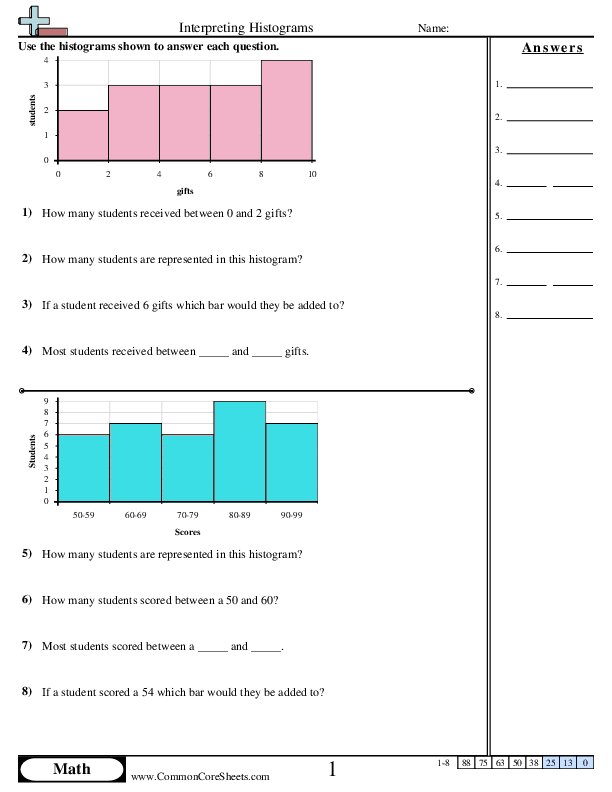
Mistake 4: Forgetting to describe context. A right-skewed histogram of exam scores means something different from a right-skewed histogram of household incomes. The shape tells you the direction of the skew. The context tells you why it matters. Never write a histogram interpretation without naming the variable and the units.
When Histograms Fail and What to Use Instead
Histograms break down in three specific scenarios. The first is when your data has a very large range with most values clustered in a tiny portion of that range. The histogram will show one tall bar and a long empty tail, and you will lose all detail in the cluster. Kernel density estimation solves this by smoothing the data, but it introduces its own bandwidth parameter, so you still need to make a choice. The second scenario is high-dimensional data. A histogram is strictly one-variable. If you need to see how two variables interact, use a scatter plot or a two-way table. Stacking histograms side by side can work for three categories, but it gets messy fast. The third scenario is small samples. With fewer than 50 observations, histogram shape is unreliable. Use a dot plot or a frequency table instead. The pattern you think you see in a small-sample histogram is often just noise.
If you are working through an Interpreting A Histogram Worksheet as part of a course, expect questions that test whether you can identify these limitations. The advanced problems usually include a note asking you to discuss bin width effects or to suggest an alternative display. That is the question that separates students who memorized definitions from students who actually understand the tool.

A Practical Checklist Before You Submit
Before you turn in any histogram interpretation, run through this list. It takes about two minutes and catches most errors. Did I state the variable and units? Did I note the bin width and how many bins were used?
Did I check the y-axis label for frequency versus density? Did I describe center, spread, and shape separately? Did I mention gaps, clusters, or outliers if they exist?
Did I avoid claiming modality without considering bin sensitivity? Did I relate the shape back to the real-world context? If you answer yes to all of these, your interpretation will be stronger than what most students turn in. The histogram itself is only as good as the reading you attach to it. The worksheet is not testing whether you can name a shape. It is testing whether you can read the data honestly, which is a different skill entirely.