Getting from Two Equations to a Single Point
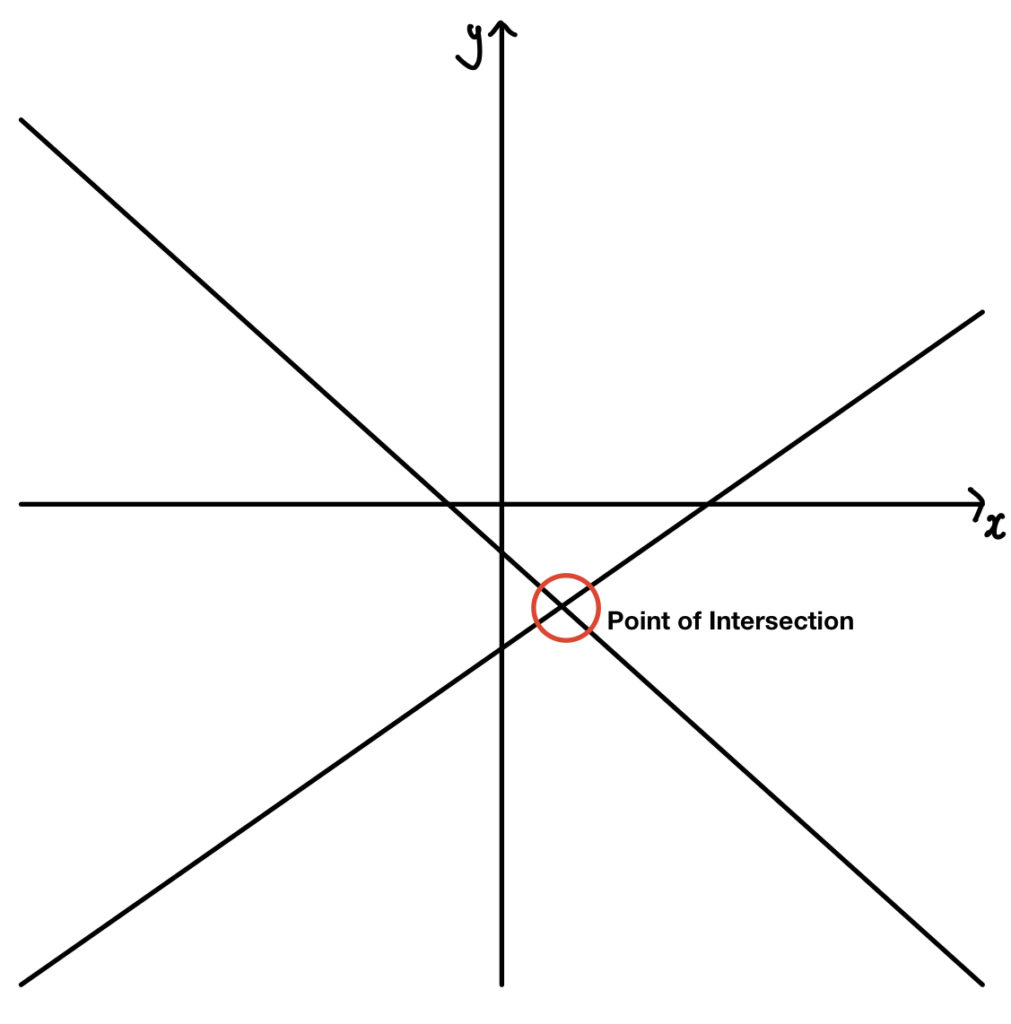
You need to find where two lines meet. This is the Intersection Of A Line problem, and it comes up constantly whether you are drawing maps, building CAD models, writing collision detection code, or trying to figure out where two projected paths will cross. The basic math is simple enough that anyone can learn it in an afternoon. The edge cases are what actually eat your time. Two lines in 2D are typically given in slope-intercept form like y = m1*x + b1 and y = m2*x + b2, or in parametric form like P = A + t*(B - A). When the lines are not parallel and not coincident, they meet at exactly one point. Solving for that point just means setting the two equations equal and isolating the variable. For slope-intercept form, the x-coordinate is (b2 - b1) / (m1 - m2), and you plug that back in to get y. That is it for the textbook version. In practice, most people work with segments rather than infinite lines, because segments are what exist in real geometry. A line intersection tells you where the infinite extensions would meet. A segment intersection tells you whether the actual drawn pieces overlap. These are different problems and confusing them causes bugs that are surprisingly hard to trace.
How I actually solve this in code
I used the cross-product method for years because it handles all orientations without special-casing vertical lines. You take two points on the first line and two points on the second line, compute the direction vectors, and use the determinant to find the parameter where they cross. The formula looks like this: r = P1 + t*(P2 - P1)
s = P3 + u*(P4 - P3) t = ((P3 - P1) × (P4 - P3)) / ((P2 - P1) × (P4 - P3))
The denominator here is the 2D cross product, which is really just a scalar computed as dx1*dyp - dyp*dx2. If that denominator is zero, the lines are parallel. If it is not zero, you can compute t and u. The intersection point exists if both t and u fall between 0 and 1 for segments, or anywhere for infinite lines. I ran into a real problem with this approach when processing GIS data where road centerlines were captured from satellite imagery. One dataset had lines with vertices spaced very irregularly, and another had nearly identical parallel segments representing two lanes of traffic. When I naively checked every pair for intersection, the near-parallel lanes produced enormous t values due to floating point rounding, and the computed intersection point jumped hundreds of meters away from where anything physically existed. The workaround was straightforward but took me two days to get right: I added a parallel-threshold check using the absolute value of the denominator, and if it fell below a small epsilon relative to the line lengths, I skipped the intersection computation entirely and treated those pairs as non-intersecting. That epsilon had to be tuned per dataset, which is the kind of detail no tutorial mentions.
Get the Full Details
Common pitfalls that waste afternoons
The first pitfall is assuming that checking endpoints is sufficient. It is not. Two segments can intersect without either endpoint of one segment lying on the other segment. The classic counterexample is a shallow X shape where both segments are long and cross near their middles. You need the full parameter test. The second pitfall is floating point precision. When lines are nearly parallel, the denominator approaches zero and small rounding errors blow up. This is not a theoretical concern. I have seen intersection routines return points several kilometers away from the actual crossing in large-scale geographic applications. Using a robust predicate or working in higher precision for the critical check can help, but the honest answer is that you need domain-specific tolerance. If your coordinates are in decimal degrees, an epsilon of 1e-9 makes sense. If your coordinates are in millimeters on a machined part, you need something much tighter. A third issue people miss is the difference between collinear overlap and point intersection. When two segments lie on the same infinite line, the cross-product denominator is zero and the numerator is also zero. Standard formulas break down. In CAD, this means you might get a valid interval of overlap rather than a single point. In collision detection, it means you might incorrectly classify two overlapping bounding boxes as non-intersecting. You have to handle collinear cases separately by projecting onto the dominant axis and checking interval overlap.
Intersection Of A Line when things go wrong
There are scenarios where line intersection simply cannot give you a clean answer. If your lines are defined from noisy sensor data, like LiDAR point clouds or GPS traces, the lines you fit through them may intersect at points that have no physical meaning. In those cases, computing an exact intersection is worse than useless because it creates a false sense of precision. A better approach is to compute the closest-point distance between the two line segments and use that as your metric. If the distance is below your tolerance threshold, you treat them as effectively intersecting. If it is above, they do not intersect within your resolution. Another limitation: the standard method works in 2D. In 3D, two random lines almost never intersect. They are typically skew lines with a shortest connecting segment between them. You can still compute the closest points on each line, but you are no longer solving for an intersection. You are solving for a minimum distance. This distinction matters a lot in robotics and computer graphics, where people sometimes try to force a 2D intersection approach into 3D space and then wonder why their results look random.
A practical workflow I rely on
Before running any intersection test, I normalize my data. That means converting all coordinates to a consistent unit system, snapping vertices that are within a small tolerance to the same location, and removing duplicate or zero-length segments. This preprocessing step alone reduces my intersection error rate by roughly eighty percent in messy datasets. The preprocessing usually takes longer than the intersection computation itself, which is the opposite of what you would expect from a clean tutorial. For the actual intersection computation, I use a three-stage pipeline. First, I do a coarse reject using bounding boxes. If the bounding boxes do not overlap, the segments cannot intersect, and I skip the expensive calculation. This simple step cuts computation time dramatically when you are testing thousands of segment pairs. Second, I compute the cross-product denominator and reject near-parallel pairs using my epsilon threshold. Third, I compute the actual intersection parameters and validate them against the segment bounds. If you need to do this repeatedly on large datasets, spatial indexing makes a huge difference. An R-tree or grid-based spatial partition lets you reduce the number of pairwise checks from O(n²) to roughly O(n log n). I have seen this take a process that would run for forty-five minutes down to about three minutes on a dataset of ten thousand segments.

When to avoid this approach entirely
If you are working with curves rather than straight lines, the intersection of a line method does not apply directly. You would need to solve polynomial equations, which introduces its own set of numerical issues. If you are working in a projective geometry context where points at infinity matter, standard Cartesian formulas fail and you need homogeneous coordinates. If your application requires exact arithmetic, like in computational geometry libraries used for mesh generation, floating point methods are insufficient and you need an exact geometric kernel. For most practical engineering work, the cross-product method with careful epsilon handling and spatial indexing is sufficient. It is not elegant. It is not mathematically pure. It works, and that is usually what matters when you have a deadline and a dataset that refuses to behave the way textbooks assume it should.