Parallel Computing Doesn't Have to Be Magic
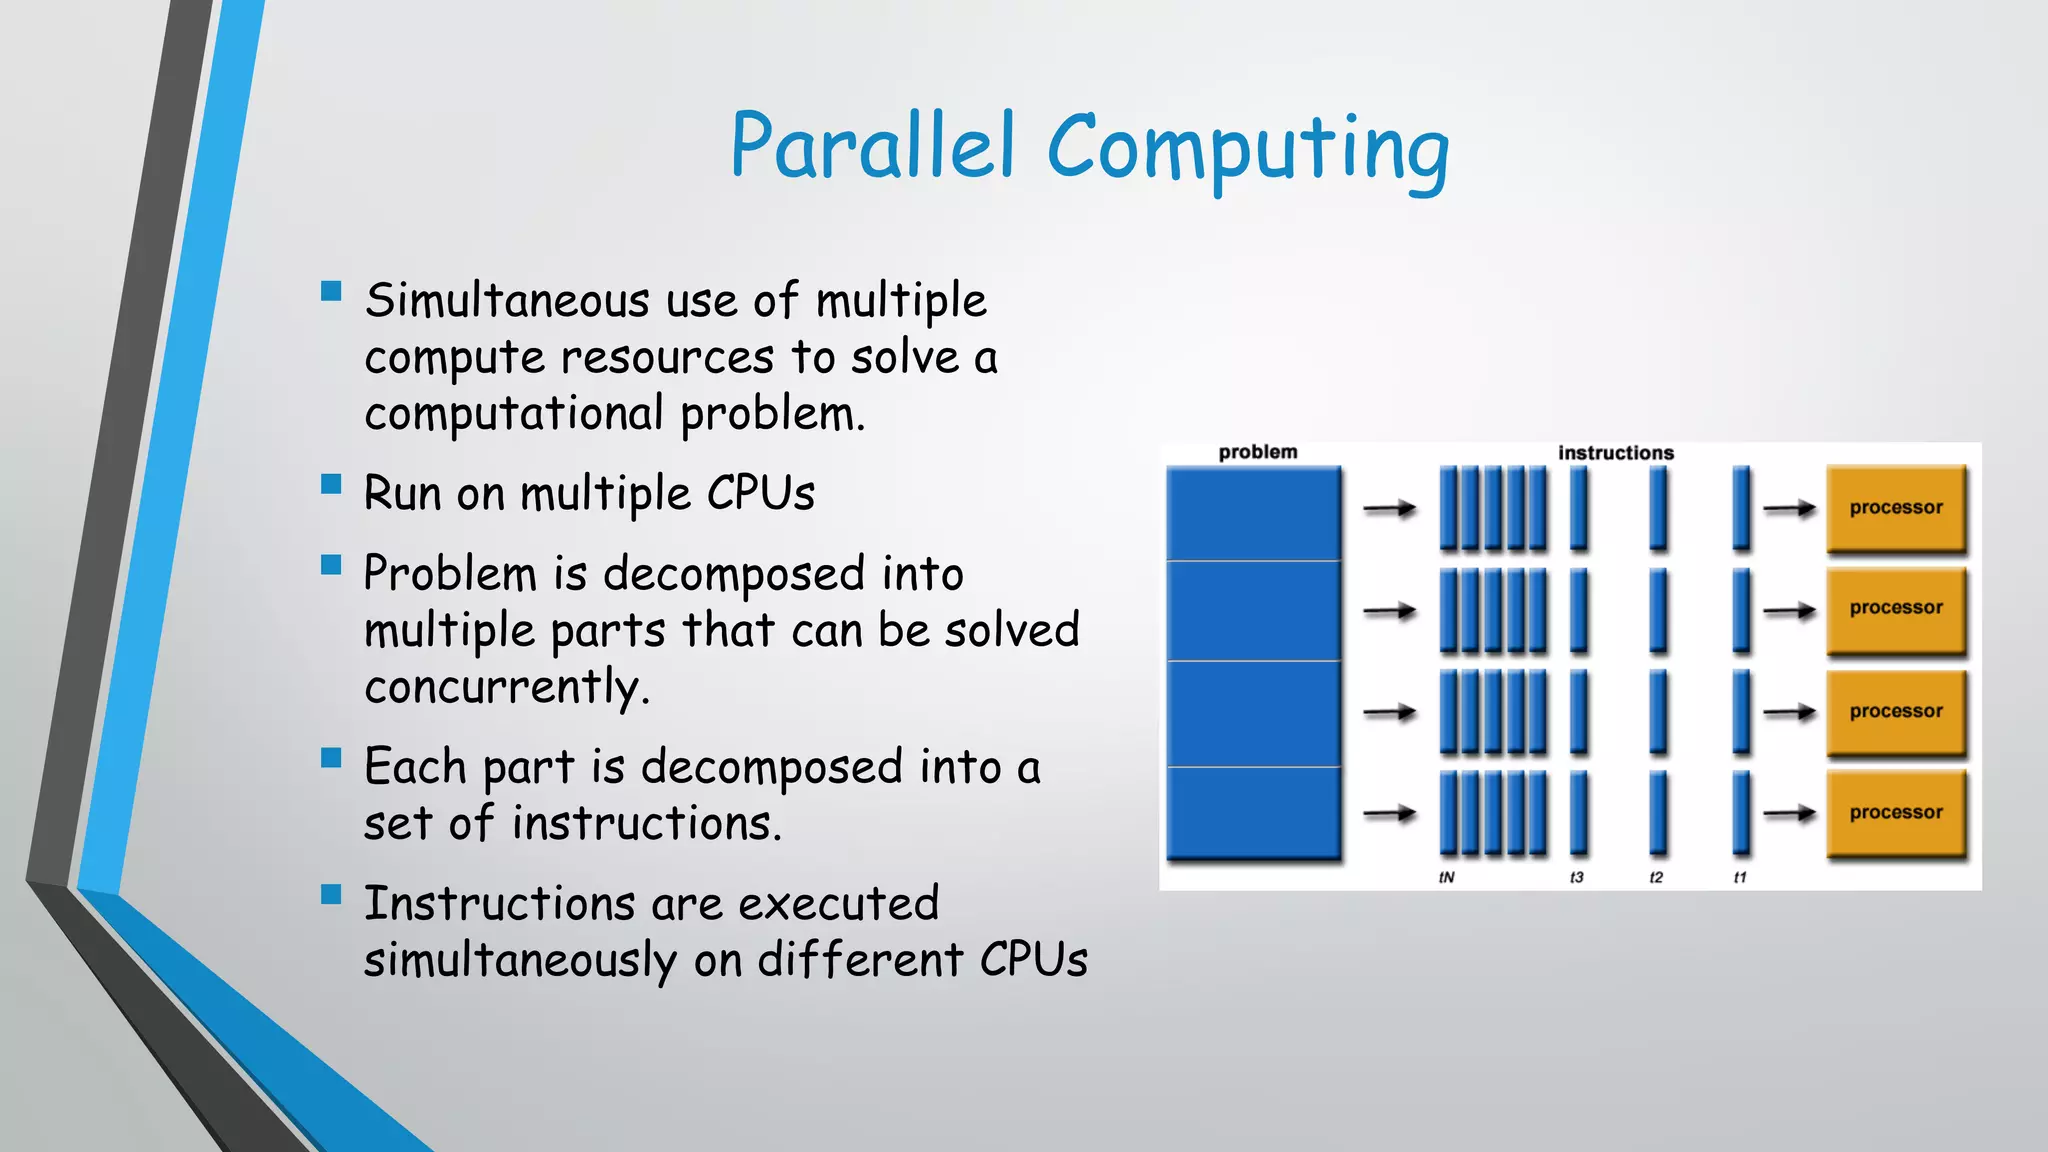
I spent three weeks last winter debugging a race condition in a C program that was supposed to process sensor data across eight cores. The bug only appeared when we ran it on actual hardware, never in testing. Turns out two threads were writing to the same cache line because I hadn't thought about false sharing. That kind of thing will test your patience regardless of how much experience you have. Parallel computing in C means splitting work across multiple threads or processes so they execute simultaneously. The standard way to do this is with POSIX threads, commonly called pthreads. You can also use OpenMP as a lighter-weight alternative if your compiler supports it, which most do these days. A third option is MPI for distributed systems, but that's overkill for machines with multiple cores on a single node. The basic structure is simple enough. You create threads, assign each one a chunk of work, and join them when they finish. The tricky part is making sure threads don't step on each other's data. That's where synchronization primitives come in: mutexes, semaphores, condition variables, and barriers.
Here's a minimal working example that spawns three threads to sum parts of an array: #include <stdio.h>
#include <pthread.h>
#include <stdlib.h>typedef struct {
long *data;
int start;
int end;
long result;
} ThreadData;
void *worker(void *arg) {
    ThreadData *td = (ThreadData *)arg;
    for (int i = td->start; i < td->end; i++)
        td->result += td->data[i];
    return NULL;
}
int main() {
int n = 1000000;
long *data = malloc(n * sizeof(long));
for (int i = 0; i < n; i++) data[i] = i;
    int num_threads = 4;
    pthread_t threads[num_threads];
    ThreadData tdata[num_threads];
    long chunk = n / num_threads;
Get the Full Details

    for (int i = 0; i < num_threads; i++) {
        tdata[i].data = data;
        tdata[i].start = i * chunk;
        tdata[i].end = (i == num_threads - 1) ? n : (i + 1) * chunk;
        tdata[i].result = 0;
        pthread_create(&threads[i], NULL, worker, &tdata[i]);
    }
    long total = 0;
    for (int i = 0; i < num_threads; i++) {
        pthread_join(threads[i], NULL);
        total += tdata[i].result;
    }
    printf("Total: %ld\n", total);
    free(data);
    return 0;
}
Compile with -pthread and run it. On my machine with four logical cores, this finishes in about 2 milliseconds for a million integers. Serial version takes roughly 7 milliseconds. The speedup isn't dramatic here because the workload is trivial, but the pattern scales when your actual computation is heavier. One thing beginners consistently miss is that thread creation has overhead. Spawning and joining threads costs time. If your per-thread work takes less than a few hundred microseconds, you might be better off sticking with a single thread. I ran into this on a project processing small JSON objects where each task took maybe 50 microseconds. Using eight threads was actually slower than using two because the scheduling overhead dominated. Stick with one thread per core for tiny tasks. Let the OS scheduler handle it. Mutexes are your primary tool for protecting shared state, but they're also a performance killer if you use them wrong. Every lock acquisition and release involves a syscall and possible context switch. If you find yourself locking a mutex inside a tight loop, you're probably doing it wrong. Instead, restructure your code so each thread works on private data and only synchronizes once at the end. That's called reduction, and it applies to summation, finding maxima, and similar operations.
Another counter-intuitive point: more threads isn't always faster. Running sixteen threads on an eight-core machine doesn't give you twice the throughput. You'll get diminishing returns after matching your thread count to your physical cores, and often you'll go slower due to cache thrashing and context switching. I learned this the hard way on a matrix multiplication benchmark where I launched thirty-two threads on an eight-core Xeon. Performance dropped by forty percent compared to eight threads. Profile before you parallelize. Use tools like valgrind/callgrind or perf to see where your bottlenecks actually are. Data alignment matters more than people expect. When two threads write to different variables that happen to share the same cache line, you get false sharing. The cache line bounces between cores and performance tanks. Align your per-thread data structures to at least the cache line size, which is typically 64 bytes. The __attribute__((aligned(64))) specifier in GCC or Clang handles this cleanly. For heavier numerical work, consider OpenMP. It lets you parallelize loops with a single pragma directive instead of managing threads by hand:

#pragma omp parallel for reduction(+:total) Compile with
for (int i = 0; i < n; i++) total += data[i];-fopenmp. It's less flexible than raw pthreads but dramatically reduces the chance of bugs. I switched a financial simulation from pthreads to OpenMP and cut the implementation time from five days to half a day. The performance was comparable because the compiler was doing the same scheduling decisions anyway. The honest downsides of parallel C programming are real. Race conditions are non-deterministic and can disappear under stress testing, showing up only in production under load. Deadlocks happen when threads acquire locks in inconsistent order. Memory management gets harder because you need to think about ownership and lifetime across threads. C gives you enough rope to hang yourself, and parallelism just gives you more rope.
If your problem involves a lot of locking, you might be better off restructuring it as a message-passing design instead. Tools like Actor frameworks or even a simple lock-free ring buffer can avoid contention entirely. For GPU work, OpenCL or CUDA would be the direction to go rather than trying to force everything through CPU threads. Start small. Parallelize one loop at a time. Measure before and after. Keep thread counts at or near your core count. Avoid locking hot paths. These habits will save you far more time than any advanced technique.