What People Actually Mean When They Say "Phonetics"
Most beginners come at this backwards. They think phonetics is about figuring out how to pronounce words correctly for a foreign language. It isn't. It's the physical study of speech sounds as acoustic events — air moving through vocal tracts, frequencies hitting a microphone, spectrograms showing energy distribution. You can do phonetics without speaking another language. You can also do it terribly and still sound perfectly fine speaking English. I learned this the hard way in 2019 when I spent three weeks trying to transcribe Welsh vowel lengths using an IPA chart designed for English. The narrow transcription came out nonsense because I kept applying English stress rules to a language that doesn't use them the same way. The fix was switching to a fieldwork handbook — Chodok's Field Manual for Phonology — and spending two days just recording the contrastive patterns before opening any transcription software. Took me from week three back to day one, but at least the data was usable after that.
Introduction To Phonetics: The Actual Starting Point
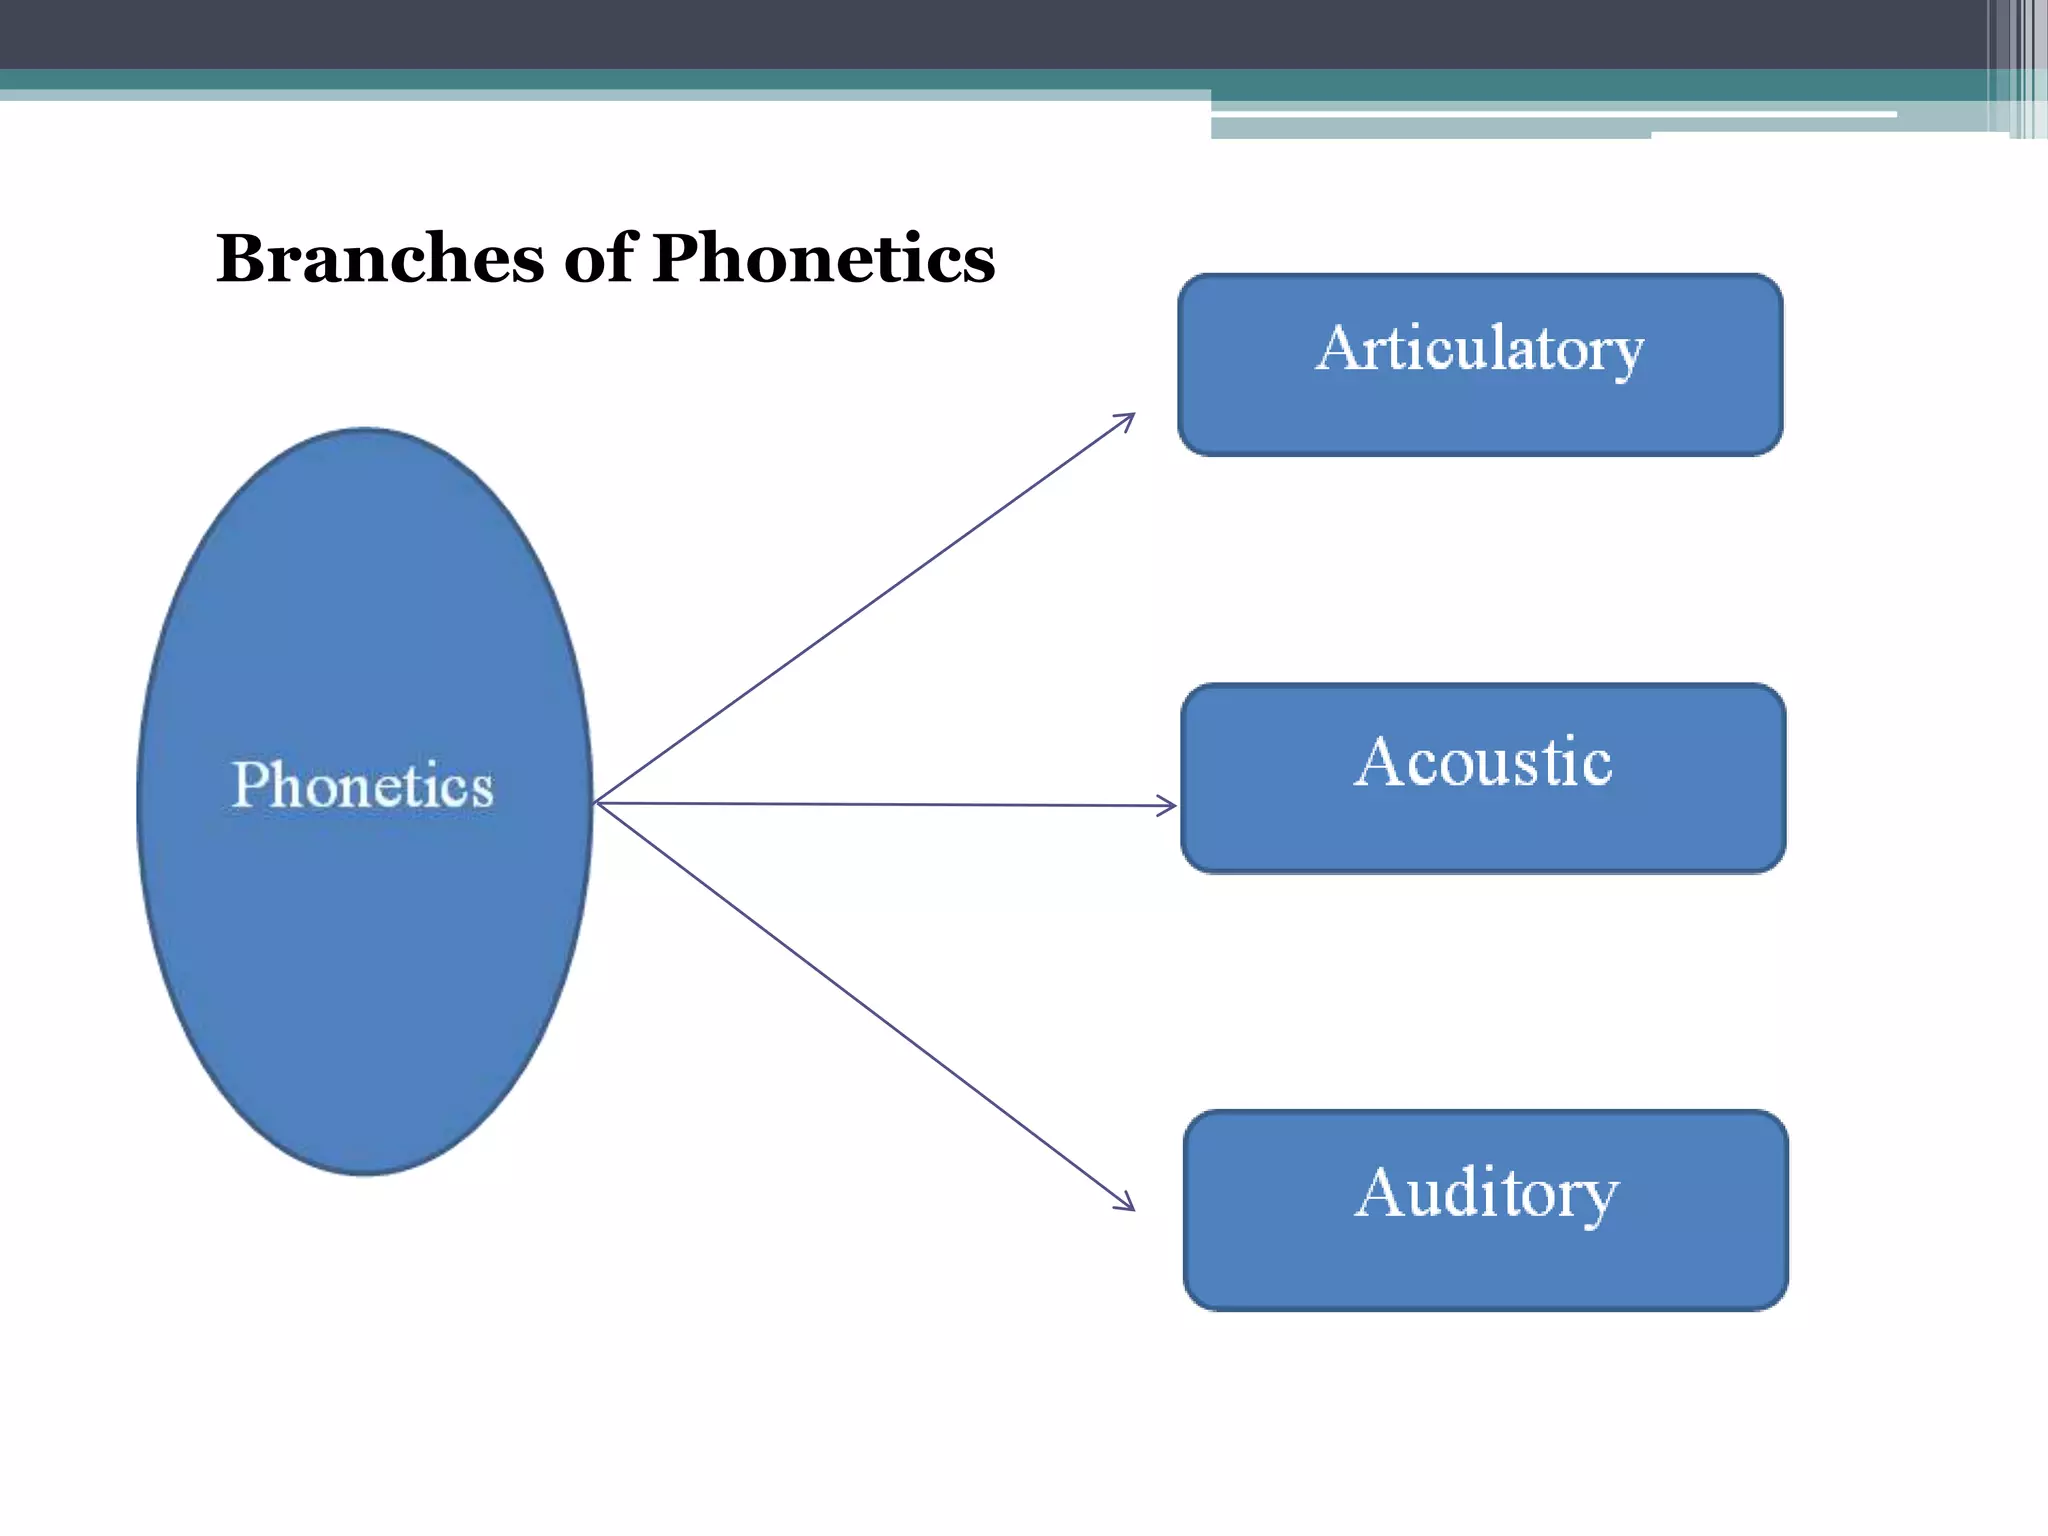
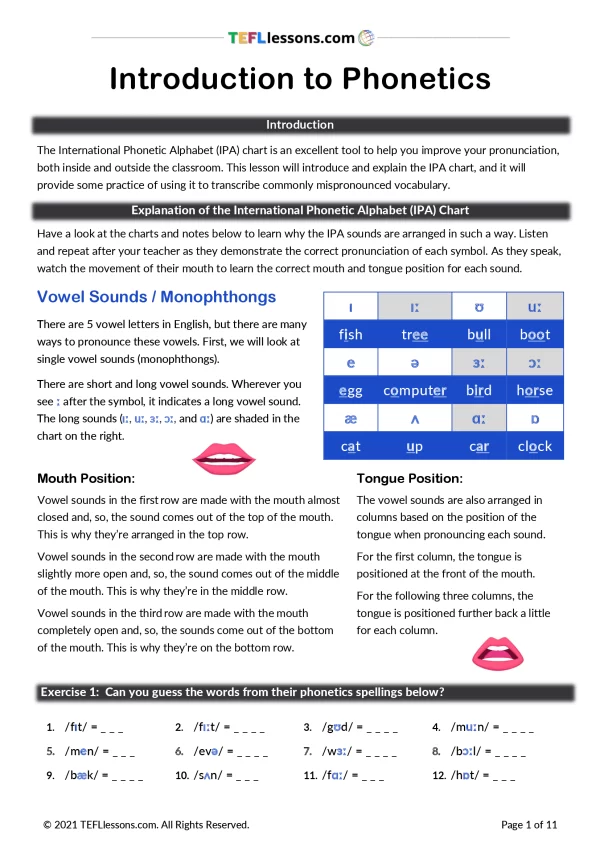
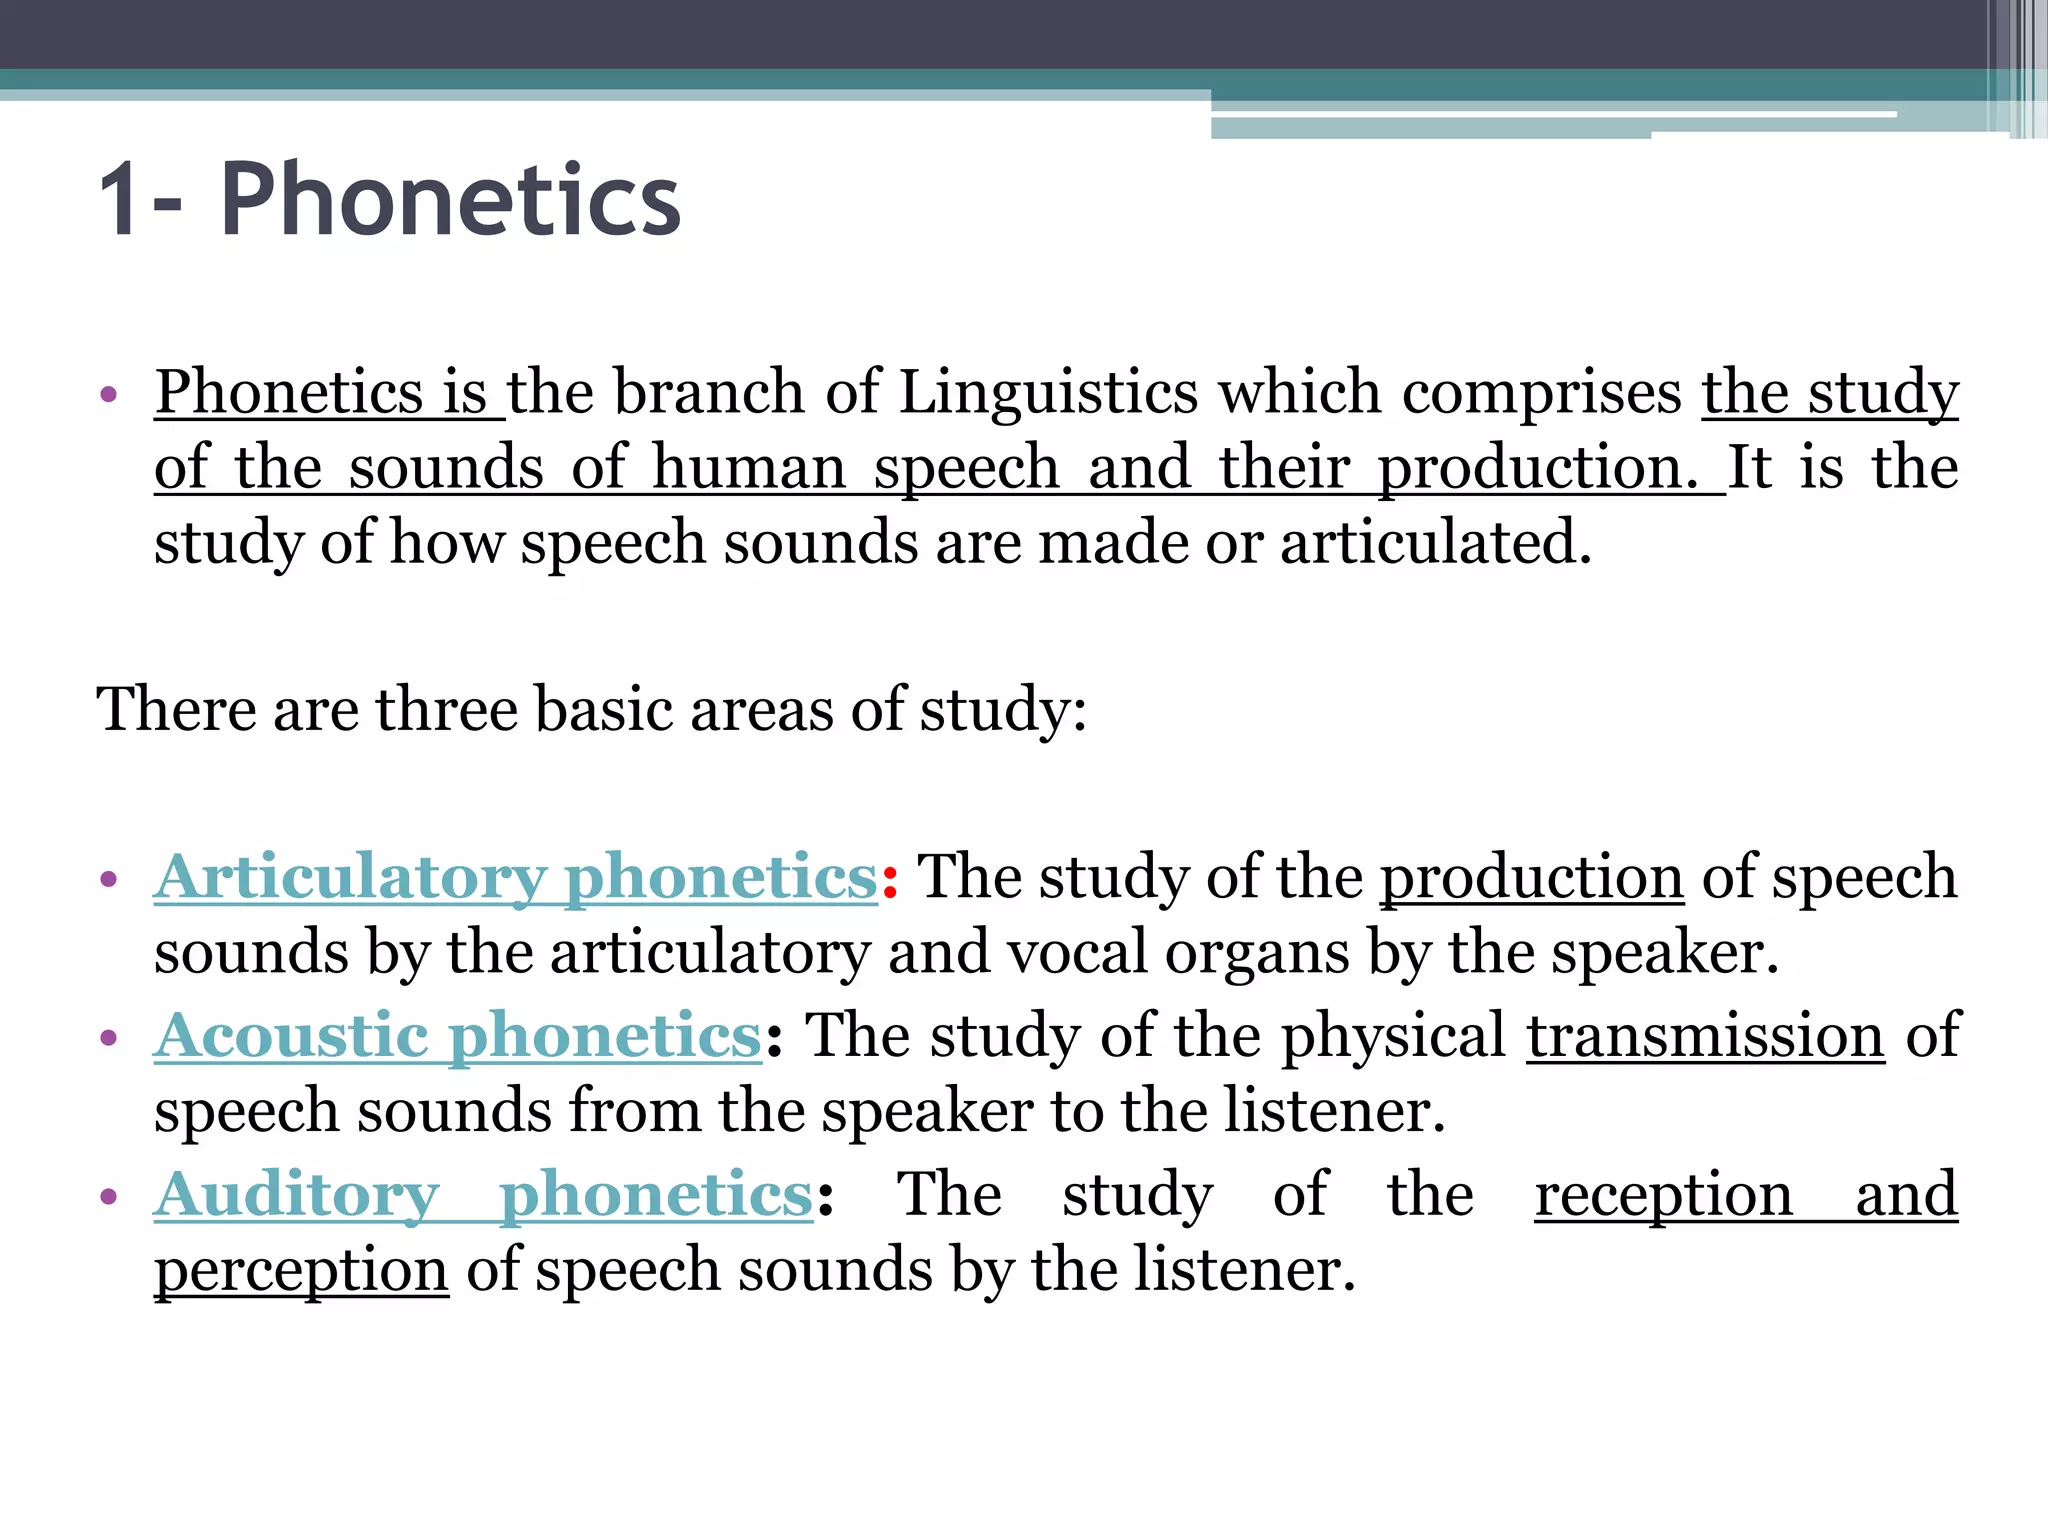
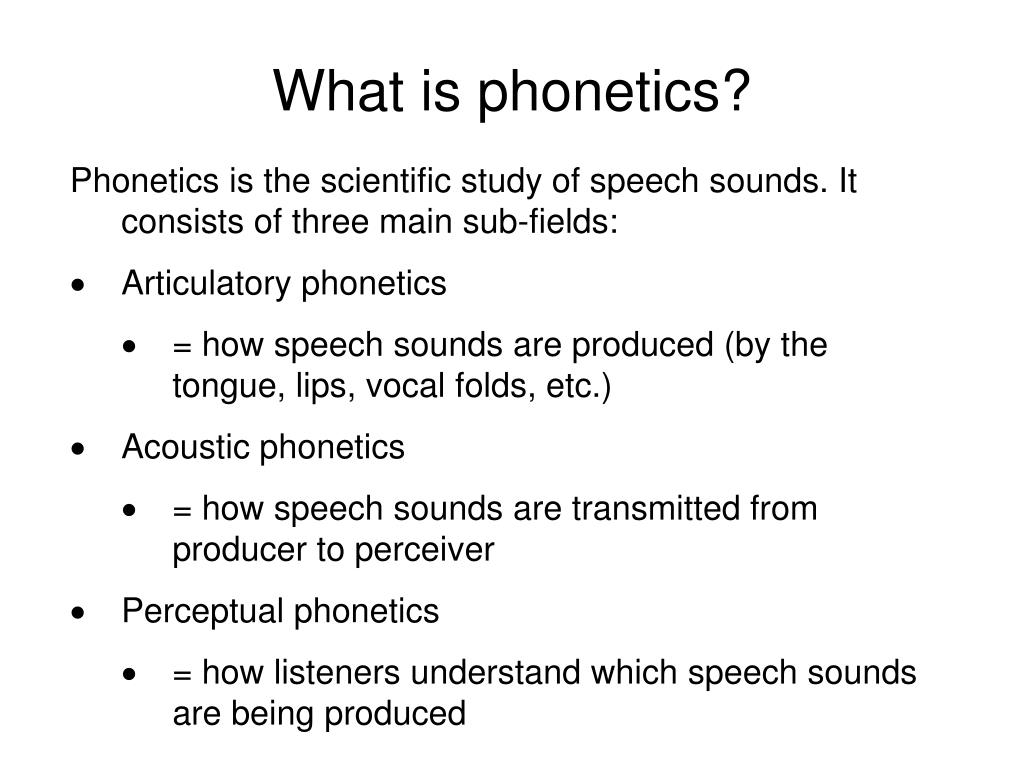
Phonetics breaks speech into three stages. Articulatory phonetics looks at where the tongue, lips, and vocal folds are. Acoustic phonetics measures the sound waves — frequency, amplitude, duration. Auditory phonetics studies how the ear and brain process those waves. Most people start with articulatory because it's the most tangible. You can feel your own vocal cords vibrate by touching your throat while saying "zzzz" versus "ssss." That's phonetics. Nothing mystical about it. The IPA, or International Phonetic Alphabet, is the standard notation system. It maps one symbol to one sound. English spelling makes this impossible — "through," "tough," and "cough" share no audible pattern but are often glossed over in casual instruction. The IPA doesn't have that problem. The symbol // is always the voiceless interdental fricative. Always. No exceptions built into the alphabet itself.
Getting Your First Spectrogram Working
You need Praat. It's free, it runs on Windows and macOS, and it's been the fieldwork standard since the late nineties. Download it from the official site. Install it. Open it. Record yourself saying "ba" then "pa" with a two-second pause between. Save the wavefile. Load it into Praat. Select the "View & Edit" option. You'll see a waveform — a squiggly line going up and down. That's amplitude over time. Click "To Spectrogram." A color heatmap appears below it. Darker areas show concentrated energy at specific frequencies. The vertical axis is frequency in Hertz. The horizontal axis is time. That's all a spectrogram is — a map of where the sound's energy lives across frequencies as it unfolds. Here's what most tutorials don't tell you: the default settings will lie to you. Praat's default window length is 0.005 seconds. That's fine for vowel formants. It's garbage for plosive bursts. Change it to 0.002 for stop consonants like /p/ and /t/. You'll see the transient energy spike that the default setting smooths away. I spent months wondering why my spectral analysis of Mandarin affricates looked muddy before someone pointed out the window length issue. Five minutes of configuration saved me months of confusion.
Get the Full Details
Articulatory Phonetic Features: The Useful Way to Categorize Sounds
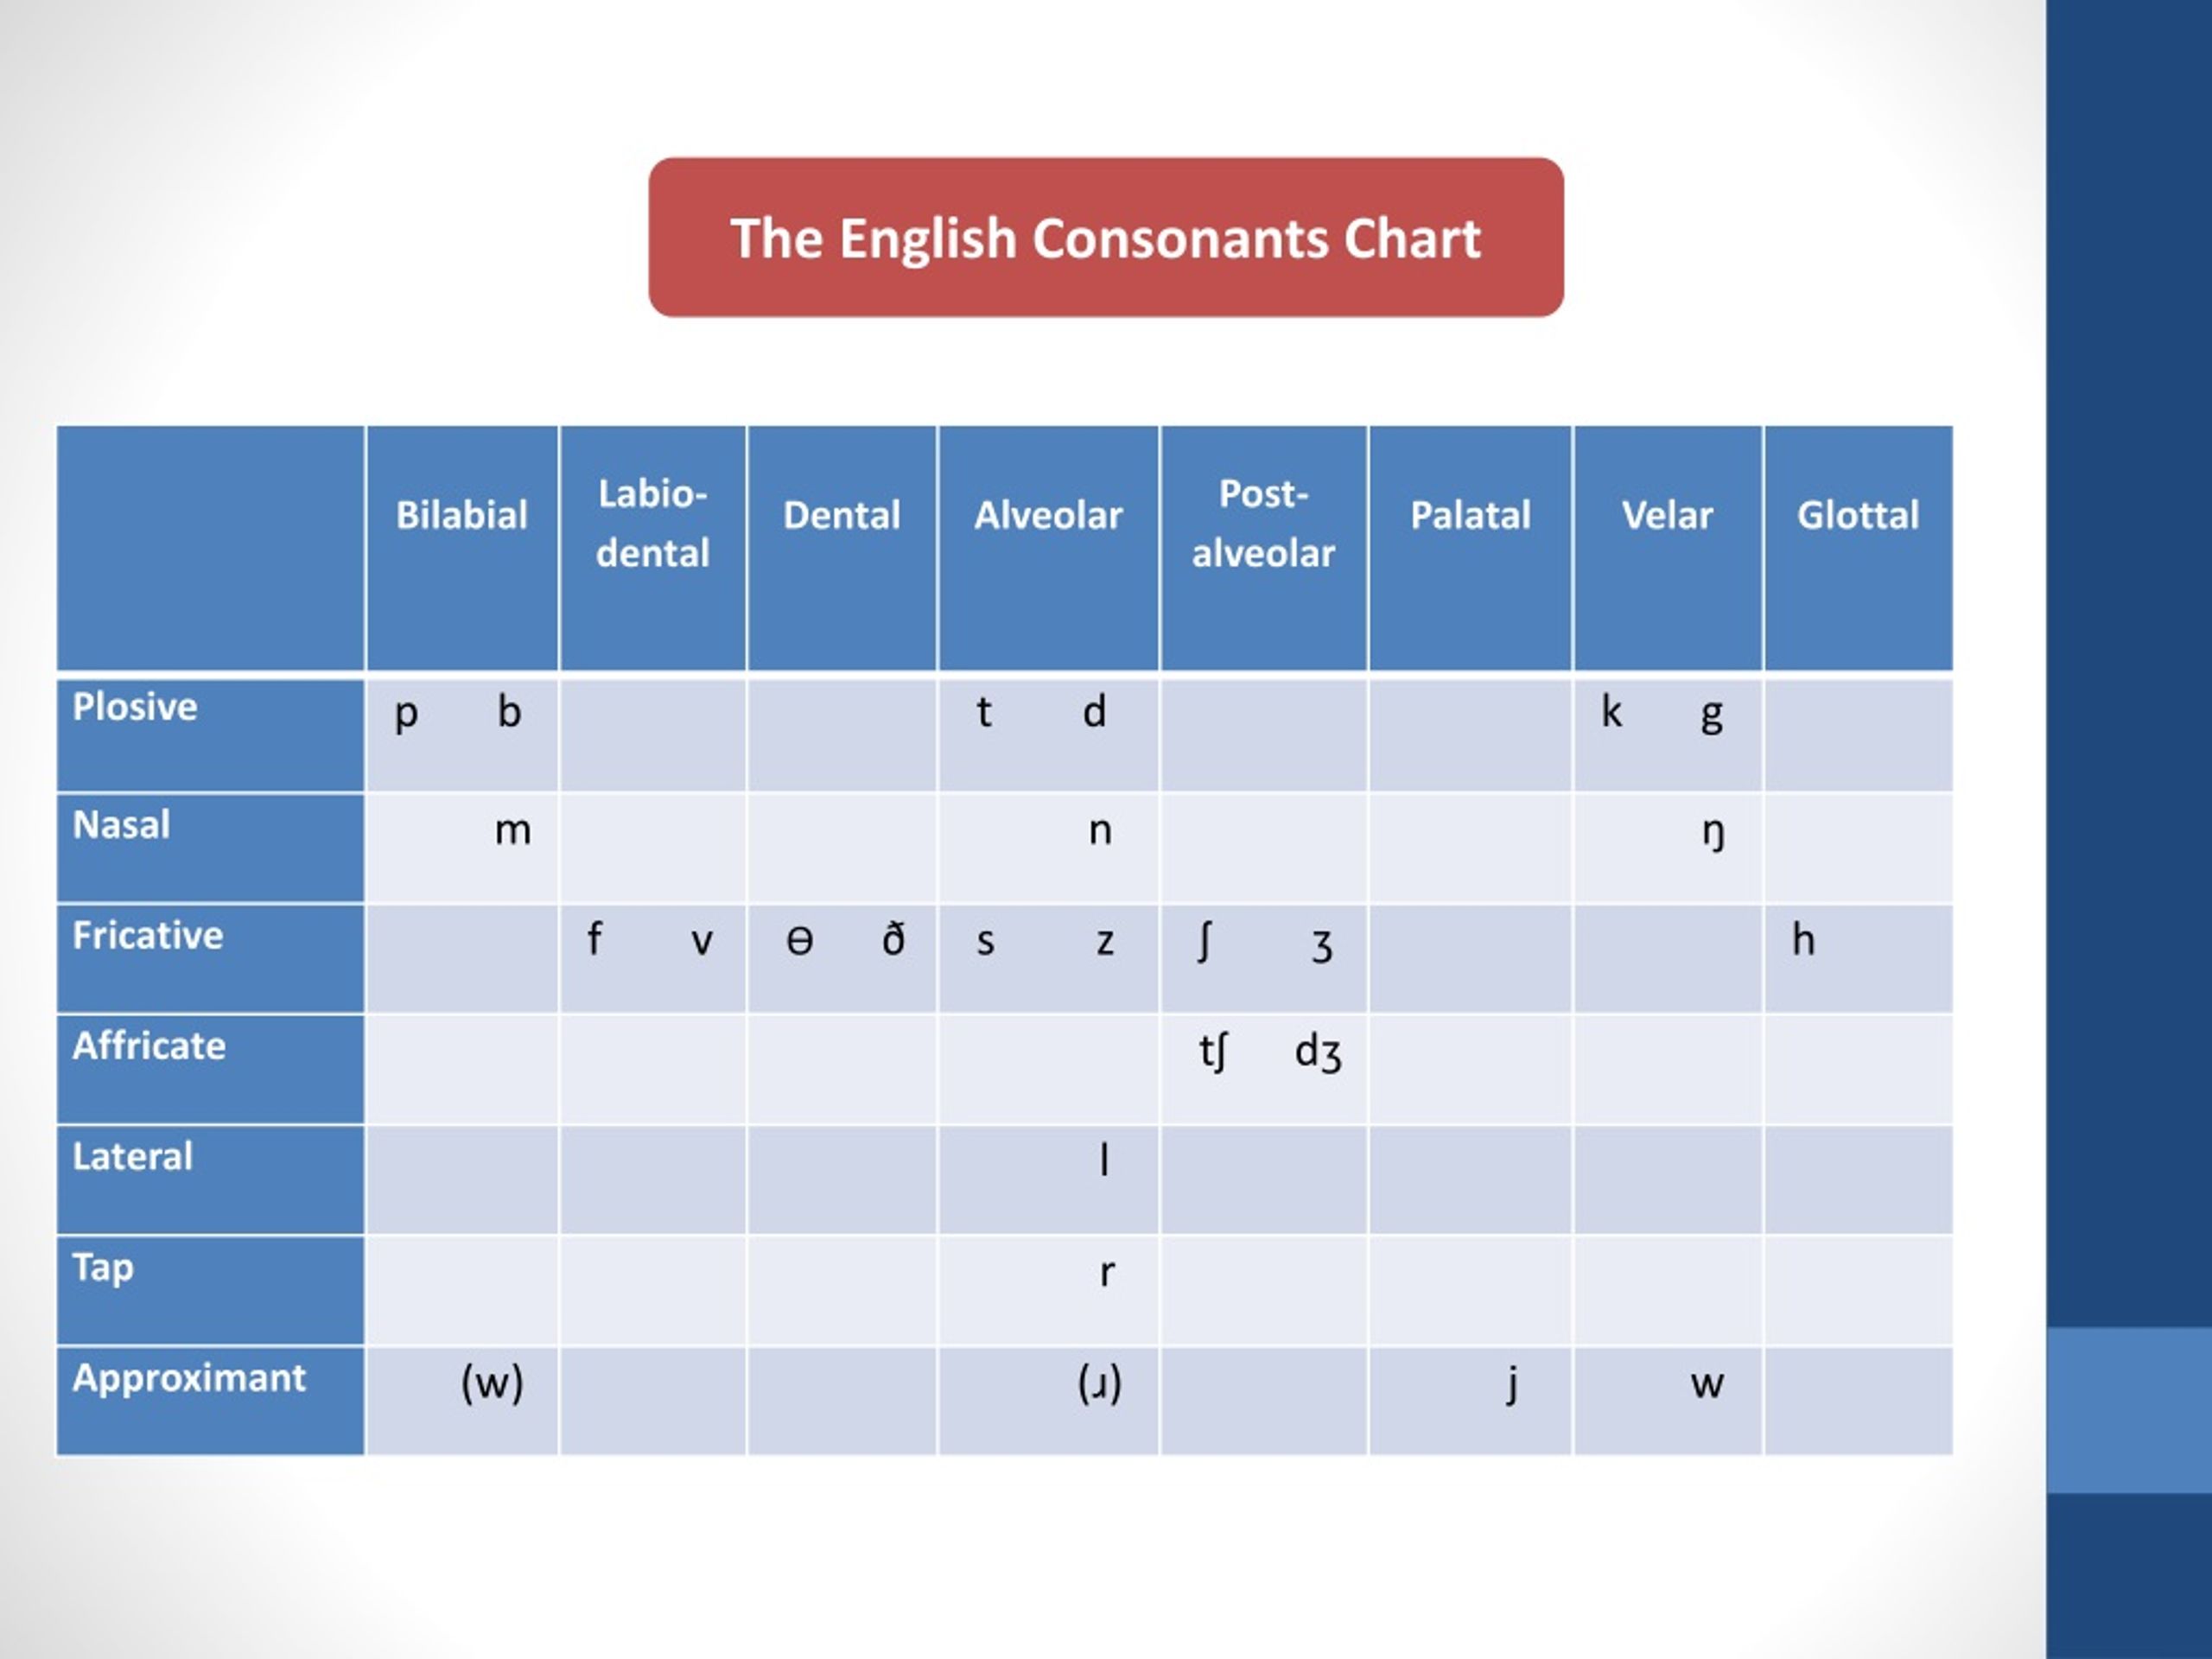
Don't memorize every IPA symbol at once. Learn the feature matrix. Every consonant has three values: place of articulation (where the constriction happens), manner of articulation (how the airflow is modified), and voicing (whether vocal folds vibrate). A /b/ is bilabial, plosive, voiced. A /f/ is labiodental, fricative, voiceless. That's it. Every consonant in every language fits into this grid. Vowels work differently. There's no constriction to measure. Instead you track formant frequencies — F1 and F2. F1 inversely correlates with tongue height. F2 correlates with tongue frontness. A high front vowel like /i/ has low F1 and high F2. A low back vowel like // has high F1 and low F2. Measure those two formants and you've located the vowel in phonetic space. Everything else — roundedness, tenseness, length — is secondary detail. The trap beginners fall into is trying to hear these differences before they can see them. They listen to a recording and say "that sounds different" without being able to point to what's actually different on the spectrogram. Train your eyes before your ears. Look at F1 and F2 values for five minutes. Then listen. The auditory distinction becomes obvious once you know what physical parameter changed.
Common Mistakes That Waste Time
Recording quality is the #1 source of bad data. A laptop built-in microphone will add noise floor and roll off high frequencies above 8 kHz. That's fine for general listening. It destroys your ability to analyze fricatives — /s/ and // differ mainly in high-frequency energy above 4 kHz. If your mic cuts off at 8 kHz, those two sounds look identical in the spectrogram. Use an external USB mic. The Behringer U-Phoria UM2 costs about forty dollars and changes everything. I've seen students spend weeks on analysis projects only to realize their equipment was the bottleneck. Equipment cost: minimal. Time lost: entire semester. Another mistake: transcribing everything you hear instead of only the contrastive units. Phonetics is not about capturing every breath sound and lip smack. It's about documenting the sound categories that distinguish meaning in the language you're studying. If your language doesn't contrast /r/ and /l/, transcribing both is noise. Focus on phonemic contrasts. Everything else is phonetic detail that doesn't affect the analysis. Auditory training without visual verification is the third trap. You can convince yourself you hear a tonal difference that isn't there. The spectrogram doesn't lie. Pitch contours show up as visible frequency tracks. If you can't see the contour on the spectrogram, you're probably imagining it. Trust the image. Your ears will catch up eventually.
Practical Workflow for a Basic Phonetic Analysis
Set up your recording environment. Quiet room. No running fans or air conditioners. Hold the mic six inches from the speaker's mouth. Record at 44.1 kHz minimum — 48 kHz is better. Save as WAV, uncompressed. MP3 adds artifacts that corrupt formant measurements. Load into Praat. Split into individual tokens. Select each token. Generate a pitch contour and a formant track. Export F1 and F2 measurements as a text table. Open that table in Excel or R. Calculate mean and standard deviation for each vowel category. Plot F1 against F2 on a scatter graph. The vowel space should take shape — front vowels clustering left, back vowels right, high vowels low on F1, low vowels high on F1. If your vowel space looks weird — say, front and back vowels overlapping completely — check your formant normalization. Raw F1 and F2 values vary by speaker anatomy. A tall man with a long vocal tract has lower formants than a small woman. Use the Lobanov or Nearey normalization method to account for this. Normalize before comparing across speakers. This step usually takes ten minutes and prevents hours of confused interpretation later.
For consonant analysis, focus on the voice onset time for stop consonants. Measure the interval between the burst release and the onset of vocal fold vibration. Voiced stops like /b/ have near-zero or negative VOT. Voiceless stops like /p/ have positive VOT around 50 to 100 milliseconds. Aspirated /p/ stretches that to 150 milliseconds or more. Measure these intervals directly on the waveform. Don't estimate by ear. The differences are often smaller than you think — 30 milliseconds separates a voiced from a voiceless stop in many languages, and that's half the duration of a single frame at 44.1 kHz sampling rate.
When Phonetics Fails You
Sometimes the data just won't cooperate. Certain languages have pharyngealized or ejective consonants that don't fit neatly into standard articulatory descriptions. Some tones have microtonal variations below the resolution of typicalPraat pitch tracking. Vowel nasalization creates formant coupling effects that standard linear prediction struggles with. In these cases, you need specialized tools — X-SAMPA for broader transcription coverage, or moving to tools like Wavesurfer for manual annotation when Praat's automated segmentation fails. There's also the limit of what acoustic analysis can tell you. Two sounds can have nearly identical spectrograms but feel completely different to a native speaker. Articulatory gestures, not just acoustic outputs, drive phonological contrast. If you need to explain why speakers perceive two acoustically similar sounds as distinct, you need electromyography or MRI data — stuff most of us never touch. For practical fieldwork, knowing where acoustic analysis hits its ceiling is as important as knowing how to use it.