Research Methods In Education Won't Save Your Thesis
You spend three weeks deciding between mixed methods and qualitative design, then realize your actual data is garbage because you didn't pre-register anything. This happens constantly. I watched a colleague lose six months of fieldwork because his sampling frame was drawn from school rosters that hadn't been updated since September, meaning roughly 23% of his "participants" had transferred out before he even sent the first email. That's not a theory problem. That's a methods problem. At its core, this field is about building a defensible chain from a research question to evidence that actually supports an answer. The chain has links. The links are things like operationalization, sampling strategy, measurement validity, and data analysis plan. Break one link and the whole thing collapses under peer review. Most people treat these as steps in a recipe. They're not. They're constraints that interact with each other in ways that textbooks rarely show clearly. Take random assignment. Everyone knows it from introductory stats. In education research, true random assignment is rare outside of tightly controlled lab-style studies with individual students. Most classroom-level work uses intact groups, which means you're working with quasi-experimental designs. That changes everything about how you analyze the data and how you frame causal claims. You can still publish strong work here. You just can't claim causation the way you would with proper RCTs, and you need to understand exactly what that limitation means for your argument.
I ran into this directly during a district-level study on literacy intervention effects. We had randomized students within schools to treatment and control conditions, which sounded solid on paper. The problem was that teachers knew which students were in their intervention group and adjusted their day-to-day instruction accordingly. Students in the control condition got more individualized attention from their general Ed teacher because the teacher knew they weren't getting the program support. Our intent-to-treat analysis showed a smaller effect than the treatment actually produced. The contamination between groups diluted the measured impact by roughly 40%. What we should have done was cluster-randomize at the teacher level, not the student level. We caught this after data collection was already underway. You can't fix that retroactively. Quantitative and qualitative approaches exist on a spectrum, not as separate rooms. Descriptive statistics, regression models, factor analysis, structural equation modeling, multilevel modeling, and time-series analysis are all quantitative tools. Each handles different data structures and different types of research questions. Multilevel modeling, for instance, is almost essential for education research because students are nested within classrooms, classrooms within schools, schools within districts. Running ordinary regression on that data violates independence assumptions and gives you inflated significance. That's not advanced methodology. That's basic correctness. Qualitative work in education tends to involve interview protocols, thematic analysis, grounded theory, ethnography, and case study design. The mistake most beginners make is treating qualitative analysis as "just coding transcripts." It's more structural than that. You need a coding framework, inter-coder reliability checks if you have multiple coders, an audit trail, and a strategy for handling disconfirming cases. Ignoring disconfirming cases is the fastest way to write something that looks like advocacy rather than research.
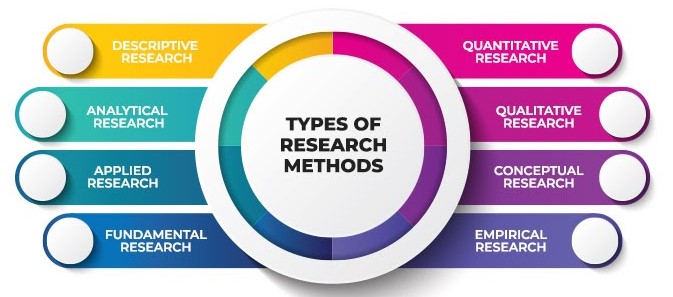
Here's a counter-intuitive point that doesn't get enough attention: bigger samples don't fix bad measures. I've seen studies with N equals 2,000 where the dependent variable was a single self-reported question about student engagement. The standard error was tiny. The measure was useless. A well-designed study with N equal to 80 using validated instruments will produce more trustworthy findings than a massive study built on improvised metrics. Always check the psychometric properties of your instruments before you worry about power calculations. Another thing people miss is the difference between statistical significance and practical significance. In large education datasets, a program effect of 0.08 standard deviations can be statistically significant at p less than .001. That's not a meaningful impact on student outcomes. It's noise dressed up in confidence intervals. Always report effect sizes alongside p-values. Hedge's g, Cohen's d, eta-squared, and explained variance ratios tell you whether a finding matters. The p-value only tells you whether the finding could have occurred by chance under your model assumptions, which is a much narrower question. When you move into research design, you'll encounter terms like exploratory, descriptive, correlational, experimental, quasi-experimental, and longitudinal. Exploratory research asks "what's going on here?" Descriptive research asks "what is the state of things?" Correlational research asks "are these variables related?" Experimental and quasi-experimental designs ask "does X cause Y?" Longitudinal research asks "how do things change over time?" Each design type has specific threats to validity. Internal validity, external validity, construct validity, and statistical conclusion validity are the four categories you need to know. Confusing them leads to design flaws that no amount of statistical adjustment can repair.
Get the Full Details
Documentation matters more than most students expect. A methods section in education research should contain enough detail that another researcher could replicate your study. That means specifying your sampling procedure, your inclusion and exclusion criteria, your instrument sources, your data collection timeline, your codebook or coding scheme, your software and version numbers, and your analytical decisions. Vague methods sections get desk-rejected. I've seen proposals turned down because the authors wrote "we conducted interviews" without specifying how many, with whom, how long they lasted, or how the data were analyzed. That's not enough information to evaluate anything. IRB approval is a real constraint in education research. If your study involves minors, you need parental consent and student assent in most cases. If you're studying sensitive topics like disciplinary practices, academic dishonesty, or mental health, the review process gets longer and more rigorous. Budget time for this. IRB turnaround can range from two weeks for exempt classification to three months for full board review. Designing around IRB requirements often shapes your methodology more than the research question itself. People who ignore this end up with approved protocols that don't match what they actually collected, which is a compliance issue that can invalidate your entire dataset. Data management in education studies is messier than in most other social science fields. You're dealing with school records, attendance data, standardized test scores, grades, behavioral referrals, survey responses, interview recordings, and observation notes. Some of these come in different formats. Some require data use agreements. Some can't leave the school district's secure servers. I once spent four days just reconciling two attendance datasets from the same school because one used fiscal year dates and the other used academic calendar dates. That's not glamorous, but it's where real research happens.
For learning these methods, start with actual methodology textbooks rather than YouTube summaries. Books like Creswell and Creswell's Research Design, Palinkas et al.'s handbook on mixed methods in education, and Hox, Moerbeek, and van de Schoot's Multilevel Analysis cover the material thoroughly. Online resources like the American Educational Research Association methodology tutorials and the National Center for Education Statistics training modules are useful supplements. Don't skip the exercises. Reading about multilevel modeling won't teach you multilevel modeling. Running simulated data through HLM or R's lme4 package will. The field has genuine limitations. Education research operates in complex human systems where you can't control every variable. Effect sizes tend to be smaller than in laboratory psychology. Longitudinal studies suffer from attrition rates that can exceed 30% over three years. Policy changes mid-study can invalidate your comparison groups. Funding cycles pressure researchers into quick, shallow studies rather than careful, thorough ones. None of these are excuses for poor methodology. They're just realities you need to plan for. If you want a practical starting point for applying these methods, the R package lavaan handles structural equation modeling for education data, lme4 covers multilevel modeling, and qualR packages like tm and quanteda support text analysis for qualitative coding workflows. SPSS and SAS remain common in institutional settings, though they lag behind open-source tools in flexibility. Stata is widely used in economics-of-education research specifically because of its causal inference packages.
The bottom line is that research methods in education are tools, not truths. They help you reduce uncertainty. They don't eliminate it. The best studies I've read acknowledged their limitations explicitly, reported their methods with surgical precision, and let the data speak within the bounds of what their design could actually support. Everything else is packaging.