Building a spreadsheet that doesn't break when someone changes a cell it shouldn't touch
Most people build investment models by stacking formulas downward until they reach a total return number, then they stare at it and hope it's right. That works fine for a quick personal comparison. It breaks hard when you hand it to someone who doesn't know Excel, or when you need to run sensitivity tables across five different scenarios at once. The actual work is in the structure, not the math. Start with three sections and don't mix them. Inputs on the left or top, calculations in the middle, outputs on the right or bottom. I keep inputs in a column labeled clearly with the assumption behind each number. If you just label a cell "Revenue Growth" and put 8% in it, you'll forget whether that means compound annual growth or total over the period within six months. Add a short text note next to every input. It takes twelve extra seconds per cell and saves you an hour of re-deriving your own assumptions later.
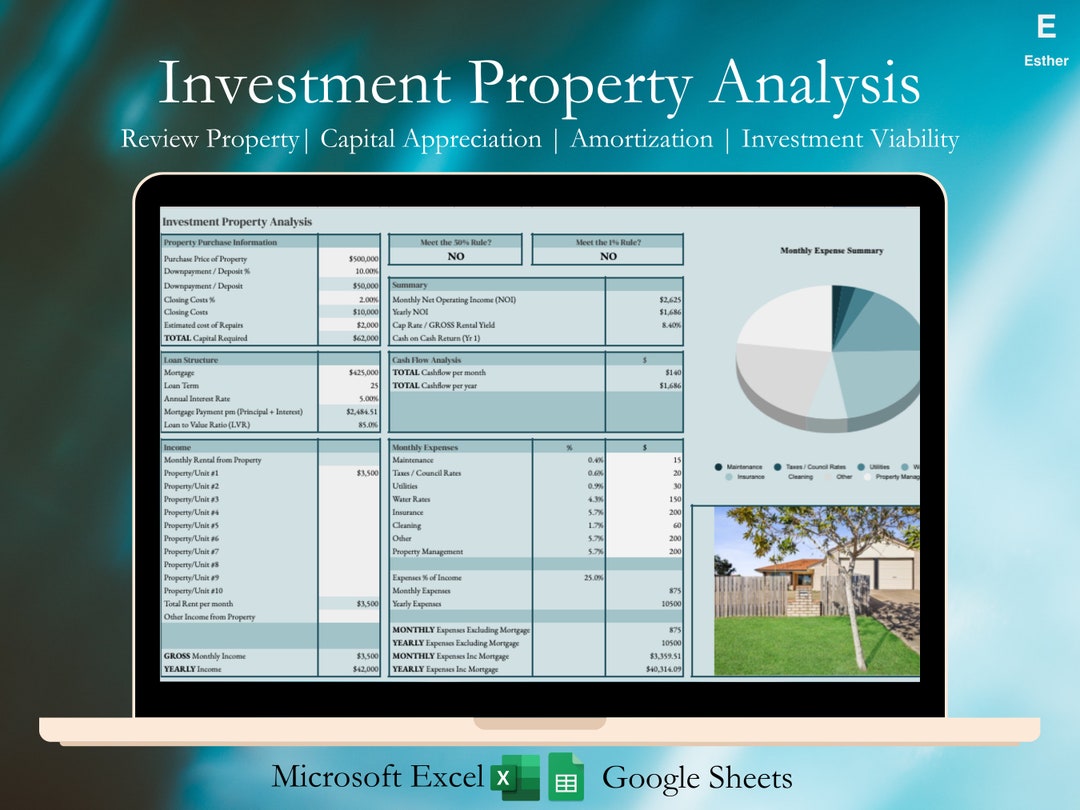
Investment Analysis Spreadsheet Structure
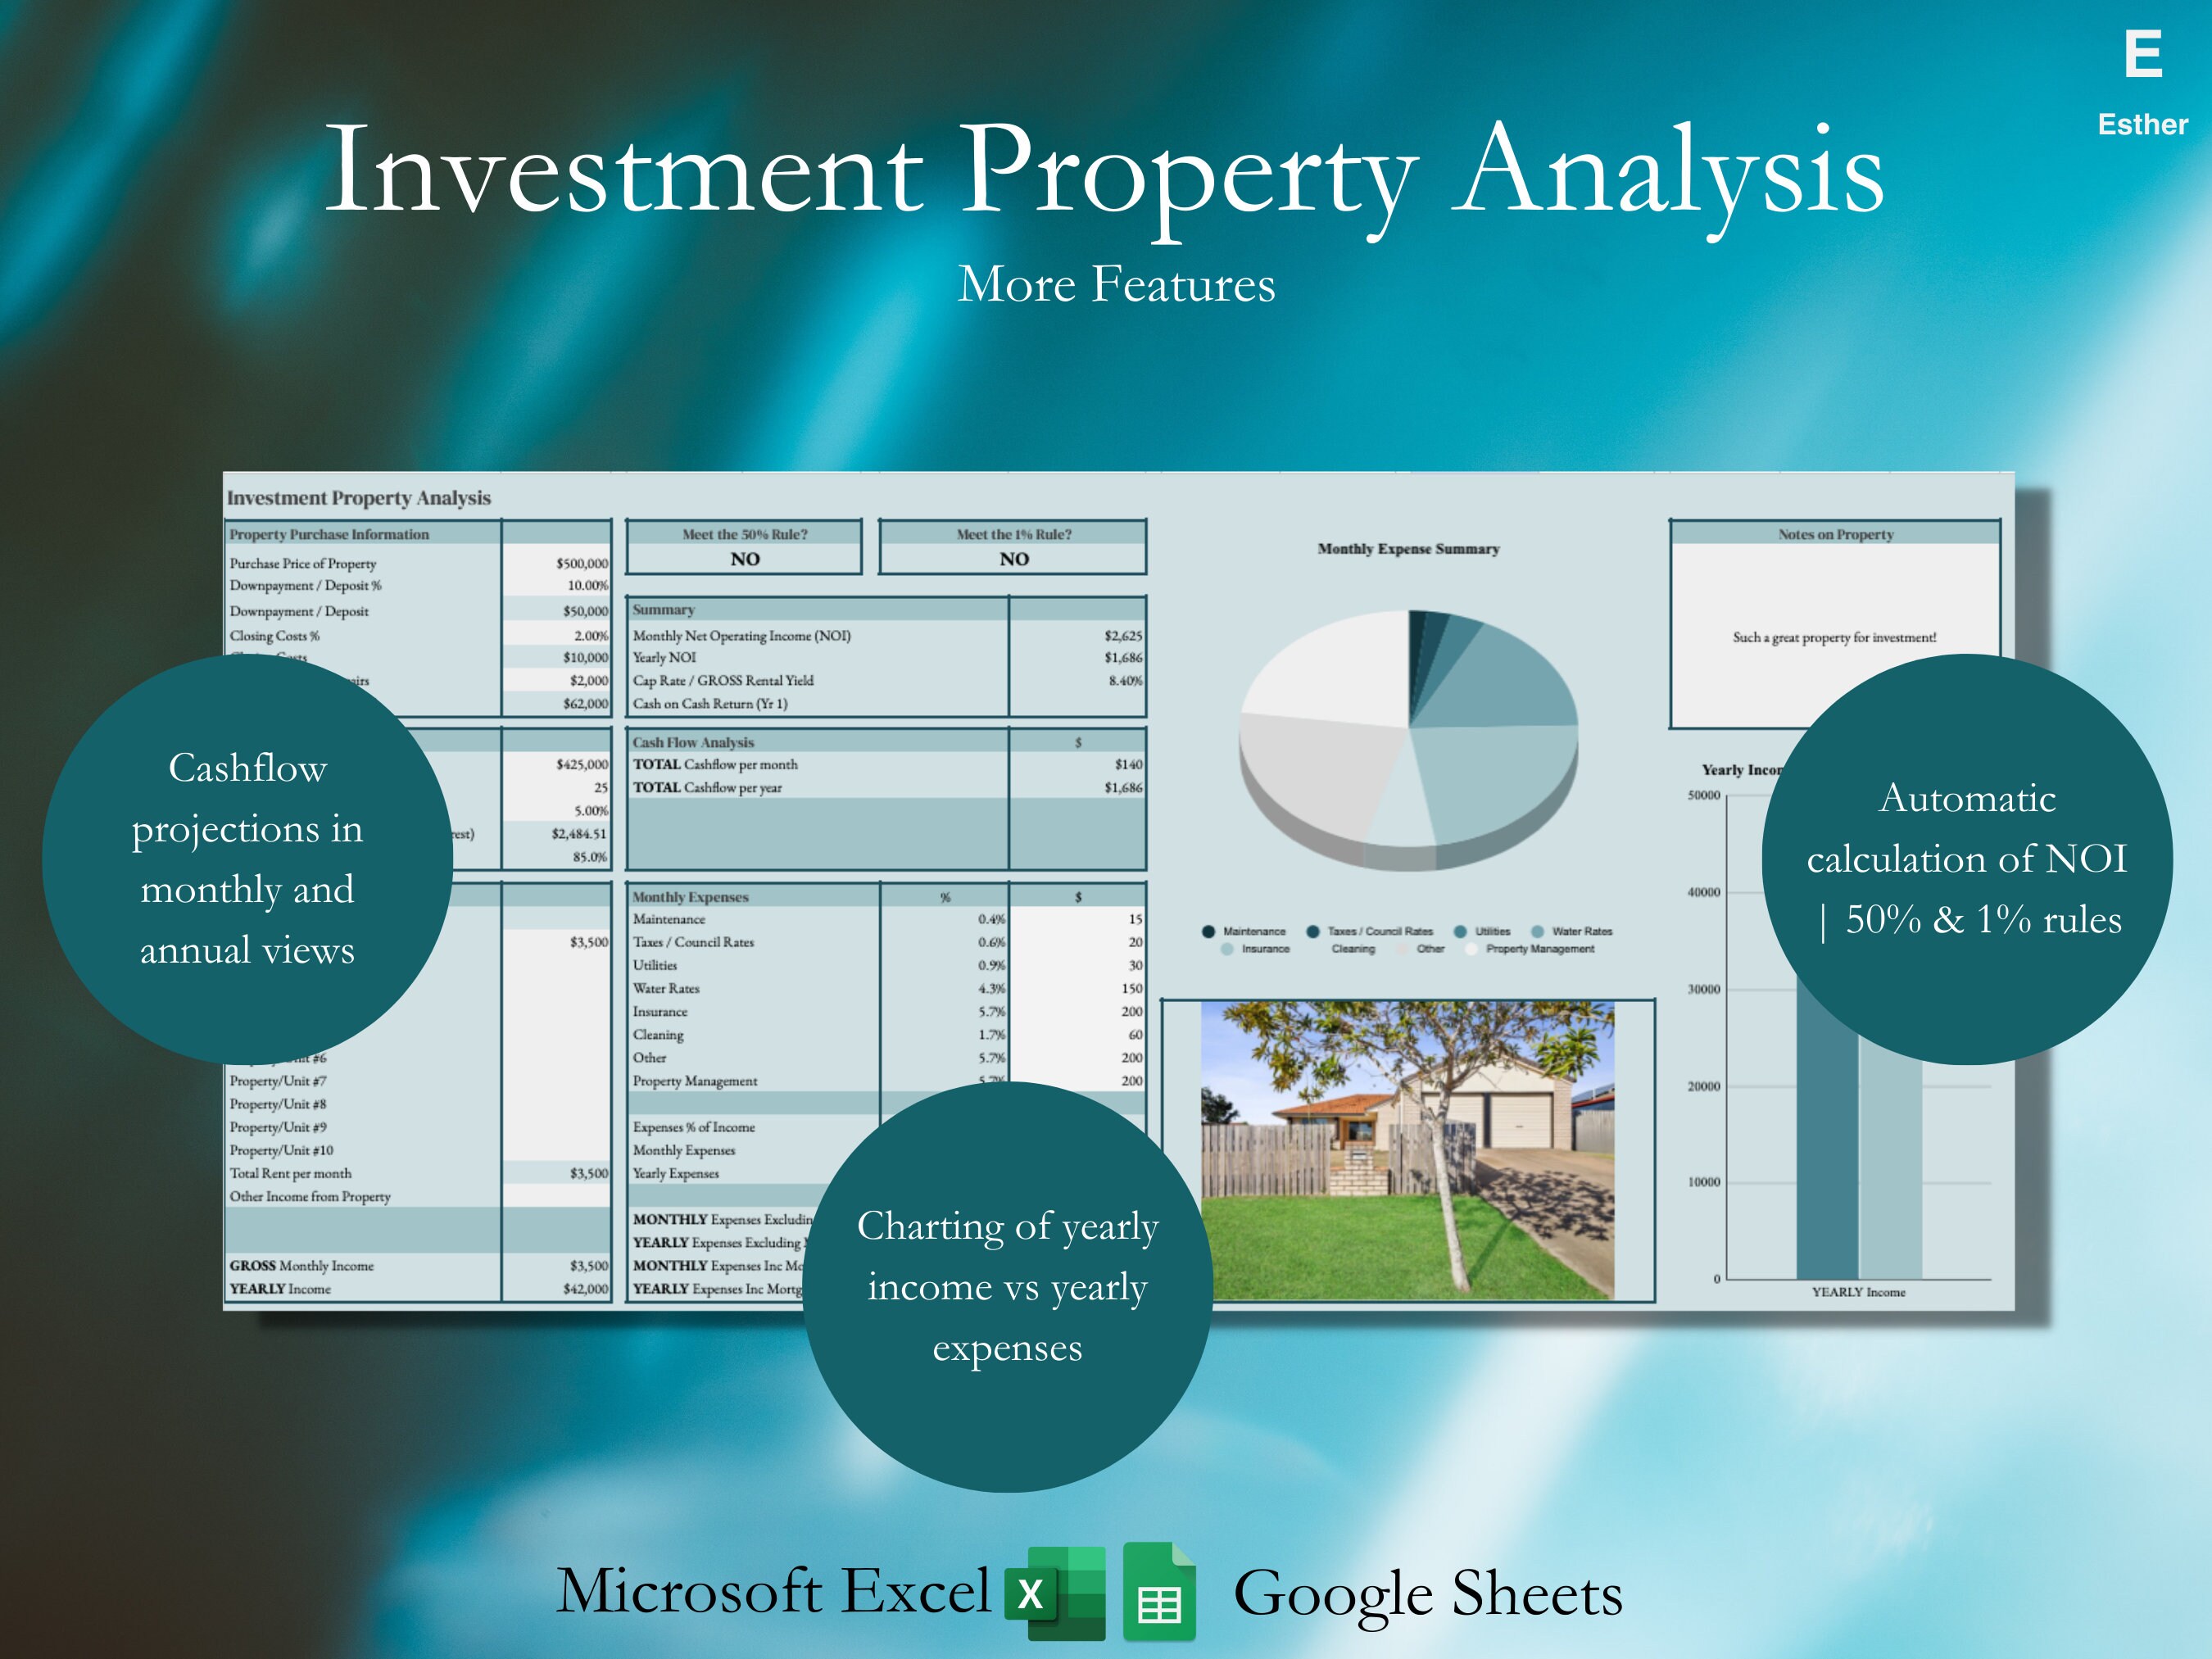
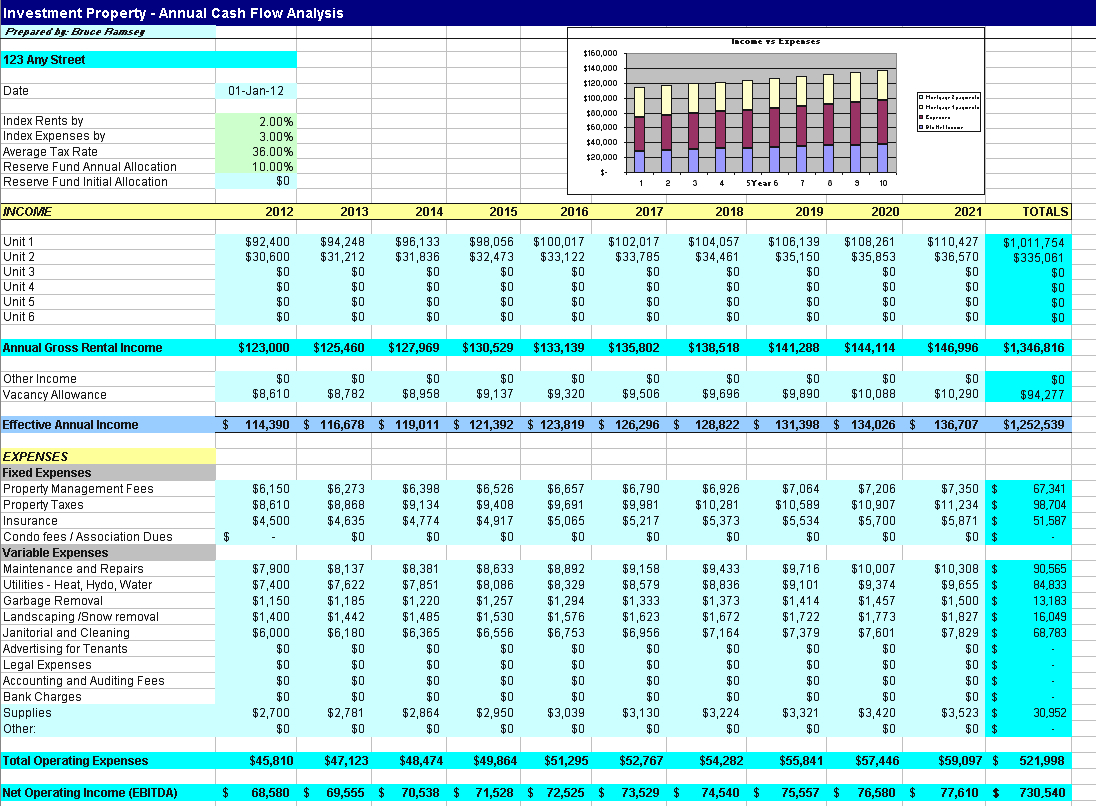
Here's the layout I actually use, not some textbook version: Row 1 through row 8: assumptions and input parameters. These are the only cells with hardcoded numbers. Everything below pulls from this block. Row 10 through row 40: the income statement bridge. Revenue minus cost of goods, operating expenses, depreciation, interest, taxes. Keep it simple enough that you can verify each line by hand in under a minute.
Row 42 through row 55: cash flow schedule. This is where most people make mistakes. They forget working capital changes and assume free cash flow equals net income divided by something. It doesn't. Working capital eats cash in the early years of any project, and it shows up as a negative line item that makes your returns look worse than they are on paper. Row 57 through row 65: NPV, IRR, payback period, and profit factor. Four metrics, not eight. More metrics don't make the model better. They just give you more numbers to argue about in meetings. The first real problem you'll hit is circular references. Your interest expense depends on your debt balance, which depends on your financing plan, which depends on your cash position, which depends on your debt service. Excel handles this with iterative calculation turned on, but turning it on silently is dangerous because you'll get a wrong answer without knowing it's wrong. Turn it on, set maximum iterations to one, and force yourself to restructure the loop by calculating debt service in a separate schedule that feeds back into the cash flow section instead of nesting it inline. This usually cuts debugging time from four hours down to forty minutes.
Get the Full Details
I once built a model for a mid-market acquisition where the working capital assumption was keyed to revenue days sales outstanding, but the seller's historical DSO varied wildly by quarter. I used a simple average and the NPV came out to positive six million. When I rebuilt it with a quarterly rolling DSO schedule pulled from the actual historical pattern, the NPV dropped to negative two hundred thousand. Same inputs, same discount rate, completely different decision. This happened because the spreadsheet rounded away the asymmetry in the cash conversion cycle. The fix was to stop using a single working capital assumption and instead build a monthly schedule tied to the actual receivables and payables drivers. Another thing nobody tells you about IRR: it assumes reinvestment at the internal rate, which is almost never realistic. If your model spits out a forty percent IRR on a project with uneven cash flows, that number is meaningless. Use modified internal rate of return instead, with a reinvestment rate tied to your actual cost of capital. Most people don't do this because Excel doesn't have a built-in MIRR function that feels intuitive. The function exists. Set the finance rate to your WACC and the reinvestment rate to something conservative like seven percent. The difference between IRR and MIRR on a typical ten-year infrastructure project is usually two to five percentage points, and that gap is exactly what separates a good deal from a bad one.
The part that actually takes time
Sensitivity tables. You need to know what breaks the model. Run a two-variable data table with discount rate on one axis and revenue growth on the other, covering the range of values your assumptions could realistically take. This usually takes twenty minutes to set up if you've already got the base case clean. The result is a heat map that shows you where your NPV crosses zero. That crossing point is more valuable than the base case number itself. It tells you the minimum revenue growth or maximum capex you can absorb before the deal stops working. Don't build a three-dimensional sensitivity analysis in the first draft. Beginners love adding complexity. A third variable creates a matrix Excel can't render cleanly and makes the model unreadable for anyone who isn't the person who built it. Two variables is the maximum before the output loses practical value. If you need more, use a scenario manager with named sets of inputs and switch between them. This adds about thirty seconds of work per scenario toggle but keeps the spreadsheet from turning into a spreadsheet. Download links are useless unless the file actually opens correctly and doesn't contain broken formulas. I'm not going to post a link to something I haven't tested in the last six months. What I can do is describe the exact structure so you can replicate it. Build a sheet called Assumptions. Build a sheet called Financials. Build a sheet called Sensitivity. Build a sheet called Summary. That's four sheets. Anything more in the first version is scope creep.
Format inputs with a light blue fill so anyone opening the file knows which cells they're allowed to change. Format outputs with a white fill. Format intermediate calculations with no fill. This visual distinction prevents people from accidentally overwriting your derived numbers, which is the most common cause of spreadsheets producing silently wrong results. One more thing. Your discount rate matters more than you think, and most people pick it by copying what their colleague used last year. If you're evaluating a private investment with illiquid cash flows, use a higher discount rate than your public equity cost of capital. A typical adjustment is plus three to five percentage points for illiquidity, plus another one to two points for the specific risk profile. This is ugly, unglamorous, and necessary. Models built with an arbitrary discount rate tend to approve too many marginal projects because the math makes them look better than they are. The spreadsheet itself will fail you in exactly three situations. First, when the cash flow pattern changes mid-model and you hardcoded a formula referencing a cell that no longer exists. Second, when someone copies the model to a new workbook and the relative references shift in ways you didn't expect. Third, when the time horizon extends beyond sixty periods and cumulative rounding errors become visible in the final row. For the first two, use absolute references sparingly but consistently, and name your key ranges. For the third, validate the final year by recalculating it manually in a separate scratch area.
There's no shortcut around the manual check. A spreadsheet will compute faster than you can reason through a problem, which means it will also convince you of wrong answers faster. Spend the first fifteen minutes verifying every formula by hand against a worked example before you trust any output.