What Amino Acids Actually Are
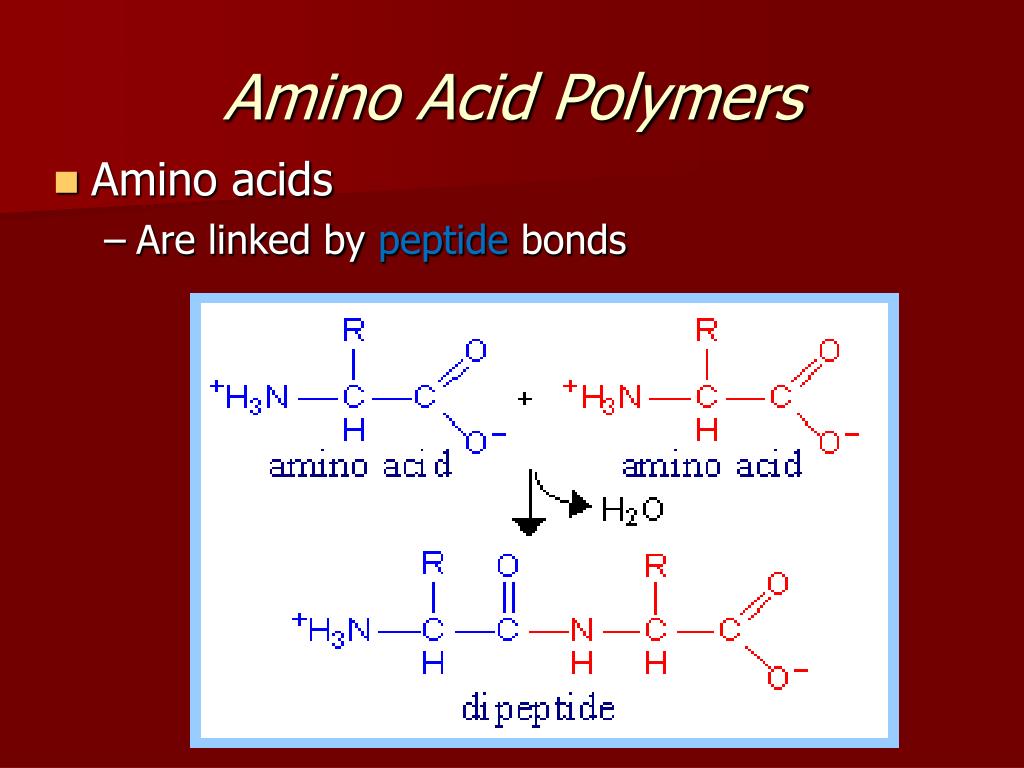
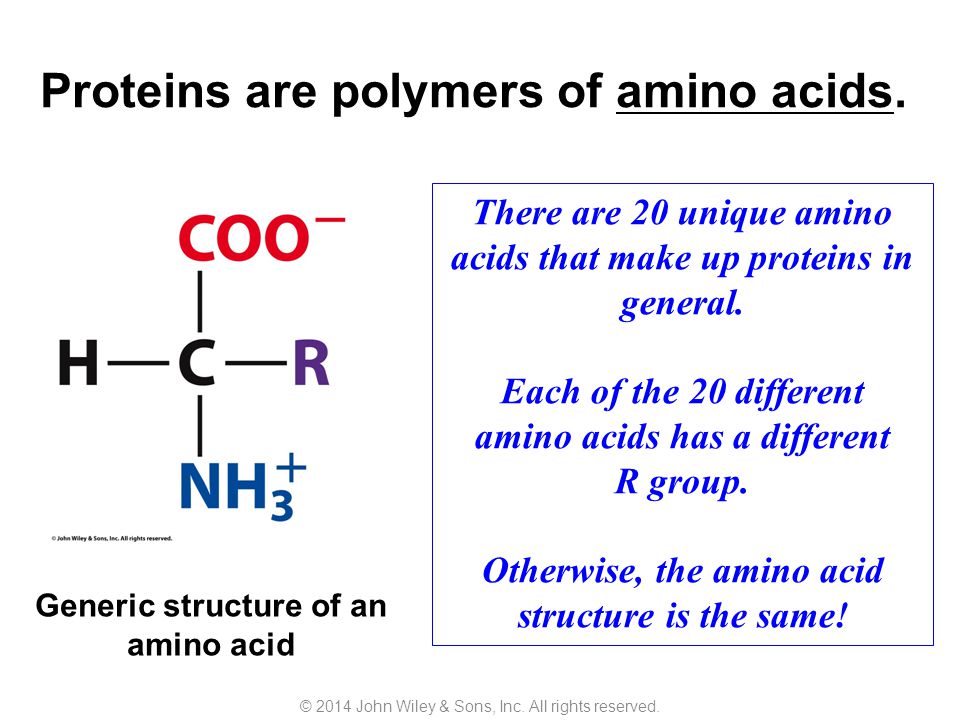
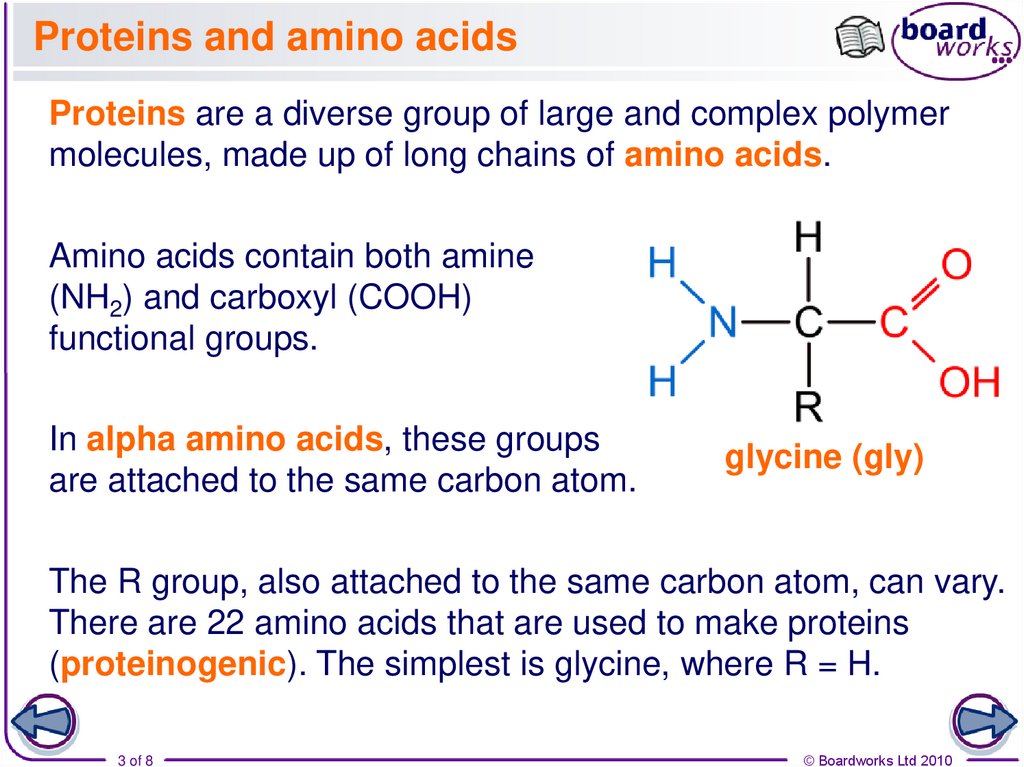
Amino acids are small organic molecules. Twenty-two standard ones exist in biology, each built around a central carbon bonded to an amino group, a carboxyl group, a hydrogen atom, and a variable side chain. That is the complete structure. Nothing more elaborate than that. They are not polymers. They are the monomeric building blocks that get linked together through peptide bonds to form polypeptides and proteins. Confusion usually comes from seeing amino acid sequences in literature and assuming the word "polymer" applies at the residue level. It does not.
Is Amino Acid A Polymer
No. An amino acid is a monomer. When you see something described as an amino acid polymer, what people actually mean is a polypeptide or protein chain — a covalently bonded string of amino acid residues. The terminology matters because peptide chemistry, degradation behavior, and analytical methods all shift depending on whether you are working with single residues or a connected chain. I once spent three days troubleshooting a GPC separation that refused to produce consistent molecular weight readings. The sample looked clean on TLC. The mass spec confirmed the expected monomer mass. Then I realized the compound in question was a short oligopeptide — a heptamer — and my calibration standards were all calibrated for discrete amino acids, not for peptide chains of that length. The stationary phase interaction was dominated by the amide backbone, not the side chains, so the elution order made no sense against a monomer reference set. I re-calibrated with a polyethylene glycol standard and ran a peptide-specific method instead. That took about forty minutes and solved the problem completely. There are a couple of things beginners consistently get wrong about this distinction. One is assuming that because amino acids can self-assemble or stack via non-covalent interactions, they qualify as polymers. Hydrogen bonding, pi-stacking, and hydrophobic collapse are real phenomena — amino acid side chains absolutely do these things — but none of them convert a monomer into a polymer. A polymer requires covalent repetition of a structural unit along a chain backbone.
Another common mistake is treating any long biological molecule containing amino acids as if the term "polymer" automatically applies to the constituent residues. It does not. The residue is still a residue. The polymer is the chain.
Get the Full Details
When the Line Gets Blurry
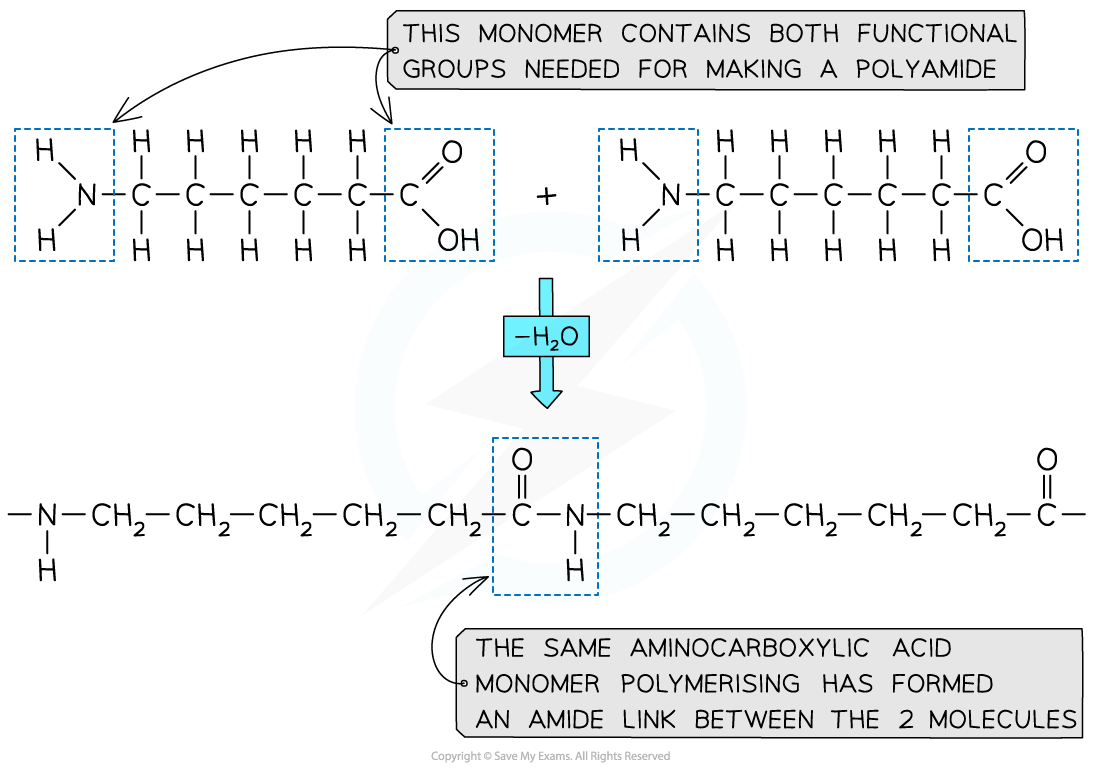
Naturally occurring polypeptides span a massive range. Small peptides like glutathione contain three residues. Insulin sits around fifty-one. Titin stretches into the tens of thousands. Despite the range, every one of those is fundamentally the same architecture: amino acid residues connected by amide linkages in a defined sequence. Synthetic polyamides complicate the picture only slightly. Nylon is a polyamide made from diamines and dicarboxylic acids, not from standard amino acid monomers. It shares the amide bond linkage but is not a peptide and should not be called a polymer of amino acids in any technical sense. Similarly, some engineered backbones incorporate modified amino acid analogs, but the classification stays the same — it is the polymer that carries the classification, not the individual units. There is one edge case worth mentioning. Some researchers refer to polyhydroxyalkanoates or other bioplastics as "amino acid–based polymers" when the feedstock originates from fermented amino acids. That is a sourcing description, not a structural one. The resulting polymer may not even contain peptide bonds. If someone calls poly-lysine an amino acid polymer, that is accurate because the backbone consists of repeating lysine residues linked by peptide bonds. If someone calls a polyester derived from lysine a polymer of amino acids, that is marketing language, not chemistry.
Practical Implications
Why does this distinction matter outside of textbook definitions. It matters because your analytical approach depends entirely on whether you are characterizing a monomer or a polymer.
- Reversed-phase HPLC of a free amino acid will show sharp, early-eluting peaks that respond predictably to a simple gradient. The same column with a peptide mixture will show broader, later-eluting peaks shaped by sequence and hydrophobicity across multiple residues.
- Mass spectrometry of monomers typically uses direct infusion or simple LC-MS with ESI at low voltage. Peptide analysis usually requires collision-induced dissociation or higher-energy collisional dissociation to generate meaningful fragment ions. The instrument settings differ substantially.
- Elemental analysis on a single amino acid gives clean C, H, N percentages. A peptide's elemental composition shifts with every added residue and terminal group, so averaging atomic ratios across a polydisperse sample produces meaningless numbers unless you know the exact distribution.
- NMR of free amino acids in D2O shows clean doublets and triplets for the alpha proton and side-chain protons. Peptide NMR requires 2D experiments like COSY or HSQC to resolve the overlapping amide and alpha regions, and even then, assignment gets difficult past ten or twelve residues without isotopic labeling.
I have seen people try to quantify a peptide using a calibration curve built from individual amino acid standards. The results are always wrong because the molar absorptivity, retention time, and ionization efficiency of a single residue do not scale linearly with chain length. A five-residue peptide will not behave like five separate amino acids dissolved in the same solvent.
Bottom Line
An amino acid is a monomer. Polymers formed from amino acids are polypeptides and proteins. The distinction is not semantics — it determines how you handle, analyze, and interpret the material. If you encounter a product or paper claiming an "amino acid polymer" and the structure does not contain a peptide backbone, someone is either being imprecise with language or selling something that deserves closer scrutiny.