So You Need to Represent Knowledge in Your AI System
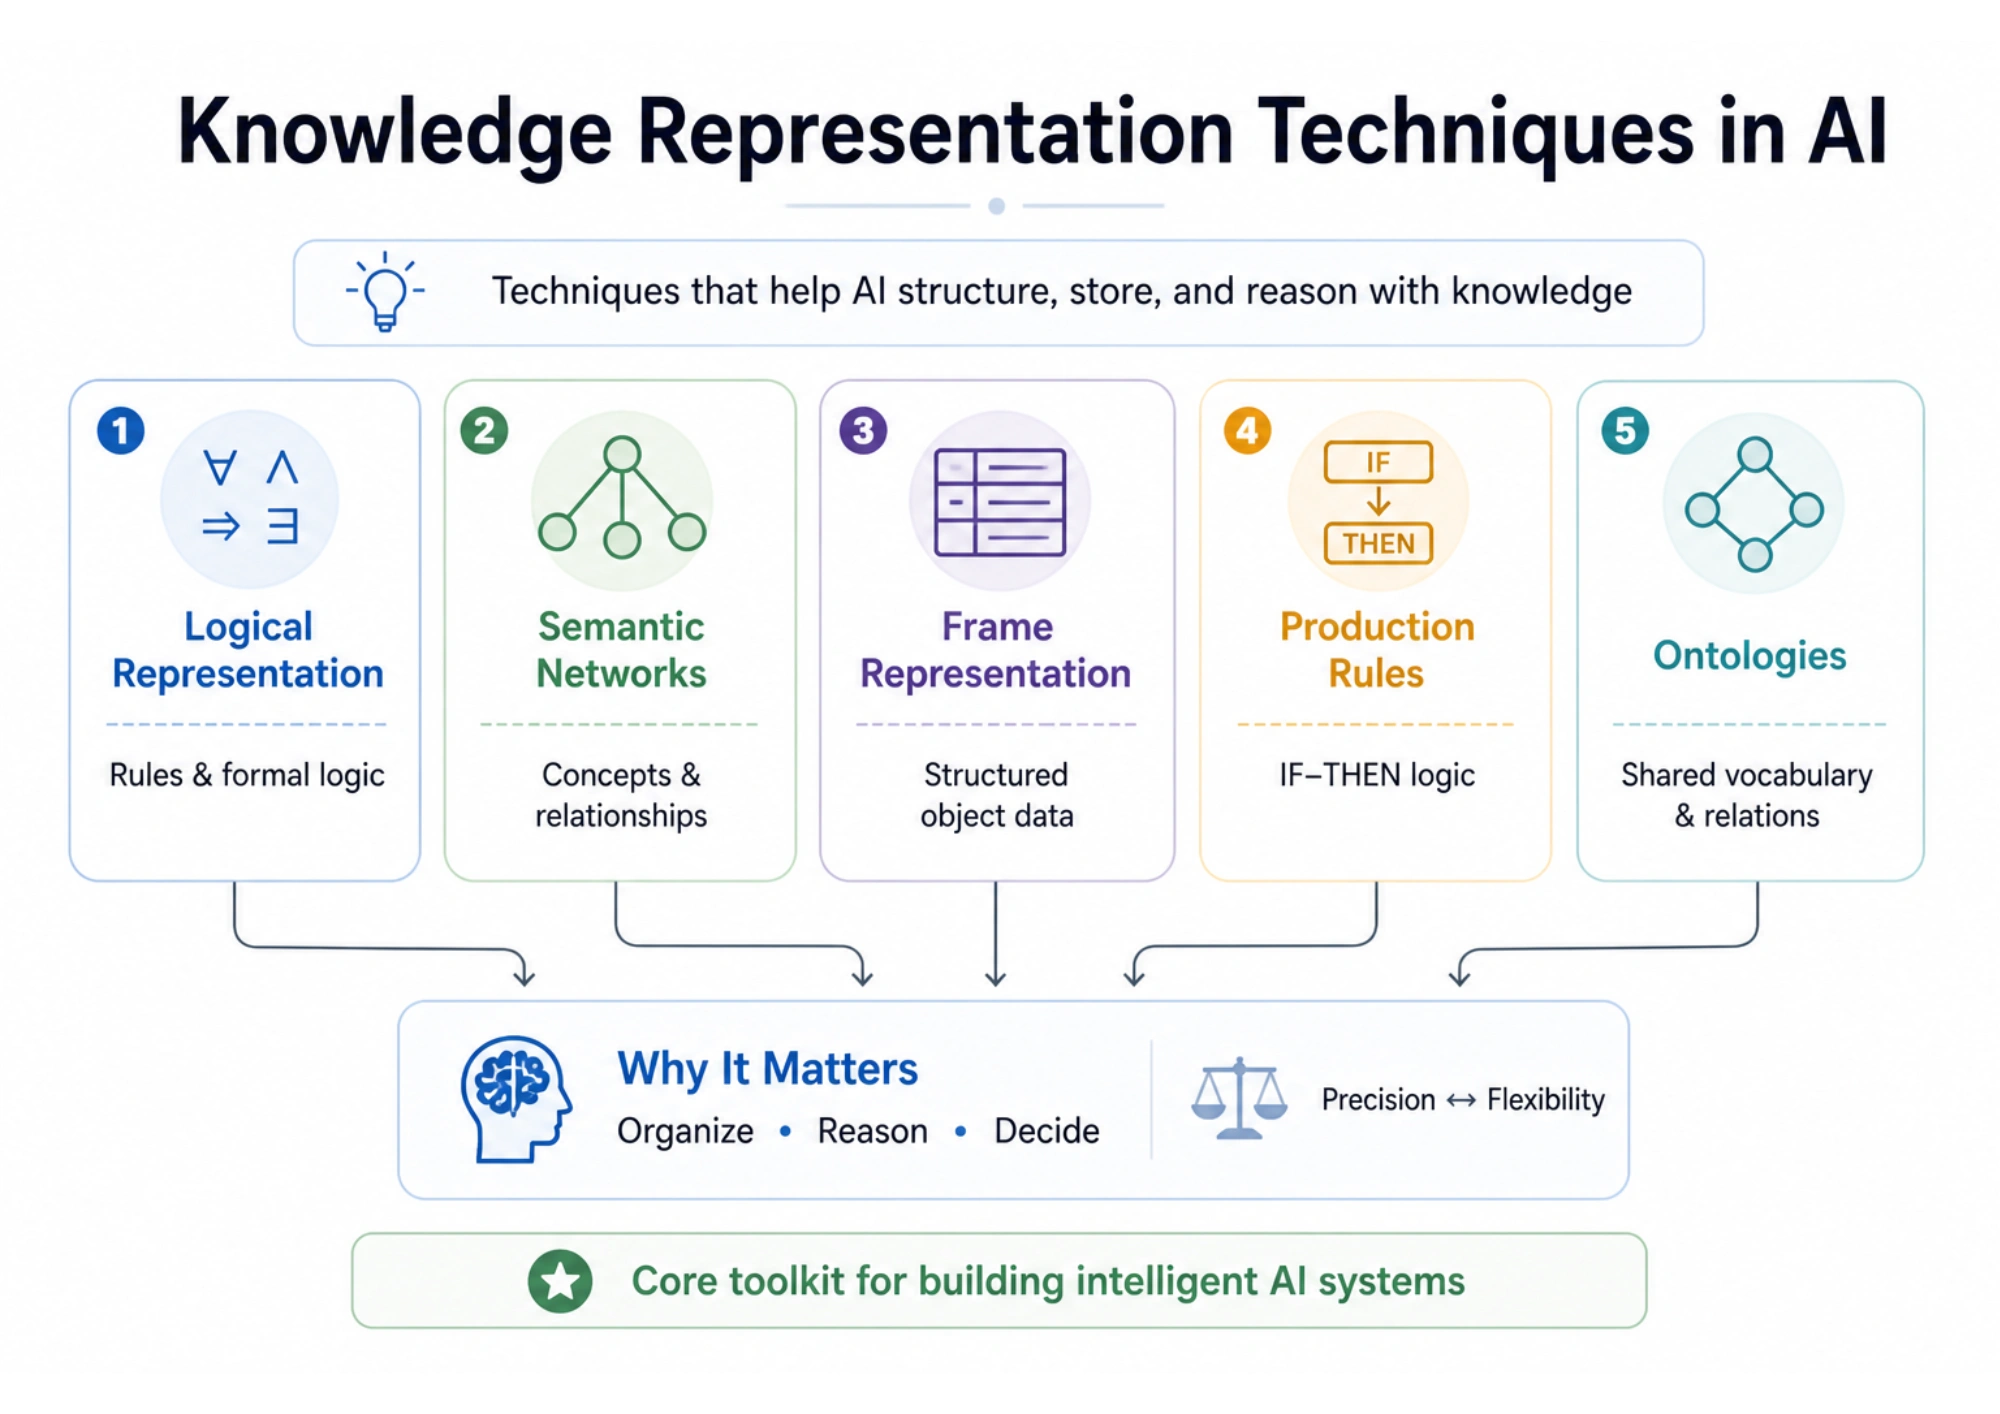
Most people jump into building an ontology or throwing a bunch of RDF triples together without really understanding what breaks later. I spent three weeks last year debugging a knowledge graph query engine that was returning completely wrong results because someone had assumed default inference rules would handle the gap between explicit facts and implied ones. They didn't. Let me walk you through what actually goes wrong and how to fix it. Issues In Knowledge Representation In Ai isn't a single problem — it's a cluster of interrelated failures that only become obvious when your system has to handle something other than textbook examples. The core issue starts with choosing a representation formalism. Most teams pick OWL or simple RDF graphs because they're well-documented. But there's a reason formal logic textbooks exist. They're dense for a reason.
The Inference Gap Nobody Warns You About
When you represent knowledge, you need to decide how much reasoning the system should do automatically versus what stays explicit. This is called the expressivity-complexity tradeoff. A description logic like EL++ lets you reason quickly but you can't express certain relationships. A full OWL 2 DL gives you more power but reasoning becomes NP-hard in the worst case. I learned this the hard way when I tried to use an SROIQ-based ontology with over 40,000 axioms and watched the reasoner take 47 minutes just to check consistency. We switched to EL++ and it dropped to under three seconds. The tradeoff was giving up some expressive features we ended up not using anyway. Another thing beginners miss: most representation issues show up in edge cases, not the main flow. Your taxonomy of product categories might work fine for a thousand SKUs and break completely when someone enters a product that belongs to two categories simultaneously. With simple hierarchical representations, that creates an inconsistency. With frame-based systems, you get attribute conflicts. The workaround is usually to introduce explicit relationship types rather than forcing everything into a strict parent-child structure. It's messier but it doesn't collapse under real data.
Handling Ambiguity and Incomplete Information
Knowledge in the real world is rarely complete and often ambiguous. A naive approach is to encode only what you know for certain and leave gaps blank. That sounds rational until you try to reason across those gaps. Non-monotonic reasoning helps here — the idea that adding new information can invalidate old conclusions. Open World Assumption versus Closed World Assumption is the technical term you'll run into. RDF and OWL use OWA by default, which means the system assumes missing information might exist. Prolog-style databases use CWA, meaning anything not explicitly stated is false. Picking the wrong one will give you silent bugs that are nearly impossible to trace. I had a case where a medical knowledge base was using OWL with OWA and the system kept flagging patients as having unconfirmed diagnoses simply because a test result hadn't been entered yet. The fix was to create a separate predicate layer for confirmed findings versus suspected findings, and apply CWA rules only to the confirmed layer. That took about a day of restructuring the schema and maybe an hour of updating the query layer. Worth it.
Get the Full Details

Scalability Is a Representation Problem Too
You can design a perfectly accurate knowledge representation and still fail because it doesn't scale. Vector embeddings and LLM-based approaches are popular now but they don't give you the same guarantees as symbolic representations. You can't query them for exact logical relationships. Hybrid systems combine both — symbolic knowledge graphs for structured reasoning and vector stores for similarity matching. The problem is keeping them synchronized. When the graph updates, your embeddings need to reflect that. When an LLM generates new facts, they need to be validated before entering the graph. A practical tip: index your ontology predicates carefully. I've seen systems where querying a single property on a large graph took 30 seconds because the underlying triplestore wasn't optimized for the cardinality of certain relationships. Switching from an unindexed broad property to a more specific typed property reduced query time to under 200 milliseconds in my experience. The ontology design itself becomes a performance issue.
Validation and Consistency Checking
Before you deploy any knowledge representation, you need automated consistency checks. Reasoners like HermiT, Pellet, or Fact++ can validate OWL ontologies but they won't catch domain-specific logical errors. You need to write your own test cases. I usually create a small set of expected inferences and verify the reasoner produces them, plus a set of contradictions that should be rejected. If your system accepts a contradiction without flagging it, something is wrong with your axioms or the reasoner configuration. The biggest practical issue most people face is version drift. Your knowledge base changes over time and old representations become incompatible with new ones. Semantic versioning for ontologies helps but isn't widely adopted. I recommend maintaining a migration map between versions and running a consistency check against each new version before merging. This usually catches about 80 percent of integration issues before they reach production. There's no perfect solution for Issues In Knowledge Representation In Ai because the problems shift as your system grows. Start simple, validate aggressively, and don't add expressivity you haven't proven you need.