The IT Root Cause Analysis Template Nobody Actually Uses Correctly
I've spent years watching teams fill out root cause analysis forms and then immediately file them away without letting anything actually change. The template itself is fine. The problem is how people use it, or don't use it. I'm going to walk through a practical version that actually works, including a format I've adapted from real incidents over the past several years. It Root Cause Analysis Template is a structured document used to investigate and document the underlying causes of IT incidents, outages, or failures. It's not just a form for compliance. When done right, it's the difference between the same incident happening every six months and never happening again. When done wrong, it's a checkbox exercise that makes everyone feel productive while nothing changes. Here's the thing most people miss: the template isn't the deliverable. The deliverable is the set of actions that come out of filling it out. If your RCA ends with "we need better monitoring," you haven't done your job. That's not an action. That's a wish.
How to Use a Root Cause Analysis Template in Practice
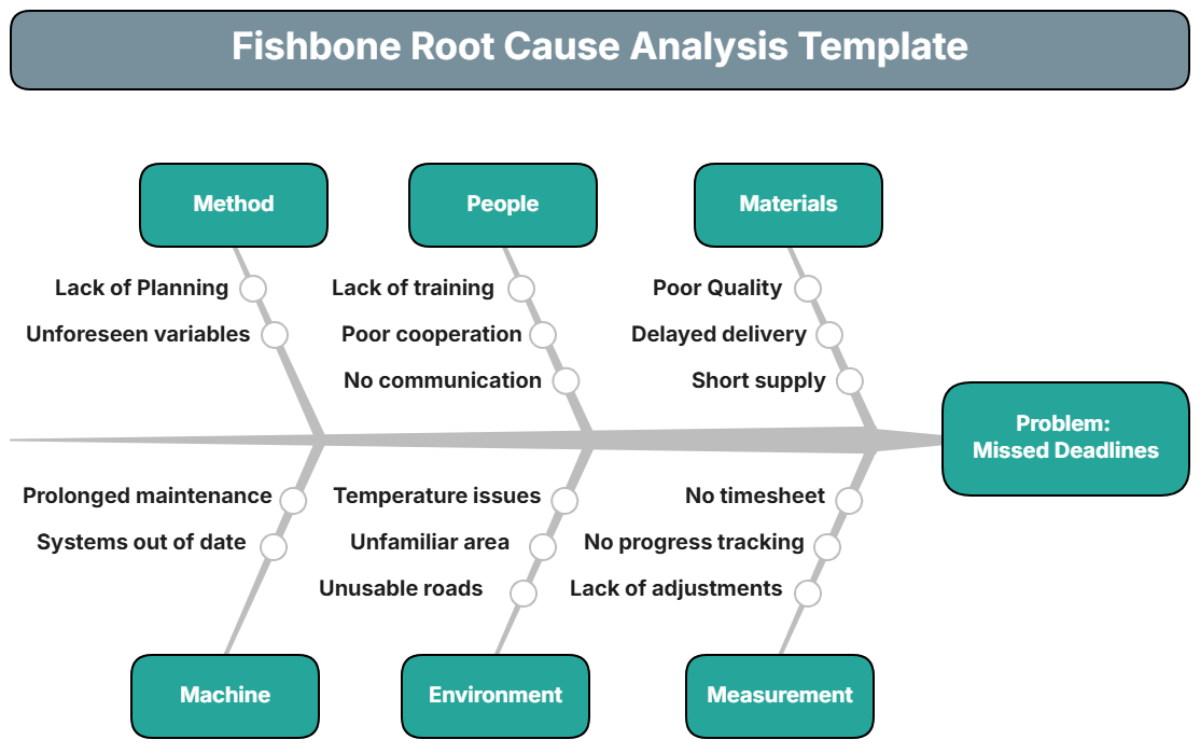
Start with the incident itself. I mean really start there. Write down what happened, when it happened, and what the impact was. Be specific. "The application went down" is useless. "The payment processing service became unreachable from 14:32 to 15:47 UTC on March 12, affecting approximately 12,000 active users and generating $47,000 in lost transaction revenue" is something you can work with. Then move to the timeline. This is where most templates get sloppy. A proper timeline includes every relevant event in chronological order: when the alert fired, when someone acknowledged it, when the fix was attempted, when service was restored. Timestamps matter. Vague language like "later that afternoon" has no place in an RCA. For the actual root cause identification, I use a method that combines the 5 Whys technique with a fishbone diagram approach, but simplified into a single worksheet. You ask why the incident occurred, then ask why that answer occurred, and keep going until you hit something actionable. Most people stop at the first or second why. That's insufficient.
I've seen this play out repeatedly. A database connection pool exhausted itself during a traffic spike. Why? Because the pool size was hardcoded to 50 connections. Why was it hardcoded? Because the previous engineer left without documentation. Why wasn't it documented? Because there's no onboarding process for infrastructure configuration. There it is. The root cause isn't the connection pool. The root cause is the lack of configuration documentation and onboarding procedures. Fixing the pool size without fixing the process means the next engineer will hardcode something else somewhere. After identifying the root cause, you need to categorize it. In my experience, causes generally fall into these buckets: human error, process failure, tool or technology limitation, environmental factor, or architectural design flaw. Be honest about which category applies. If you're blaming human error, dig deeper. Human error is almost always a symptom of a broken process or poor tooling. Then come up with corrective actions. Each action should be specific, assigned to a person, and have a due date. No exceptions. "Improve monitoring" is not a corrective action. "Add CloudWatch alerts for database connection count exceeding 80 percent capacity, assigned to Sarah Chen, due by April 30" is a corrective action. The difference matters because accountability drives results.
Get the Full Details

I'll share a specific problem I ran into recently. We had an incident where a Kubernetes pod kept crashing in a loop. The standard RCA template pointed toward resource limits being too low. But the real issue was a memory leak in a third-party logging library that only manifested under sustained load above a certain threshold. The template's standard categories didn't really fit. What I ended up doing was creating an additional section in my version of the template called "Uncovered Scenarios" where I documented cases where the standard framework fell short. This section has become one of the most valuable parts of our incident review process because it flags patterns that don't fit neatly into the usual buckets.
The IT Root Cause Analysis Template Format
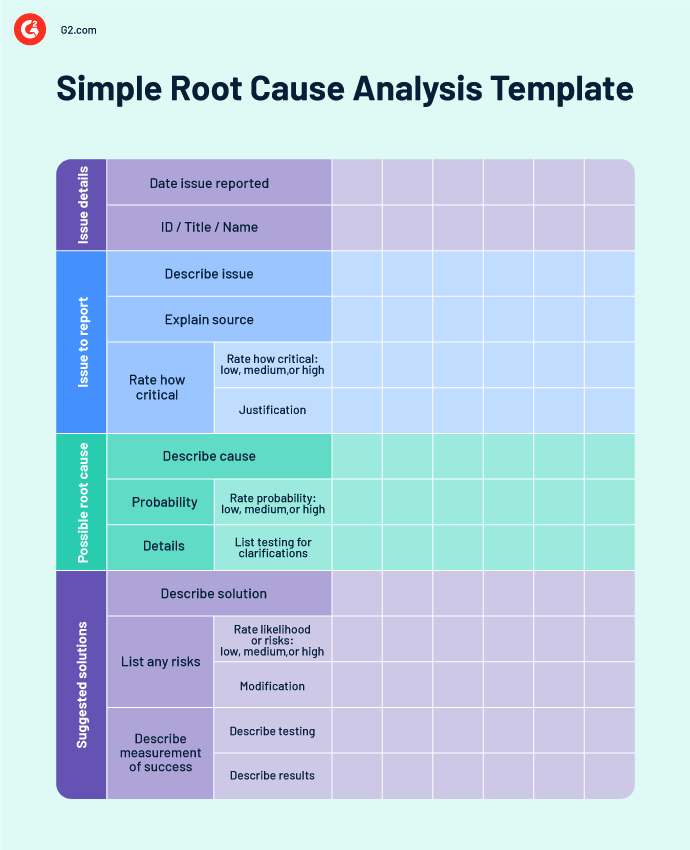
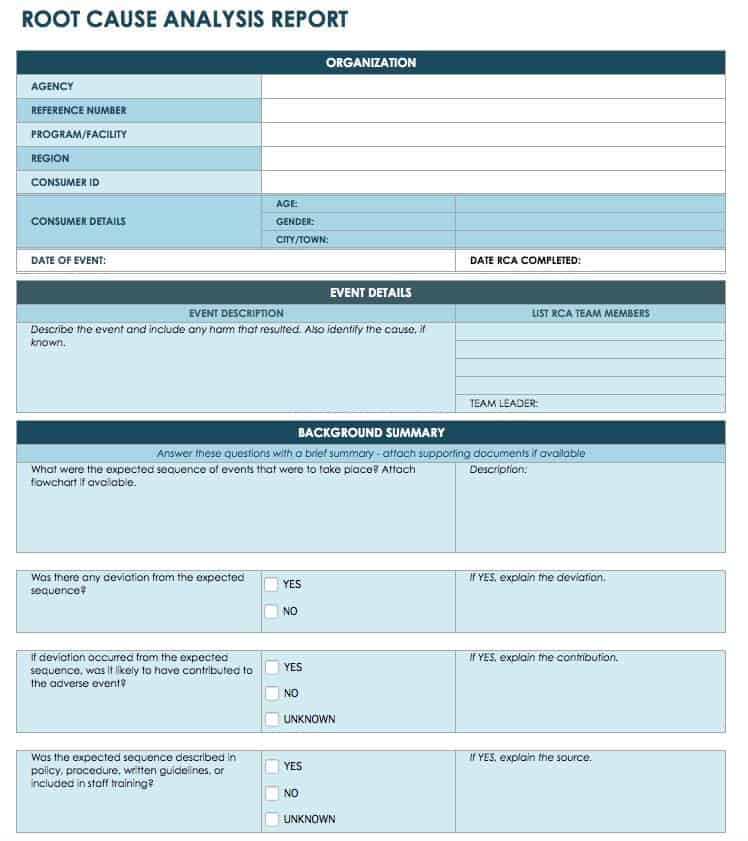
Here's the structure I use. It's not fancy. It covers the essentials without adding fluff that nobody reads. Incident Summary: Title, date, time affected, severity level, systems impacted, brief description of what happened. Impact Assessment: Number of users affected, duration of outage, financial impact if measurable, reputational impact, any regulatory implications.
Timeline of Events: Chronological list of everything that happened, with timestamps. Include detection time, response time, resolution time, and any key decisions made during the incident. Root Cause Analysis: The primary root cause statement, the chain of reasons leading to it (5 Whys or similar), and the category classification. Contributing Factors: Anything that made the incident worse or longer. Slow detection, inadequate runbooks, unclear escalation paths, missing dependencies, communication failures. These don't excuse the root cause but they explain why the impact was what it was.
Corrective Actions: List of specific actions with owner and deadline. Each action should directly address either the root cause or a contributing factor. Prioritize them by impact and feasibility. Preventive Measures: Changes to processes, training, architecture, or tooling that would prevent recurrence. This is separate from corrective actions because prevention is about building something new, not just fixing what broke. Follow-Up: A section I insist on adding. How will we verify that the corrective actions were completed? When will we review whether the incident recurs? What metrics will tell us the fix actually worked? Without this section, the RCA dies on page one.
Common Mistakes That Ruin Root Cause Analyses
The biggest mistake I see is rushing through the template. People treat it like a form to complete rather than a process to understand. If your RCA takes less than an hour for a significant incident, you're probably not doing it right. A thorough analysis of a medium-severity incident typically takes 2 to 3 hours of focused work. A major outage might take a full day. That's not wasted time. That's the minimum investment required to prevent the same incident from happening again. Another common error is stopping the analysis too early. "The server failed" is not a root cause. "The disk filled up because a log rotation job stopped running" is closer. "The log rotation job stopped because the cron schedule was changed during a patch deployment and nobody verified it afterward" is the actual root cause. Each level gets you closer to something you can fix. I also notice that people rarely involve the right stakeholders. An RCA for a database outage should include the DBA team, the application team, the infrastructure team, and whoever was on call that day. If you only include the people who directly caused the problem, you'll miss systemic issues. If you include too many people, the meeting becomes unproductive. The sweet spot is usually 4 to 6 people who have direct knowledge of the incident.
There's also the problem of blame-oriented RCAs. When people fear that admitting a mistake will hurt their career, they hide information. The analysis becomes a exercise in deflecting responsibility rather than understanding the system. This is one of those areas where leadership sets the tone. If you punish mistakes publicly, you will get shallow RCAs. If you treat incidents as learning opportunities, you'll get genuinely useful ones.
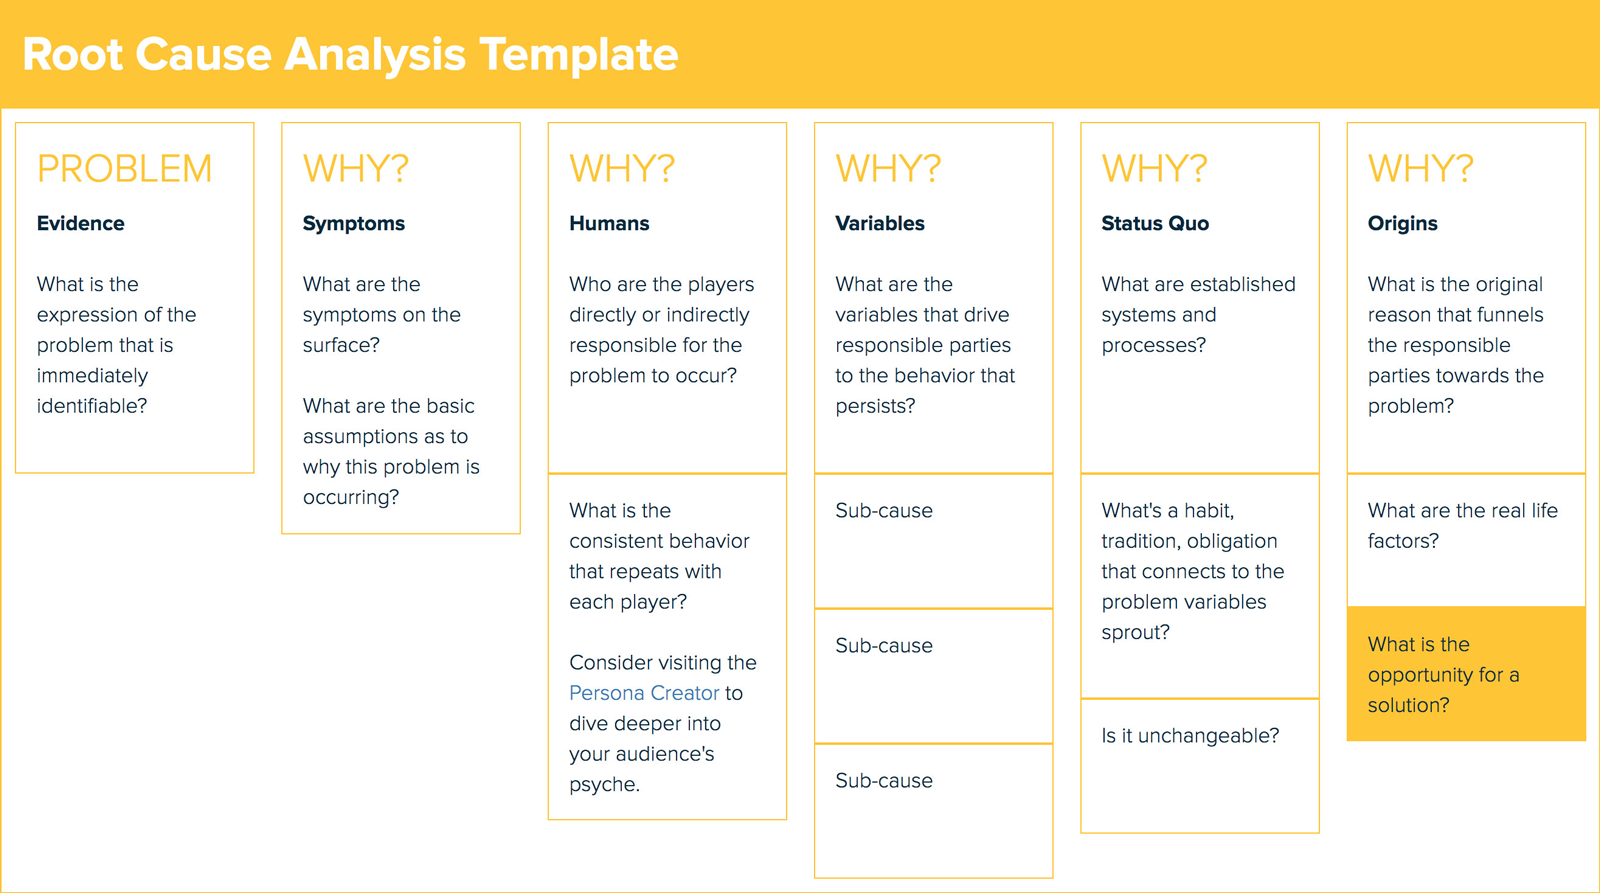
When the Template Doesn't Work
I need to be straightforward about limitations. A root cause analysis template is not useful for every type of incident. For very minor issues—a single user unable to log in, a non-critical bug discovered during testing—the formal template is overkill. In those cases, a quick post-mortem note in your issue tracker is sufficient. The template shines when incidents have real impact: downtime, data loss, security breaches, or significant customer-facing degradation. The template also struggles with complex, multi-factor incidents where the cause isn't linear. Sometimes an incident results from a combination of small failures across different systems that each seemed acceptable in isolation. In those cases, the 5 Whys approach breaks down because there isn't one chain to follow. You might need a different framework, like failure mode and effects analysis (FMEA) or a bowtie analysis, to map out the interconnections properly. Another scenario where the template fails is when the root cause is fundamentally unknowable. If you lost data and have no backups, no logs, and no recovery path, you can still fill out the template, but you won't find a root cause. In those situations, the honest answer is that the cause cannot be determined with available information, and the focus should shift entirely to preventive measures: better backups, more comprehensive logging, earlier detection systems.
Where to Get a Working Template
I don't have a downloadable file to share, but I can tell you exactly how to build one that works better than most pre-made templates you'll find online. Start with the format I outlined above. Put it in Google Docs or Confluence so your team can collaborate on it. Add a section for action item tracking with fields for status, owner, and completion date. Make it a living document, not something that gets written once and forgotten. Integrate it into your existing incident management workflow. If you use PagerDuty, Opsgenie, or similar tools, create a standard incident report template that pulls in data automatically—timestamps, responder information, alert history. The less manual data entry required, the more likely your team is to actually complete the RCA. I've found that the best version of an IT Root Cause Analysis Template is the one your team actually uses consistently. A simple template that gets filled out for every incident beats a comprehensive template that only gets used after major outages. Consistency builds a knowledge base. Over time, you'll see patterns emerge across multiple RCAs that no single incident would reveal on its own.