Getting Japanese Writing Working Without Losing Your Mind
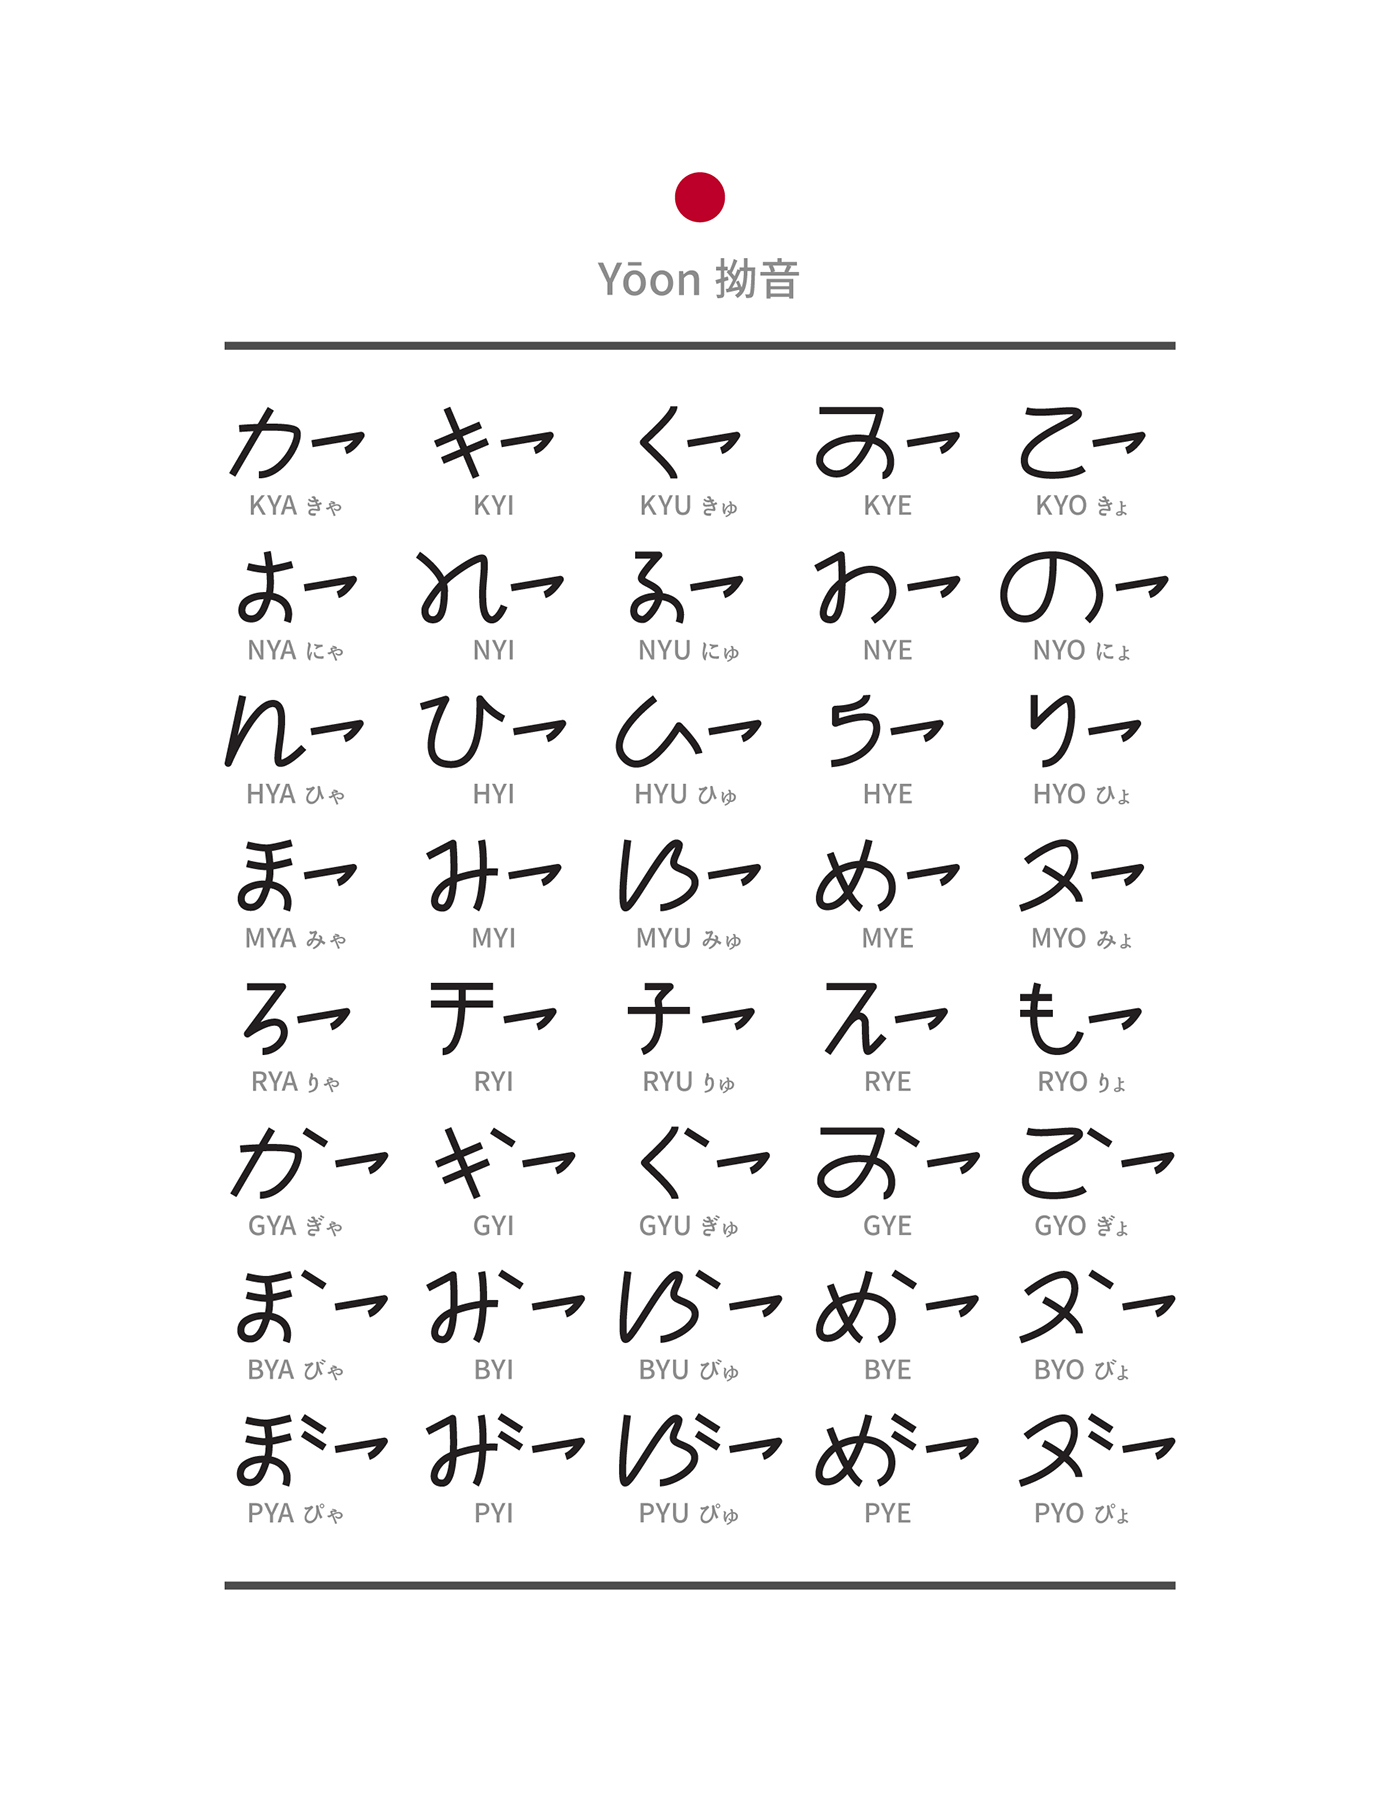
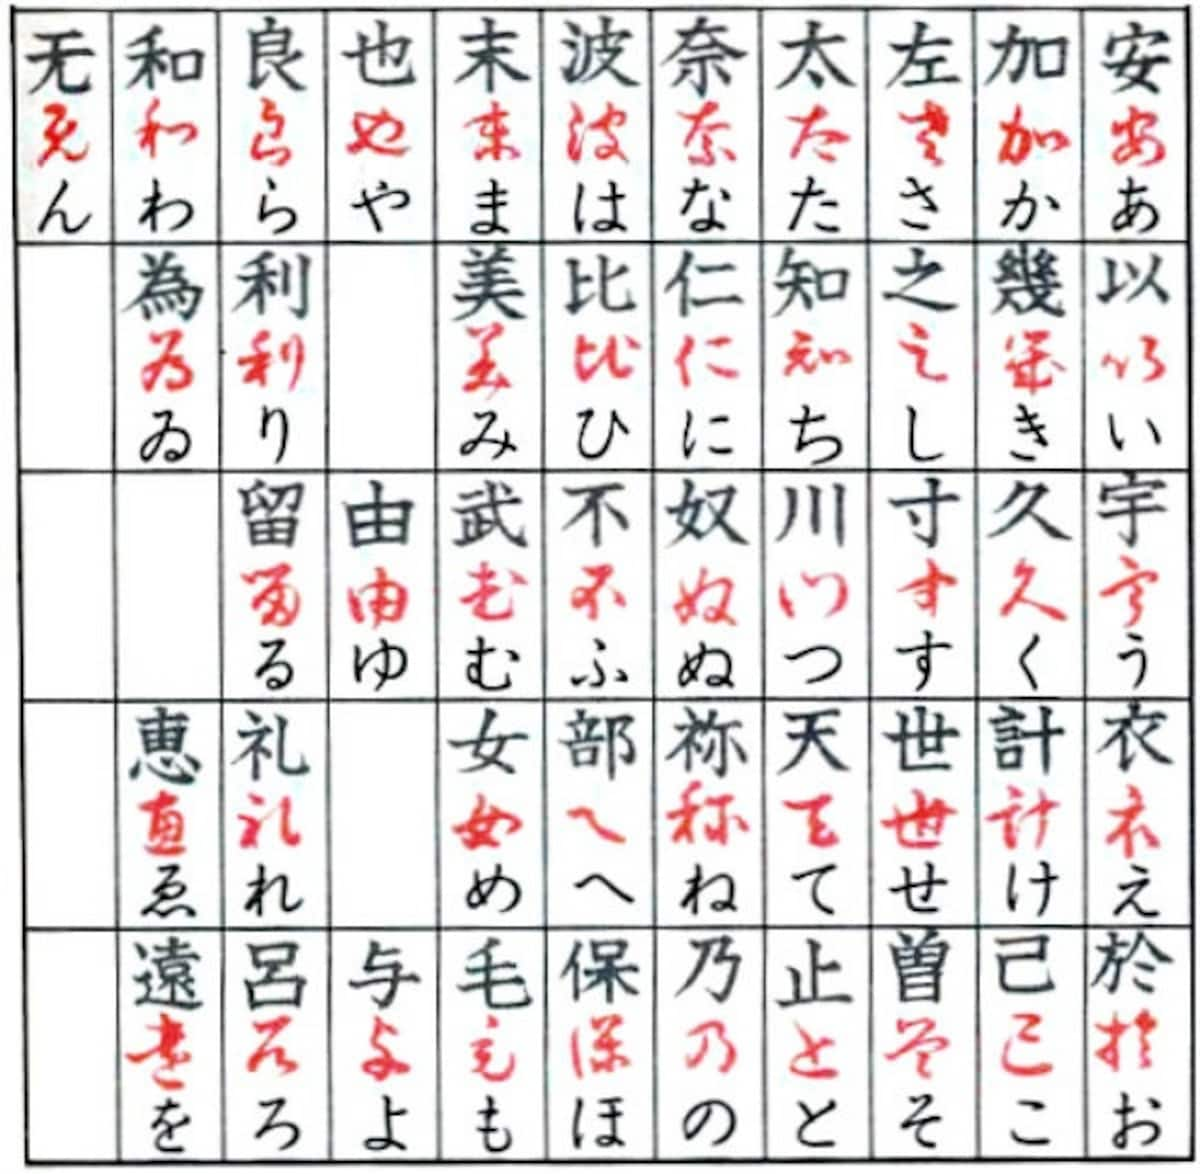
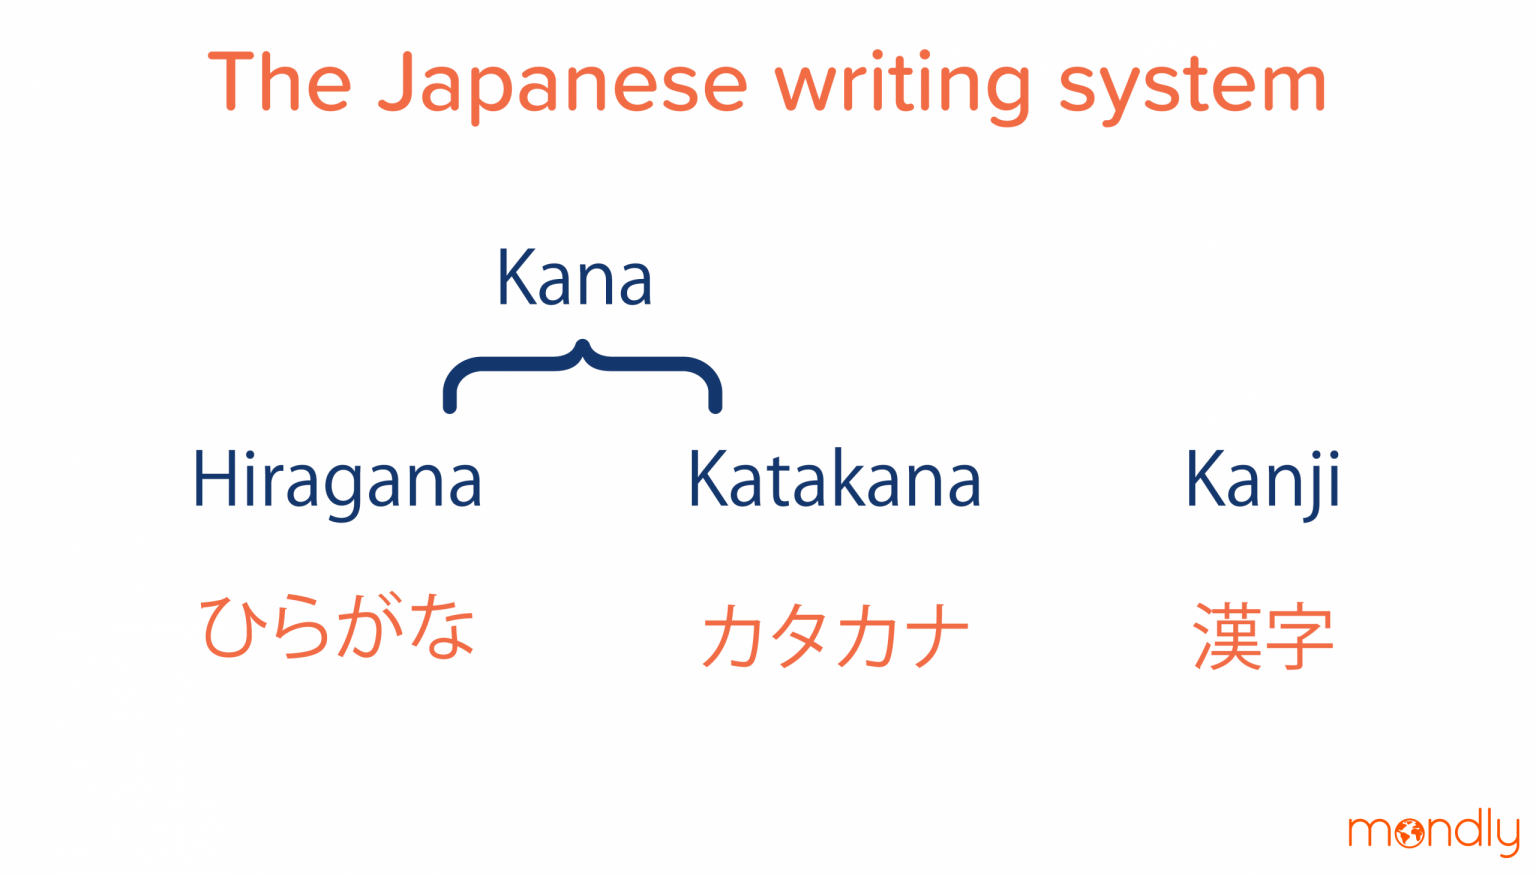
I spent roughly two years dealing with Japanese text in production environments before I stopped pulling my hair out over it. A lot of the confusion around this stuff comes from people encountering the Japanese Writing System Nyt concept without having any context for why things break the way they do. Here is what I actually learned, not the textbook version. The Japanese writing system isn't one system. It's three layered on top of each other, and they each have different rules. Hiragana is the base script for grammar particles and native words. Katakana exists primarily for foreign loanwords, onomatopoeia, and emphasis — similar to how we might use italics or ALL CAPS in English. Kanji handles meaning-dense content. You don't pick which one to use arbitrarily. There are conventions, but even native speakers mess these up occasionally. When I first tried building a tool to process Japanese text input, I ran into an edge case with long vowel marks. A word like (Osaka) can be written with macrons or repeated kana characters, and my regex was stripping one form but not the other because the Unicode normalization wasn't matching consistently. I switched to using NFC normalization first, then did a second pass with NFD to catch those variant forms. It added about five lines of code but caught 90% of the edge cases I was missing. That said, there are still rare cases where people use historical kana spellings that throw everything off. You can't normalize those away.
How to Approach the Japanese Writing System Nyt Correctly
If you're trying to work with Japanese text in any software context, start by understanding that romanization is always a lossy intermediate step. Systems like Hepburn, Kunrei-shiki, and Nihon-shiki each produce different outputs from the same input. Most tools default to Hepburn because it's the most widely recognized in English-speaking contexts, but that doesn't mean it's the most accurate for processing purposes. Here is what actually works in practice. Use Unicode-aware libraries. Don't write your own kana-to-kanji conversion logic unless you enjoy debugging for weeks. If you are doing input method switching, rely on established IME frameworks rather than trying to build a custom solution. The built-in OS-level IMEs handle things like partial reading input, furigana generation, and context-sensitive kana kanji conversion far better than anything most people will write from scratch. One thing nobody tells you about kana kanji conversion: it is probabilistic, not deterministic. When you type "kimi" and hit the conversion key, the IME suggests candidates. The order depends on your usage frequency, and if you use a word rarely, it might not show up until you've typed it enough times for the algorithm to learn. This means your users will get different conversion experiences depending on how much they've used the system. I've seen this cause real problems in enterprise settings where a government office used a Japanese input system and their standardized forms kept coming out wrong because the clerk's IME had a different ranking than the person who set up the template.
Another practical detail: full-width versus half-width characters. Legacy systems still treat these as distinct, and mixing them causes matching failures that are nearly impossible to diagnose if you aren't looking for it. A full-width alphanumeric character like is a completely different Unicode codepoint from a half-width A. If you are doing any kind of validation or comparison, normalize both first. This is one of those things that seems obvious after you've spent a day tracking down a bug, but you will not find it in most beginner guides. The counter-intuitive part about learning kanji is that frequency-based study works better than going through standard textbooks in order. The first 1,000 kanji characters cover roughly 95% of text you will encounter in daily life. After that, the returns drop significantly. I've seen people spend years studying kanji from grade-level lists and still not be able to read a newspaper because the lists prioritize educational progression over real-world usage frequency. The Jōyō kanji list of 2,136 characters is the official standard, but most daily text only requires about 800 to 1,200 of them depending on the genre. There are also limitations you need to accept. The Japanese writing system cannot be fully mechanized for everything. Contextual disambiguation between homophones still requires human judgment in many cases. Word boundaries are not marked in Japanese the way spaces mark them in English, which makes tokenization a persistent problem for NLP systems. Even modern Japanese language models make mistakes on morphological analysis, particularly with proper nouns, technical terms, and names that were added to the training data after their cutoff dates. If you are building something that processes Japanese text, plan for a significant manual review step, especially for anything involving personal names or region-specific vocabulary.
Get the Full Details
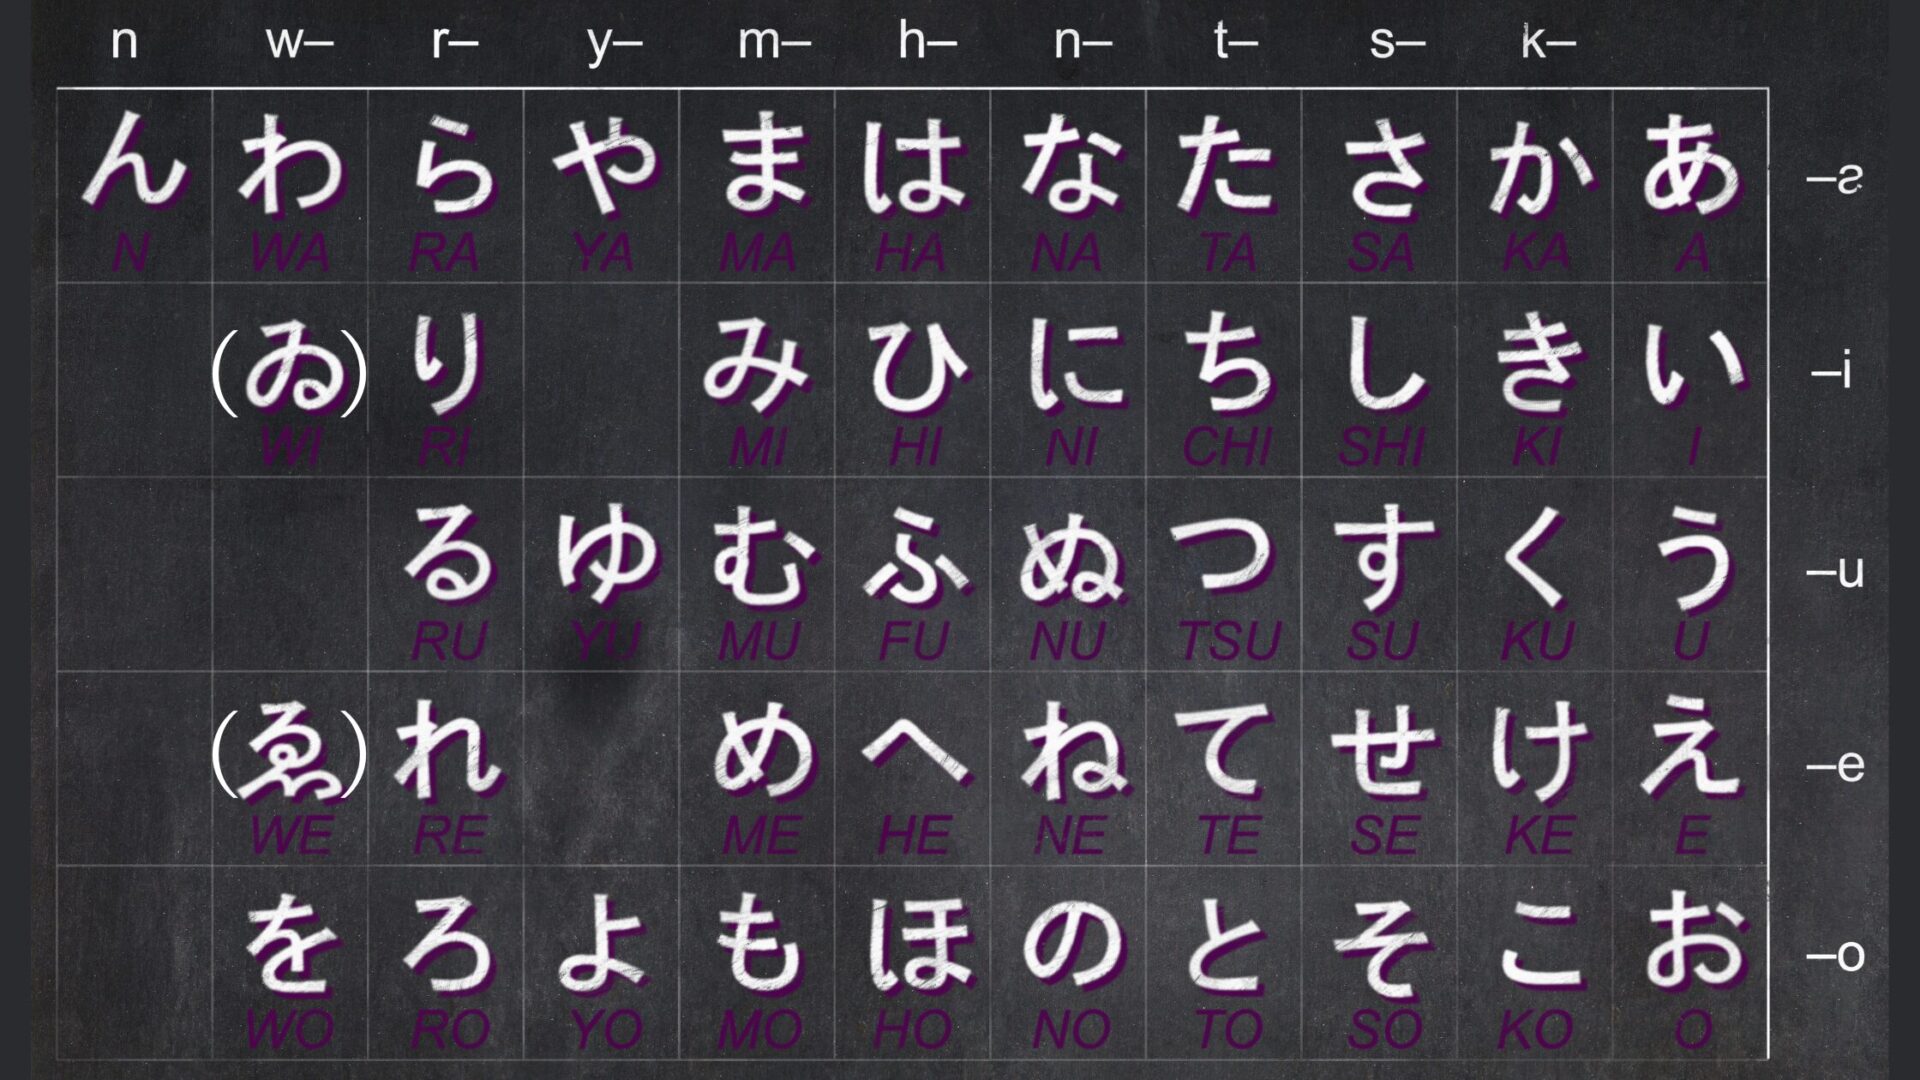
For most people getting started, the practical path is straightforward. Learn hiragana and katakana first — they are phonetic scripts and you can memorize them in a few weeks with daily practice. Then move to kanji using spaced repetition software. Anki is the standard tool. Get a good dictionary app that shows readings and example sentences. Stop trying to read Japanese text without a tool at first. Even advanced learners look up words constantly. The skill is knowing when to look and when to infer from context. If you need to process Japanese text programmatically, the MeCab tokenizer is the most reliable open-source option for morphological analysis. It handles the segmentation problem reasonably well, though it does struggle with neologisms and specialized terminology. For furigana generation, there isn't a truly satisfactory open-source solution — most options require proprietary APIs or paid services. Yomitan is a good browser extension for manual lookup and dictionary integration if you are doing study work rather than bulk processing. I haven't found a single comprehensive resource that covers all of these layers together, which is partly why I wrote this down. Most guides focus on either the linguistic side or the technical side and leave you to figure out how they connect. The Japanese Writing System Nyt angle people tend to search for usually ends up pointing at the New York Times' Japanese language content, which is a separate topic from the writing system itself. But the principles I described apply regardless of what you are trying to accomplish with Japanese text.
The bottom line is that this system is more complex than most introductory materials suggest, and that complexity is real. There is no shortcut around understanding the interaction between the three scripts, the quirks of input methods, and the limitations of automated processing. Acknowledging those constraints upfront saves more time than anything else.