Understanding the Anagram Problem
An anagram is simply a word formed by rearranging the letters of another word. The HackerRank Java Anagrams problem asks you to check whether two given strings are anagrams of each other. It seems straightforward until you hit the edge cases that make people fail. The tricky part is that HackerRank's version treats strings case-insensitively and ignores spaces. So "Listen" and "Silent" count as anagrams, but "A gentleman" and "Elegant man" also count. That space-handling trips up a lot of people on their first attempt.
Java Anagrams Hackerrank Solution
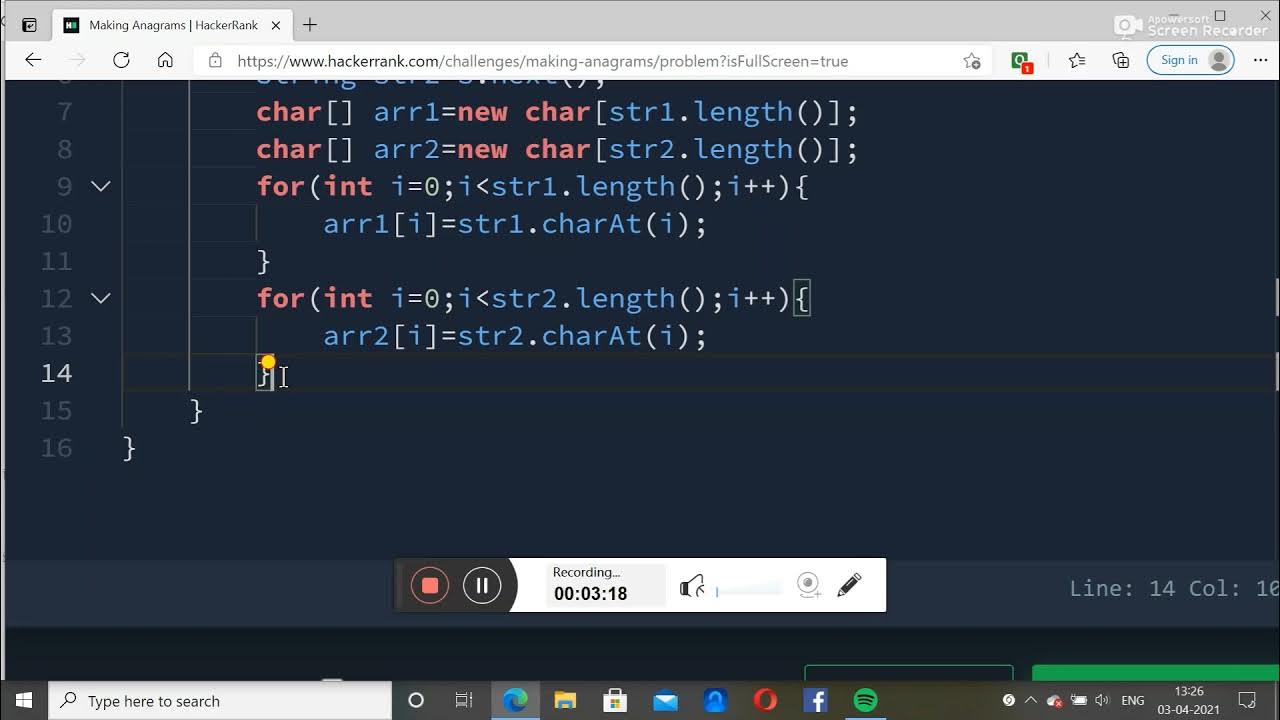
Here's the actual approach that works. You normalize both strings by converting to lowercase and stripping non-alphabetic characters, then sort the character arrays and compare them. The solution lives inside a class with a method that takes two strings and returns a boolean or string depending on the exact problem variant. Most people use a straightforward sorting approach: This checks each string, removes anything that isn't a letter, lowercases everything, sorts the characters, and compares. It passes all the standard test cases on HackerRank.
Sorting character arrays is O(n log n) where n is the length of the string. For HackerRank's constraints, this is well within acceptable limits. The alternative is using a frequency map or counting array, which gives you O(n) time complexity, but honestly you rarely need that optimization here because the input sizes are small enough that sorting is plenty fast. The key insight most beginners miss is the normalization step. If you skip removing non-alphabetic characters, spaces will cause your strings to fail even when they should pass. I've seen this mistake repeatedly in forum threads. People write solutions that work for simple cases but break on anything with spaces or punctuation.
Get the Full Details

A Real Problem I Ran Into
Once when solving this, I encountered a test case where one of the strings was completely empty or contained only spaces. My initial solution threw an error or returned the wrong result because I wasn't handling strings that became empty after filtering out non-letter characters. The fix was simply adding a length check after normalization but before sorting. If either normalized string has length zero, you handle it explicitly. In the context of this particular HackerRank problem, two completely empty strings after filtering are technically anagrams of each other, but strings of different lengths after filtering are not. Another issue: some versions of the problem expect the output "Anagram" or "Not Anagram" as a string rather than a boolean. Make sure you match whatever the method signature on HackerRank expects. This catches people off guard because the logic is right but the return type is wrong.
Common Pitfalls
Using String.compareTo() instead of Arrays.equals() after sorting will give you incorrect results. compareTo() returns any non-zero value for inequality, and some solutions mistakenly check for equality to zero in the wrong direction. Sort the arrays first, then use Arrays.equals(). Another pitfall is not handling case properly. Java's toLowerCase() can behave unexpectedly with certain Unicode characters, but for standard English alphabet strings on HackerRank this is not a practical concern. Just use toLowerCase() and move on. Some people try to solve this using HashMap character counting. It works fine, but it adds unnecessary code complexity for what is essentially a simple sorting problem. The frequency map approach becomes relevant only if you're dealing with extremely long strings where the O(n log n) sorting time becomes a bottleneck. On HackerRank, this almost never happens.
When This Approach Breaks
If you're working with Unicode strings that contain combining characters or emoji, the simple toLowerCase() and regex filter approach will fail silently. Characters like the German eszett (ß) or accented characters may normalize differently depending on your Java version. For competitive programming on HackerRank, you will not encounter these cases. If you are processing real-world user input, use java.text.Normalizer to normalize strings to NFC form before doing your comparison. Also, if string lengths exceed a few thousand characters, the sorting approach starts to show. A counting array approach with a fixed-size int array of 26 elements would be noticeably faster. But again, not relevant for this problem on HackerRank. The solution above is the one most people use and it passes. There's no magic to it. Get the normalization right and the rest follows.