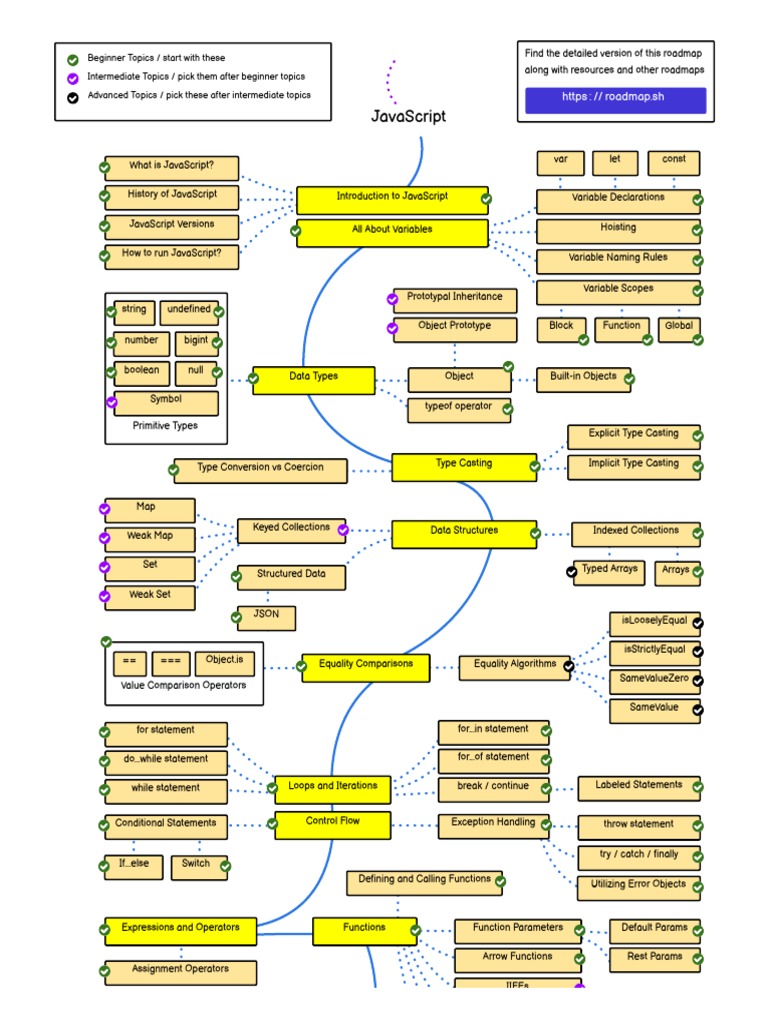
JavaScript Comprehensive Guide Walkthrough
Most people learning JavaScript hit a wall somewhere around the middle of their journey. They can write a basic click handler and make things appear on screen, but then everything falls apart when they try to connect an API, manage state across components, or understand why their async code isn't behaving the way they expect. The gap between writing JavaScript that works in a tutorial and writing JavaScript that works in production is bigger than most resources acknowledge. I've spent years mentoring developers who hit this exact problem, and the ones who break through usually do it by following a structured path that covers the pieces beginners skip. This walkthrough goes through that path. Not the surface-level "learn syntax" material, but the practical guide that actually shows how JavaScript works when you're building something real.
Core Concepts You Actually Need
Let me start with something that trips up even experienced developers: the difference between how primitives and objects are passed around in JavaScript. Primitives like numbers, strings, and booleans are copied by value. Objects and arrays are copied by reference, which means two variables can point to the same data in memory. I once spent three hours debugging a React component where the state wasn't updating properly. The issue? I was mutating an object directly instead of creating a new reference. The pattern state.value = 5 instead of setState({ ...state, value: 5 }) is one of those things that silently causes bugs for weeks before you figure out what's happening. Understanding hoisting is another foundational piece that most tutorials don't emphasize enough. When you declare a variable with var, it gets hoisted to the top of its scope but initialized as undefined. This is why you can accidentally use a variable before its declaration without getting an error—until your logic depends on it having a specific value.
The let and const keywords fixed some of this, but they introduced the temporal dead zone, where accessing a variable before its declaration throws a ReferenceError instead of returning undefined. It's a different class of bug, but it happens frequently enough that you should know about it.
Get the Full Details

Async Patterns That Matter
Asynchronous JavaScript is where most beginners hit serious trouble. The callback pattern got replaced by promises, and promises got supplemented by async/await, but understanding the underlying mechanics matters more than memorizing syntax. Here's what most guides don't explain clearly: every promise is either pending, fulfilled, or rejected, and once a promise settles, it stays settled. You can't change its state. This has implications for error handling that trip people up. I've seen developers write code like this and wonder why the error handler never fires:
async function fetchData() { try { const data = await callApi(); return data; } catch (e) { console.error(e); } } The problem? The try/catch only catches errors that happen synchronously inside the async function or errors from the awaited promise. If the function completes successfully but returns a rejected promise later in the call chain, the error bubbles up to whatever calls fetchData, not to the catch block inside it. The event loop is the mechanism that makes all of this work. JavaScript is single-threaded, which means it can only do one thing at a time. The event loop manages a queue of tasks and callbacks, processing them one by one while the main thread remains free.
Microtasks like promise resolutions have higher priority than macrotasks like setTimeout callbacks. This means if you have a chain of promises, they all resolve before the next setTimeout callback runs, even if that callback was scheduled to fire sooner.
Common Pitfalls and How to Avoid Them
One of the most counter-intuitive aspects of JavaScript is how equality checking works. The == operator performs type coercion, which means "5" == 5 returns true but "5" === 5 returns false. Using == is generally considered bad practice because the coercion rules are complex and easy to get wrong. Another common trap is mutating the DOM inside a loop without debouncing. If you're making 50 DOM updates in rapid succession, the browser has to recalculate layout and paint after each update, which kills performance. Wrapping your updates in requestAnimationFrame or using a library that batches DOM changes can cut your render time from several seconds down to under a hundred milliseconds. Closure leaks are another subtle issue that beginners rarely encounter until their applications become slow. When you create a closure inside a loop and reference loop variables, those variables stay in memory for as long as the closure exists, even after the loop finishes. This was a common source of memory leaks in older jQuery codebases.
The workaround is straightforward: capture the variable value at the time of closure creation using an IIFE (Immediately Invoked Function Expression) or by using let instead of var, which creates a new binding for each iteration of the loop.
When JavaScript Isn't the Right Tool
It's important to be objective about where JavaScript falls short. For computationally intensive tasks like image processing, real-time 3D rendering, or heavy data analysis, JavaScript's single-threaded nature becomes a bottleneck. The runtime overhead of the V8 engine can't match what compiled languages like Rust or C++ can achieve for the same workload. If you're building a browser game with complex physics, consider WebAssembly alongside JavaScript rather than trying to implement everything in pure JS. WebAssembly gives you near-native performance for the heavy computation while JavaScript handles the UI layer. Similarly, for server-side applications that need to handle thousands of concurrent connections, Node.js can become a limiting factor. While Node is excellent for I/O-bound work, CPU-bound tasks will block the event loop and degrade response times for all connected clients.

Building a Real Project: What the Theory Looks Like in Practice
Let me walk through what a typical JavaScript project looks like from start to finish, based on my experience building and maintaining several medium-sized applications over the past decade. Start by setting up a development environment that includes a package manager, a linter, and a bundler. Tools like Vite have made this process significantly simpler than it used to be, reducing setup time from an afternoon to about fifteen minutes depending on your needs. Structure your code using a modular approach. Each module should have a single responsibility, and dependencies should flow in one direction. This isn't just good practice—it's necessary for maintainability. I've worked on codebases where the dependency graph was so tangled that changing one feature required touching dozens of unrelated files.
Write tests that cover your critical paths. Unit tests should verify individual functions, while integration tests should verify that different parts of your application work together correctly. Don't try to test everything—focus on the logic that would be expensive to break and hard to debug when it does break. When deploying, consider the tradeoffs between different strategies. A single-page application can be served as static files from a CDN, which is fast and cheap. But if your application needs server-side rendering for SEO or performance reasons, you'll need a different architecture. The ecosystem moves fast, and new tools appear regularly. Stay pragmatic about adopting them. Just because a tool is popular doesn't mean it's the right choice for your project. Evaluate based on your specific requirements, not on hype or trending discussions.
Understanding JavaScript deeply takes time and experience, but following a structured path like this JavaScript Comprehensive Guide Walkthrough gives you a solid foundation to build on. The goal isn't to memorize every API or framework feature—it's to understand how the language works so you can reason about your code when things go wrong.