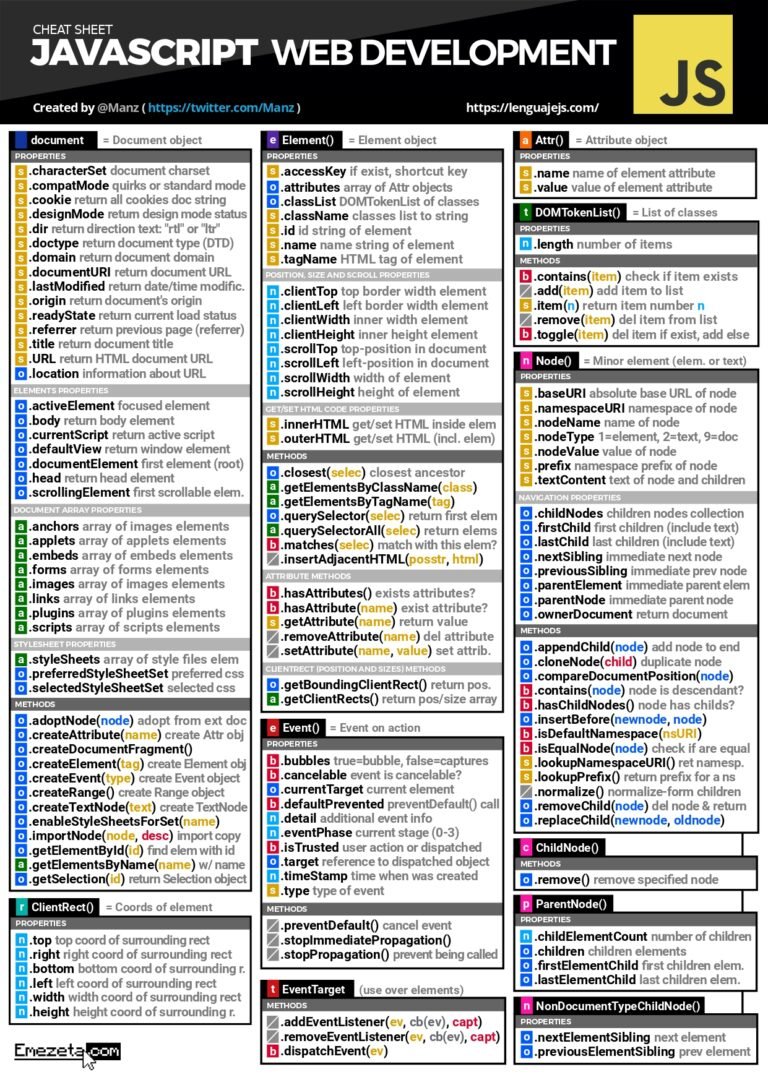
Why most JavaScript tutorials get it wrong
I spent years watching developers come up through JavaScript tutorials that taught them the surface stuff without the teeth. You know the ones—everything works in the example but breaks the second you try to apply it to a real project. This guide is trying to be different, which means skipping the motivational speech and getting straight into what actually matters when you're debugging at 11pm. There's a particular problem I ran into recently that most beginner guides wouldn't warn you about. I was working on a Node.js backend service where I needed to handle large JSON payloads from an external API. The data came back as stringified numbers larger than Number.MAX_SAFE_INTEGER, and JavaScript silently lost precision without throwing a single error. I spent about forty minutes chasing a bug that turned out to be a classic case of integer precision loss in JavaScript's double-precision floating point representation. The workaround was parsing those fields as BigInt immediately upon receipt, using a custom JSON reviver in JSON.parse(). This is the kind of thing that separates people who know JavaScript from people who merely use JavaScript tutorials that never mention it.
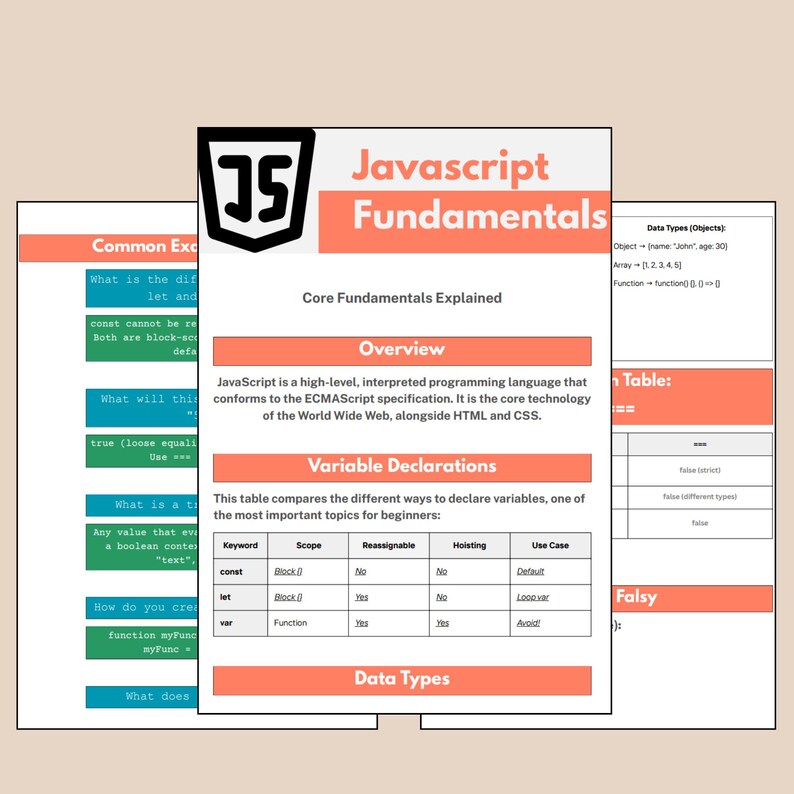
JavaScript Essential Guide With Examples
Let's start with closures because they're the foundation of almost everything you'll build, yet most developers treat them like a weird edge case instead of a primary tool. A closure is simply a function that retains access to its outer scope's variables even after the outer function has returned. That's the definition. Here's what it feels like in practice: you wrap some private state inside a function, expose only the methods that should manipulate it, and forget about it. It works until you accidentally capture a large object reference and create a memory leak. I've seen production servers grind to a halt because a closure held onto a DOM element or a huge array that the garbage collector couldn't touch. Always be deliberate about what you're closing over. Practical example: const createCounter = () => { let count = 0; return { increment: () => ++count, decrement: () => --count, getCount: () => count }; };
This is trivial code but it demonstrates the pattern. Every React hook, every event emitter library, and most state management solutions under the hood use this exact mechanism. Understanding closures means understanding the runtime of the language, not just its syntax.
The event loop explained without the hand-waving
Most explanations of the event loop talk about call stacks and queues without giving you a practical mental model. Here's mine. JavaScript is single-threaded. One thing happens at a time. When you schedule a setTimeout(fn, 0), that callback doesn't run immediately. It gets pushed into the microtask or macrotask queue depending on what it is, and it only executes when the call stack is completely empty. This is why your UI freezes less often when you chunk heavy operations using requestIdleCallback instead of running them synchronously. The critical insight that advanced tutorials skip: promises are microtasks. They execute before macrotasks like setTimeout and setInterval. If you chain multiple .then() calls, they all run in order during the same tick of the event loop, before any other pending macrotask gets a chance. This behavior is what makes async/await work predictably. It's also what trips people up when they expect asynchronous code to interleave with setTimeout callbacks in ways that don't actually happen. Example of microtask priority:
Get the Full Details
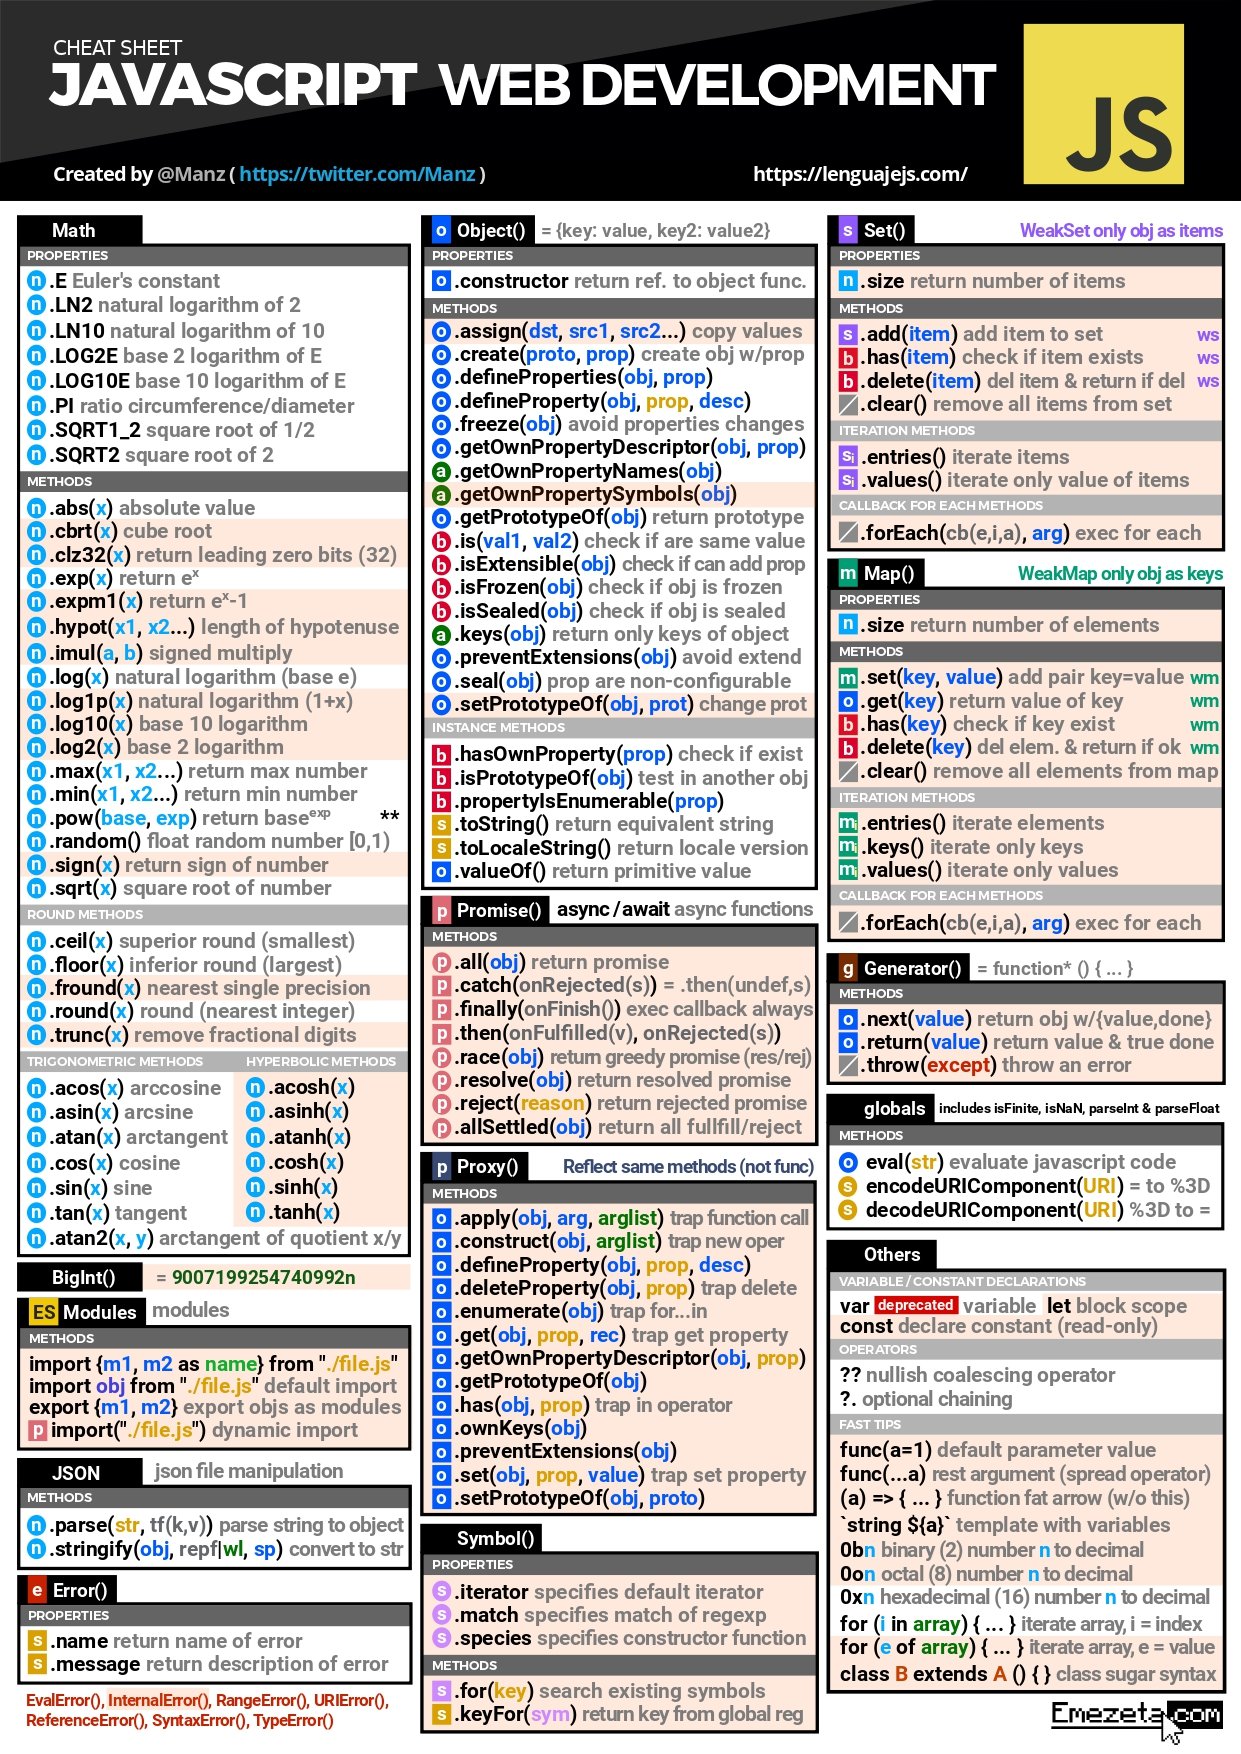
console.log('start'); setTimeout(() => console.log('timeout'), 0); Promise.resolve().then(() => console.log('promise')); console.log('end'); The output will always be start, end, promise, timeout. Not because of any special magic but because the event loop processes the microtask queue before moving to the macrotask queue. Memorize this ordering. It will save you hours of confusion when debugging race conditions in your code.
Prototypal inheritance versus class syntax
JavaScript has class syntax now. It looks like classical inheritance from Java or C#. It is not classical inheritance. Under the hood, classes in JavaScript are syntactic sugar over prototype chaining. The instanceof operator checks the prototype chain, not the class definition itself. This distinction matters when you're writing library code or working with frameworks that manipulate prototypes directly. I encountered this directly when debugging a third-party component library that used prototype manipulation for mixin-style composition. My code used class-based inheritance, and the library's methods were appearing on instances but not passing instanceof checks against the base class. The fix was to use Object.setPrototypeOf() to link the prototype chains manually. Nobody tells you this in a JavaScript tutorial because framework code abstracts it away, but when things break at that level, you need to understand the mechanism. Understanding the prototype chain:
function Person(name) { this.name = name; } Person.prototype.greet = function() { return 'Hello, ' + this.name; }; const alice = new Person('Alice'); console.log(alice.greet()); // 'Hello, Alice' console.log(alice.hasOwnProperty('name')); // true console.log(alice.hasOwnProperty('greet')); // false console.log(alice.__proto__ === Person.prototype); // true The hasOwnProperty check on greet returns false because greet lives on the prototype, not on the instance. This is how JavaScript achieves memory efficiency. Every instance shares the same prototype methods instead of each owning a copy. Classes don't change this. They just make the syntax cleaner while keeping the same underlying behavior.
Async patterns that actually work in production
Callbacks are dead. We all know this, but plenty of codebases still run on callback-heavy architectures. The modern approach uses promises and async/await, but there are nuances that beginner tutorials gloss over. One of the biggest is error handling. In callback style, you pass an error as the first argument. With promises, unhandled rejections are silent until they crash your process. With async/await, a single uncaught rejection can take down your entire request handler if you don't wrap it properly. I learned this the hard way on a service that processed batch jobs. A single failed API call inside a parallel promise.all() array would reject the entire batch, losing all the other results. The solution was wrapping each promise in a try-catch and resolving with a sentinel value instead of letting the rejection propagate. This tradeoff means you lose the automatic failure signal but gain resilience. For batch processing, resilience usually matters more than immediate failure notification. Production-safe parallel execution:

async function fetchAll(items) { const results = await Promise.all( items.map(async (item) => { try { const response = await fetch('/api/data/' + item.id); return await response.json(); } catch (error) { return { id: item.id, error: error.message, data: null }; } }) ); return results; } Notice the try-catch inside the map callback. Without it, one failure aborts everything. With it, you get partial results and can handle failures downstream. This pattern is essential for any service that calls external APIs in parallel. The performance impact is negligible because Promise.all still executes all fetches concurrently. You're not serializing anything. You're just containing the failures.
Type coercion traps that will cost you time
JavaScript's type coercion is one of the most misunderstood features of the language. The == operator performs coercion. The === operator does not. This rule is simple, but the edge cases are where people get burned. For example, null == undefined evaluates to true because JavaScript treats them as loosely equal during coercion. But null === undefined is false because they are fundamentally different types. NaN === NaN is false because NaN is defined as not equal to itself. These behaviors are consistent within the language specification, but they're not intuitive. I was reviewing a payment processing module once where a condition checked price == 0 to detect free items. The price field came from an API as a string "0", which coerced to the number 0 and passed the check. But when the field was an empty string "", it also coerced to 0, incorrectly marking an item as free. Switching to strict equality === caught the bug immediately. The fix was to parse the string to a number first, then compare with ===. This is a specific, concrete example of why type coercion catches people who rely on tutorials that only show the basic cases. The typeof operator behaves differently than expected:
typeof null; // "object" - this is a documented bug in the language typeof NaN; // "number" typeof []; // "object" typeof {}; // "object" typeof (() => {}); // "function" - this one is correct The typeof null returning "object" is a historical bug that will never be fixed because it would break too much existing code. The typeof array returning "object" is by design because arrays are objects in JavaScript. If you need to distinguish arrays from plain objects, use Array.isArray() instead of relying on typeof. There is no better alternative that doesn't involve downlevel polyfills.
Memory management and performance pitfalls
JavaScript garbage collection is automatic, which means developers treat memory like it's infinite. It isn't. Closures are the most common source of memory leaks in JavaScript applications. When you create a closure, it captures references to all variables in its outer scope. If that closure is retained somewhere—perhaps in an event listener, a timer callback, or a global object—the captured variables cannot be garbage collected, even if they're no longer logically needed. The worst case I've dealt with involved a charting component that stored references to DOM elements inside a closure used by an animation loop. Every frame, the closure held onto element references that were no longer in the document. Over several hours of use, the browser's memory footprint grew from 50MB to over 2GB before the process was killed. The fix was replacing the closure-based storage with WeakRef, which allows the garbage collector to reclaim the referenced objects when no strong references remain. WeakRef is relatively new in JavaScript and requires careful handling with FinalizationRegistry if you need cleanup notifications, but it solved the problem cleanly. Detecting closures that outlive their usefulness:
const weak = new WeakRef(largeObject); const weakRef = weak.deref(); if (weakRef !== undefined) { console.log('still in memory'); } else { console.log('was garbage collected'); } WeakRef.deref() returns undefined when the target has been collected. This is useful for implementing caches and object pools without preventing cleanup. The performance overhead is minimal compared to the alternative of manually tracking and clearing references.
When to use module systems
JavaScript had no native module system for most of its history. Libraries invented their own solutions—CommonJS for Node, AMD for browsers, UMD for both. Now there's ES modules, which are the standard. But there's a gotcha that most JavaScript Essential Guide With Examples resources don't mention: ES module exports are live bindings, not snapshots. When you export a variable, changes to that variable are reflected in all imports automatically. This is different from CommonJS, where exports are copied by value at import time. This caused a real problem for me when I was refactoring a shared configuration module. The original code used CommonJS require(), which created a copy of the config object at import time. I switched to ES modules without adjusting the initialization logic, assuming the behavior would be identical. It wasn't. Some modules imported the config before it was fully populated and got an incomplete snapshot. Others imported after and got the full object. The inconsistency showed up as intermittent bugs in production that were nearly impossible to reproduce. The solution was to export a function that returns a fresh copy of the config instead of exporting the config object directly, or to ensure all imports happen after initialization completes. Live binding behavior in ES modules:
// config.js let config = {}; export const setConfig = (value) => { config = value; }; export const getConfig = () => config; // app.js import { setConfig, getConfig } from './config.js'; setConfig({ debug: true }); console.log(getConfig()); // { debug: true } - reflects latest value This pattern avoids the live-binding surprise because consumers call a function rather than reading a variable directly. It's a small change but it prevents the subtle divergence that occurs when different parts of your codebase import at different times.
Practical debugging strategies
The best debugging tool in JavaScript is still console.log(), despite everyone telling you to use a debugger. There's no shame in it. Breakpoints pause execution, which can change timing-sensitive behavior in asynchronous code. Logging shows you the actual state at the exact moment you need it. Use console.table() for array data. Use console.trace() when you need to understand how you got to a particular point in the call stack. Use console.time() and console.timeEnd() to measure performance bottlenecks without adding external tooling. I once spent two days debugging a race condition in a WebSocket-based real-time application. The issue only occurred under high load when messages arrived faster than the client could process them. Set breakpoints and the messages would arrive in a different order because the debugger paused execution. Stepping through the code made the bug disappear. The solution was to add timestamp logging to each message and compare the arrival order against the processing order. The logs revealed that messages were being reordered by the browser's task queue, not by the application logic. Switching to a priority queue for message processing resolved the issue entirely. No amount of breakpoint debugging would have caught this because the debugger was part of the problem.

What most guides omit about JavaScript
JavaScript is not a perfect language. It has design flaws inherited from its original 10-day specification period. It makes incorrect assumptions about how programmers think. It treats NaN as a number, which makes numeric validation tedious. It has parseInt() without a radix parameter defaulting to decimal, which means parseInt("08") returns 0 in some browsers because it interprets leading zeros as octal. These are not minor issues. They are structural problems that affect real code every day. The pragmatic response is not to avoid JavaScript. It's to know where the traps are and work around them. Use === instead of == everywhere. Always specify the radix in parseInt(). Check for NaN with Number.isNaN() instead of checking isNaN() because Number.isNaN() doesn't coerce its argument. Use Array.isArray() for arrays. Use Object.hasOwn() or Object.prototype.hasOwnProperty.call() instead of the in operator for property checks. These are small choices that prevent a disproportionate number of bugs. The community response to these issues has been mixed. Some projects adopt TypeScript to catch these problems at compile time. Others rely on ESLint rules like eqeqeq and radix to enforce correct patterns. Both approaches work. TypeScript catches more errors but adds build complexity. ESLint catches fewer errors but adds almost no overhead. The choice depends on your team's tolerance for tooling and your willingness to trade development speed for safety.
I've used both approaches on production projects. TypeScript projects tend to have fewer runtime type errors but more friction during refactoring because the type system is strict about changes. ESLint-only projects move faster initially but accumulate runtime bugs that surface later. Neither is universally better. The best teams use a combination—ESLint for style and correctness rules, TypeScript for types where the value justifies the overhead. If you're starting a new project and the team has JavaScript experience but limited TypeScript experience, don't force TypeScript on day one. Get the project working with solid ESLint configuration first. Introduce TypeScript when you hit a problem that static typing would have prevented. This avoids the overhead of learning a new system before you understand why you need it. Most JavaScript Essential Guide With Examples resources skip this advice because they're written for people who already know the answer, not for people who are trying to figure out whether they need the answer.
Resources that actually help
The MDN Web Docs remain the most reliable reference for JavaScript API documentation. It's not glamorous but it's accurate and covers edge cases that other sources omit. The ECMAScript specification is the authoritative source but it's written for language designers, not practitioners. Use it when you need to resolve a dispute about behavior, not when you're learning the language. Kyle Simpson's You Don't Know JS series is still useful for deep dives into closure scoping and prototype chains, though some of it is dated. For current best practices, the Node.js documentation and the V8 engine blog provide insights into how the runtime actually works, which is more valuable than any tutorial. One resource that deserves more attention is the JavaScript.info website. It covers topics that most guides skip, like garbage collection internals, the event loop implementation details, and the differences between browser and Node.js environments. It's written clearly without the hype that characterizes so much technical writing. I reference it regularly when I need to verify a behavior against the specification rather than against someone's blog post.
Final thoughts on learning JavaScript
Learning JavaScript thoroughly takes longer than most people expect because the language rewards deep understanding with predictable behavior and punishes surface-level knowledge with confusing bugs. The gap between "I know JavaScript" and "I understand JavaScript" is measured in months of production experience, not weeks of tutorial completion. The examples and patterns in this guide are based on situations where things broke in ways that tutorials didn't predict. That's the actual curriculum. The official language specification is the textbook, but the textbook alone won't teach you how to handle the edge cases. The people who master JavaScript are the ones who read the errors carefully instead of googling the error message and copying a solution. They understand why the error happened, not just how to make it go away. This mindset takes time to develop. It's not something a guide can instill. But it's the difference between writing code that works and writing code that stays working.

