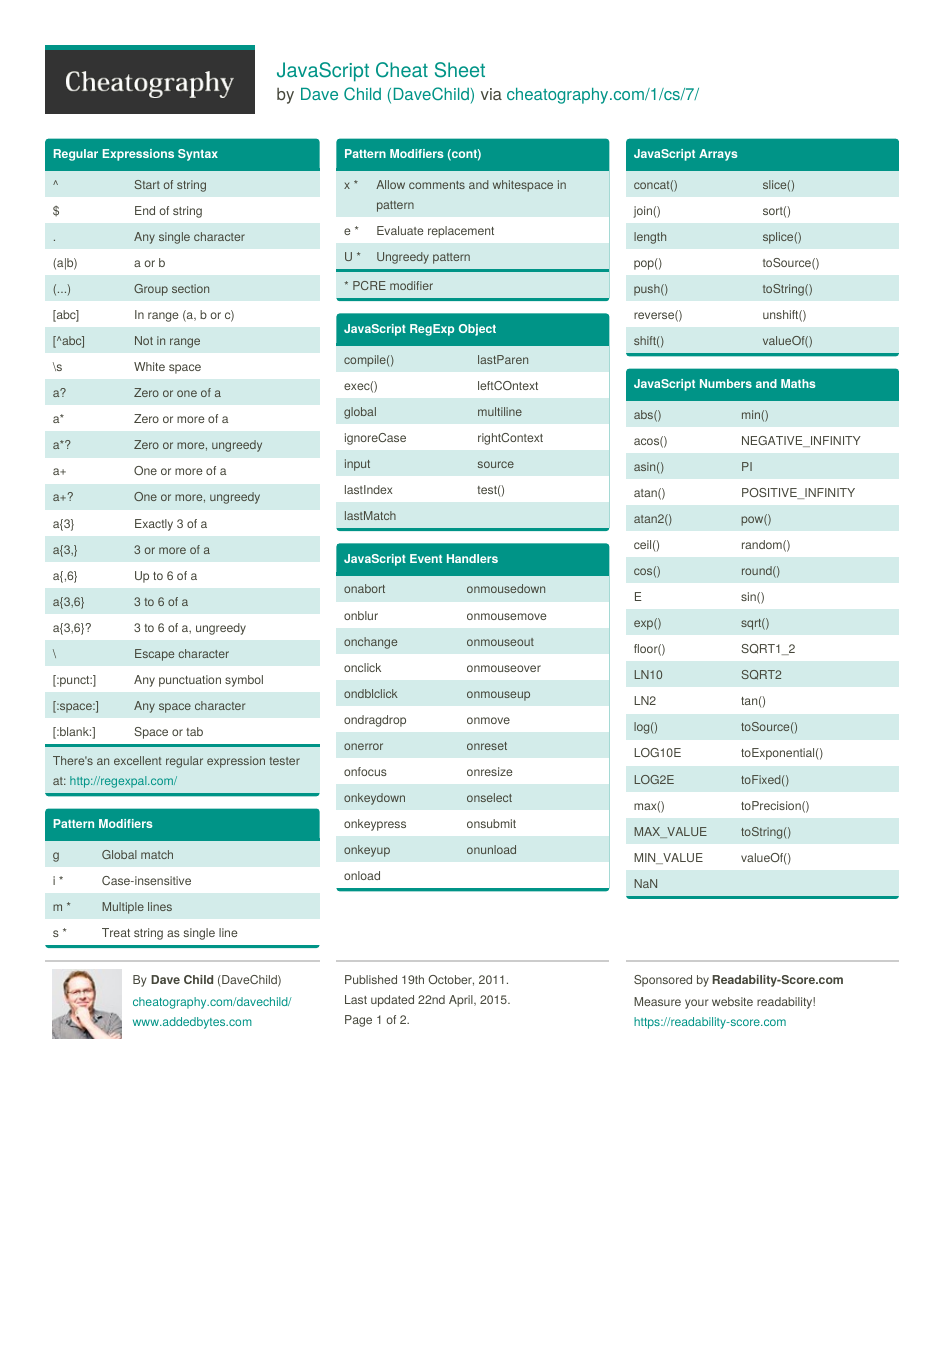
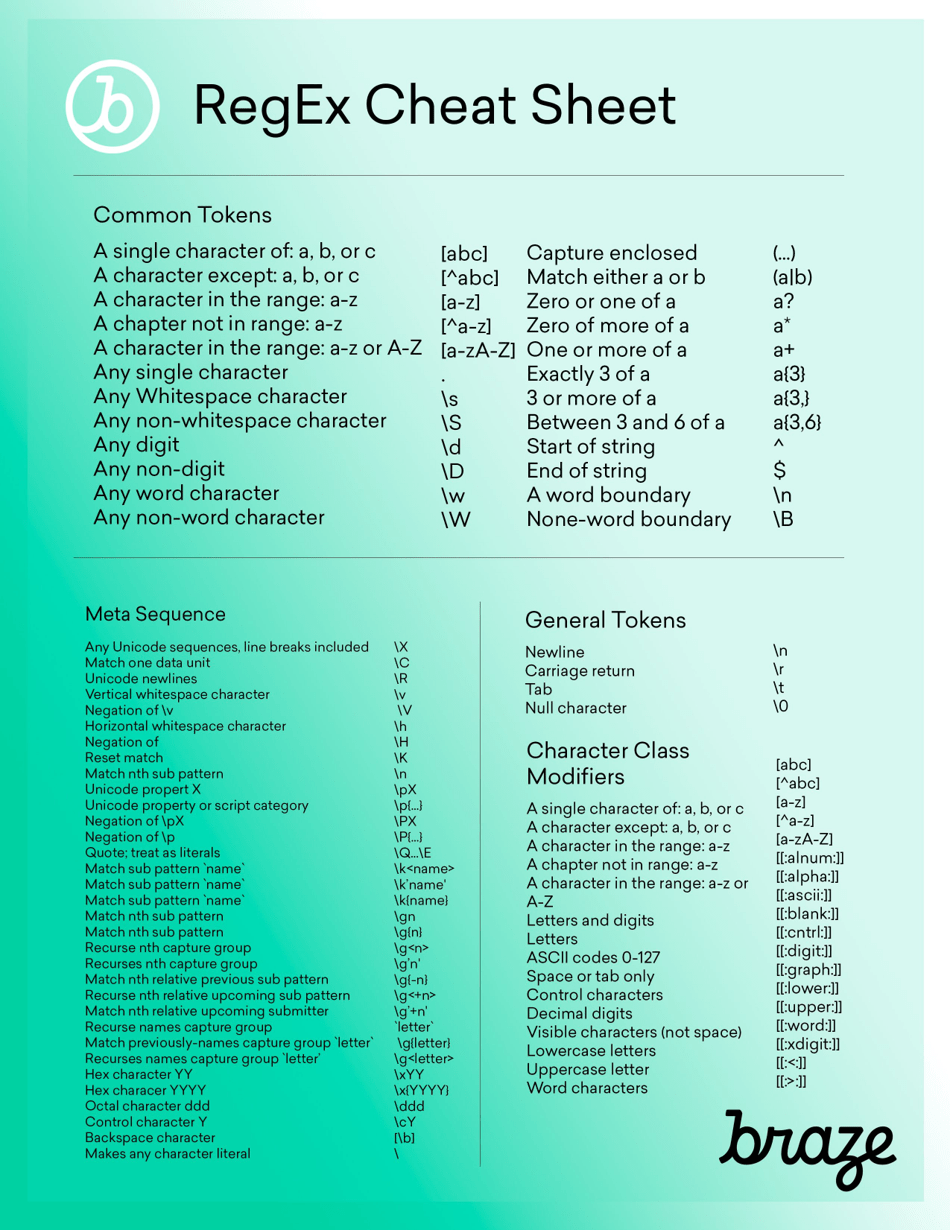
Regular expressions are a pain in JavaScript if you approach them the wrong way. Most people build patterns by copying from Stack Overflow and testing them once in the console. That works until it doesn't. A JavaScript Regex Cheat Sheet becomes useful the moment you stop treating regex like magic and start treating it like a language with its own grammar.
I once spent three hours debugging a validation pattern that refused to match a specific email format. The input looked correct. The pattern looked correct. The issue was the `u` flag being omitted, which caused JavaScript's regex engine to treat the character class as surrogate pairs rather than Unicode code points. The email contained a non-ASCII character that technically qualified under RFC 5322 but fell into a Unicode range that the engine couldn't parse without that flag. Once I added `u`, the pattern matched immediately. That cost me half a workday.
JavaScript Regex Cheat Sheet
Understanding the basics is table stakes. Every JavaScript Regex Cheat Sheet covers character classes like \d, \w, and \s, but the real friction comes from knowing when those shorthand tokens break in edge cases. \d matches any Unicode decimal digit when the `u` flag is present, but without it, it only matches ASCII 0 through 9. That distinction matters more than most developers realize.
Character classes deserve attention because they behave differently depending on context. Square brackets create negated classes with a caret: [^abc] matches anything except a, b, or c. But placing a hyphen inside the brackets creates a range. [a-z] matches lowercase letters, while [a-zA-Z0-9] covers the full alphanumeric set. The hyphen loses its special meaning when placed at the start or end of the class: [-abc] matches a literal hyphen or any of those letters. This trips up people who assume the hyphen always means "range."
Anchors define where a match must occur. ^ anchors to the start of the string or line with the `m` flag. $ anchors to the end. Without the `m` flag, ^ and $ only match the absolute beginning and end of the entire string, not individual lines. If you're processing multi-line text, the `m` flag is mandatory for line-level anchoring.
Quantifiers control repetition. The most common mistake I see is using greedy quantifiers when lazy ones are required. .* will consume as much as possible before backtracking, which means /<(.*?)>/g and /<.*?>/g behave differently from /<.*>/g. The greedy version on a string like <div>hello<span>world</span></div> would match everything from the first < to the last > in a single hit. The lazy version returns two separate matches. I've corrected this in production code more times than I care to count.
Lookahead assertions are where regex gets genuinely powerful and genuinely confusing. Positive lookahead (?=pattern) checks that a pattern follows without consuming it. Negative lookahead (?!pattern) does the opposite. For example, validating a password that must contain at least one number and one special character: ^(?=.*\d)(?=.*[!@#$%^&*]).+$. This works but it's slow on large inputs because each character position triggers two full scans of the remaining string. If performance matters, consider a simpler validation approach instead of squeezing everything into one pattern.
The `g` flag changes how String.prototype.match() behaves entirely. Without g, "abc123def".match(/\d+/) returns an array with the match and index properties. With g, it returns only an array of all matching substrings: ["123"]. If you need capture groups with g, you have to use RegExp.prototype.exec() in a loop instead. This inconsistency is one of the most frequently overlooked aspects of JavaScript regex.
Pitfalls That Cost Me Time
One issue that never gets enough discussion is the interaction between non-capturing groups and alternation. Consider /(foo|bar)?baz/. The question mark applies to the entire group, making it optional. But if you write /foo|bar?baz/ without parentheses, the `?` only modifies the r. The engine interprets this as either "foo" or "rbaz." Parentheses define the scope of quantifiers and modifiers, and getting that wrong produces patterns that match the wrong strings.
Another problem is string escaping versus regex escaping. In JavaScript, "\\d" creates a string containing backslash-d, which the regex engine reads as a digit character class. But "\\\\d" creates a string with two backslashes and a d, which the regex engine reads as a literal backslash followed by d. When building patterns dynamically from template literals or concatenation, the escaping layer compounds quickly. I recommend defining patterns as regex literals whenever possible: /\d+/ instead of new RegExp("\\d+"). The latter is fine for runtime-generated patterns, but readability degrades fast.
JavaScript regex doesn't support recursive patterns or arbitrary lookbehind. If you need to match nested structures like balanced parentheses, regex alone won't solve it efficiently. You'd need a proper parser or at minimum a state machine. I learned this the hard way when a colleague insisted on using a regex to validate HTML tags with nesting. The pattern worked for one or two levels but produced false positives beyond that. We rewrote it as a stack-based validator in under an hour.
Practical Pattern Examples
Here are patterns I actually use in production code, not theoretical examples.
ISO date validation: ^\d{4}-(0[1-9]|1[0-2])-(0[1-9]|[12]\d|3[01])$ — This validates year-month-day format without accepting impossible dates like February 30th. If you need full date correctness including month length and leap years, use the Date constructor as a secondary check rather than extending the regex further.
Email validation: ^[^\s@]+@[^\s@]+\.[^\s@]+$ — This catches the vast majority of obviously invalid emails. It's intentionally loose because RFC 5322 compliance would require a pattern thousands of characters long, and no browser or server treats a technically valid but impractical email any differently in practice.
URL extraction: https?:\/\/(?:www\.)?[-a-zA-Z0-9@:%._\+~#=]{1,256}\.[a-zA-Z0-9()]{1,6}\b(?:[-a-zA-Z0-9()@:%_\+.~#?&\/=]*) — This is the standard pattern from the URL spec simplified. It handles http and https, optional www, common TLDs, and query strings. It fails on newer generic top-level domains with unusual characters, but those are rare in practice.
Hex color code: ^#?([0-9a-fA-F]{3}|[0-9a-fA-F]{6})$ — Matches both shorthand #fff and full #ffffff forms with optional hash prefix.
Phone number (US): ^\+?1?[-.\s]?\(?\d{3}\)?[-.\s]?\d{3}[-.\s]?\d{4}$ — Accepts formats like +1-555-123-4567, (555) 123-4567, and 555.123.4567. Not suitable for international numbers without significant modification.
Performance Considerations
Regex compilation in JavaScript is relatively expensive compared to simple string operations. The V8 engine optimizes frequently used literal patterns, but patterns constructed via new RegExp() inside a loop get recompiled on every iteration. If you're matching the same pattern across thousands of strings, hoist the regex creation outside the loop.
Certain patterns cause catastrophic backtracking. A classic example: ^(a+)+$ applied to a string like aaaaaaaaaab. The engine tries every possible way to distribute the as between the inner and outer groups, and the number of combinations grows exponentially. For inputs of length 30, this can take several seconds. Adding a possessive quantifier isn't possible in JavaScript regex, but you can often rewrite the pattern to avoid ambiguity: a+ instead of (a+)+ achieves the same result without the exponential blowup.
Use the .test() method when you only need a boolean result. It's faster than .match() because it doesn't construct result arrays or capture group objects. For high-throughput validation, this difference is measurable.
The sticky flag y matches only at lastIndex, which makes it useful for parsing token streams where you need to advance position deliberately. It behaves differently from g in that a failed match resets lastIndex to zero rather than trying the next position. This is niche but important for custom parsers.
If you need something more powerful than JavaScript regex offers, look into modules like XRegExp or consider using a dedicated parser library. JavaScript's regex engine is good for text filtering and validation, but it's not a parsing tool. Knowing the boundary between those two use cases saves a lot of frustration.