What You Actually Need to Know About JDE Training Resources
Most people searching for a Jd Edwards Training Manual are trying to figure out how to get from zero to functional in JD Edwards EnterpriseOne. The reality is that there isn't one single manual that covers everything. Oracle's documentation is scattered across multiple platforms, and some of it is years out of date. You need to know where to look and what to ignore. The closest thing to an official training manual is Oracle's Education curriculum paired with the JD Edwards EnterpriseOne documentation set. Oracle offers classroom courses and online learning paths, but the free materials live on the JD Edwards World site and in the Knowledge Center. The manuals you'll actually use day to day are the BookByBook guides. Each business function has its own book — R42 series for accounting, P03 series for customers, F4101 for inventory. These are available as HTML through the application itself or as PDFs on Oracle's documentation portal. I spent weeks cross-referencing these before I stopped treating them like textbooks. They're reference material, not learning sequences. If you read them cover to cover hoping to understand the system, you will waste your time. Use them when you hit a specific problem. Look up the form or business function you're working with, find the relevant book, read the process flow section, then move on.
The Practical Path Most People Should Take
Start with the application itself. Press F1 on any field to pull up the help text. It is basic, often incomplete, but it tells you what the field does, what table it writes to, and what validation rules apply. From there, learn the object types. A version is a saved set of selection and sort criteria. A business function is the executable logic behind a menu choice. A data model is the table structure. A form is what the user sees. Understanding what each object type controls changes how you approach any problem. The PSC BookServer was built for exactly this kind of lookup. It is an internal knowledge base that most companies leave unused because nobody told new hires it exists. It contains design documents, release notes, known issues, and configuration guides. Access it through the JDE website and search by object name. If you are working on a custom process and the standard documentation is vague, the BookServer usually has something useful. Here is a concrete example of why knowing your object types matters. A few years ago I was troubleshooting a cost update issue in manufacturing. The actual cost wasn't rolling through properly for certain item-master records. The surface behavior looked like a B01052460 job failing silently. The standard help pointed toward the cost rebuild process, which didn't help. I traced the problem back to a data integrity issue in the F41021 table. Certain items had mismatched unit-of-measure records in the F41001 and F41021 relationship. The B01052460 job was skipping those records because the UOM conversion wasn't resolving. The fix wasn't a configuration change or a process adjustment. It was a data correction in F41001 where the alternate UOM conversion factors were blank for about forty items across two warehouses. Once I ran a targeted update through a simple SQL statement in the environment, the cost roll completed on the next run. I spent three days on that because I was looking in the wrong layer first.
Common Pitfalls Beginners Miss Completely
The biggest mistake I see is treating versions as interchangeable. Every menu option in JDE runs through a version, and each version has its own selection criteria, sort order, and environment overrides. When someone copies a version without understanding what the selections do, they break downstream processes. For example, a version for the F4211 line entry form might have a selection on SOPT like "SOPT = 'S'". If you copy that version and remove the selection to try to see all order types, you will now see credit memos and invoices mixed with sales orders, and any downstream batch process tied to that version will process the wrong document types. Another thing nobody warns you about is the difference between run-time validation and compile-time validation. Some fields validate when you save. Others don't validate until the process runs. This means you can create a record that looks valid in the form but fails during batch processing. The F0911 ledger entry is the most common offender. You can enter a combination in F0911 that passes the form-level check but violates the GL account structure at runtime. The error only surfaces when you run the batch, not when you enter the data. Form personalization is another trap. Users love it because it lets them hide columns and rearrange fields. But when you push a custom version to five hundred desktops, personalized forms break because the personalization file is stored locally and doesn't travel with the version. I've seen support tickets where the reported issue was "the form is missing fields after upgrade" when the real problem was that the users had personally removed those columns six months ago and the upgrade wiped their local settings.
Get the Full Details
What These Resources Don't Cover and Why That Matters
The official documentation assumes you are working in a standard Oracle template deployment. It does not cover customizations, third-party integrations, or the modifications most companies make to their F tables. If your company has custom fields added to F4211 or a modified address book structure, the manual is almost useless for your situation. You need internal documentation from your implementation partner or the notes left by the people who built your custom objects. That documentation rarely exists in a centralized location. It lives in email threads, shared drives, and the minds of people who have already left the company. Oracle's training courses are structured for people who learn best in a classroom setting with a guided curriculum. If you are self-directed, they move too slowly and skip over the things you actually need to know. The gap between the course material and real work is wide. Courses teach you how to navigate the standard menus and run standard processes. They don't teach you how to debug a failed batch job or trace a data issue through nine layers of validation. For practical skill-building, the most effective approach is pairing the books with sandbox access. Set up a test environment that mirrors your production data structure. Break things on purpose. Run a batch job with the wrong selections and watch what fails. Create a version with bad sort order and see how the report output changes. This takes about twice as long as just reading the documentation, but it builds the kind of intuition that prevents you from making the same mistake twice.
There are also community forums and the JD Edwards User Community website where practitioners share solutions. The quality varies wildly. Some posts are from certified consultants who know what they're talking about. Others are guesses that have been upvoted because they sound plausible. Cross-reference everything you find there with the official documentation before applying it to a live system.
A Note on Downloadable PDFs You Find Online
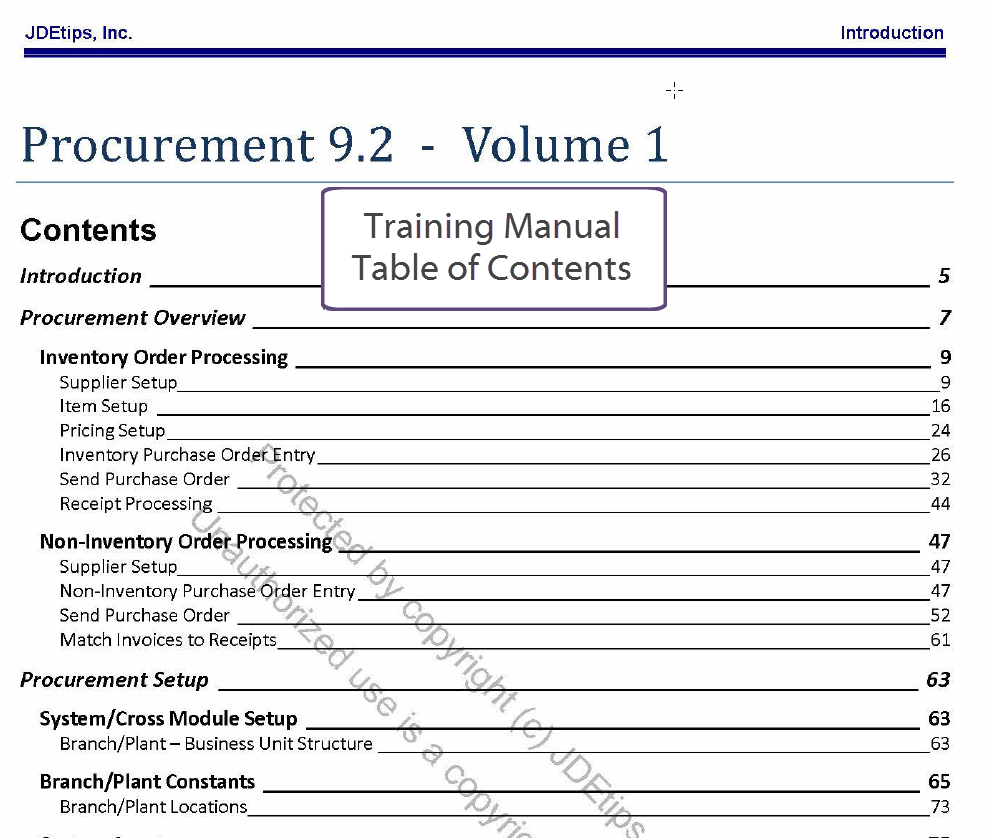
Search results will show dozens of PDFs claiming to be "the complete JDE training manual." Most of these are compiled from older documentation releases, sometimes from JD Edwards World rather than EnterpriseOne, and sometimes they are missing entire sections. A PDF from 2012 won't cover features added in later releases. An old World manual won't have the EnterpriseOne architecture. If you use a downloaded PDF, verify the release version against your own system. R9.2.x features won't appear in an R8.x document. The effort to verify takes ten minutes. The cost of following outdated instructions is measured in broken processes and wasted hours.