Building a Kafka Connect Architecture Diagram that doesn't look like a mess
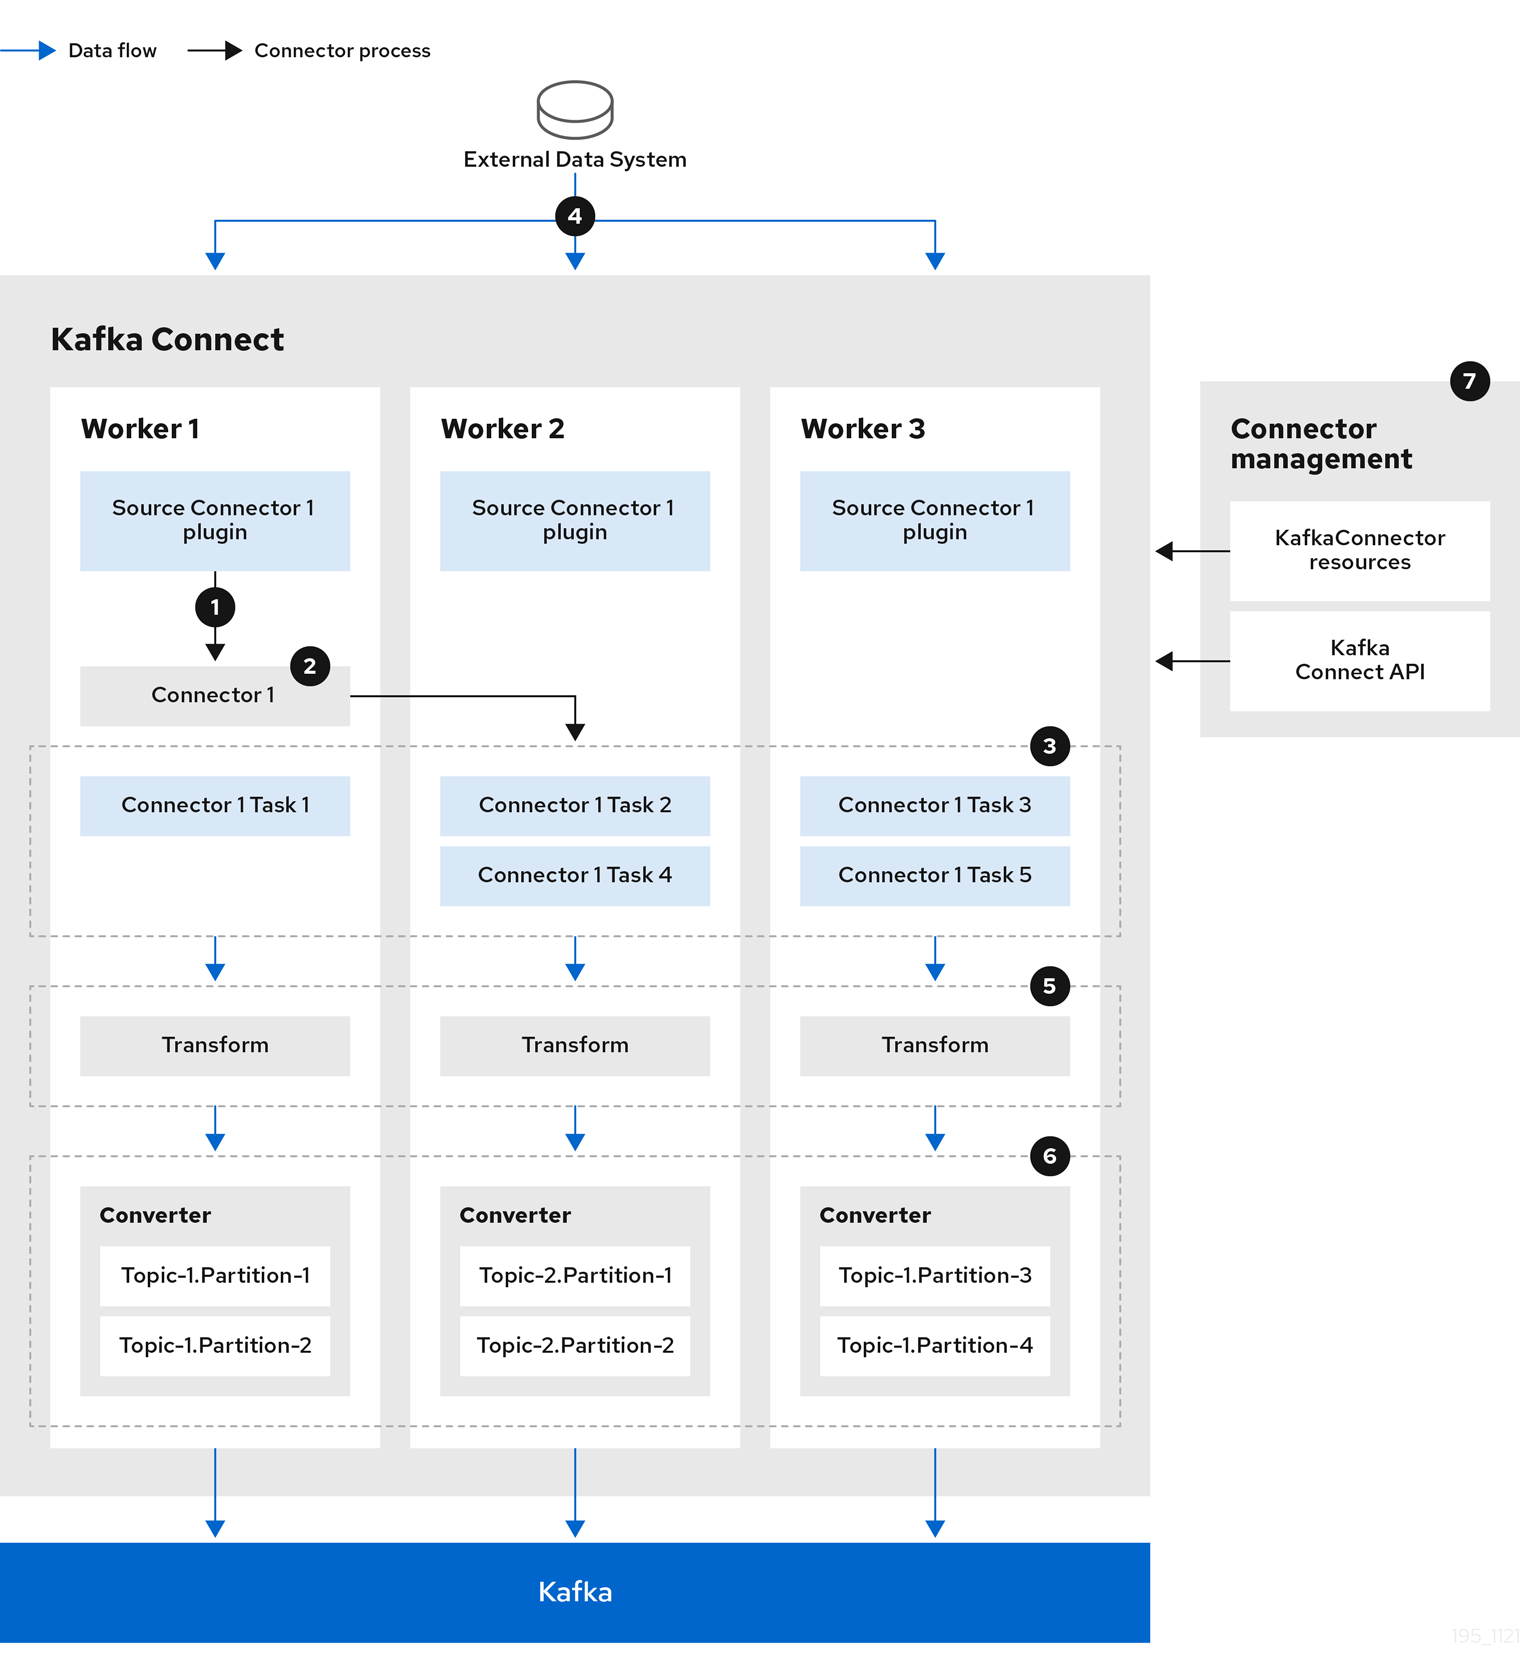
Most people trying to draw a Kafka Connect Architecture Diagram end up with either a child's crayon sketch or something that requires a magnifying glass to read. The problem is that Connect sits in the middle of everything, so every diagram tries to show too much at once. I've spent the better part of three years maintaining diagrams for production Kafka deployments, and I've learned that clarity comes from knowing what to leave out. Here's what actually matters in a useful diagram, and how I build one from scratch.
Kafka Connect Architecture Diagram
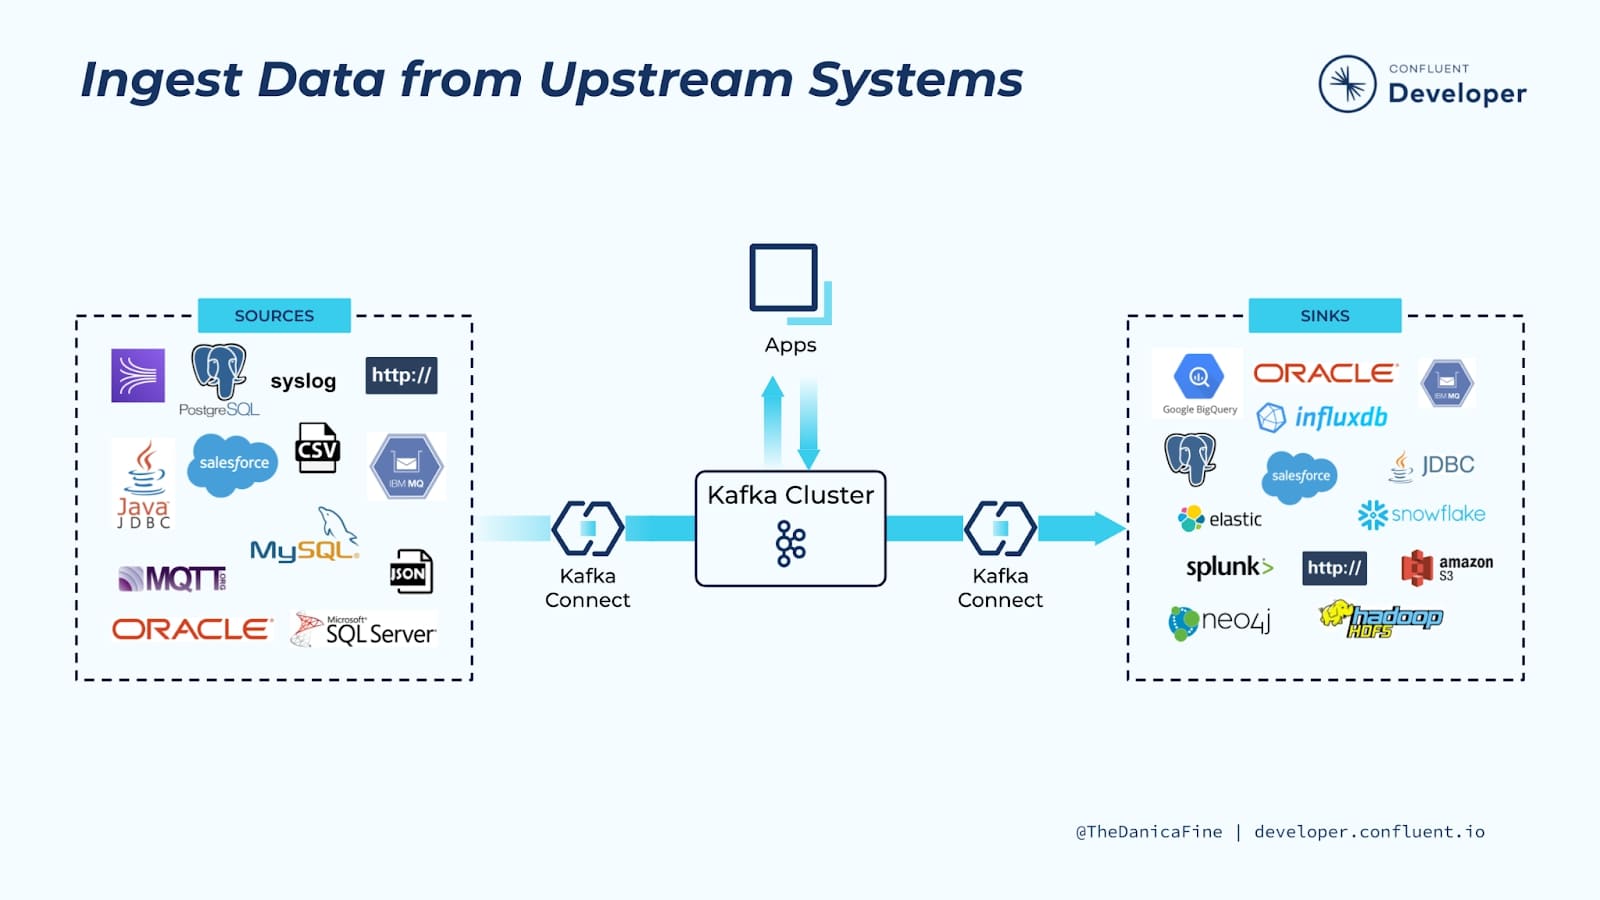
Start with three layers. Source tier, the cluster itself, and sink tier. That's the skeleton. Everything else is decoration unless your audience specifically needs to see it. The source tier gets connectors that feed data in. You don't list every connector type. Pick the ones running in your environment. If you're pulling from Postgres, Oracle, and a Kafka topic, draw three boxes labeled with those names, connected by arrows pointing toward the Connect workers. A single line with an arrow says everything about direction. Don't add color coding. Don't add gradients. Black lines on white backgrounds are legible from ten feet away or on a phone screen at 2 AM when someone is on call. The Connect workers go in the center. This is where most diagrams go wrong. People draw one box labeled "Kafka Connect" and call it a day. Real deployments run multiple workers across multiple nodes. Show at least two worker boxes. Label them Worker 1 and Worker 2 if you have two, Worker 1 through 4 if you have four. Add a small note under each one indicating whether it's running in distributed or standalone mode. Distributed mode means task assignment happens automatically. Standalone means you're responsible for manual distribution and you should probably switch if you have more than one developer touching the config files.
The Kafka cluster sits below the workers. Two boxes for the brokers is enough. Three if you want to show redundancy. Draw lines from each worker to each broker. You don't need to show every internal communication channel. Topic names go on the lines if they matter. Leave them off if the reader already knows what topics your pipeline uses. The sink tier mirrors the source tier but in reverse. Boxes for your destination systems with arrows pointing away from the Connect workers. Elasticsearch, S3, a database, another Kafka cluster downstream. Label each with the connector name you're actually using. "S3 Sink" is more useful than just "S3" because someone reading the diagram five months from now needs to know whether you're using the official S3 connector or a custom implementation. Schemas go in the Schema Registry. That's a separate box somewhere to the side. One line from each worker pointing to it. Don't overcomplicate this part. Most teams use Avro with the Confluent Schema Registry. If you're doing JSON Schema or Protobuf, note it in a single word next to the box. Nobody needs a paragraph explaining schema evolution at this level of detail.
Get the Full Details

Rest API endpoints are easy to forget until you need them. Add a small box labeled "Connect REST API" near the workers with a line connecting it. This is what you hit with curl commands when you're deploying connectors or checking status. It matters to operators. It doesn't matter to executives looking at a high-level overview, so put it in a corner rather than making it a focal point. I ran into a specific problem last year that taught me to always include the offset storage topic in these diagrams. We had a connector failover scenario where tasks were reassigned to different workers, and the team couldn't figure out why data was being duplicated. The root cause was that the offset topic configuration used a replication factor of one in our staging environment, which meant when the only broker holding those offsets went down, the connector lost its place in the source data. We drew the diagram after the incident to prevent recurrence, and I always make sure to add a line from each worker to a box labeled "offset.storage.topic" with a note about the replication factor. It took about twenty minutes to add that detail, and it saved us from a similar outage two months later. Tools matter less than you'd think. I use draw.io for most work because it's free, exports cleanly to PNG and SVG, and handles multi-page diagrams without complaint. Lucidchart is fine if your company already pays for it. Visio works if you're stuck in a Microsoft shop. The diagram tool is not the hard part. The hard part is deciding what to omit.
Here are the things beginners consistently include that clutter the diagram without adding information. Consumer groups for every single connector. If you have twelve connectors, don't draw twelve consumer group boxes. One generic label near the workers is enough. Internal Kafka topics like __connect-configs, __connect-offsets, and __connect-status. These exist whether you draw them or not. Mention them once in a small footnote if your audience needs to know they're there. Authentication details. SSL certificates, SASL configs, mTLS handshakes. These belong in an operations runbook, not on an architecture overview. You can add a separate appendix page for security configuration if someone asks for it. One counter-intuitive thing about Connect diagrams that most people miss. The horizontal scaling story is almost always wrong in these drawings. Everyone draws workers in a row like identical processors. In practice, your connector assignment depends on partition counts, key serializers, and workload distribution. If you have a source connector reading a topic with 48 partitions and four workers, each worker handles roughly 12 partitions. But if you mix connectors with different partition counts, some workers end up doing significantly more work than others. A good diagram includes a small table or note showing the partition-to-worker mapping for your actual deployment. I started adding this after watching a team burn through their broker resources because the diagram they followed assumed even distribution that didn't exist in reality. Another nuance that catches people off guard. Connector restart behavior. When a connector fails and auto-restarts, it starts from its last committed offset in the offset storage topic, not from the beginning or the end of the source data. This is documented behavior, but it shows up repeatedly in diagrams where people assume failed connectors either lose data or reprocess everything. Add a short annotation near the offset storage topic box that says "restarts resume from last committed offset" and you prevent a whole class of misunderstanding. Five words that save hours of confusion during incident response.
Limitations worth stating bluntly. Kafka Connect is not great at very high throughput individual message processing. The framework adds overhead for serialization, deserialization, and task management. If you're moving terabytes per day through a small cluster, you'll see CPU contention on the workers before you hit any Kafka broker limits. The diagram won't show this, but your architecture should account for it by showing separate worker pools for heavy vs. light connectors. Also, Connect has no built-in exactly-once semantics across source-to-sink for most connector pairs. Transactional delivery works within the Kafka ecosystem, but when you're reading from a relational database and writing to something external, you get at-least-once delivery and you need idempotency handling in your sink or your data will have duplicates on retries. Put a small warning note about this on the diagram. It saves someone from discovering it during a production incident. If you need a starting template, the Confluent documentation has a basic architecture diagram you can download and modify. It's accurate but sparse, missing details like the REST API, schema registry connections, and offset storage that matter for real deployments. I usually start from that template and add the missing pieces. For teams that want something closer to production-ready, I've seen people adapt the diagram from the Confluent Kafka Connect Reference Guide, which includes a slightly more detailed version with worker configuration notes. Neither covers edge cases like multi-cluster deployments or Cross-Cluster Replication scenarios, so you'll need to extend those anyway. The file format you deliver matters more than the content in some orgs. SVG scales without quality loss and embeds cleanly in Confluence pages. PNG is fine for presentations but blurs when projected. PDF preserves layout across platforms but is hard to edit collaboratively. I default to SVG for internal documentation and export PNG only when sending to people who insist on opening files in basic image viewers. Whichever format you choose, keep the source file in your version control system alongside your infrastructure configs. Diagrams rot faster than code when nobody can track changes to them.
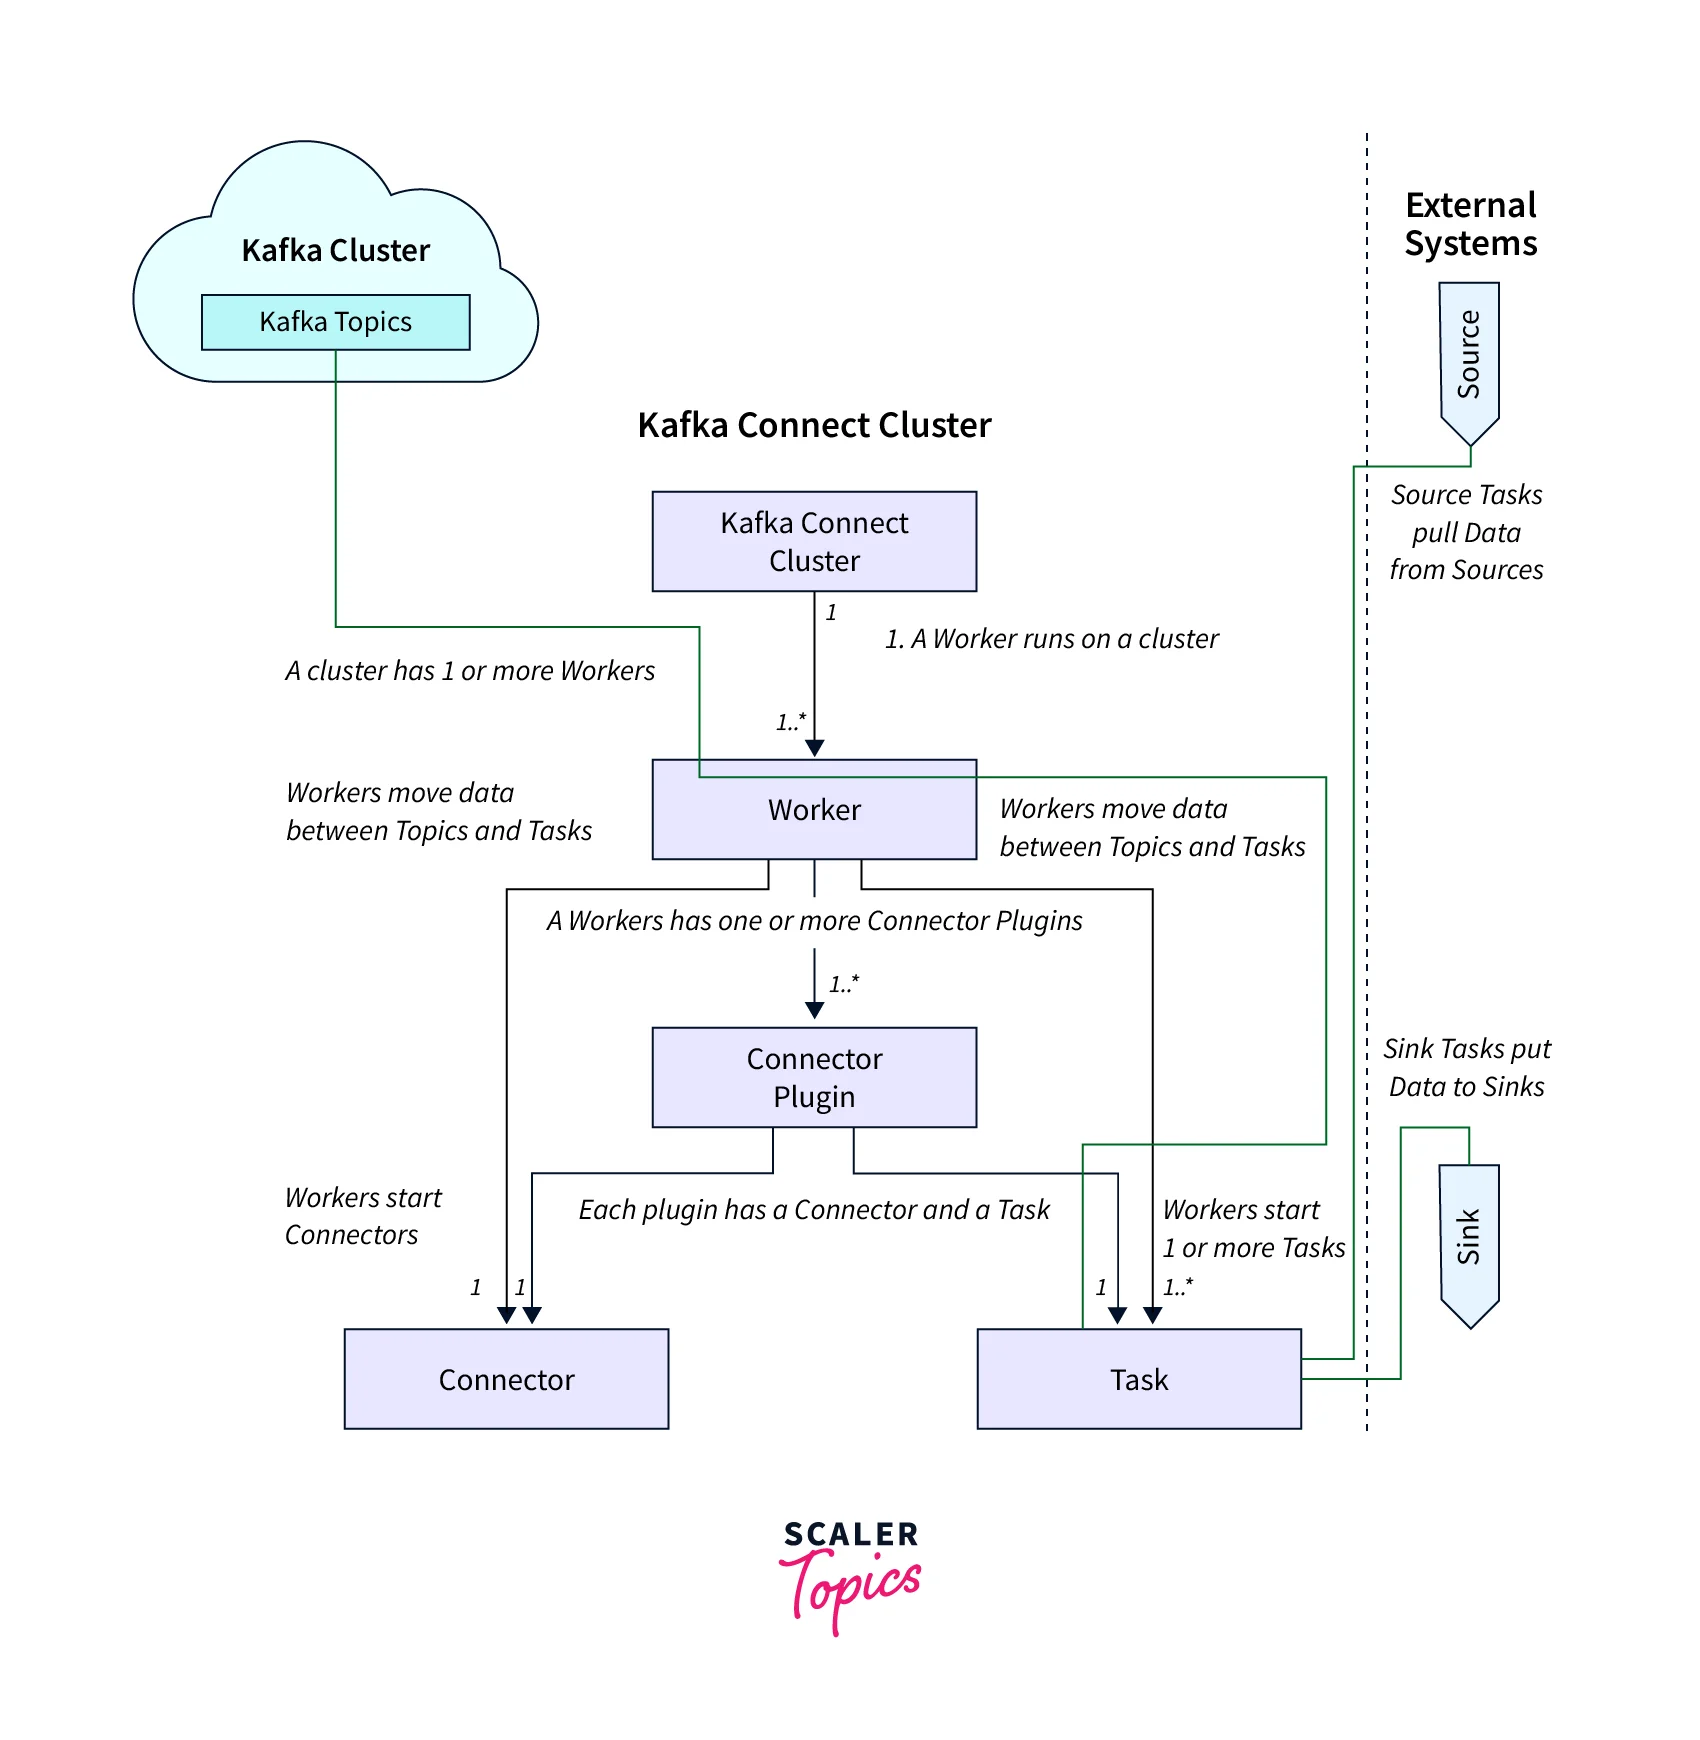
Name your diagram files with dates and version numbers. Something like kafka-connect-architecture-v3-2024-01.svg. Not because the content changes that often, but because when you revisit it six months later and someone asks when this version was last updated, you'll know without opening the file to check metadata. Simple habit that prevents a surprising amount of confusion in teams that move fast. Finally, share the diagram with the people who actually operate the connectors, not just the people who designed them. There's a difference between an architecture diagram meant for documentation and one meant for operational use. The latter needs phone numbers or Slack channels next to each component, runbook links, and alerts that correspond to each connector. I add a small legend in the corner of every operational diagram listing the on-call rotation for the data platform team and the link to the monitoring dashboard. Takes thirty seconds to add and cuts mean time to detection by roughly half during incidents because nobody wastes time searching for the right Grafana URL.