Getting Your Head Around Kazakhstan's Language Situation
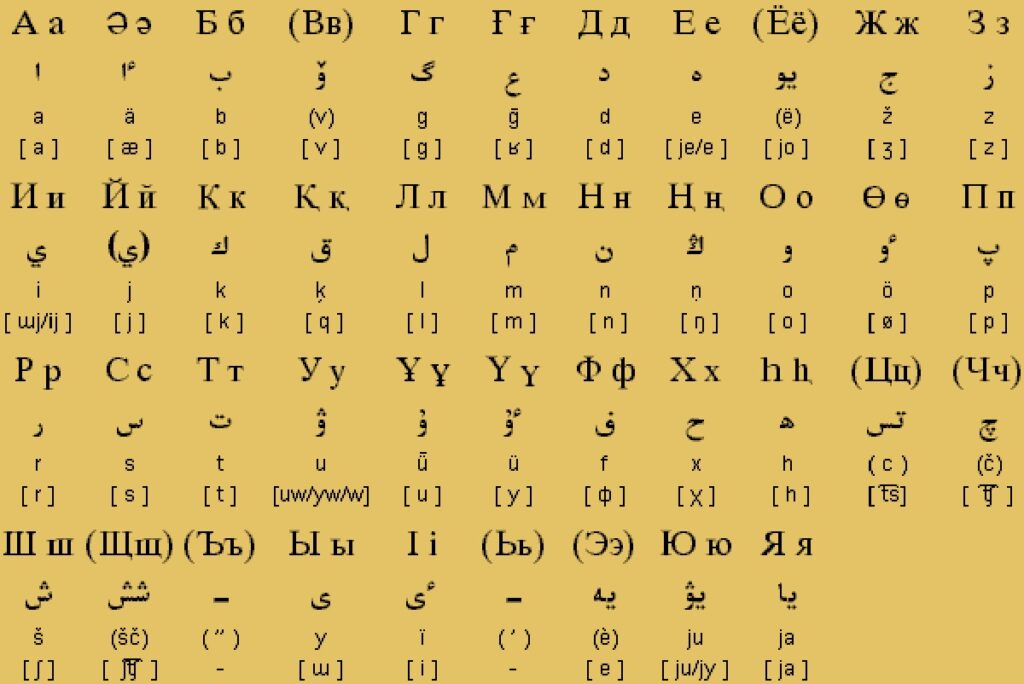
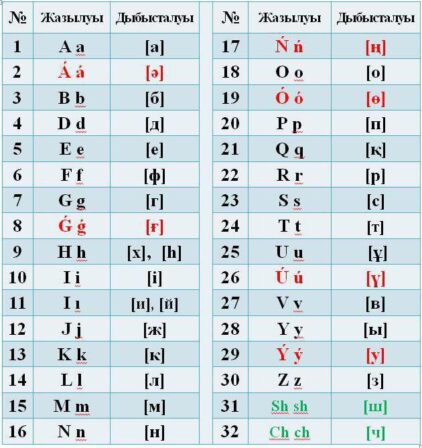
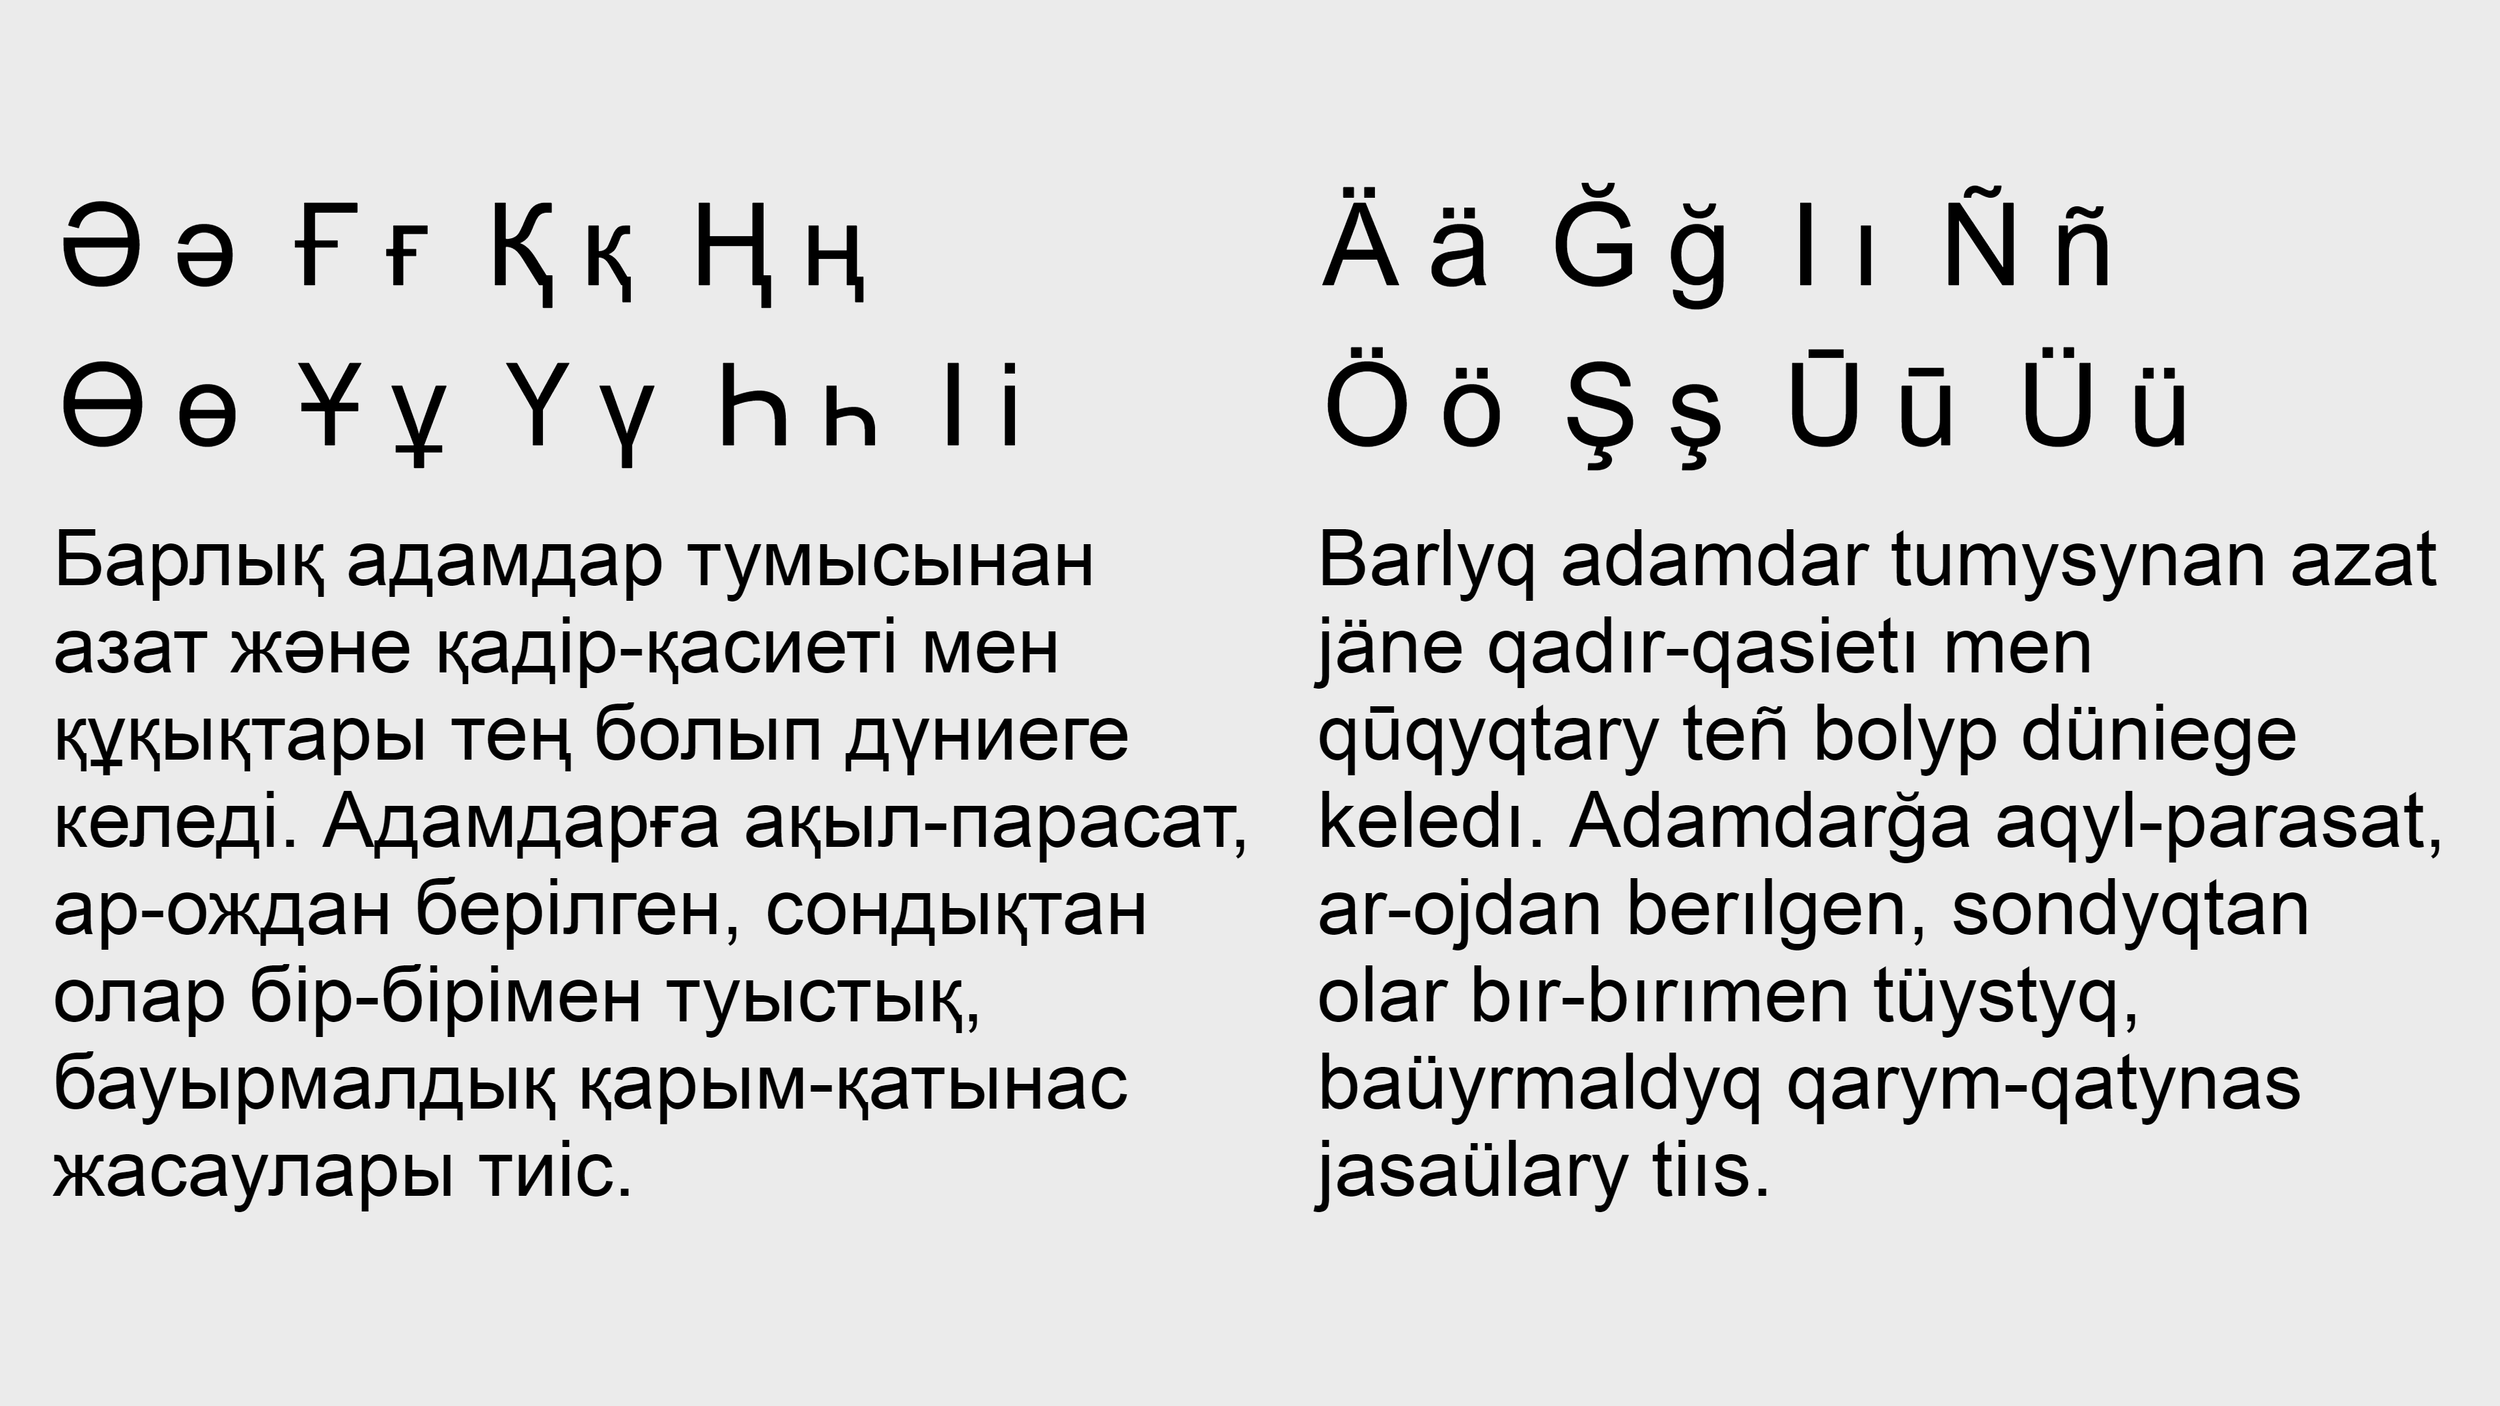
Kazakhstan has two official languages at the legal level: Kazakh and Russian. Kazakh carries state language status, which means government institutions are supposed to operate in it primarily. Russian is designated as officially used, so you'll see it everywhere in practice. When people talk about Kazakhstan official languages Kazakh usually comes up first because of the push toward revitalization, but ignoring Russian gets you nowhere fast. If you're trying to work with Kazakh-language materials, the first thing you need to understand is that the script situation is actively changing. The government committed to transitioning from Cyrillic to a Latin-based alphabet, and the roadmap has gone through several revisions. Right now, you will encounter texts in Cyrillic, Latin, and sometimes a mix of both depending on the source. Government decrees still publish in Cyrillic even though newer signage and some digital platforms are switching. If you're building something that needs to handle both, don't assume one script will cover it. I spent three weeks cleaning up a dataset where municipal documents alternated between scripts depending on which department generated them. The workaround was building a normalization layer that mapped character variants rather than trying to force everything into one alphabet. The linguistic reality is that Kazakh is a Kipchak Turkic language, related more closely to Kyrgyz and Tatar than to Turkish. That matters if you're working on translation or NLP tools. Machine translation models trained on Turkish data will underperform significantly on Kazakh. I learned this the hard way when a client assumed a Turkish-Kazakh pair would work decently out of the box. It didn't. The morphology is agglutinative in both, but the vowel harmony patterns and core vocabulary diverge enough that you need Kazakh-specific training data. You can get decent results with a multilingual model fine-tuned on Kazakh corpora, but off-the-shelf solutions will leave you chasing accuracy.
What Actually Exists Today
There isn't a single authoritative corpus or unified resource that covers everything. You'll piece together what you need from a few sources. The National Corpus of the Kazakh Language exists but is small compared to what you'd need for production work. Some university departments have their own annotated datasets. Open-source efforts on Hugging Face and GitHub have been growing, mostly around NMT and tokenizers. For Russian-Kazakh parallel text, you will find more in government domains because of the bilingual legislation requirements, but civil society and technical documentation skew heavily Russian. The digitization effort is real but uneven. Older government records, court documents, and academic publications are still primarily in print or scanned PDFs. The transition to born-digital Kazakh is happening, particularly in tech-forward cities like Almaty and Astana, but rural administrative centers move slower. If you're collecting data from government portals, expect the language mix to vary by region and by institution type.
Common Pitfalls
One thing beginners consistently mess up is treating Kazakh and Russian as interchangeable in any context. They are not. Legal documents, court proceedings, and formal government correspondence may be published in both, but the Kazakh version is the one that carries state authority. The Russian version exists for accessibility. If you are doing compliance or legal research, relying on the Russian text alone is risky because terminology shifts slightly between versions, and the Kazakh terms map to concepts that don't have clean Russian equivalents. Another pitfall is assuming the Latin transition means Cyrillic is going away soon. It isn't. The timeline has shifted multiple times, and even when the switch happens, you will be dealing with Cyrillic for years because of legacy content, older speakers who never learned the Latin forms, and the cost of replacing everything from street signs to software interfaces. Build for both.
Get the Full Details
Working With Real Data
If you need to process Kazakh text, start by deciding your script target. If your audience or system expects Cyrillic, you can normalize Latin input to Cyrillic fairly straightforwardly since the mapping is mostly one-to-one. The reverse is harder because some Latin characters represent sounds that don't have exact Cyrillic counterparts. Vowel harmony means your stemming or morphological analysis needs to account for front versus back vowels, and Kazakh has vowel length distinctions that some transcription systems drop. I once tried to build a search feature that indexed product names in Kazakh and got terrible recall because the tokenizer stripped vowel length markers that were actually meaningful for distinguishing similar-looking words. For speech recognition, Kazakh is under-resourced compared to Russian. Acoustic models trained on Russian will produce garbage when fed Kazakh audio. If you have budget for it, collect your own data in the relevant domains. If you don't, look for open speech datasets from Kazakh universities or international organizations working there. The quality will vary, but it beats starting from scratch with no reference data.
When This Doesn't Work
There are situations where investing in Kazakh-language infrastructure isn't worth it. If your user base is small and already comfortable operating in Russian, the return on building full Kazakh support may not justify the cost. Many businesses in Kazakhstan operate bilingually without issue, and the Russian-language ecosystem is mature. The question is whether your specific use case requires Kazakh specifically or if bilingual coverage is sufficient. Also, if you're dealing with dialectal variation across regions, the standard literary Kazakh used in media and government doesn't capture all spoken varieties, and that gap shows up in ASR and NLP outputs. The bottom line is that working with Kazakh requires planning for both scripts, accepting that tools are less polished than for major European languages, and not assuming similarity to Turkish solves anything. The legal framework favors Kazakh, the practical reality runs on Russian, and the transition is ongoing enough that rigid assumptions will cost you.