Understanding Kb Mb And Why People Keep Confusing Them
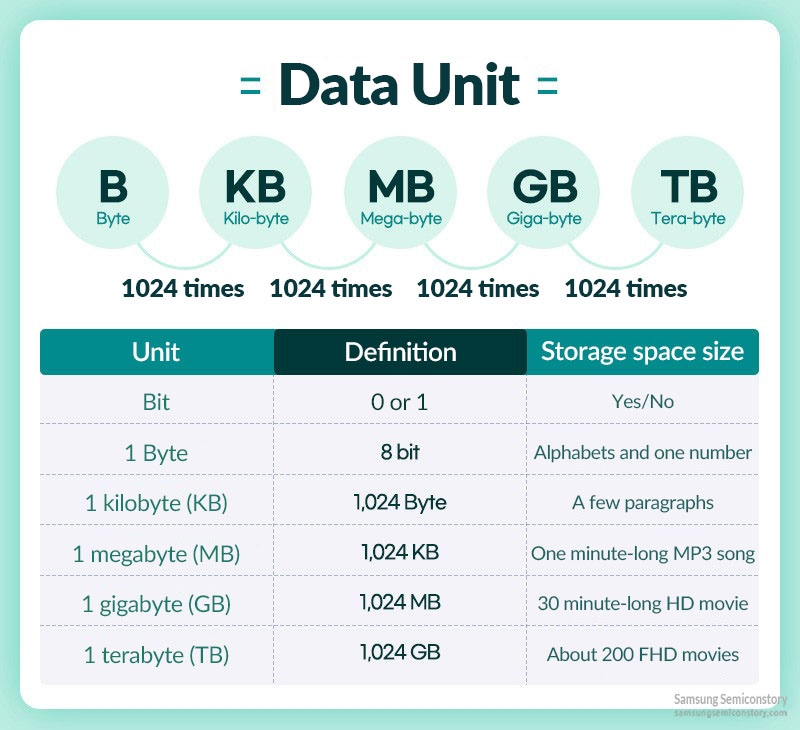
Most people see these units on a file size, a download bar, or a data plan and assume they all mean roughly the same thing. They don't. The confusion is worse than it looks, and it's why I once uploaded a 500 MB video to a server that refused it saying the file was too large, only to realize hours later I had configured the upload limit in kilobytes instead of megabytes. The server was rejecting a 500 KB file, not a 500 MB one. Total waste of an afternoon. The core problem is that there are two competing naming systems running side by side, and nobody bothered to make them easier to distinguish. Base 10 (SI/Decimal): This is the system used by hard drive manufacturers, ISPs, and most consumer-facing specs. One kilobit (kb) equals 1,000 bits. One kilobyte (KB) equals 1,000 bytes. One megabit (Mb) equals 1,000 kilobits. One megabyte (MB) equals 1,000 kilobytes. The pattern continues: gigabyte is 1,000 megabytes, terabyte is 1,000 gigabytes, and so on.
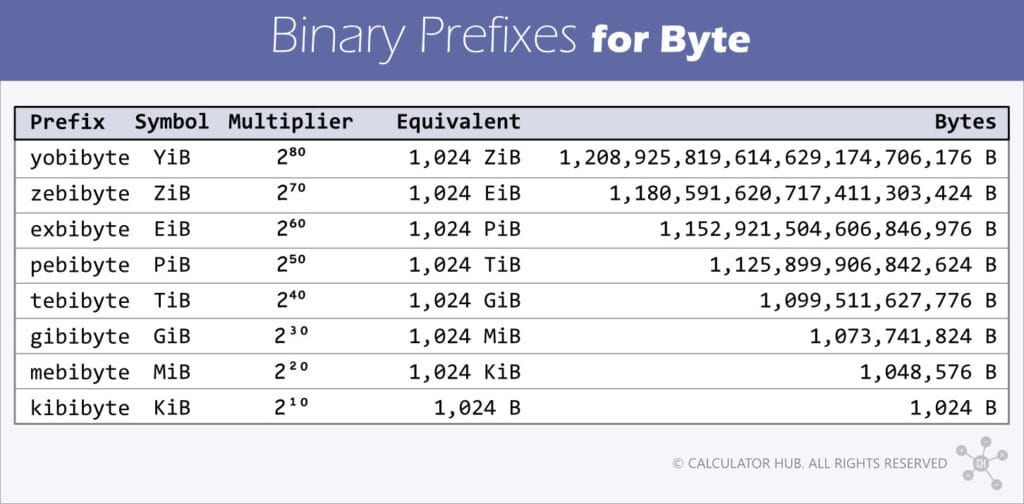
Base 2 (Binary): This is what operating systems traditionally use for internal storage calculations. One kibibit (Kib) is 1,024 bits. One kibibyte (KiB) is 1,024 bytes. One mebibit (Mib) is 1,024 kibibits. One mebibyte (MiB) is 1,024 kibibytes. The "kibi" and "mebi" prefixes were introduced by the IEC in 1998 to fix the ambiguity, but adoption has been glacial. Here is where it gets annoying in practice. A file that shows as 1,000 MB on your hard drive's marketing spec sheet will show up in Windows Explorer as approximately 953 MiB because Windows divides by 1,024 repeatedly. That gap between 1,000 and 953 compounds at every tier. By the time you reach terabytes, a 1 TB drive reports as roughly 931 GiB in the OS. It is not a bug. It is just the math. Network speeds add another layer. Internet service providers advertise speeds in megabits per second (Mbps), lowercase b. Your download manager shows progress in megabytes per second (MB/s), uppercase B. The conversion is straightforward but easy to miss: divide the Mbps number by 8 to get your expected MB/s. A 100 Mbps connection tops out around 12.5 MB/s. If you see anything close to 100 MB/s on that connection, you are either on a local network or someone is mislabeling the speed.
I ran into a specific edge case once while converting CSV exports between a legacy Python script and a newer Node.js pipeline. The Python side was writing file sizes using decimal kilobytes, and the Node side was reading them as binary kibibytes. A batch of 10,000 files that should have been exactly 1 GB total came out to about 976 MB on the receiving end. The discrepancy was small enough that nobody noticed until I started seeing occasional truncation errors in the destination system. The fix was explicit: I added a `--binary-units` flag to the converter script and used the `decimal` module in Python to force base-10 arithmetic, then explicitly divided by 1024 on the Node side before writing. Took about twenty minutes to implement and saved me from spending weeks chasing phantom data corruption. Another thing people consistently get wrong is the relationship between bandwidth and file size when estimating transfer times. You cannot directly compare a file size in bytes to a connection speed in bits. You have to convert one or the other first. Take a 2 GB file and a 50 Mbps download. Convert 2 GB to megabits: 2 times 8 equals 16 megabits. Then divide 16 by 50. The result is 0.32 seconds, which is obviously wrong because I forgot that 2 GB is 2,000 megabytes, not 2 megabytes. Correct calculation: 2 GB = 2,000 MB = 16,000 Mb. 16,000 divided by 50 equals 320 seconds, or roughly 5 minutes and 20 seconds under ideal conditions. Real world, with overhead and throttling, probably closer to 7 minutes. The error I made at first is the kind of thing that happens when you stop thinking about the units and just plug numbers into a calculator. The practical takeaway is that you need to know which system your tool is using. Most command-line tools on Linux and macOS default to binary when displaying file sizes, which is why `ls -lh` shows 1.0K for a 1,024-byte file. Some tools like `du` have a `--block-size` flag that lets you switch between decimal and binary output. Windows File Explorer sticks to binary even though it labels the units as KB and MB rather than KiB and MiB, which is another source of confusion. If you are writing scripts that handle file sizes across platforms, always explicitly declare which convention you are using. Magic numbers like 1024 and 1000 inside code are a fast track to subtle bugs that surface only under load.
Get the Full Details
Storage vendors will continue to use base 10 because it makes their drives look bigger. Operating systems will continue to use base 2 because it is baked into decades of code. Network providers will continue to advertise in bits because it makes their speeds look larger. None of this is going to change. The best approach is to be aware of the mismatch and double-check your conversions whenever the numbers feel off.