Working with the Korn Ferry Leadership Architect assessments
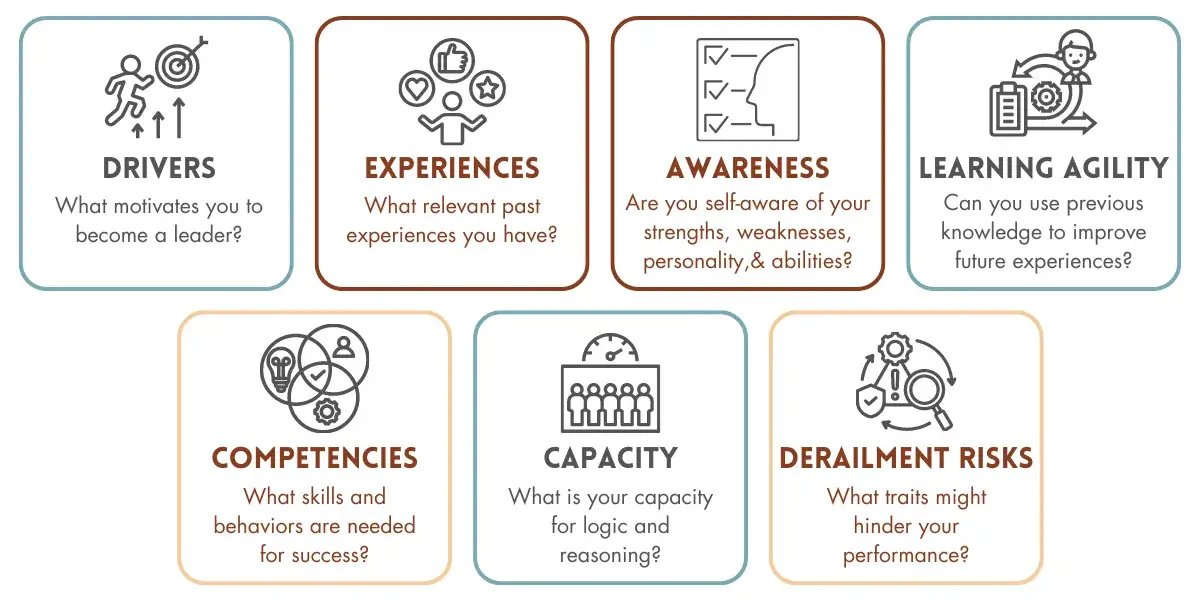
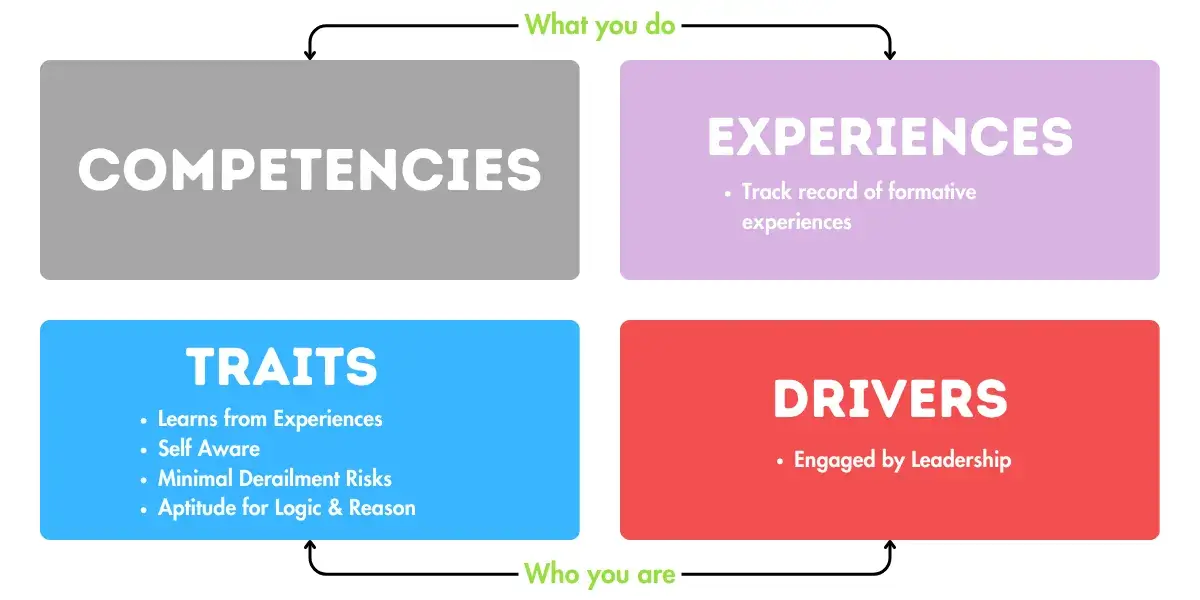
I've been administering and reviewing Korn Ferry competency-style assessments for organizations for a while now. They come in a few flavors depending on what the client ordered—Leadership Architect, Professional Profile, or Development Center—and the format changes slightly, but the core mechanics stay the same. You get a browser-based instrument with situational judgment items, rating-scale statements, and sometimes a short in-tray exercise. The whole thing takes roughly 45 to 90 minutes depending on the suite. It maps responses against the Leadership Architecture framework. That's their taxonomy of ~168 behaviors and competencies broken into drives, capabilities, and personal characteristics. When a company commissions the assessment, they select a targeted subset relevant to the role. A senior engineering manager evaluation will weight problem-solving and technical influence differently from a sales leadership profile. The output score report shows where a candidate clusters on each dimension and how that cluster compares to a reference group—usually a peer norm or a best-practice norm the client chooses. The scoring isn't a simple percentage. It's a norm-referenced model. Your raw responses get converted into standard score bands, then the algorithm flags consistencies and inconsistencies across items. That's important because the built-in validity scales aren't theatrical—they actually catch patterned responding without being obvious about it.
I've seen companies treat the report like a definitive truth. It isn't. It's one structured data point. The predictive validity numbers published in the technical manuals hover around 0.30 to 0.45 for job performance depending on the role and norm used. That's respectable for a single instrument, but it means almost everything else matters too—work samples, structured interviews, reference checks. The assessment will move the needle, but it won't carry the decision alone.
How to go through the assessment process as a candidate
If your employer is sending you the link, check the email for the intended role and the norm group. Sometimes they'll tell you directly. Sometimes they won't. You can usually infer it from the job description. A director-level role in a matrixed organization will expect different response patterns than an individual contributor role in the same company. The same person could score in two very different zones depending on which benchmark they're compared against. Work through the items in a quiet block of time. No second-guessing each choice too long. The situational judgment questions present a scenario and ask you to rank or select the best and worst response. The scoring keys off what the norm group—people in similar roles who performed well—tend to choose. So the strategy isn't to answer how you wish you'd act. It's to answer how someone in that role at that level would realistically act, given the organizational context implied in the question. Here's a practical problem I ran into with one candidate last year. She was extremely conscientious, so every situational item had two answers that both looked reasonable to her. She spent extra time on maybe a third of the items, overthinking the trade-offs. The assessment engine registered inconsistency across the consistency checks because her earlier responses set one pattern and her deliberated responses drifted into a different pattern. She got flagged not for faking good, but for pacing disruption. I've seen this enough that I now tell candidates to lock in an answer within ten to fifteen seconds and move on unless the scenario genuinely contains new information they haven't seen before.
Get the Full Details
The rating-scale portion works differently. You'll see statements like "I analyze data before making a decision" and rate how accurately it describes you. Some people read these literally and pick the middle option too often. The scale distribution will look flat, which the validity checks interpret as lack of self-awareness or low discriminative responding. Pick sides when the statement is clearly true or clearly false for you. A balanced profile isn't the goal here. An accurate one is.
Scoring interpretation and common misreads
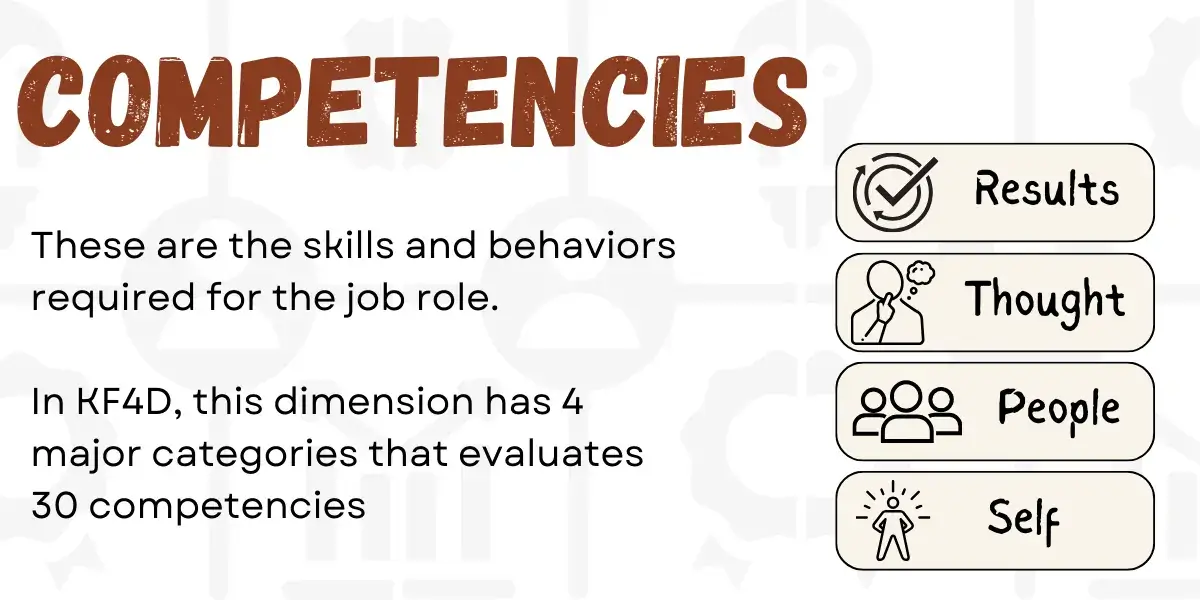
The reports use banding—usually something like low, average, high, and very high—rather than exact percentiles. A "high" band doesn't mean the top ten percent. It means above the reference group median by a defined bandwidth. The exact bandwidth differs by module and norm group, so don't try to convert bands to percentiles yourself. It'll be wrong. One counter-intuitive thing about these reports is that the highest-scoring candidate isn't always the best hire. The Leadership Architecture includes dimensions where very high scores can indicate overextension. For example, a very high achievement drive combined with a low sociability score often shows up in people who burn out or alienate their teams. I had a client pass a candidate who scored in the top band across nearly every capability dimension, which initially looked perfect. The behavioral descriptors behind the scores told a different story. He was highly assertive and highly decisive with low collaboration and low flexibility. He was going to ship fast and create friction everywhere. We restructured the interview to stress-test team dynamics, and he didn't clear it. The assessment didn't fail. It was just underweighted correctly in the final decision. Another misread I see constantly is treating a single dimension as destiny. People latch onto one label—"low strategic thinking"—and decide the candidate is unfit for a leadership role. But the competencies interact. Someone with modest strategic thinking but very high coaching and development might be a stronger people-leader than someone with high strategic thinking and low interpersonal effectiveness. The reports show interactions if you read the behavioral descriptions. Don't skip those.
What to do if you're the hiring manager using the tool
Define the role profile before the candidates take it. Pick the competencies that matter, set the band expectations, and decide which dimension gaps are acceptable. If you send candidates through blind and then realize you never specified whether problem-solving or influencing mattered more, you'll waste the data. The platform lets you build a role-specific blueprint with weighted competencies. Use it. It usually takes me about twenty minutes to set up a clean blueprint for a standard leadership role. Combine the results with at least one work sample. The Korn Ferry instrument is good at predicting cultural fit and capability alignment, but it's weaker on actual skill demonstration. A coding test, a writing sample, a presentation exercise—something real—will surface things the assessment can't. The assessment tells you what someone is likely to do. The work sample tells you what they actually can do.
Getting Access to the Korn Ferry Competency Assessment for Practice
There isn't a legitimate free download of the actual instrument. The full assessment is proprietary and distributed only through licensed corporate accounts. Anything claiming to sell or share the real questions is either a scam or violating licensing agreements. What does exist are published practice samples, third-party simulation tools that mirror the format, and the official candidate guide that Korn Ferry provides to organizations to distribute to their applicants. If you're preparing on your own time, the most useful approach is working through the format, not memorizing answers. Do a few public situational judgment practice sets so you understand the ranking mechanic. Read the Leadership Architecture dimension descriptions so you know what the traits actually measure. Review common corporate decision-making frameworks like prioritization matrices and stakeholder analysis, since the scenarios draw from those universes. That preparation usually takes two to three hours total and addresses the actual skill the assessment probes. A final note on the tool's limitations. It struggles with role ambiguity and cross-cultural comparison. If the norm group doesn't closely match your candidate pool, the bands become less meaningful. A candidate from a highly direct communication culture might score lower on collaboration in a norm built around indirect communication environments, even though they're effective in their own context. I once reviewed a report where a strong international candidate appeared to have low persuasiveness simply because the reference group was calibrated to a regional communication style. We adjusted by switching the norm group and re-scoring, which flipped several bands. Always verify the norm match before acting on the report.
The assessment is a solid component of a hiring process when used correctly. It gives you structured behavioral data fast, surfaces risk flags through consistency checks, and maps clearly to organizational language. It's not a crystal ball. It doesn't replace judgment. Used alongside interviews and work samples, it usually cuts the screening time for leadership roles from a full week of unstructured evaluations down to about two days of focused review.