Measuring the Right Things in Tech Development
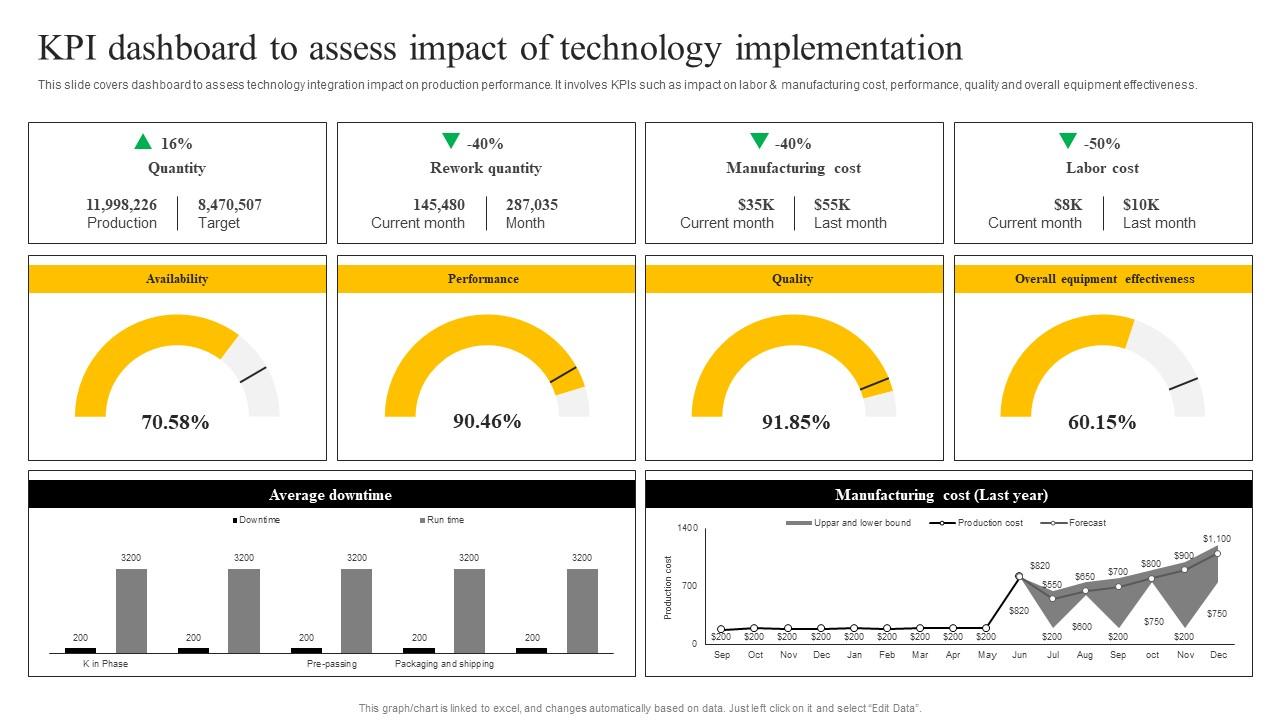
Kpi For Technology Development is one of those topics that gets overcomplicated because people treat it like a dashboard exercise instead of a signal-finding problem. You've probably seen teams implement tracking systems that generate hundreds of metrics and then nobody looks at them after month two. I've been there. Here's what actually works when you strip away the analytics theater. Start with deployment frequency and lead time for changes. These two alone tell you more about your team's capability than any custom scoring system ever could. A SaaS company I consulted for had 47 different KPIs across their dashboards. The engineering leads couldn't tell you their median lead time without running a SQL query. We cut it down to three numbers and everything else became background noise. The DORA metrics framework is worth knowing because it gives you a baseline, but using it blindly is where most teams go wrong. Lead time for changes measures how long it takes from a commit to production. Deployment frequency tells you whether your team ships incrementally or in massive monthly batches. Change failure rate tracks how often deployments cause incidents. Mean time to restore measures recovery speed. These four together give you a picture. Five hundred together just give you a spreadsheet problem.
I ran into a specific issue last year with a platform team that was hitting all their KPI targets but the product was clearly regressing. Their lead time dropped to under an hour and deployment frequency hit thirty times per day. The catch was that they'd redefined "deployment" to mean deployment to staging, not production. Their actual production deployment process was gated behind a manual approval step that added three to four days. The metric looked great on paper and completely hid the bottleneck. We fixed it by tying the KPI to actual production deployments only and requiring that the definition include user-facing availability, not just code reaching a server.
What Beginners Miss About Tracking
One thing nobody tells you is that some of your best KPI signals are negative ones. Counting things going right is easy and flattering. Tracking things that almost happened or quietly failed at the edge is where the useful data lives. An elderly care software project I worked on tracked a metric called "scope drift incidents." That's whenever requirements changed mid-sprint without a formal change request. It seemed petty at first. After three months, we realized scope drift correlated directly with bug rates climbing 40 percent in the following sprint. Fixing the intake process for scope changes reduced that bug rate by more than half. Another counter-intuitive point: cycle time and lead time are not the same thing, and mixing them up ruins your analysis. Cycle time is the actual work duration from when someone starts on a task to when it's done. Lead time includes the waiting time before work begins. If your team has good cycle time but terrible lead time, the problem isn't development velocity. It's how work gets prioritized and handed off. We saw this on an identity verification system project where developers were finishing work in two days but the average lead time was eleven days because tickets sat in a "review" queue that nobody cleared regularly. No amount of optimizing code output would fix that. It needed a process change in ticket triage.
Get the Full Details
Building a System That Doesn't Fall Apart
Set up automated collection from day one. Manual reporting gets dropped the moment anyone finds it inconvenient, and convenience breaks usually happen within the first three weeks. Connect your CI pipeline to feed deployment data, hook your issue tracker to pull cycle times, and let an incident management tool capture failure and recovery data. A properly configured setup takes about twenty minutes to build and then runs itself. The alternative is someone spending two hours every Friday afternoon compiling data that's already wrong by the time it reaches management. Keep the number of active KPIs under five per team. More than that and people start gaming the ones they don't care about while pretending to track the ones they do. I recommend a tiered approach where each team maintains their own three to five core metrics and an aggregate dashboard pulls one summary number from each team for executive visibility. That summary should be a weighted composite, not an average, because a team with poor change failure rate matters more than a team with slow but stable deployments. There's a real limitation to this approach that you need to acknowledge upfront. KPIs are lagging indicators. They tell you what happened, not what's about to happen. By the time your mean time to restore spikes, the damage is already done. Pair your KPI tracking with leading indicators like test coverage trends, code review turnaround time, and build failure rates. These shift earlier and give you a chance to intervene before the lagging numbers move against you. Test coverage alone won't predict quality, but a drop of more than five percent week over week usually means something shifted in the testing culture before the metrics catch up.
The Practical Breakdown
Here's what the core setup looks like in practice. Track lead time for changes as a median, not an average, because outliers skew averages badly. Three to five days is a solid target for most web applications. Deployment frequency should be daily or better for services that change regularly. Change failure rate below fifteen percent keeps you in a healthy zone. Mean time to restore under one hour for critical systems and four hours for standard services are reasonable starting points. For non-functional tracking, monitor resource utilization patterns. A database migration I oversaw had perfectly healthy deployment metrics but the team was burning through compute credits at three times the projected rate because nobody connected the KPI system to infrastructure costs. We added a cost-per-deployment metric that flagged when optimizations during refactoring were actually increasing cloud spend. That single addition saved the project roughly eighteen thousand dollars per quarter. Don't chase vanity metrics like lines of code written or tickets closed. Those sound productive and measure nothing useful. Lines of code correlate poorly with quality and ticket count ignores complexity entirely. A team closing two hundred simple tickets in a sprint is doing something very different from a team closing forty tickets involving distributed system migrations.
When KPI Systems Fail Completely
Be honest about where this breaks down. KPI systems don't work well for exploratory research projects or early-stage prototyping where the path forward genuinely isn't known. If your team is investigating whether a new technology stack can solve a problem that hasn't been clearly defined yet, trying to measure lead time for changes is like timing a person who's walking through a dark room looking for a door. The metrics you need there are different, and calling them KPIs just confuses everyone. Use learning milestones instead, and be explicit about switching measurement frameworks when the project moves from exploration to execution. A smaller but more common failure mode is when management treats KPIs as performance targets rather than diagnostic tools. Once a team knows their lead time affects their bonus, they'll find ways to game it. Shortening ticket sizes to make lead time look better without actually improving throughput is the classic example. The moment you attach rewards to specific numbers, the numbers become unreliable. Use KPIs for system diagnosis, not individual evaluation. If you need a starting toolkit, Datadog or New Relic can ingest deployment data from GitHub Actions or Jenkins, PagerDuty feeds incident recovery times, and you can build a simple aggregation dashboard in Grafana or even Google Sheets with API pulls if you want to keep it lightweight. The specific tools matter less than establishing a consistent definition for each metric and sticking to it. Changing what "lead time" means every quarter makes trend analysis impossible and just creates confusion.
The point isn't to collect data. It's to collect the right signals so you can make decisions faster than you would without them. Everything else is administrative overhead dressed up as strategy.