Checking Your Deployment Rollout History in Kubernetes
Most people learn about rollout history the hard way. Their app breaks after an update and they realize they have no idea what actually changed between versions. Here is the straightforward way to look it up without going through your entire Git blame log.Kubectl Get History Of Deployment
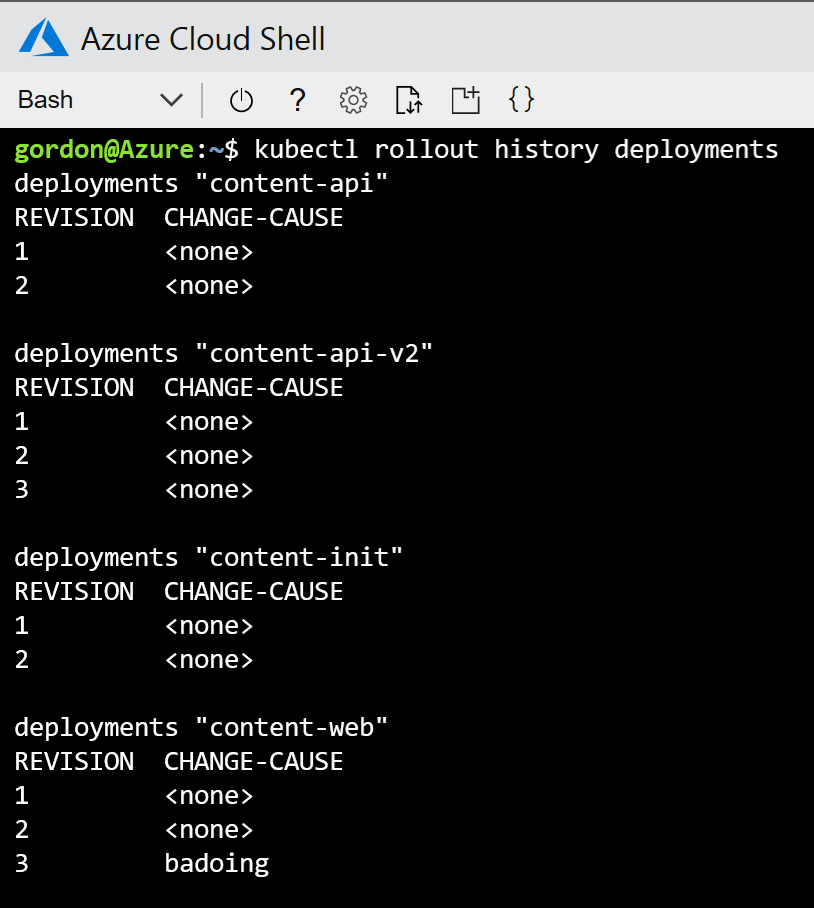
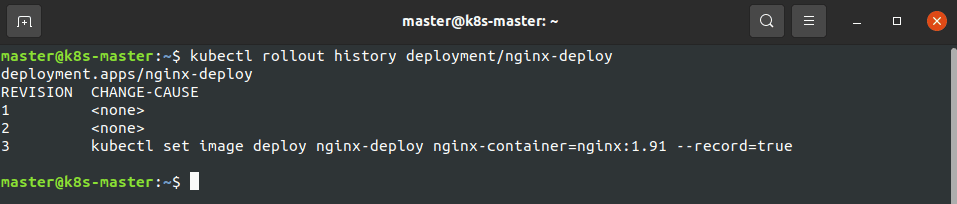
The basic command is simple enough that you probably already know it, but I will write it out anyway because people still type it wrong when they are stressed at 2 AM. You run: kubectl rollout history deployment/<deployment-name> That gives you a numbered list of revisions. Each revision corresponds to a config change that triggered a rollout. The output looks something like this:
revision 1: image nginx:1.19
revision 2: image nginx:1.21
revision 3: image nginx:1.23 By default you only see deployments in the current namespace. If your deployment lives somewhere else, add -n <namespace> to the command. I have lost count of the times I ran the command and then spent ten minutes wondering why nothing showed up before remembering the pod was in the payments namespace, not default. If you want to see what exactly changed in a specific revision, append --revision <number> to the command. Like this:
kubectl rollout history deployment/my-app --revision 2 This dumps the full spec for that revision including resource limits, environment variables, and image tags. It is useful when you need to reconstruct what went wrong without digging through a CI pipeline log from three weeks ago. There is one thing most guides leave out. The rollout history is not stored in etcd the way you might expect. It lives in an annotation on the ReplicaSet objects themselves. When you scale a deployment or change any field in the spec that triggers a rollout, Kubernetes creates a new ReplicaSet and writes the previous spec into the history annotation on that new ReplicaSet. That means the history is only as complete as the ReplicaSets that still exist on the cluster.
Get the Full Details
Here is where things get annoying. If someone ran kubectl delete replicasets to free up resources, or if you have a retention policy that prunes old ReplicaSets, your history disappears with them. I hit this exact problem last year on a staging cluster where a cleanup job was deleting ReplicaSets older than seven days. We needed to roll back to revision 4 but the annotation data was gone. There was no way to recover it from kubectl alone. We ended up pulling the deployment manifest from our Git repo at that commit SHA and comparing it manually to figure out what we had changed. It took about twenty minutes that I would happily have saved if I had known about the annotation thing sooner. Another detail that trips people up. Running kubectl set image deployment/my-app nginx=nginx:1.23 does not always create a new revision. If the image tag is the same as the current one, Kubernetes treats it as a no-op and skips the revision bump. I learned this when I was trying to trace why revision numbers jumped from 3 to 7 overnight during a canary rollout script that was accidentally reapplying the same image multiple times. If you want to see how many ReplicaSets are being retained for history, check the spec.revisionHistoryLimit field on your deployment. The default is 10. Set it higher if you need deeper history, lower if you are worried about cluster resource usage from old ReplicaSet objects piling up. I keep mine at 20 on production clusters. It is a small cost and it saves a panic when you need to go back further than ten revisions.
To actually roll back to a previous revision, you use: kubectl rollout undo deployment/<deployment-name> --to-revision=<number> This creates a new ReplicaSet based on the spec from that revision and starts a fresh rollout. The old current revision becomes just another entry in the history. There is no permanent deletion unless you explicitly clean it up later.
One more thing. If you are managing deployments across many namespaces or clusters, writing these commands by hand gets tedious fast. I started using a small shell script that loops over deployments and prints the last three revisions for each one. Not glamorous but it cuts down on context switching when you are doing incident response across a dozen services. The commands work the same whether you are on EKS, GKE, AKS, or a bare metal cluster with kubeadm. The behavior is consistent because it is part of the upstream Kubernetes API. You will find the same output format everywhere. I also want to mention that kubectl rollout status deployment/<name> is worth knowing about even though it is not strictly about history. It tells you whether the most recent rollout completed successfully or if it is still progressing. I usually run history first to identify which revision broke things, then status to watch the rollback in real time.

That is really all there is to it. The feature is not fancy but it does what it needs to do as long as you keep those ReplicaSets around.


