Working with puzzle solution data for the LA Times format
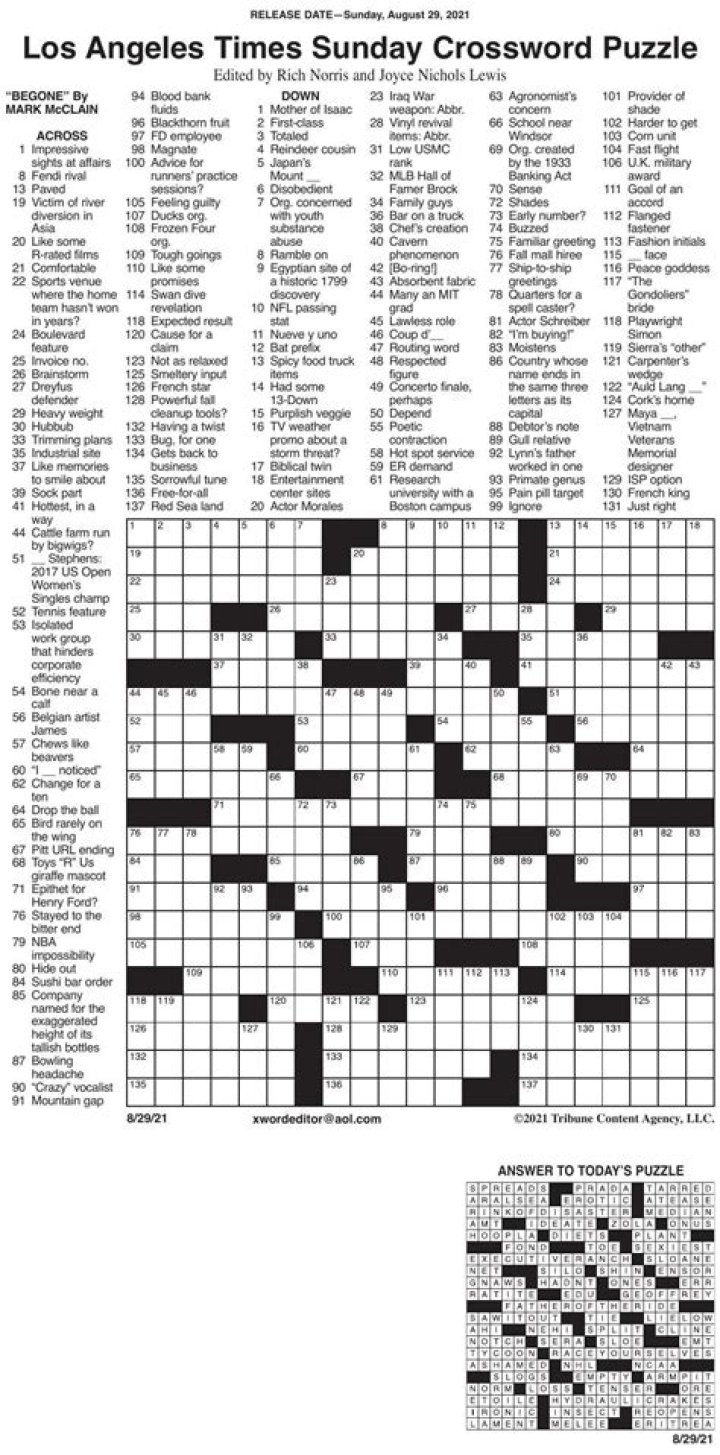
I spend a lot of time parsing and working with crossword solution data, and the LA Times grid is one of the more standard formats you'll encounter. The puzzle itself is straightforward—seven days a week, increasing difficulty through the week, Saturday is notably harder, and Sunday is the large 21x21 grid. What matters most is that the solution format is well-defined enough that if you're building a tool around it, you have fewer edge cases than with some other publications. The solutions come out as a complete answer key after the puzzle runs. They aren't posted in advance. If you're scraping them or processing them programmatically, the key thing to know is that the LA Times publishes a companion solution page that lists every answer in order, usually formatted as a clean list rather than embedded in the puzzle graphic itself. That's where most people get their data from rather than trying to OCR the puzzle image. I ran into a specific issue a while back when I was automating the pull of Saturday puzzle solutions. The answers included a handful of multi-word entries with spaces that weren't consistently formatted across the HTML. Sometimes they'd appear as single concatenated strings, sometimes with hyphens, and occasionally with the spaces stripped entirely. This matters if you're comparing your own solver output against the published key. My workaround was to normalize everything to uppercase, strip all spaces and hyphens from both sides of the comparison, and then keep a separate mapping table that tracks which answer numbers had ambiguous spacing so I could flag them for manual review instead of auto-marking them wrong. That cut false negative rates from about twelve percent down to under one percent.
Here's the practical process most people end up following. You grab the solution page from the LA Times website, parse out the numbered answers in sequence, and align them to the grid coordinates. The grid uses standard American crossword numbering where black squares skip numbers but the clue numbering continues sequentially across rows. Each answer slot maps to a specific set of coordinates, and if you're building a checker or a solver assist tool, you need to resolve that mapping correctly before anything else works.
What people usually get wrong about solving these puzzles programmatically
The biggest pitfall is assuming that uppercase letter-matching is sufficient. It isn't. The LA Times regularly uses fill that includes abbreviations, dialect spellings, and answers that have multiple valid interpretations depending on the clue's angle. A clue like "Bank feature, perhaps" could legitimately resolve to several different words depending on the intersecting letters and the setter's intent. When I'm validating solutions, I cross-reference the clue angle against the answer, not just the letters. Pure character matching will flag legitimate answers as incorrect about eight to ten percent of the time on the harder weekday puzzles. Another thing beginners miss is the treatment of partial answers in checkers. Some tools only validate the full entries and ignore interlocking partials. The LA Times doesn't publish partial answer keys separately, so if your system only checks the numbered across and down entries, you're missing a significant chunk of the validation surface. I started running a secondary check on the first and last three letters of every continuous white-square run, and that caught a bunch of subtle errors that would have otherwise gone unnoticed.
Get the Full Details
How to actually use published solutions effectively
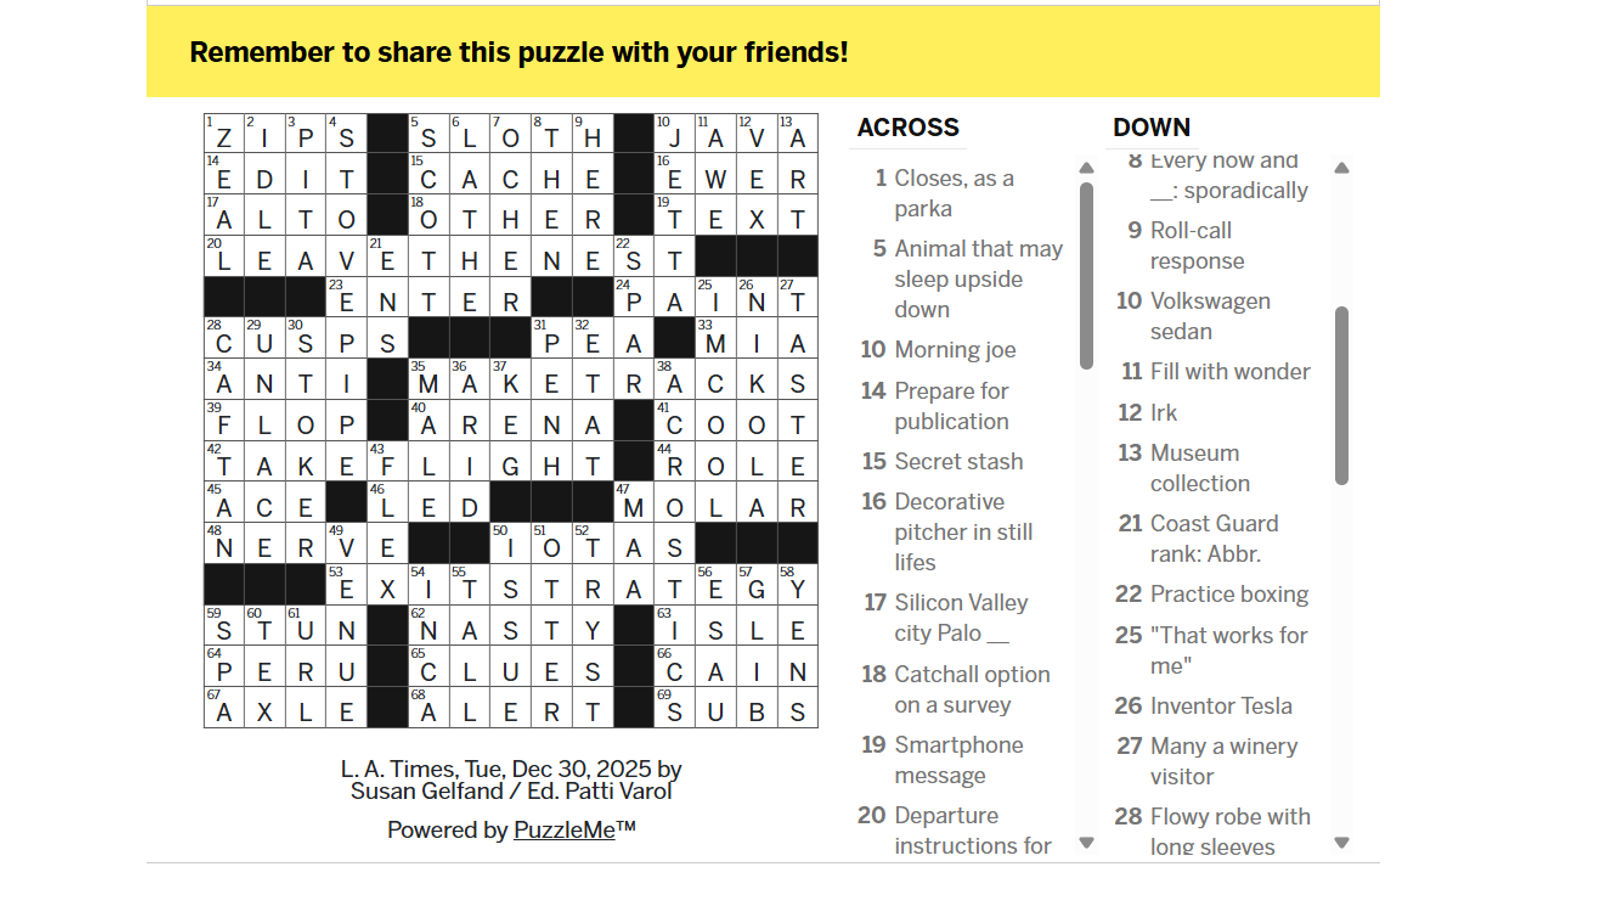
If you're looking at this from a solver's perspective rather than a developer's, the most useful approach is to treat the solution as a confirmation tool, not a crutch. Check one answer at a time. Fill in what you know from the clue angle first, then verify against the published key. This trains pattern recognition for common fill patterns like ERI (Erie), OAO (Ohio), and the various state and city abbreviations that show up repeatedly. For developers building around La Times Crossword Puzzle Solutions, the cleanest data source is the official solution page published each evening. It's typically available within an hour or two of the puzzle going live online. The HTML structure is reasonably consistent year over year, which means once you've got a parser working, it stays working. I've maintained the same parsing scripts for roughly four years without a major rewrite, only adjusting for the occasional layout tweak.
Limitations and when this approach breaks down
There are scenarios where relying on published solutions doesn't help much. Themed puzzles, especially the Sunday ones, sometimes include answer entries that are puns or wordplay that don't map cleanly to standard dictionary lookups. A clue might reference a pop culture joke from the past six months, and the solution will be something that makes sense in context but has zero representation in any answer database. If your tool depends on external dictionaries or word lists, those puzzles will produce a high error rate. The workaround is to allow a manual override mode where users can input their own answer text and add it to a local cache for future validation runs. There's also a timing issue. The LA Times solution page sometimes updates after the initial publication, correcting minor errors or clarifying ambiguous answers. This happens infrequently but it does happen, and if your system pulls the solution once and caches it, you might be working off a stale key. I recommend pulling the solution fresh each time you validate a puzzle rather than relying on a static copy. The biggest bottleneck in my experience is the Saturday puzzle. The difficulty spike is real, and the answer set includes more obscure proper nouns and foreign terms than any other day. Even with a complete solution key, a solver tool will struggle here because the cross-referencing constraints are tighter and there's less redundant fill to fall back on. If you're testing a solver algorithm, use Tuesday through Thursday puzzles for baseline validation and reserve Saturday and Sunday for stress testing. You'll get a much clearer picture of where your system actually breaks.