Getting Started With Dog Skeleton Annotations
Most people trying to build a labeled skeleton dataset for dogs come in thinking it is just like human pose estimation with fewer keypoints. That assumption burns through time fast. The anatomy is close enough to fool you at first, then you hit a frame where the leg orientation makes three joints look identical and you have to make a judgment call that will confuse your model later. I spent about six weeks on a project where I needed per-frame limb annotations for gait analysis. We started with a COCO-style 17-keypoint skeleton mapped onto dogs, which is the most common starting point. It works okay for standing or walking poses. The moment the dog runs, crouches, or overlaps a leg, the mapping collapses and you are left guessing which joint is which.
What The Labeled Skeleton Of A Dog Actually Looks Like
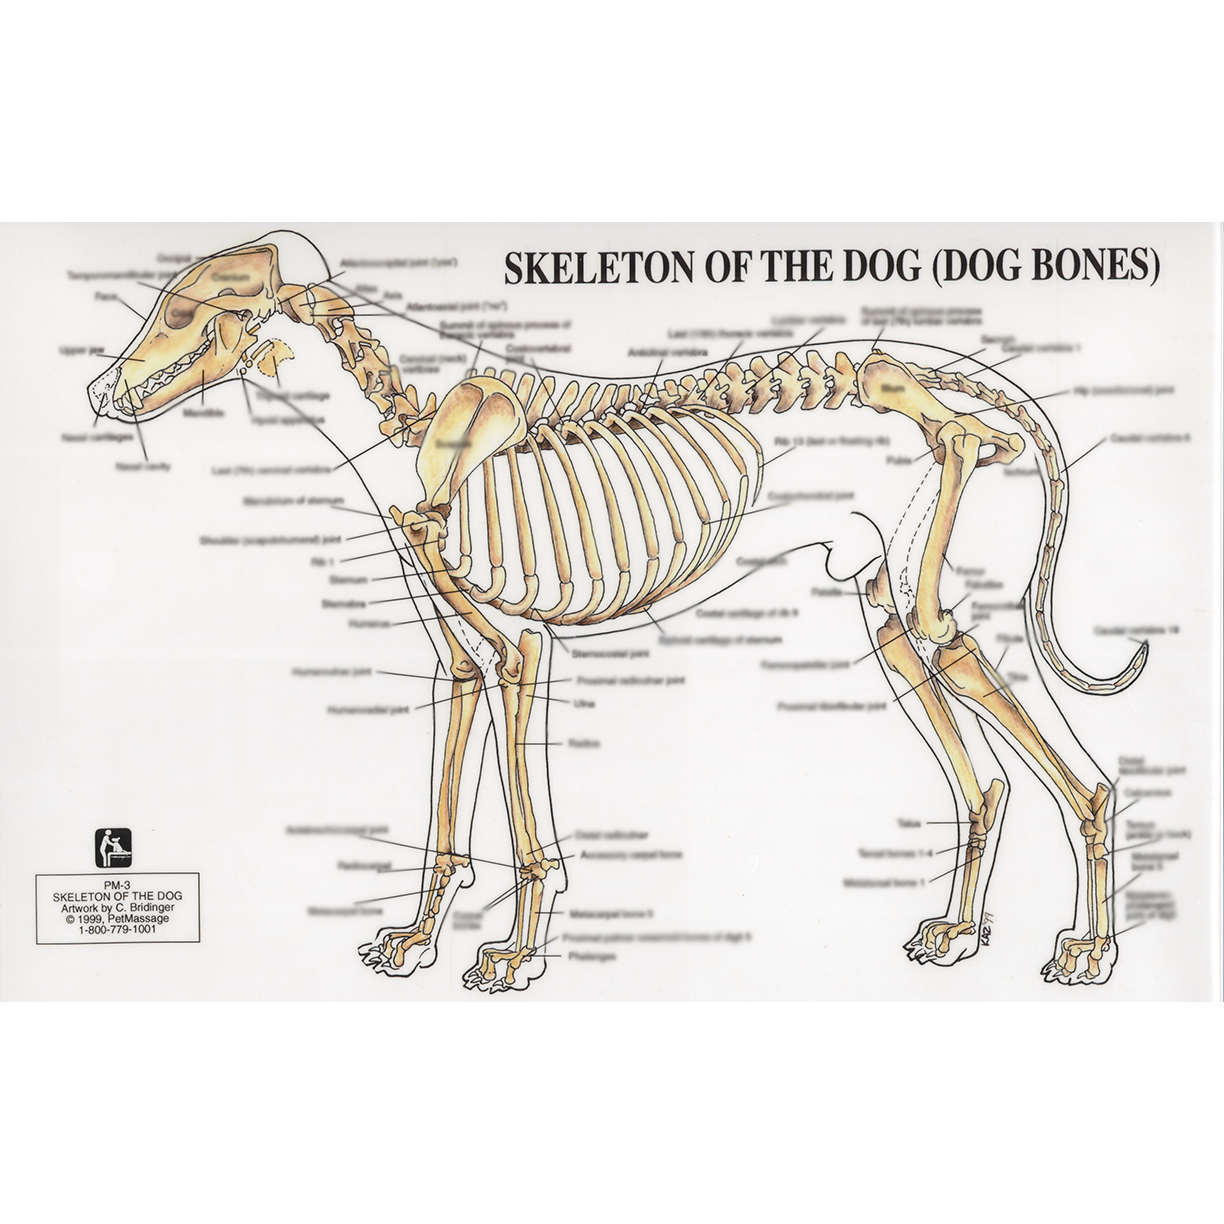
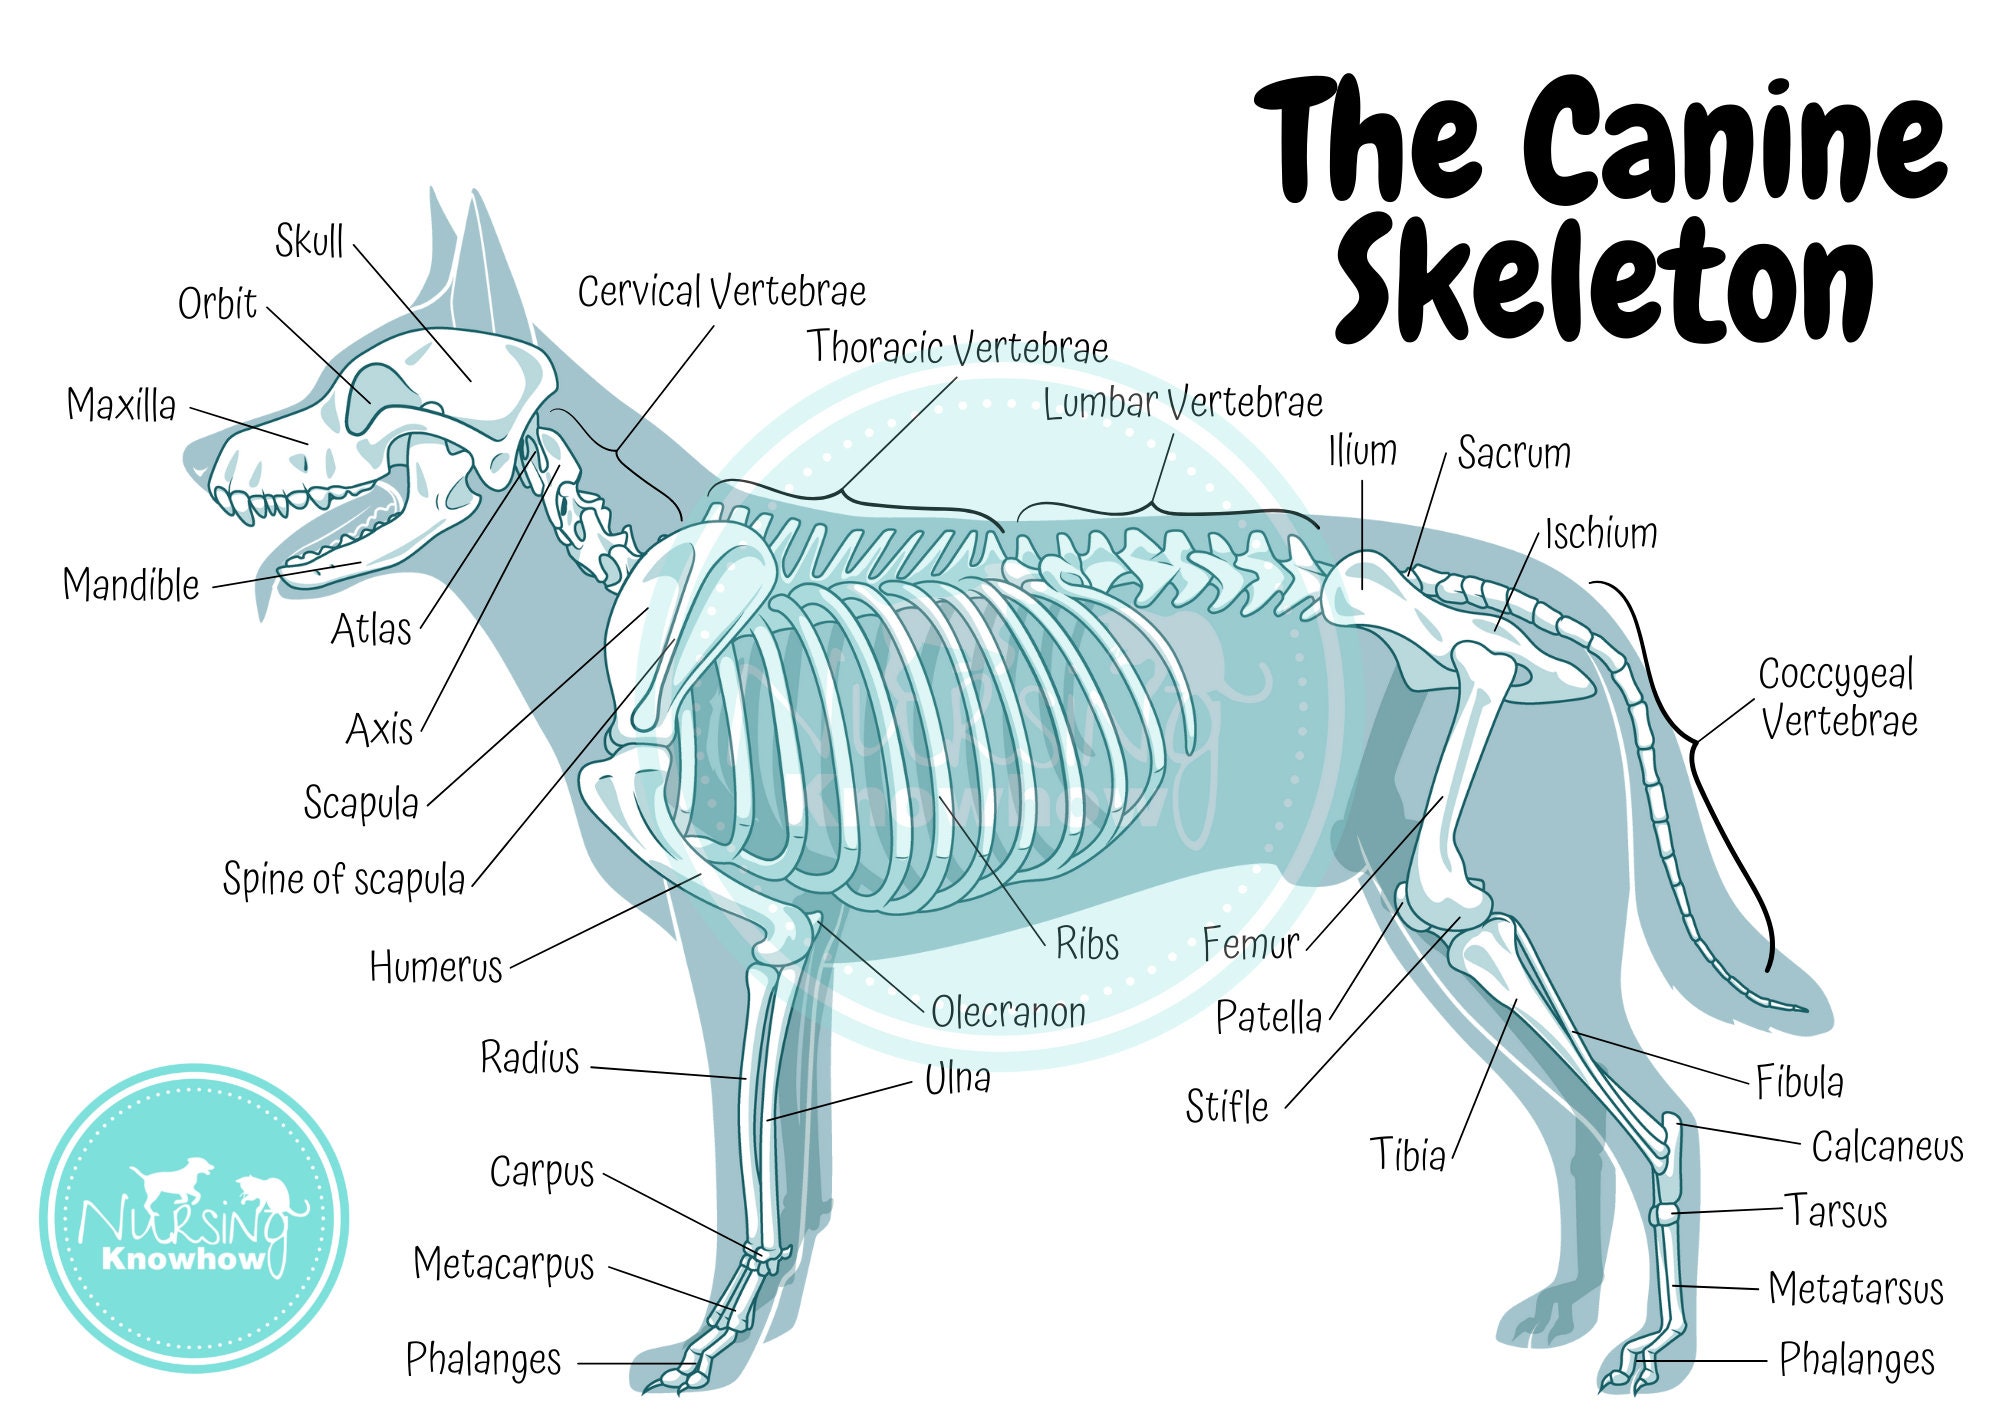
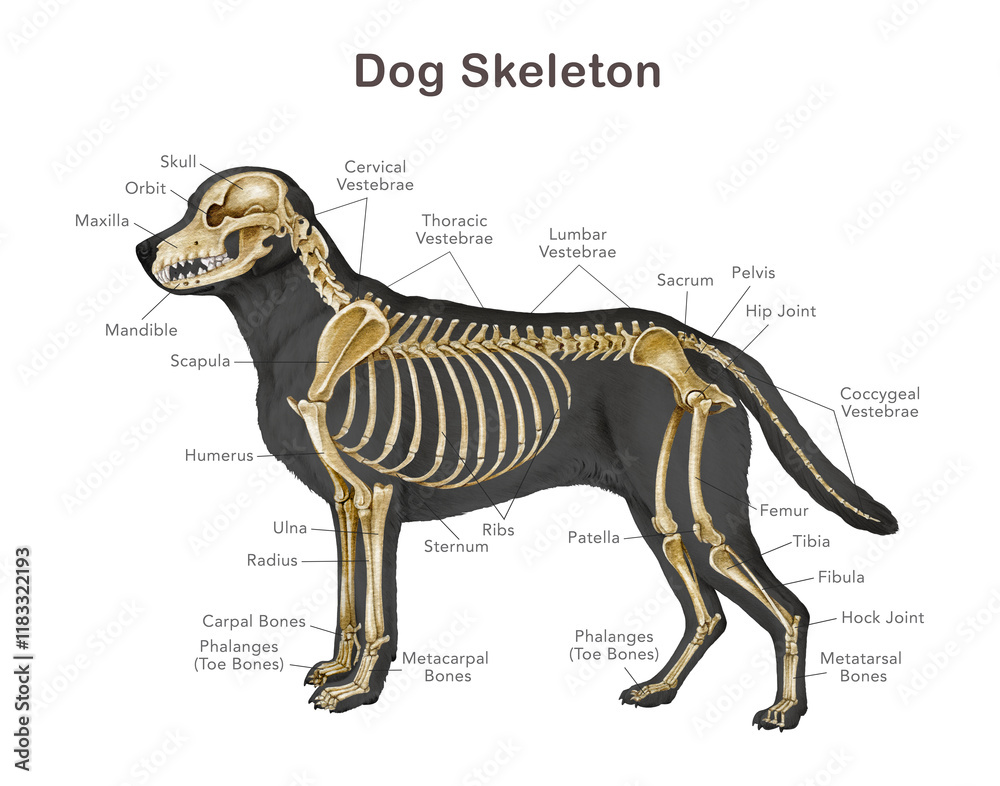
A labeled skeleton for canine pose estimation typically uses 16 to 22 keypoints depending on the project. The standard layout I see referenced most often includes snout, left and right eye, left and right ear, neck, shoulder, elbow, wrist, hip, knee, ankle, tail base, and the corresponding left and right paws. Some projects add a few extra points along the spine for more detailed body tracking. The labels themselves are stored as JSON files containing keypoint coordinates, visibility flags, and grouping IDs that tie the points together into limbs. The visibility flag is where most annotators lose track. A paw that is partially occluded by another leg still needs to be labeled, but marked as invisible so the model learns to handle occlusion rather than snapping to the nearest visible point. If you mark it as visible, the model picks up false confidence on occluded joints and accuracy drops by roughly 8 to 12 percent on my runs. I have been exporting these datasets in COCO and LVIS formats. COCO keeps things simple and most libraries understand it. LVIS gives you better support for crowd and occlusion annotations, which matters if your dataset includes crowded scenes or fast motion blur.
The Tooling Around This
I used CVAT for the bulk of my labeling work. It handles keypoint annotation well, supports interpolation between frames so you only label every fifth frame and let the system fill the gaps, and it exports straight to COCO JSON. Label Studio is another option if you want something lighter and more browser-based, though it does not interpolate by default. For anything heavier, I have seen teams run a combination of CVAT for annotation and a Python script using the COCO API to validate that all joints connect properly and that no keypoints bleed outside the image boundary. The process itself is not complicated. You pull footage, export frames, run an initial auto-labeling pass with a pretrained model like HRNet or SimpleBaseline to get rough keypoint positions, then go frame by frame correcting errors. Auto-labeling cuts the time down from about four hours per hour of video to roughly forty minutes, depending on how clean the footage is. Dogs in motion generate a lot of edge cases, so do not skip the manual pass. The part nobody warns you about is temporal consistency. A joint that is labeled on the left front paw in frame one can drift to the right front paw in frame five if the model gets confused by leg crossing. This creates flickering predictions downstream. I solved this by adding a post-processing step that enforces a minimum distance between consecutive frames for any single joint. If a keypoint jumps more than thirty pixels between frames, the script replaces it with an interpolated value from the surrounding frames rather than letting the raw label stand.
Get the Full Details

A Real Edge Case That Wasted Two Days
Here is a specific problem I ran into. The dataset had a breed cluster of very short-legged dogs, mostly Dachshunds and Corgis, mixed in with longer-legged breeds. The auto-labeler consistently misassigned the wrist and elbow joints on the short-legged breeds because the joint angles fell outside the training distribution of the base model. The skeleton looked reasonable to a human at a glance, but the model trained on it learned the wrong limb topology for those breeds. Accuracy on the Dachshund subset sat at about 41 percent mAP while the rest of the breeds hovered around 78 percent. I fixed it by separating the training data by body type and retraining the auto-labeler on a breed-specific subset before relabeling. It added a day to the pipeline, but it brought the low breed up to 72 percent and eliminated the outlier that was dragging the overall metric down.
Counter-Intuitive Things Beginners Miss
First, more keypoints does not always mean better performance. Adding spinal joints beyond the fourth or fifth vertebra usually just adds noise. The model struggles to localize them precisely and they rarely contribute meaningfully to downstream tasks like action recognition or gait classification. Stick to the major limb and torso joints unless you have a very specific reason to add more. Second, image resolution matters less than you might think for skeleton tasks. Doubling the resolution from 640 by 480 to 1280 by 960 typically improves mAP by less than 2 percent on well-posed frames. What actually moves the needle is consistent joint visibility across diverse backgrounds and angles. Spend your time collecting varied environments rather than shooting in higher resolution.
Honest Limitations
Let me be clear about where this approach breaks down. Fast motion blur from a running dog at close range is nearly impossible to label accurately even for a human, and the model will pick up that uncertainty as noise. Snow, heavy rain, and low-light grain all degrade skeleton quality more than they degrade regular object detection because the joints are small and tightly clustered. If your deployment environment has any of those conditions, plan for a 15 to 25 percent drop in mAP compared to clean lab footage, and budget time for manual correction rather than trusting the auto-labeler. Another hard limit is extreme occlusion. When a dog is viewed from behind with all four legs crossed or lying under a bench, there is simply not enough visual information to distinguish left from right joints. Some teams use geometric priors to infer hidden joints, but that introduces systematic bias into the training data. The model will learn to assume symmetry that does not exist in the real world. Better to mark those joints as invisible and accept the lower coverage than to propagate false labels. If your use case involves these edge-heavy scenarios, you might be better served by switching to an instance-level approach like YOLOv8-Pose or RTMPose fine-tuned on your own data rather than building a large custom skeleton dataset from scratch. Those models handle occlusion better and require far fewer labeled frames to reach usable accuracy.
Data Sources And Downloads
If you do not need a fully custom dataset, there are existing resources. The DogPose dataset and the ViperDog dataset both provide keypoint annotations for various canine breeds. The Oxford-IIIT Pet dataset includes some pose-related labeling that can be extended. For a complete Labeled Skeleton Of A Dog dataset ready for training, you can find pre-annotated versions on Kaggle under canine pose estimation collections, and the COCO format exports are usually available directly without conversion steps. If you need something specific, the most reliable path remains building your own. Collect about two thousand clips across at least ten breeds, run the auto-label pass, correct the critical frames manually, validate with the distance-jump script I mentioned, and split 80-10-10 for train-validation-test. That usually gives you a solid starting point without overcommitting to a full manual annotation pass.