Working with Constraints Without Losing Your Mind
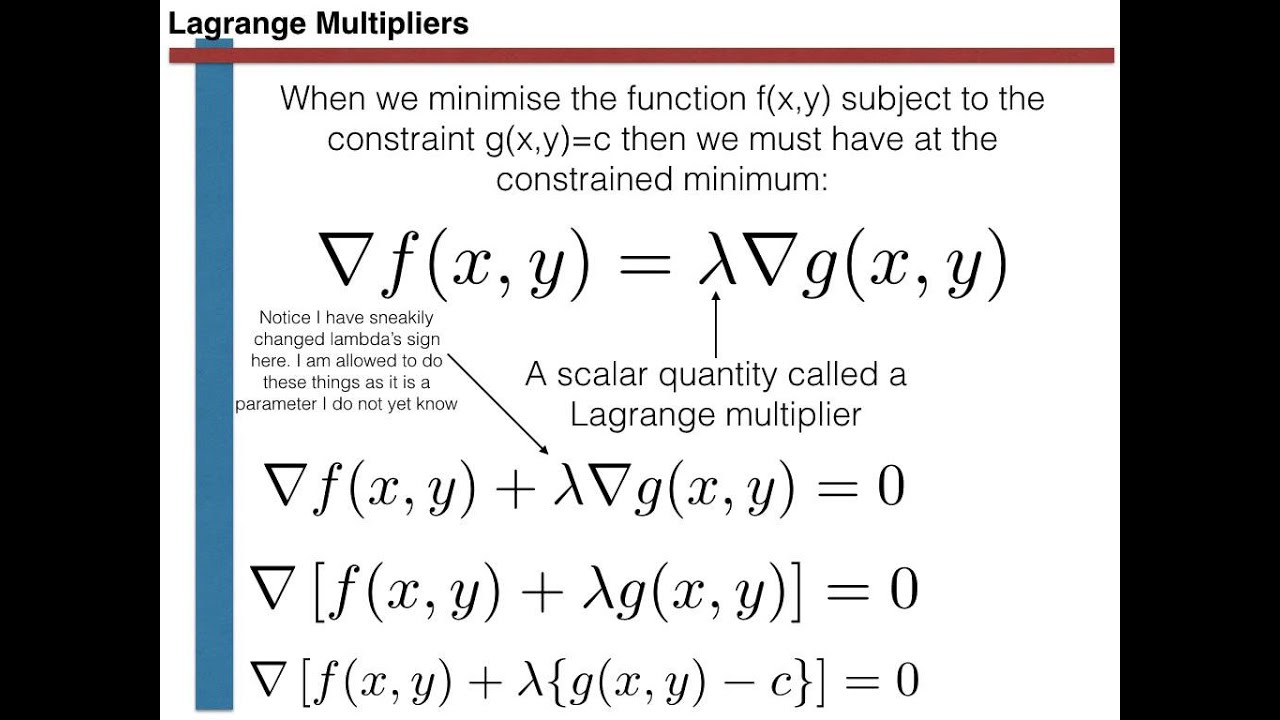
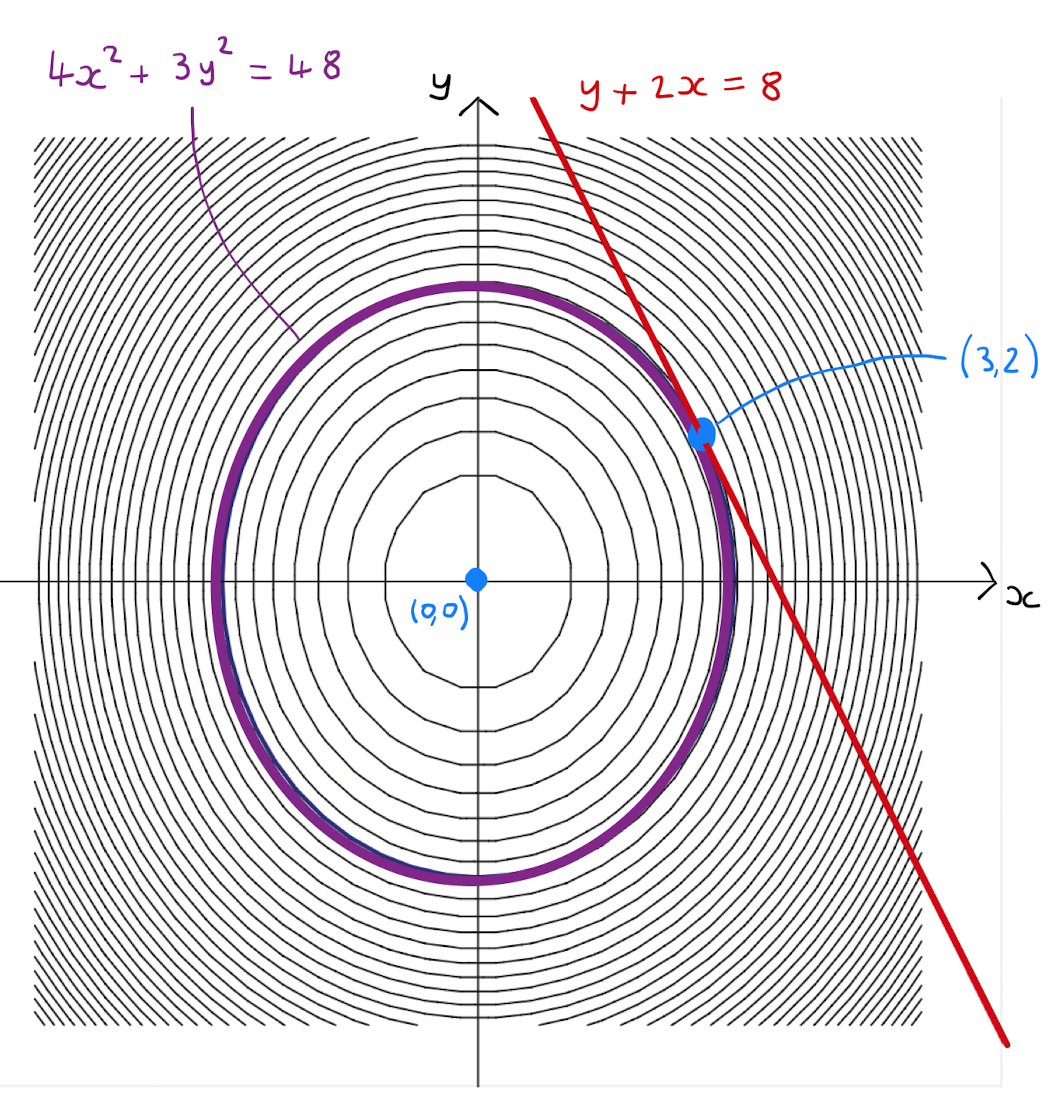
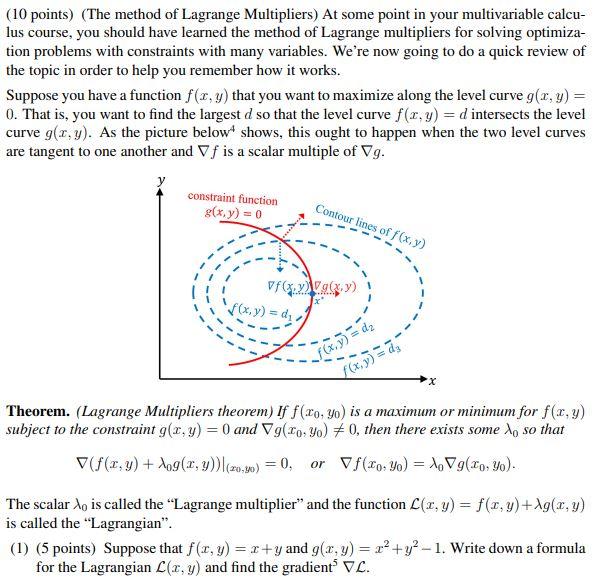
When you need to optimize a function subject to one or more equality constraints, the Lagrange S Method Of Multipliers is the standard approach. I have used it across structural engineering design, economics modeling, and machine learning regularization pipelines. It is reliable when you respect its assumptions and frustrating when you ignore them. The method is straightforward in theory. You take an objective function f(x) and a constraint g(x) = 0, combine them into a single Lagrangian L(x, ) = f(x) + g(x), then find points where the gradient of L vanishes. That gives you a system of equations you solve simultaneously for the variables and the multiplier.
Why the Multiplier Matters Beyond Just Solving
Most people stop once they find x*. The value is not just an intermediate step. In practice, tells you the sensitivity of the optimal objective to a small relaxation of the constraint. If 3.7 in a cost minimization problem with a budget constraint, tightening that budget by one unit will increase your minimum cost by roughly 3.7 units. That interpretation is what makes this method useful in real optimization workflows rather than just an academic exercise. I ran into a genuine edge case last year while working on a thermal management problem. We had three temperature constraints coupling five design variables, and the standard Lagrangian setup produced a Jacobian that was numerically singular at the solution point. The constraints were linearly dependent near the optimum because two of the temperature sensors sat in thermal equilibrium zones where their gradients aligned. The solver kept drifting. What fixed it was reformulating the dependent constraint as a difference equation — instead of g2(x) = 0 and g3(x) = 0, I substituted g3(x) - g2(x) = 0, which removed the near-parallel gradient and restored full rank to the KKT system. The solution converged in three iterations after that change instead of oscillating for hundreds.
The Core Procedure
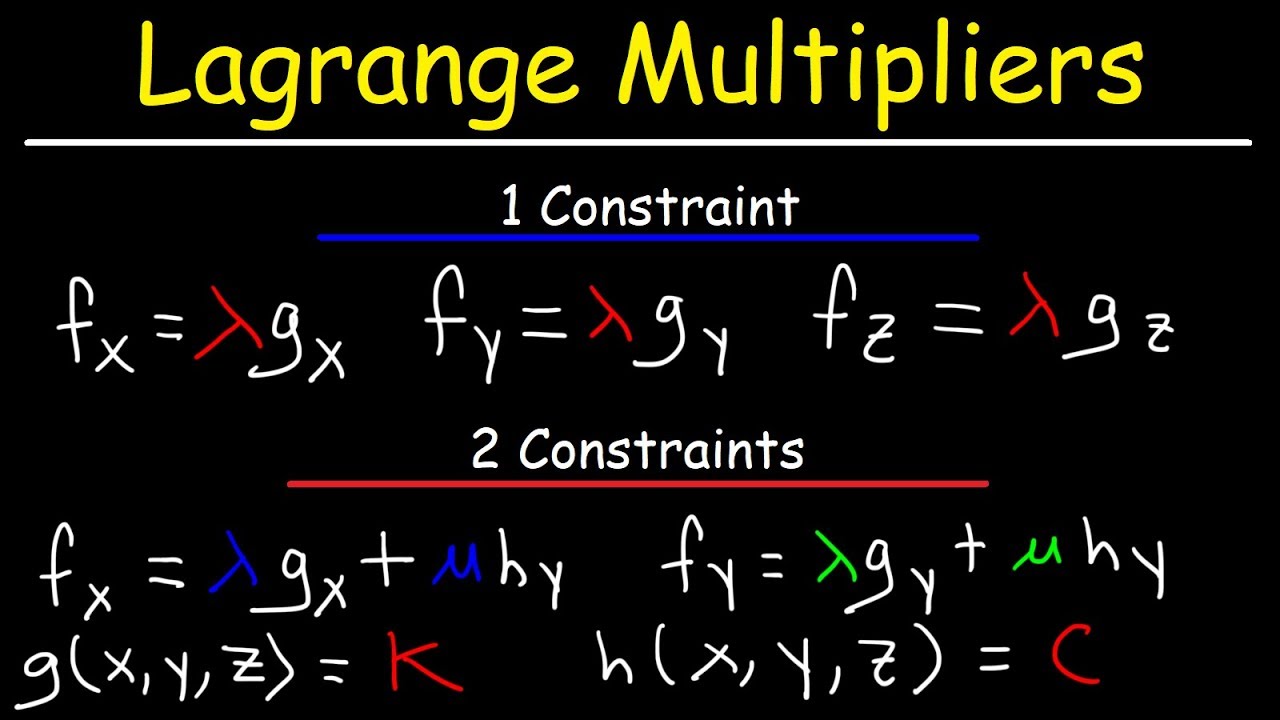
Here is the mechanical process without any fluff. Step one: Write down your objective function and every equality constraint in the form g_i(x) = 0. If a constraint is given as h(x) c, convert it to h(x) - c = 0. Inequality constraints require a different treatment entirely, which I will address later. Step two: Form the Lagrangian. For n variables and m constraints:
Get the Full Details

L(x, ..., x, , ..., ) = f(x, ..., x) + · g(x, ..., x) Step three: Compute partial derivatives of L with respect to every x variable and every . Set each one equal to zero. This gives you n + m equations in n + m unknowns. Step four: Solve the system. Analytically if the algebra permits. Numerically otherwise.
I tend to use a Newton-Raphson approach on the full KKT system rather than trying to reduce variables by substitution. Substitution looks cleaner on paper but introduces algebraic complexity that often makes the numerical solution harder, not easier. A well-conditioned Newton solve on the full system is usually faster and more robust.
A Concrete Example
Minimize f(x, y) = x² + y² subject to x + 2y = 5. The Lagrangian is L = x² + y² + (x + 2y - 5). Partial derivatives:

L/x = 2x + = 0 = -2x L/y = 2y + 2 = 0 = -y L/ = x + 2y - 5 = 0
Setting the two expressions for equal: -2x = -y, so y = 2x. Substituting into the constraint: x + 4x = 5, x = 1, y = 2. The minimum is at (1, 2) with f = 5. The multiplier = -2, which means relaxing the constraint constant from 5 to 6 would increase the minimum value by approximately 2.
Where the Method Breaks Down
The Lagrange method assumes constraint qualifications hold at the optimum. The most common failure mode is when the gradients of the active constraints are linearly dependent at the solution point. This is called a constraint qualification violation, and when it happens, the Lagrange multiplier may not exist or may not be unique. You will see the solver either fail to converge or return a solution that depends heavily on your initial guess. Another practical limitation: this method only handles equality constraints directly. For inequality constraints, you need the KKT framework, which adds complementary slackness conditions. Even then, if you have a mix of equalities and inequalities, the problem becomes a nonlinear programming problem that generally requires iterative numerical methods rather than a closed-form solution. I also want to flag something that beginners consistently miss. The Lagrange method finds stationary points, not necessarily minima or maxima. A stationary point on the constraint surface could be a saddle point. You need to check the bordered Hessian or evaluate the objective at nearby feasible points to determine the nature of the critical point. Skipping this verification step is why some people get results that look mathematically correct but are physically wrong.
Numerical Implementation Notes
If you are implementing this in code, do not form the full KKT matrix explicitly unless your problem is small. For problems with more than about 20 variables, use an augmented Lagrangian approach or an interior-point method. The augmented Lagrangian adds a quadratic penalty term /2 · ||g(x)||² to the Lagrangian, which improves conditioning and allows you to handle the constraints more stably during iteration. This is essentially what the Lagrange S Method Of Multipliers evolved into for practical computation. For Python implementations, scipy.optimize.minimize with the SLSQP method handles equality-constrained problems efficiently and uses an augmented Lagrangian internally. If you need the multipliers explicitly for sensitivity analysis, extract them from the optimizer's result object rather than solving a separate system afterward. The method is not a universal solver. It works well for smooth, convex problems with well-separated constraints. When you hit non-convexity or degeneracy, you will need to fall back on global optimization techniques or reformulate the problem structure. Knowing the boundary of where this method applies is as important as knowing how to apply it.