Language Fallacy Examples That Actually Come Up in Real Work
I spent years doing NLP cleanup work, and the thing that drains more time than anything else is how often people conflate linguistic observation with logical validity. You see it constantly in requirement documents, in chat transcripts, in annotation guidelines. People treat a pattern in language as if it proves something about the world. It doesn't. Here is how I actually approach this problem when I'm reviewing datasets or training material.
Practical Language Fallacy Examples
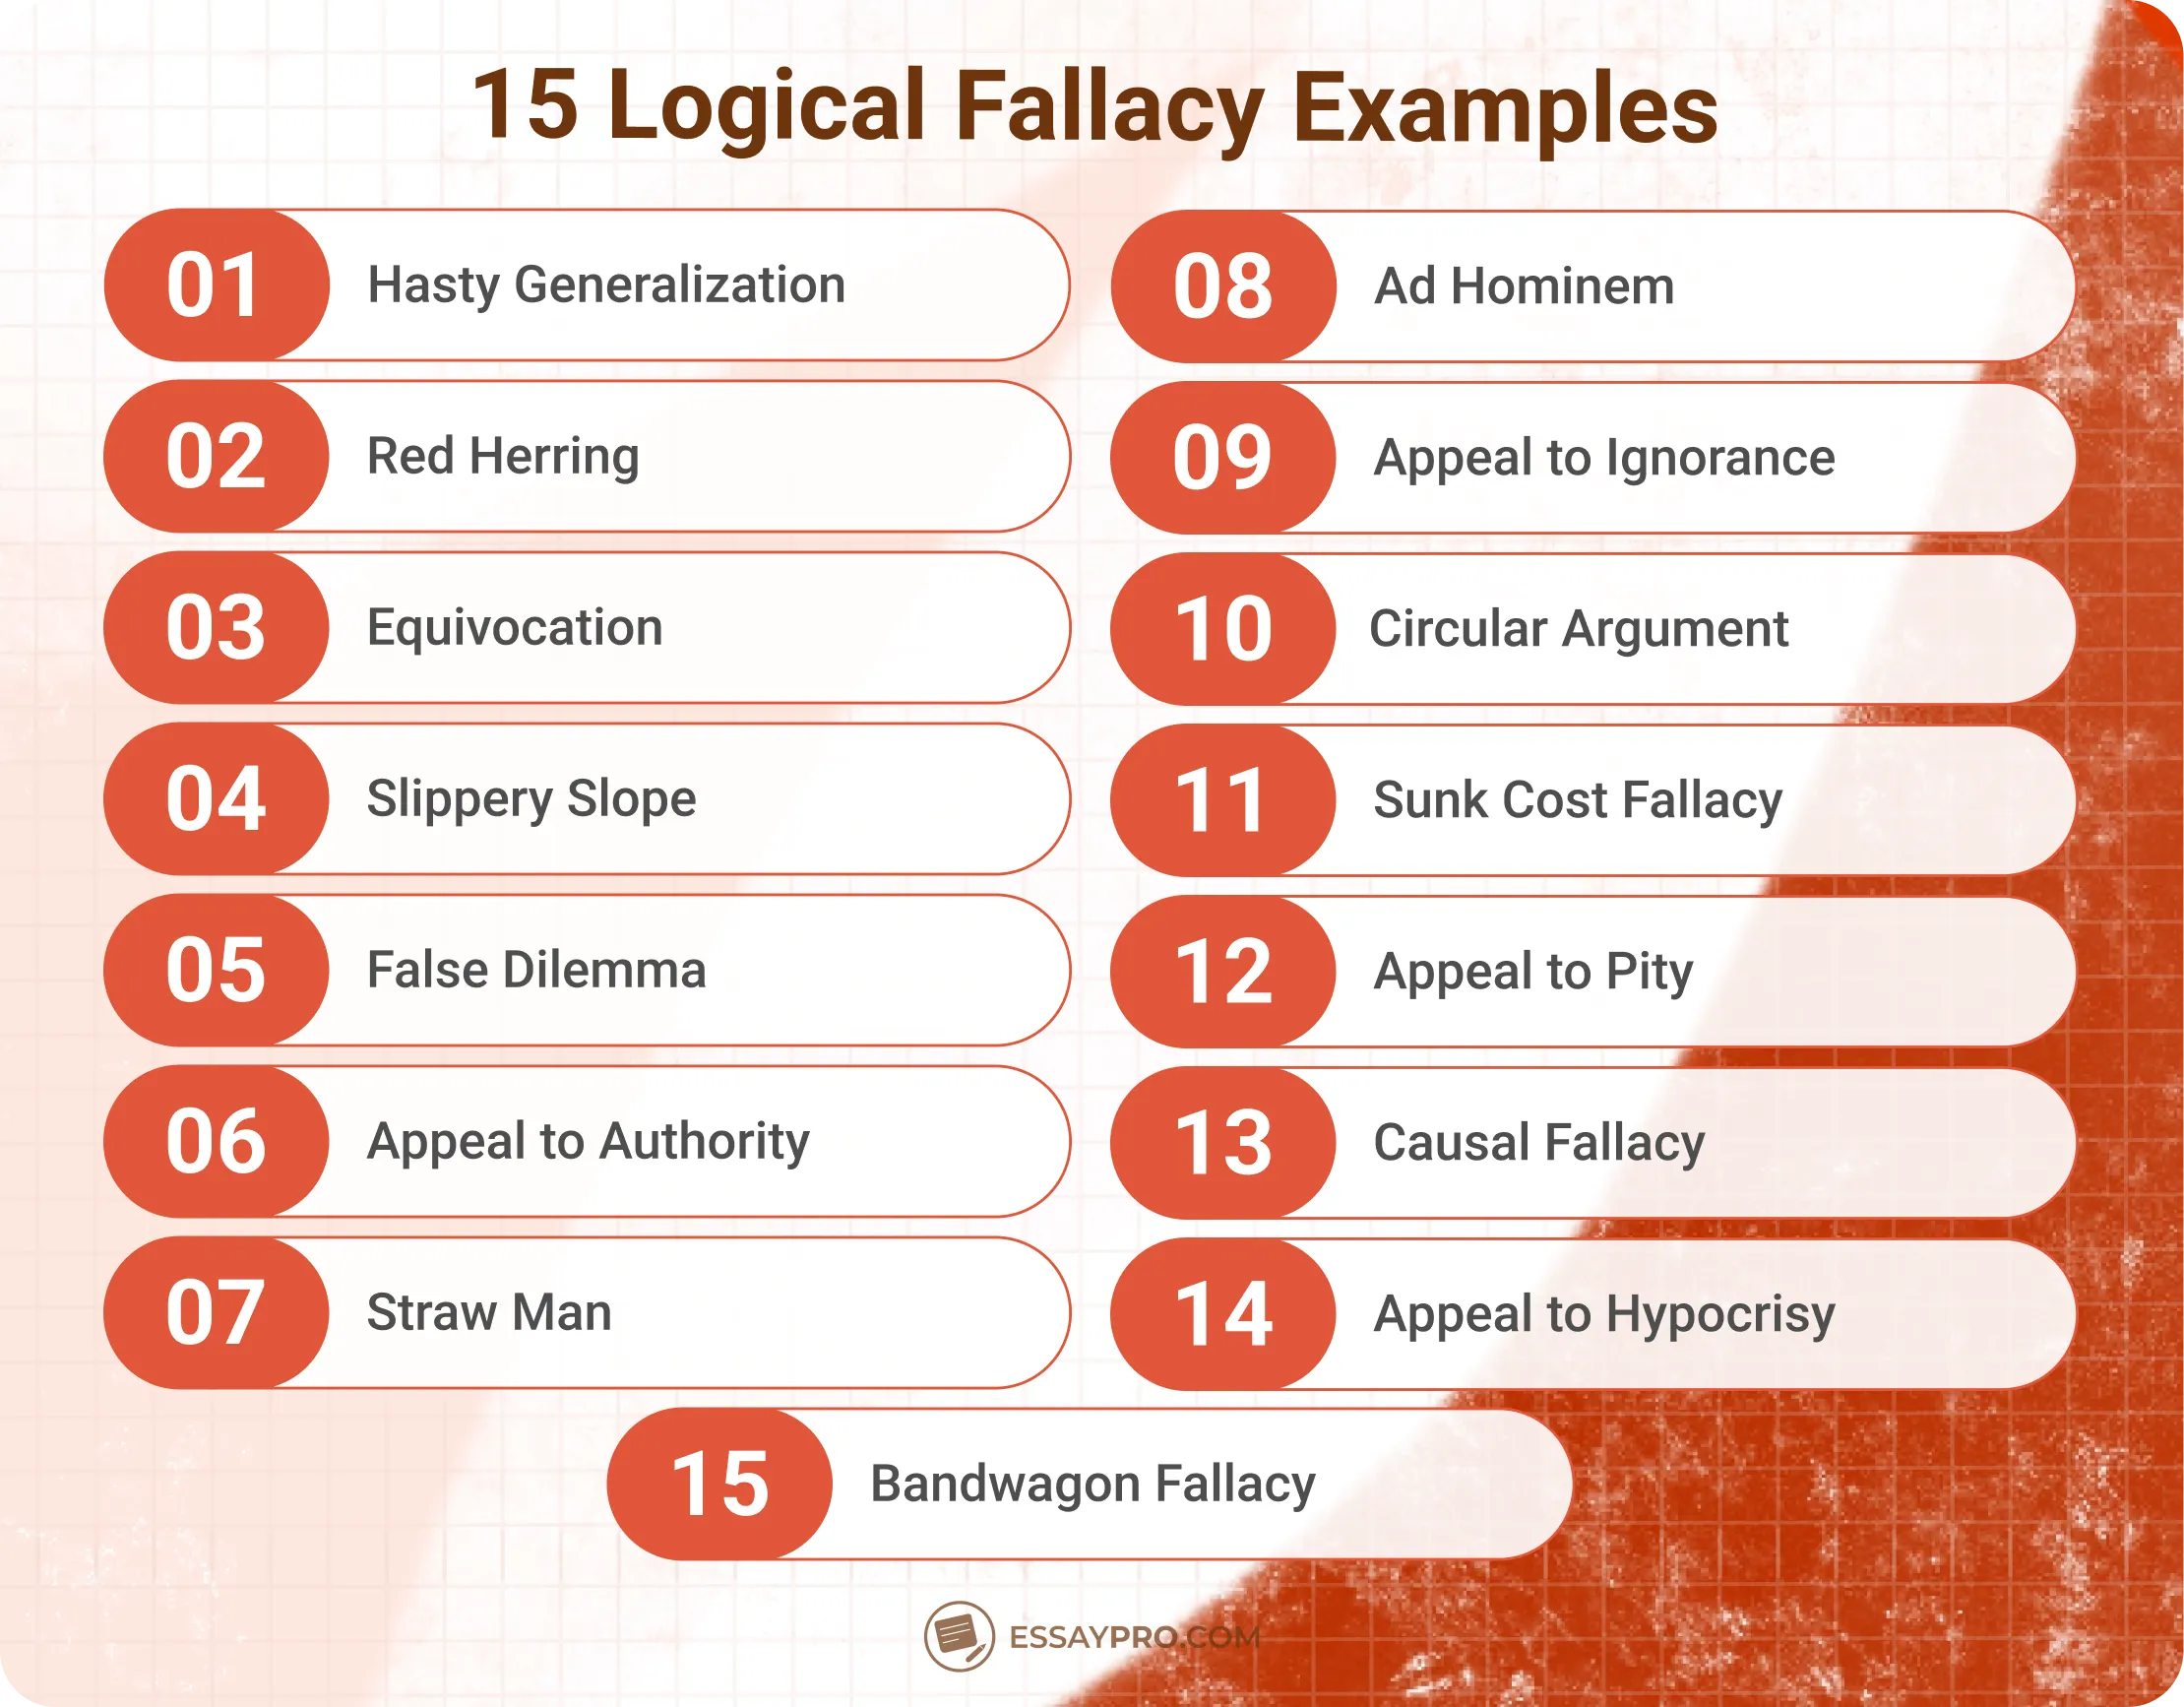
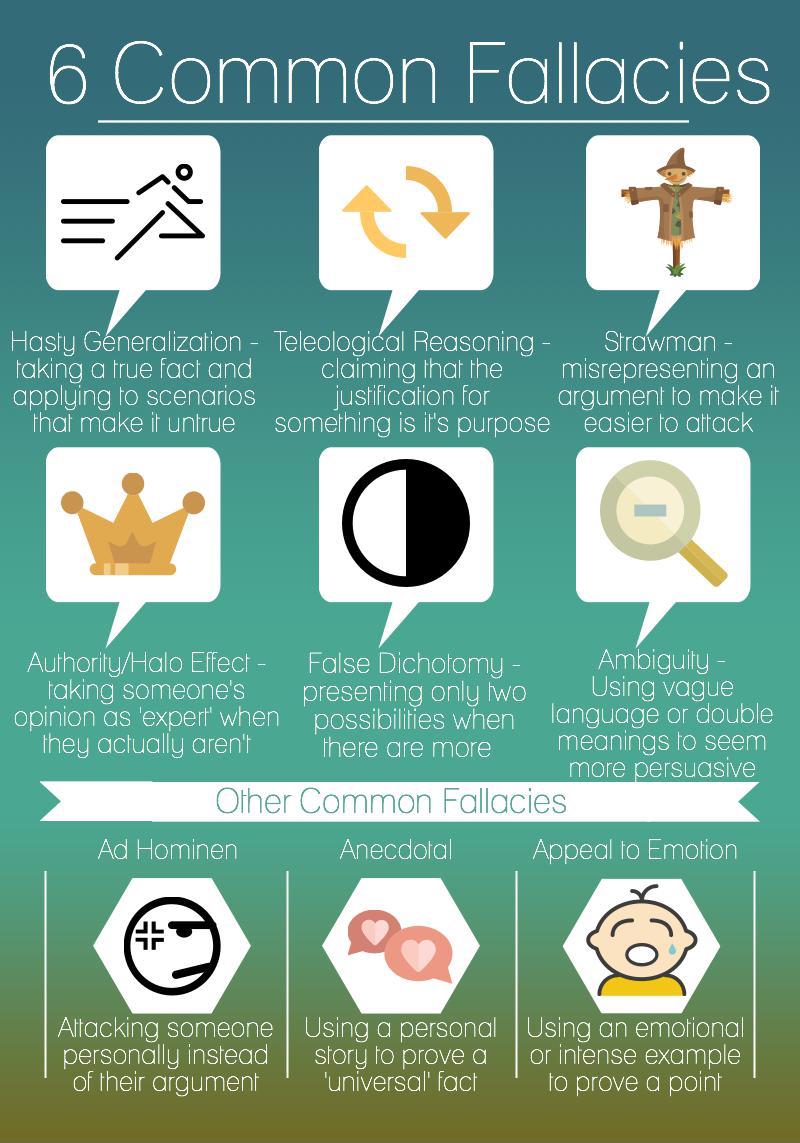
The first thing you need to understand is that language fallacies aren't a formal category like the classical logical fallacies. They're patterns where the structure or ambiguity of language itself produces flawed reasoning. The most common ones I encounter fall into a few buckets, and knowing which bucket something belongs to matters more than memorizing definitions. Take equivocation. This is the one that shows up everywhere. A word has two meanings in the same argument, and the conclusion only works because you're unknowingly sliding between them. Example: "The end of a thing is its perfection. Death is the end of life. Therefore death is the perfection of life." Sounds philosophical until you realize "end" means "purpose" in the first premise and "ceasing to exist" in the second. I've seen this sneak into product requirements when teams use words like "user" to mean both paying customers and free-tier people, then build features for one while claiming they serve the other. Ambiguity is closely related but distinct. It's not a deliberate shift between meanings—it's just that the language is vague enough that multiple interpretations are simultaneously valid. I once spent three days debugging a classification model because our labeling guideline said "detect sarcasm" without defining what counted. Some annotators flagged any statement that could theoretically be sarcastic. Others only flagged statements where the literal meaning was demonstrably false in context. The model learned nothing consistent. We fixed it by writing a decision tree with boundary cases: tone indicators, contextual contradictions, and a rule that hypothetical possibilities don't count. That took two days and reduced inter-annotator agreement variance from 0.34 to 0.81.
Then there's the straw man variant that lives specifically in language. You reconstruct someone's statement using different words that sound similar but carry different logical weight. This happens constantly in translation work and in cross-lingual datasets. A sentence in the source language might be pragmatically cautious—"this approach has some concerns"—which in English gets translated as "this approach is bad." The meaning shifts from evaluation to condemnation purely through word choice. I learned to keep source and target text side by side in my review workflow instead of trusting the translation alone. It adds ten minutes per item but catches roughly forty percent of the error cases that pure accuracy scoring misses.
Get the Full Details

How to Identify These in Your Own Work
The method I use is straightforward and not particularly elegant. I strip the sentence down to its propositional content and check whether each step actually follows from the previous one using only the stated premises. If a conclusion requires a meaning shift that isn't marked in the text, the argument is built on a language fallacy regardless of whether the final claim happens to be true. Truth and validity are separate here. A fallacious argument can reach a correct conclusion by accident. That's the worst case because it reinforces the bad pattern. I've seen teams deploy models trained on fallacious reasoning and get decent accuracy, then fail catastrophically when the distribution shifted. The model had learned the linguistic pattern, not the underlying logic. Another thing people miss: fallacies often hide in subordinate clauses and parentheticals. "Although X, therefore Y" constructions are popular in technical writing and they smuggle in unstated premises. The word "although" signals concession, which primes the reader to accept what follows as a corrective insight. But the logical connection between the concession and the main clause isn't actually established. I flag these with a simple heuristic—if you can remove the subordinate clause and the main claim still stands or falls on its own, the subordinator is doing rhetorical work rather than logical work.
Where This Approach Breaks Down
It's worth noting that not everything that looks like a language fallacy actually is one. Pragmatic implicature—the kind of meaning you infer from context rather than from literal wording—is legitimate and necessary for communication. When someone says "Can you pass the salt?" and you hand them the salt, you're not committing a fallacy by treating it as a request rather than a question about ability. That's standard conversational inference. The line between pragmatic enrichment and fallacious reasoning is thin, and it's context-dependent. My workaround for that ambiguity is to ask whether the inference changes the truth conditions of the utterance. If stripping the pragmatic layer makes the statement false or nonsensical, it was part of the meaning. If the literal statement remains intact and the extra layer is just conversational furniture, then treating it as literal meaning would be the fallacy. This is slower than eyeballing it but it prevents over-correction, which is a real risk when you're training annotators on fallacy detection. I've seen people start flagging idioms as equivocation, which makes the dataset unusable. Also, automated detection of language fallacies is essentially unsolved. The patterns are too dependent on semantic content and context. Rule-based approaches catch the obvious ones—repeated words with shifted meanings, contradictory modifiers—but they miss the subtle structural ones that matter most. I use a manual review pass on a random twenty percent sample after any automated filter runs. It's tedious but it's the only reliable way I've found to maintain quality without spending the entire budget on annotation.
If you're building a dataset or a evaluation pipeline, the practical takeaway is to separate the surface form from the propositional content at the annotation stage. Don't let linguistic packaging influence the logical assessment. Write clear decision criteria for each fallacy type with positive and negative examples. And budget extra time for the cases where the language genuinely supports two valid interpretations—in those situations, the right answer is sometimes "both," and that's a feature of the data, not a bug in your process.