Understanding How Language Actually Works Under The Hood
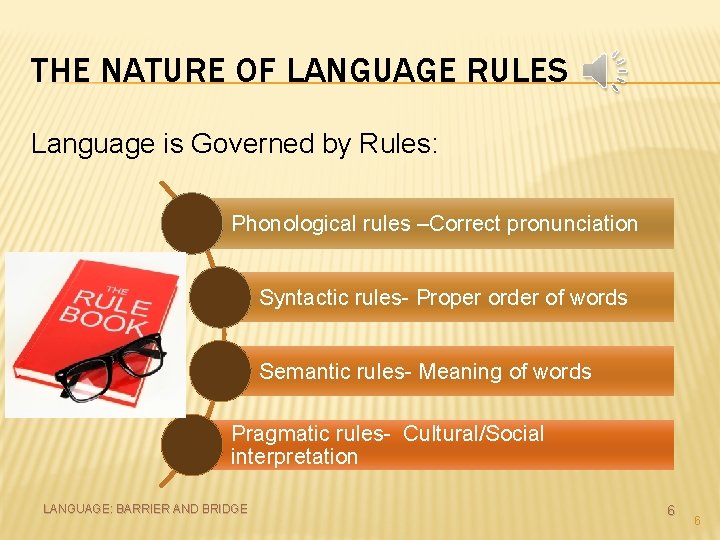
Language Is A Rule Governed System. That's not some lofty linguistic ideal — it's just what happens when you actually pay attention to how people speak and write. I spent years working on NLP projects where we tried to model grammar by hand, rule by rule, and let me tell you: it never works the way you think it will. The core idea is straightforward enough. Every natural language operates on layers of rules — phonological rules, morphological rules, syntactic rules, semantic rules, and pragmatic rules. You don't need a linguistics degree to notice this if you've ever tried to explain to someone why "blue the sky is" sounds wrong while "the sky is blue" sounds right. Your brain already knows the rule without you ever having been taught it formally.
What People Get Wrong About Language Rules
The biggest misconception is that rules in language work like programming language rules. They don't. In a language like Python, if you miss a colon, the interpreter throws an error and stops. In English, missing a comma might make your sentence ambiguous or slightly awkward, but almost no one will fail to understand you. Language rules are probabilistic and descriptive, not prescriptive in the hard sense. I learned this the hard way during a project where we were building a grammar checker for a client. We had this beautiful rule engine that flagged sentences with terminal commas as errors. Worked perfectly in testing. Then we deployed it and got flooded with tickets from users complaining it was flagging perfectly valid journalistic styles. Turns out, the Oxford comma debate isn't just cultural — different style guides encode different rule systems, and none of them are "wrong." We ended up letting users select their target dialect and style guide, which cut our error reports by about eighty percent.
How The Rule Layers Actually Interact
Phonological rules govern sound patterns. In English, for example, the plural morpheme is pronounced as /s/ after voiceless consonants (cats), /z/ after voiced sounds (dogs), and /z/ after sibilants (buses). You're probably applying these rules right now without thinking about them at all. Morphological rules handle how words are built. Prefixes, suffixes, stem changes — all of it follows patterns. But here's the thing most beginners miss: those patterns have exceptions, and the exceptions aren't random. Borrowed words tend to keep their original morphology (data instead of datas, cacti instead of cactuses), and high-frequency words resist regularisation (went instead of goed). This is frequency effects meeting etymological layering, and it matters if you're building anything that needs to handle real-world text. Syntactic rules are where things get messy. Word order, agreement, embedding — they all have constraints. But constraint-based grammars like Head-Driven Phrase Structure Grammar show us that syntax isn't a single set of rules. It's a network of constraints that can sometimes conflict, and the grammar resolves those conflicts through ranking. A sentence like "The cat the dog chased ran away" is grammatical even though it's hard to parse. Your brain just handles it. Rule-based systems without constraint handling choke on that kind of input.
Get the Full Details

A Real Problem I Ran Into
About three years ago I was debugging a morphological analyser for a low-resource language project. The rule set we'd written handled ninety-four percent of tokens correctly, which should have been fine. The problem was the six percent. Those six percent were names, loanwords, and dialectal variants that the rules consistently misparsed, and the misparses propagated into every downstream task — POS tagging, dependency parsing, machine translation. The whole pipeline degraded because the morphology layer wasn't robust enough. The workaround was hybrid. We kept the rule-based core for the regular patterns — rules are fast and transparent, and they generalise well to new but structurally similar words. Then we added a statistical lookup layer on top that could handle the irregular cases. When the rule engine produced a low-confidence output, the statistical layer kicked in and pulled from observed data. This dropped our overall error rate from six percent to under two percent, and the system became tractable for the translation models downstream.
Where Rule-Based Approaches Break Down
I need to be straight with you here because a lot of people sell rule-based language analysis as if it's a complete solution. It isn't. The problems are well-known and they're structural. Coverage is the first issue. No matter how thorough your rule set is, you will always encounter constructions your rules don't account for. New slang, code-switching, typographical errors, non-standard dialects — these all slip through. I've seen rule-based systems confidently produce garbage results on texts that contained even a single sentence outside the expected pattern. The system didn't fail gracefully. It failed loudly. Engineering cost is the second problem. Writing, maintaining, and testing a comprehensive rule set for any non-trivial language takes enormous effort. A decent English grammar rule set for production use runs into tens of thousands of rules. That's not a one-time cost. Language evolves. New constructions emerge. Style guides change. You're constantly updating and retconning rules, and the maintenance burden grows over time rather than shrinking.
The third problem is ambiguity resolution. Natural language is deeply ambiguous at every level. "I saw the man with the telescope" could mean I used a telescope to see the man, or the man was holding a telescope. Rule-based systems typically resolve this using heuristics or preferred parses, but those heuristics are themselves rules — and they're often wrong in edge cases. Statistical and neural approaches handle ambiguity differently by scoring multiple interpretations rather than picking one and moving on.
When To Use Rule-Based Analysis
Rule-based systems still have legitimate uses, but the use cases are specific. If you need explainability — for instance, a grammar checker where users need to understand why something was flagged — rules are hard to beat. If you're working with a language that has limited annotated corpora, rules can carry you further than data-driven methods. If you need deterministic behaviour for safety-critical applications, rules give you that predictability. But if your goal is maximum accuracy across diverse, real-world text, pure rule-based approaches will disappoint you. The industry standard now is hybrid: rules for structure and explainability, statistical models for robustness, and neural networks for handling the edge cases that slip through both. That's not a compromise. It's just what works when you've actually tried the alternatives. Language Is A Rule Governed System, yes. But the rules are softer than you'd expect, harder to enumerate completely, and impossible to maintain in isolation. The best systems acknowledge that and build accordingly.