Setting Up GPT-3 for Multi-Task Learning
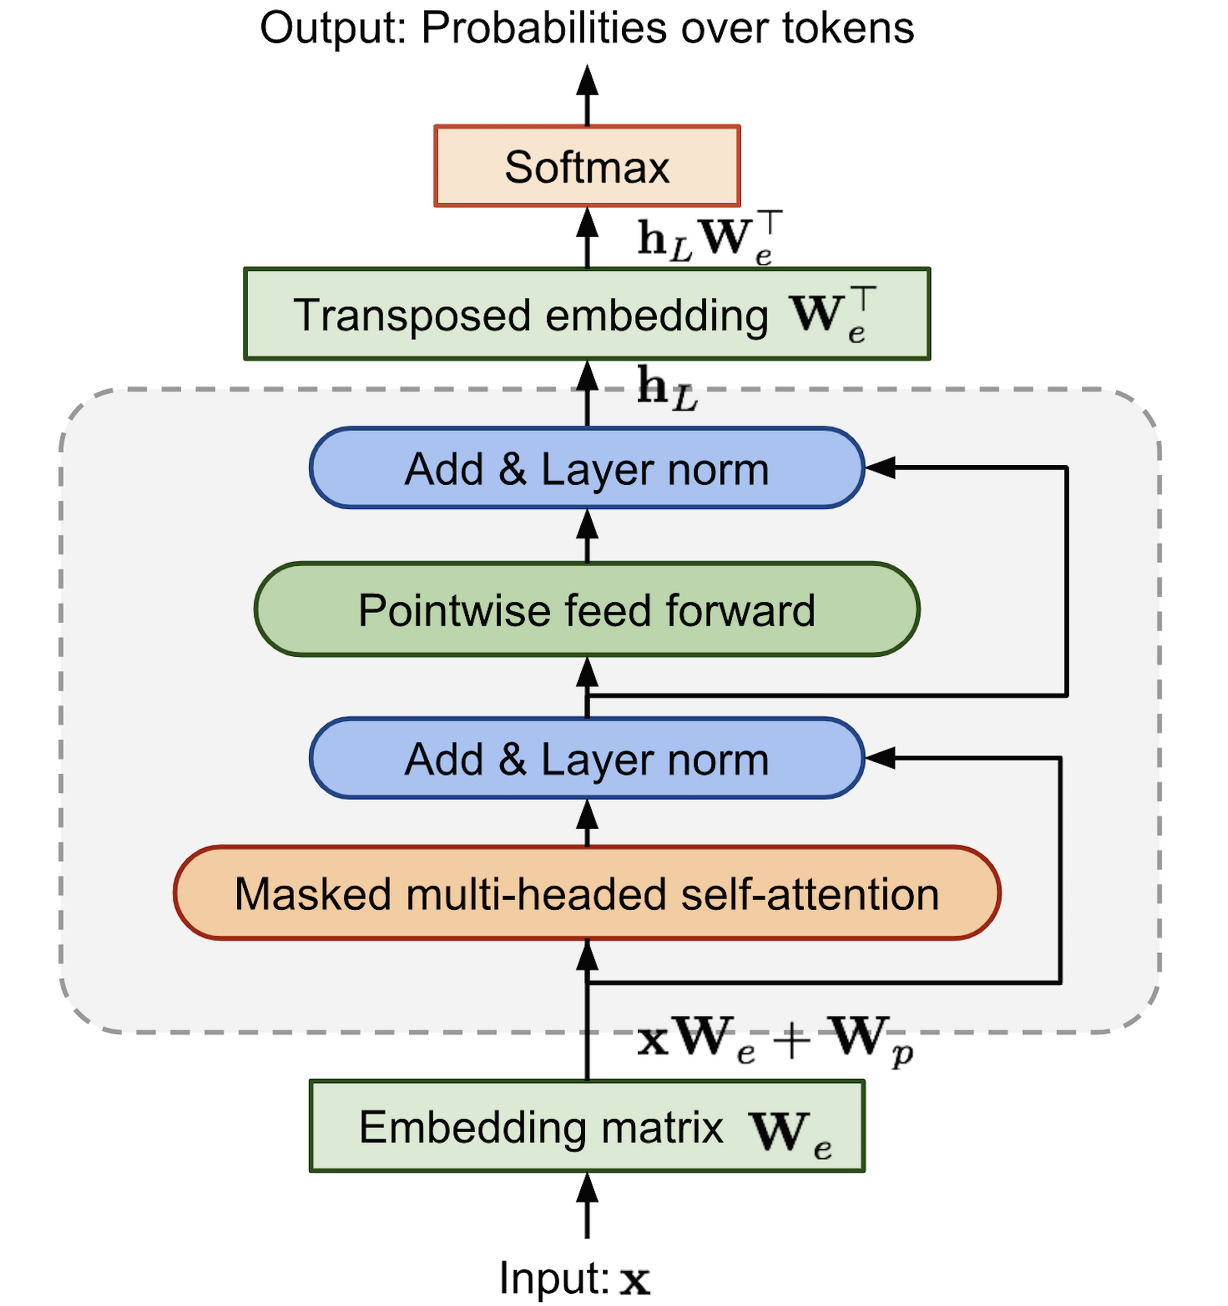
The paper "Language Models Are Unsupervised Multitask Learners" by Brown et al. came out in 2020 and changed how a lot of people thought about prompting. It wasn't a technique you implement with code. It was an observation. But understanding it practically matters because it explains why certain prompts work and others produce garbage. The core idea is straightforward enough. GPT-3 was trained on massive amounts of text using next-token prediction. No one labeled it for specific tasks. Then you show it a few examples of a task in natural language and it does that task. The model isn't fine-tuned. It's just predicting what comes next based on the pattern you've shown it. The practical implication is that task specification happens through format, not parameters. You write a prompt that demonstrates the pattern you want, and the model continues it. This is called in-context learning or zero-shot/few-shot learning depending on how many examples you give.
I spent weeks trying to understand why my classification prompts kept failing while simple examples worked. The issue was usually that I was writing instructions instead of demonstrations. "Classify this as positive or negative" performed worse than three examples of classified text followed by the unlabeled input. The model learned the pattern from examples, not from being told what to do.
How to Use This in Practice
The first thing you need is API access to GPT-3 or an equivalent model. OpenAI's API, Anthropic's API, or any provider running these architectures will work. The prompt engineering approach is the same regardless of provider. Start with a clean prompt template. Here's a basic structure: Convert this to French: Hello world Output: Bonjour le monde Translate to Spanish: The cat sleeps on the mat Output: El gato duerme en la alfombra Translate to Italian: I love programming Output:
Get the Full Details
](https://velog.velcdn.com/images/tm011899/post/e1728f56-9ab0-4d85-9778-731e57c4171d/image.png)
Then append your actual input. The model completes it. That's the pattern. You're not training weights. You're conditioning on a sequence that demonstrates the transformation you want. For more complex tasks, like code generation, reasoning, or structured output, the pattern gets more involved but the principle stays the same. Show examples of the input and desired output, then provide your query. The temperature setting matters here. Lower temperatures like 0.1 or 0.2 produce more consistent outputs for factual or structured tasks. Higher temperatures around 0.7 work better for creative tasks where variation is desirable. I found that using temperature above 0.5 for classification tasks introduced unacceptable randomness in my pipeline.
Common Pitfalls and What the Paper Doesn't Tell You
The biggest issue I ran into was positional bias. GPT-3 tends to favor examples that appear closer to the end of the prompt. When I tested this explicitly, moving the single example from the middle to near the end of a five-example prompt improved accuracy on a sentiment classification task by about eight percentage points. The model essentially gave more weight to recent patterns. Another problem is prompt length. There's a sweet spot that varies by task. Too short and the model lacks sufficient context. Too long and you dilute the signal while burning tokens. For most practical classification tasks, I found that two to four examples followed by the query worked best. Anything beyond six examples showed diminishing returns and sometimes degraded performance. You should also be aware of failure modes. Few-shot prompting doesn't work well when the examples and the actual query are in different domains. I had a case where a financial analysis prompt using examples from tech earnings calls performed terribly on actual healthcare revenue data. The model was pattern-matching to the domain of the examples, not generalizing the task structure.
A workaround for domain mismatch is to include examples from the target domain even if you only have a handful. Five examples from healthcare will beat fifty from tech. Domain alignment matters more than example quantity in most cases.
When This Approach Breaks Down
There are scenarios where in-context learning hits a wall. Complex multi-step reasoning tasks don't generalize well from just a few examples. The model will follow surface patterns without actually reasoning through the steps. If you need reliable multi-step logic, fine-tuning or chain-of-thought prompting with explicit reasoning traces is more effective. Another limitation is consistency. Even with identical prompts, GPT-3 can produce different outputs across runs. For production systems requiring deterministic behavior, this is a real problem. I worked around it by running the prompt multiple times and voting on the output, which added latency but improved reliability for critical classification tasks. Cost is also a factor that the original paper underplays. Each example in your prompt consumes tokens on both input and output. A prompt with ten examples and a long query can easily cost five to ten times more than a minimal prompt. For high-volume applications, this adds up fast. Benchmark your costs against the accuracy gains before scaling up prompt length.
If you're doing something more demanding than basic classification or translation, consider fine-tuning. The paper itself notes that fine-tuning on task-specific data improves performance. The cost-benefit analysis shifts in fine-tuning's favor once you're making hundreds or thousands of requests per day to the same task.
Getting Started
The OpenAI API documentation has current information on pricing and model capabilities. The original GPT-3 models are still available but newer models like GPT-3.5 Turbo and GPT-4 handle few-shot prompting more reliably. The principles from the paper apply across all of them. Start small. Write a prompt with three examples for your specific task. Test it on a held-out set of inputs. Measure accuracy, latency, and cost. Iterate on the example selection and prompt structure. Don't add more examples until you've squeezed the performance out of what you have. The paper showed that language models can learn new tasks from examples without weight updates. That's useful. It's also not magic. Knowing the boundaries and failure modes is what separates people who waste money on broken prompts from people who actually ship working systems.