What You Actually Need to Know About Venezuelan Spanish
Spanish in Venezuela has regional features that can throw off learners who only studied textbook Caribbean or European Spanish. I spent time tracking down translation resources for regional content and ran into a wall of mismatched vocabulary. That experience changed how I approach the Language Of Venezuela South America from a practical standpoint. Venezuelan Spanish uses vos instead of tú in most of the country. Verb conjugations shift accordingly. Decir becomes decís. Vos sos from Argentina works differently here. The voseo is widespread but often confused by Spanish courses designed for Mexico or Spain. If you're building any kind of NLP pipeline or learning material, you need tools trained on Venezuelan corpora. Standard datasets like CC-100 will drown your model in Mexican and Argentine data, and the model will perform poorly on real Venezuelan text. There are also regional variations within Venezuela. Coastal speech near Caracas has different intonation than the western states like Táchira or Zulia. A person from Maracaibo may drop final consonants more noticeably than someone from the Guayana region. This isn't just phonetic variation. It affects how automated speech recognition systems perform across different states.
Practical Problems With Machine Translation on Venezuelan Spanish
I was working on a document translation project last year involving Venezuelan government and legal text. The Google Translate and DeepL outputs were readable but wrong in key places. The word quemar in Venezuela commonly means to hit someone, not to burn. A legal clause got translated as if it described arson instead of assault. Another issue: apartament is how Venezuelans say apartment. Standard translations output "apartment" and miss the local terminology that appears throughout property documents. The workaround I used was straightforward. I pulled the CMU and Wikipedia-based multilingual corpora, filtered for Venezuelan sources, and created a small domain-specific glossary. Then I ran the MT output through a post-processing step that swapped known Venezuelan terms using a simple lookup table. Translation quality for legal and administrative text improved significantly after that. The glossary approach takes about 30 minutes to set up for a specific domain.
Common Pitfalls Learners and Developers Miss
The biggest mistake people make is assuming Venezuelan Spanish is close enough to other dialects that they can ignore regional training data. They can't, not if accuracy matters. Even basic customer service chatbots built on generic Spanish corpora will confuse users when confronted with local slang. Words like wey, bacano, and chimba carry regional meanings that standard models treat as noise. Some NLP pipelines simply strip these out, which destroys sentiment accuracy in user feedback. Another counter-intuitive point: some Venezuelan Spanish features are being documented in standard dictionaries, but the dictionary definitions still lag behind actual usage. Fila doesn't just mean queue or line in Venezuela. It can mean being tired or exhausted, depending on context. This changes how a parsing model understands sentence structure in casual speech.
Get the Full Details

Resources That Actually Work
If you need training data or reference material, start with the RedILCA corpus and the Venezuelan Wikipedia mirror. The Venezuelan news archive at El Nacional and Ultimas Noticias provide current written Spanish with regional spelling and vocabulary preserved. For speech, the Venezuelan Spanish ASR benchmarks from recent papers give you realistic test cases rather than synthetic data. For learners, the Real Academia Española's Palabras de los venezolanos section is useful, though incomplete. It covers only a fraction of active vocabulary. More practical is using the ASALE website and supplementing with local forums and social media to see how words are actually used in different contexts and age groups.
Where Standard Approaches Break Down
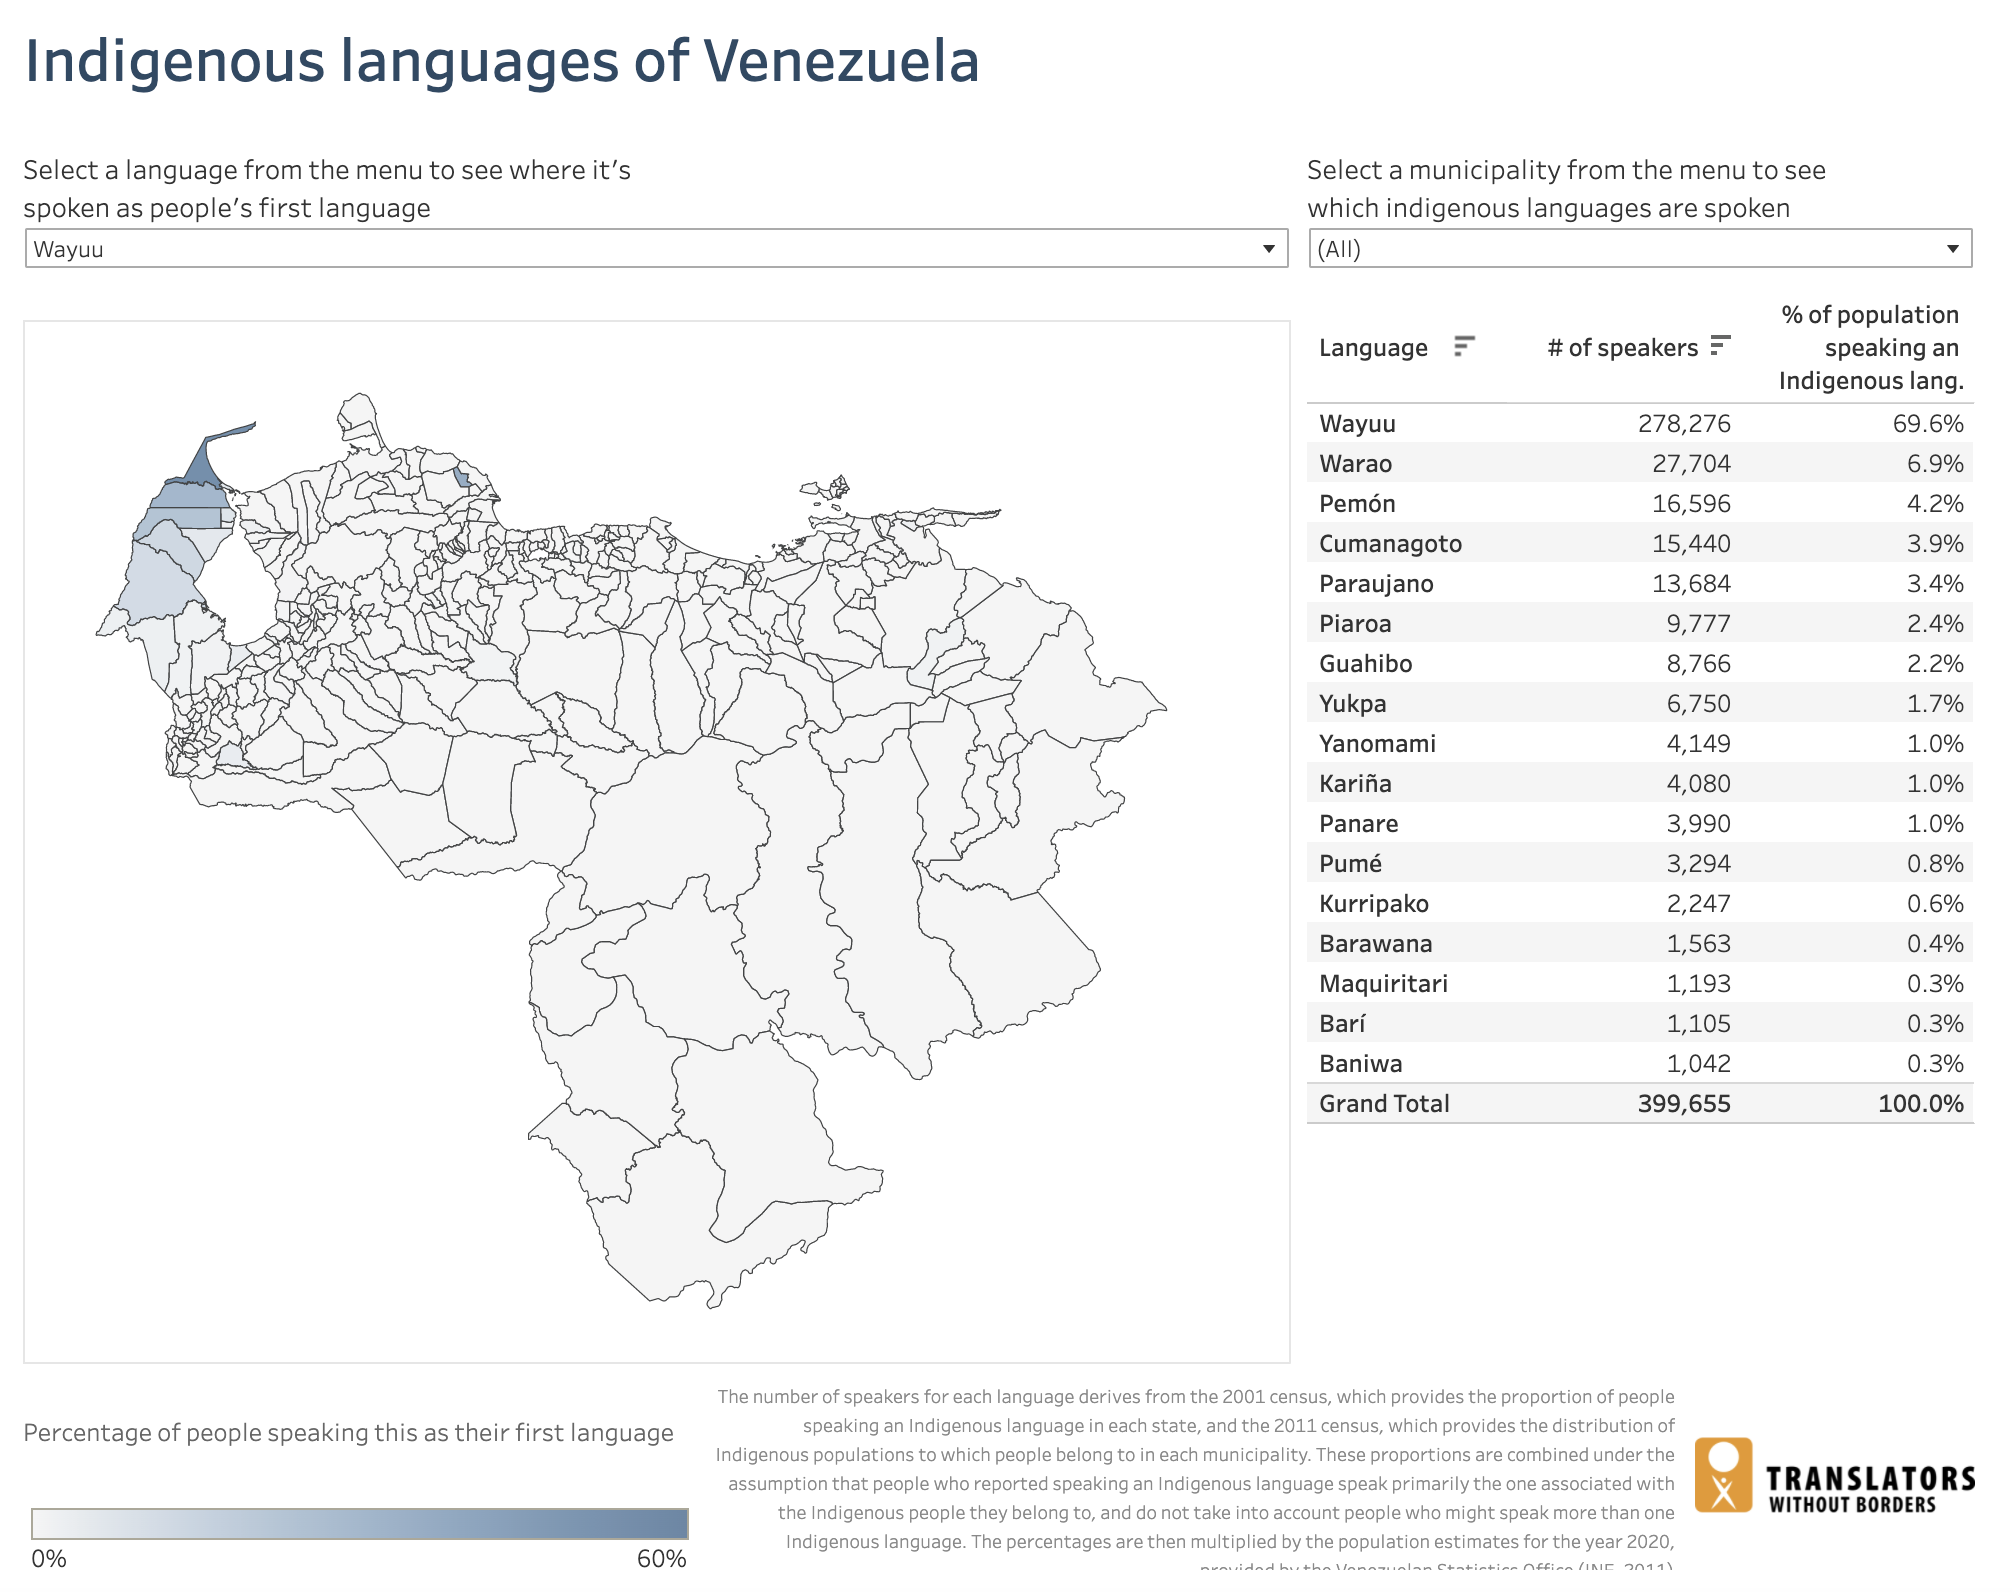
No existing tool handles Venezuelan Spanish perfectly. Google's NMT models improve with each update but consistently underperform on code-switched text where Spanish mixes with English or indigenous languages like Wayuu. Legal and medical documents are especially problematic. These domains use standardized terminology that overlaps with other Spanish-speaking countries, but the surrounding conversational text introduces regional variation that flattens in generic processing. For high-stakes translation work, the best approach remains a hybrid: machine translation for speed plus human review on domain-specific glossary terms. I budget roughly 15 minutes per page for a bilingual reviewer familiar with Venezuelan variants. It is not free but it avoids the kind of costly errors that come from trusting off-the-shelf tools without adaptation.