Building a Languages Spoken In America Pie Chart: What Actually Works
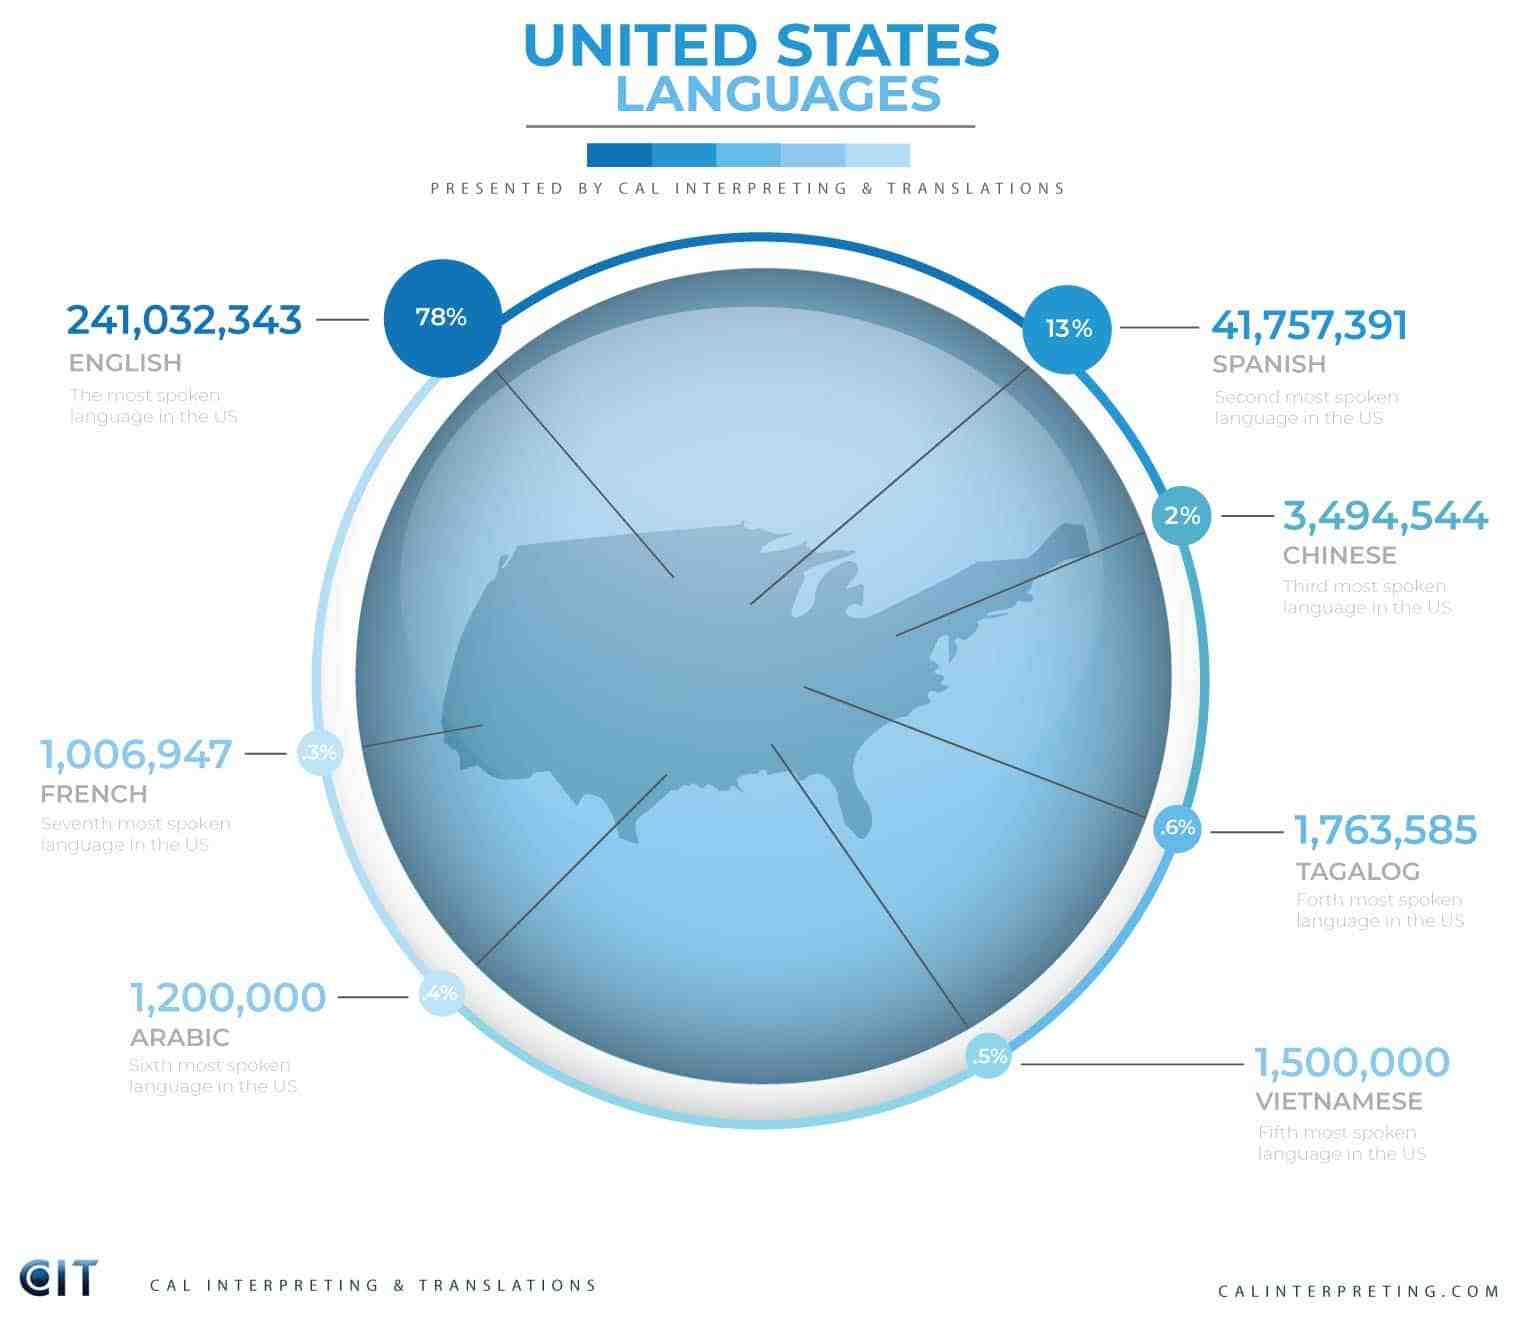
A pie chart showing languages spoken in America is straightforward to make but tricky to get right. The data comes from the US Census Bureau's American Community Survey, which asks households what language they speak at home and whether anyone over five also speaks English less than very well. The 2023 ACS one-year estimates give you the numbers most people rely on. English is spoken by roughly 78% of the population at home as the only language. Spanish comes next at about 13%. Chinese languages total around 1%, Tagalog sits near 0.6%, Vietnamese at roughly 0.5%, Arabic at about 0.4%, and French including Haitian Creole rounds out the top tier at close to 0.7%. The remaining categories fall below 0.3% each and include Korean, Hindi, Russian, and a long tail of other languages. I prefer using Python with matplotlib because it handles the cleanup work better than Excel does, especially when you need to merge categories. You can pull the raw data directly from the Census Bureau API using their Python client library, which returns clean tabular data. If you don't want to deal with the API, the Census website lets you download CSVs from their data explorer under the "Language Spoken at Home" table, specifically table ID S1601. That table gives you counts for every language pair combination, which is useful if you need the bilingualism breakdown rather than just the household language number. The basic code takes about ten lines once you have your data loaded. Here is the core of it:
import matplotlib.pyplot as plt
labels = ['English only', 'Spanish', 'Chinese', 'Tagalog', 'Vietnamese', 'Arabic', 'French/Haitian', 'Other']
percentages = [78, 13, 1, 0.6, 0.5, 0.4, 0.7, 6.3]
plt.pie(percentages, labels=labels, autopct='%1.1f%%', startangle=90)
plt.title('Languages Spoken at Home in the United States')
plt.show() The autopct parameter formats the percentage labels directly on the slices, and startangle=90 rotates the chart so the largest slice begins at the top, which reads better. If you are doing this in Excel, select your two columns of data, go to Insert > Pie Chart, and pick the 2D variant. The 3D version distorts the visual proportions and makes it harder to compare slices accurately, so skip it unless someone specifically asks for one.
Where the Data Gets Messy
The ACS defines "language spoken at home" as the language most frequently spoken in the household, not the language of primary communication for every individual member. That distinction matters because a household where parents speak Spanish and children speak only English gets coded as Spanish-speaking for the primary language count, but those same children would not appear in the limited English proficiency column. The Census tries to separate these two measurements, but they overlap in ways that create confusion when you are just trying to make a clean pie chart. I ran into a specific problem last year when someone asked me to produce a chart that showed the number of people who speak a non-English language at home but are fluent in English. The ACS table S1601 has a column for "speaks English less than very well" among non-English speakers, but the marginal totals do not line up the way you expect. The counts include people who self-report as bilingual at lower proficiency levels, and the error margins on smaller language categories are substantial. My workaround was to pull the detailed cross-tabulation data from the Census microdata sample instead of relying on the published summary tables. The PUMS files contain individual-level records where each person has their own language and English proficiency flags, which lets you filter and aggregate exactly the way you need rather than wrestling with inconsistent marginal totals. It takes longer to process, maybe two to three hours for someone who is not used to working with survey microdata, but the results are accurate.
Get the Full Details

Common Mistakes to Avoid
The biggest issue is treating the "Chinese" category as a single language. The Census separates Mandarin and Cantonese in some tables but lumps other Chinese varieties together depending on the table ID you pull. If you use the summary tables, you may end up with a Chinese slice that is actually a mix of several distinct languages with different speaker populations. The fix is to break Chinese into Mandarin, Cantonese, and Other Chinese varieties using the detailed breakdown tables. Tagalog and Filipino are sometimes reported separately and sometimes combined, so check the source before you assign a single number. Another mistake is ignoring regional variation. A pie chart that aggregates the entire country will look very different from charts produced for individual states. California and Texas have different language distributions than Minnesota or New York. The national average masks these differences entirely. If your audience needs regional data, produce separate charts rather than pretending a single pie tells the whole story. The ACS provides state-level estimates, though the one-year estimates have wider margins of error for smaller states. The five-year estimates are more stable but less current. The pie chart format itself has limitations that you should acknowledge. It shows proportion within a single year, but it does not convey trends over time. Language shift happens, and the percentage of homes speaking Spanish at home has been rising steadily for decades while the Chinese-speaking population has grown even faster in recent years. If someone wants to see those dynamics, a line chart or stacked area chart communicates the change much more clearly than a static pie chart ever could.
Practical Data Sources
The Census Bureau's data.census.gov portal is the primary source. Search for table S1601 or use the American Community Survey language tables directly. The API endpoint is https://api.census.gov/data/2023/acs1?get=B16001_B03003&for=us:01, which pulls the core language data. For microdata, you need to register for a Census account and request access to the PUMS files, a process that takes a few business days. If you want something faster and do not mind working with published summaries, the Migration Policy Institute maintains updated tables based on ACS data with clearer categorization than the raw Census output. Their summaries are what I use when I need quick reference numbers without downloading and processing raw microdata. Most people finish a basic pie chart in under thirty minutes using the summary table approach. The full version with proper category cleanup, error margin notes, and regional comparisons usually takes two to four hours depending on how detailed you want to be. The data is publicly available and free, so there is no cost barrier, only a time barrier for anyone who wants the numbers to be accurate rather than approximately right.