Fine-Tuning Models Without Losing Your Mind
I spent three weeks last year fine-tuning a model for a customer support routing task and learned more from the failures than anything in any tutorial. Here is what actually happens when you do it right.Large Language Model Fine Tuning: The Practical Steps
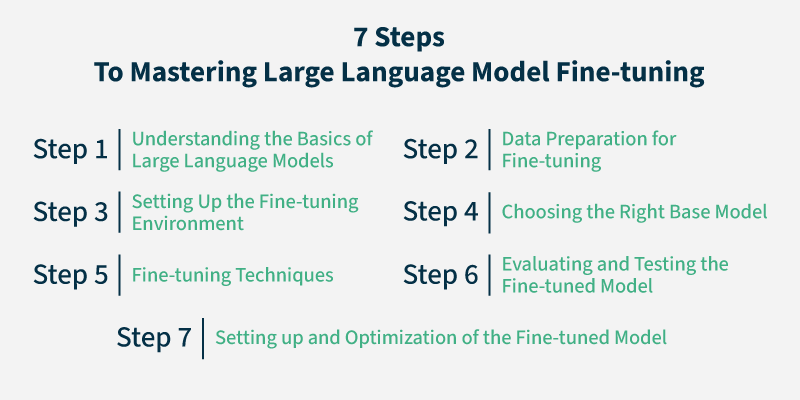
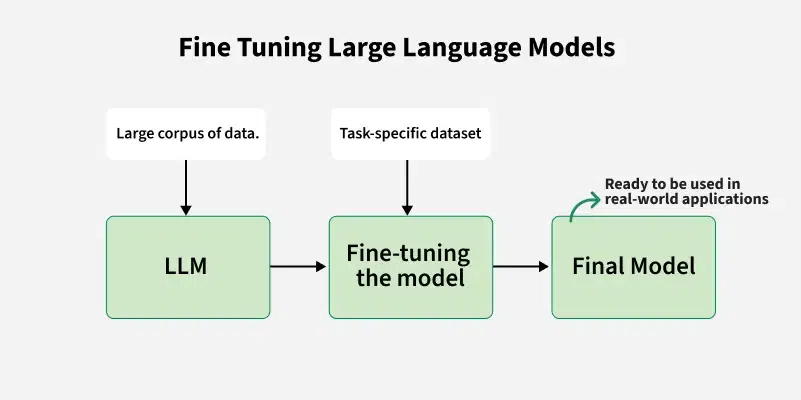
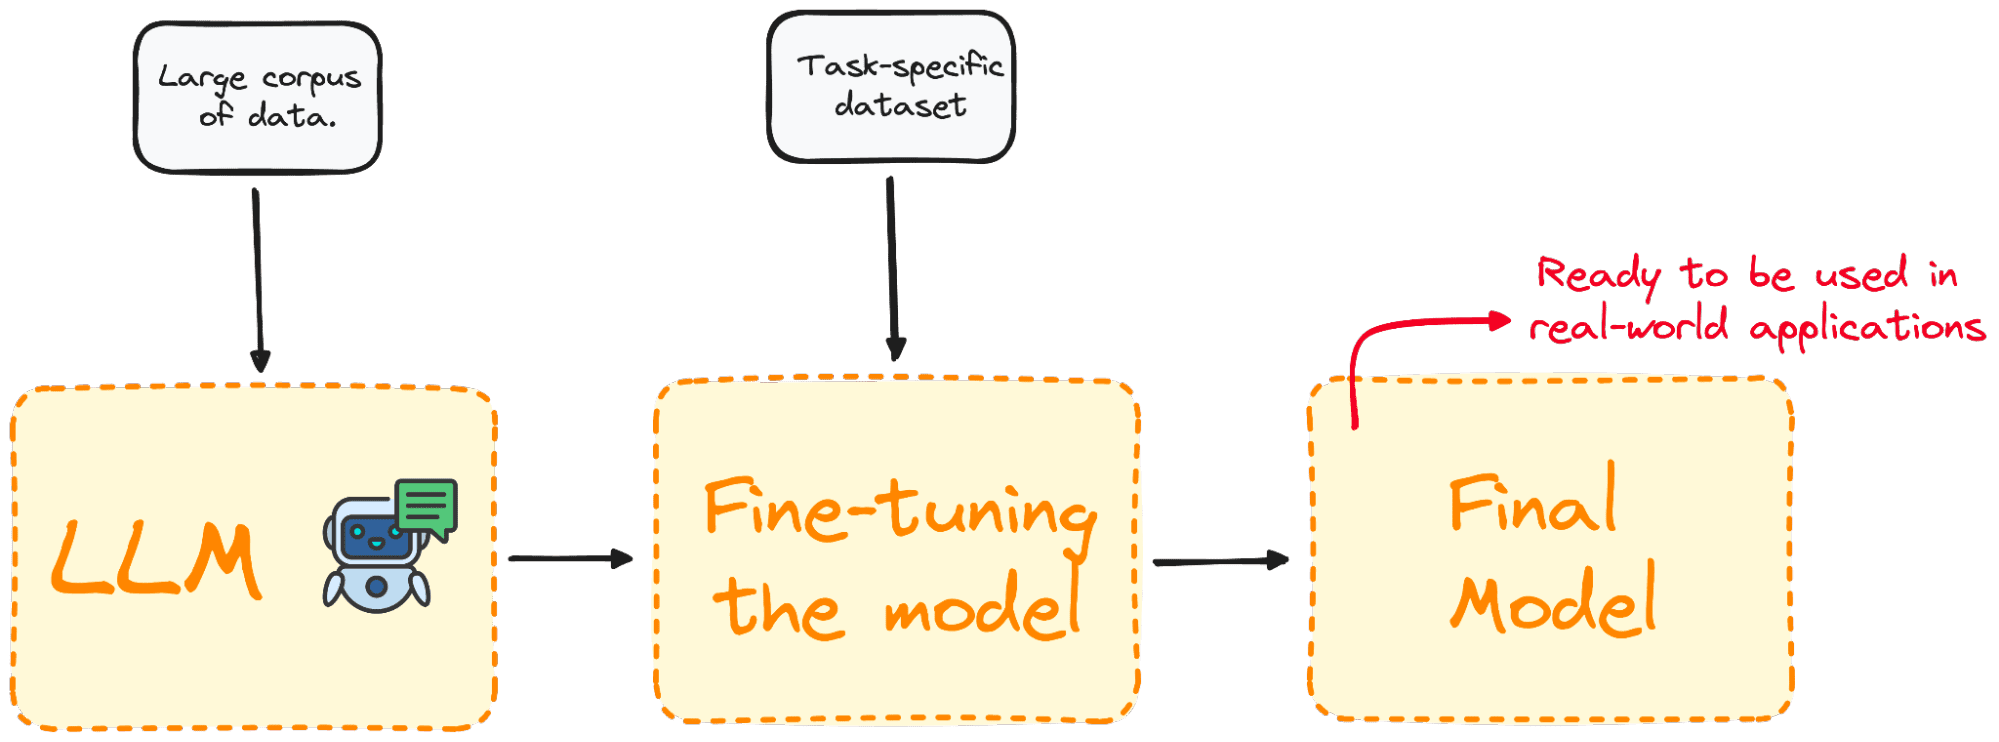
The process starts with a base model and a dataset tailored to your specific need. You pick a model like Llama 3.1 8B or Qwen 2.5 7B depending on your GPU budget, then format your data into instruction-response pairs. The actual training uses a framework like Unsloth or Axolotl, which handles the LoRA adapters and gradient checkpointing so you are not manually managing CUDA memory across layers. The first step most people skip is dataset curation. A well-curated dataset of 500 examples beats a messy dataset of 50,000 every time. I found this out the hard way when I tried to train on a publicly available instruction dataset and the model started generating perfectly formatted but completely irrelevant answers. The problem was domain mismatch, not quantity. I ended up writing 420 custom examples by hand and the results improved immediately.
What Actually Happens During Training
LoRA fine-tuning works by freezing the base model weights and injecting low-rank matrices into the attention layers. Instead of updating trillions of parameters, you are only tuning a small fraction of them. This is why you can fine-tune an 8B model on a single RTX 4090 in most cases. The adapters get saved as separate files, which you then merge back into the base model using a conversion script when training finishes. The typical hyperparameter setup I use is a learning rate around 2e-4, LoRA rank of 64, alpha of 128, and about 3 to 5 epochs. Going beyond 5 epochs on a small dataset is almost always overfitting. I learned this when my validation loss started climbing on epoch 6 while the training loss kept dropping. The model was memorizing, not learning.
A Problem I Encountered That No One Writes About
During one project, the fine-tuned model would generate correct answers in the chat format but completely broke when I switched to batch inference. The outputs came back as raw JSON with no response field, just a string of tokens that looked like the start of a completion task rather than a chat completion. It took me four hours to realize the issue was in how I was constructing the conversation template. The fine-tuning process had learned the <|start_header_id|>user<|end_header_id|> format because that is what I used in training, but my inference code was sending prompts in plain text without the proper message structure. The fix was straightforward, but it was not obvious because the model was not failing. It was producing technically valid output, just not the format my application expected. Always validate inference with the exact prompt structure your production system will use before declaring a model ready. Unsloth at github.com/unslothai/unsloth gives you roughly 2x training speed and 60 percent less memory usage compared to standard HuggingFace training. It is worth the hour of setup time. Axolotl at github.com/axolotl-ai-cloud/axolotl provides a YAML-based configuration system that is much easier to version control and reproduce than writing training scripts from scratch. I recommend Axolotl if you plan to experiment with different dataset configurations frequently. For the base models themselves, Hugging Face is the standard source. Llama 3.1 8B Instruct is a solid default choice. Qwen 2.5 7B Instruct tends to follow instructions more closely out of the box. Both support LoRA fine-tuning well and have active communities around them.
Get the Full Details
When Fine-Tuning Is the Wrong Choice
There are situations where fine-tuning adds more problems than it solves. If your task is primarily about retrieving specific information from a knowledge base, RAG with a good embedding model will outperform a fine-tuned model at a fraction of the cost and with zero training time. Fine-tuning cannot teach a model facts it does not already know the capacity to learn. If your answers require real-time data or internal documents, you need retrieval, not fine-tuning. Another case where fine-tuning is wasteful is when your desired behavior is already close to what the base model does. I once fine-tuned a model to be more concise in its responses and spent two days on the training process, only to find that a simple system prompt telling it to be concise produced the same result. You should always test a strong prompt first. Fine-tuning should be your second option, not your first.
Pitfalls That Waste Days
Data leakage is the most common technical mistake. If your training and test examples share structure or content, the model will appear to perform well during evaluation but fail in production. I caught this once by checking whether my test set had examples with the same entity names appearing in the training set. They did, and removing them dropped my reported accuracy by about 12 percent, which turned out to be a more honest number. Another issue is mixing instruction formats during training. If some examples use "Question: ... Answer: ..." and others use a chat template with roles, the model learns to expect inconsistency and its behavior becomes unpredictable. Keep your formatting uniform across the entire dataset. Finally, be aware that LoRA adapters have a limited capacity. You cannot effectively fine-tune a model to do something fundamentally outside its base capability. Asking a small model to perform complex mathematical reasoning through fine-tuning alone usually fails because the base model simply does not have the underlying reasoning pathway built into its weights. In those cases, moving to a larger base model is the actual solution, not more training data.