Understanding What You're Actually Working With
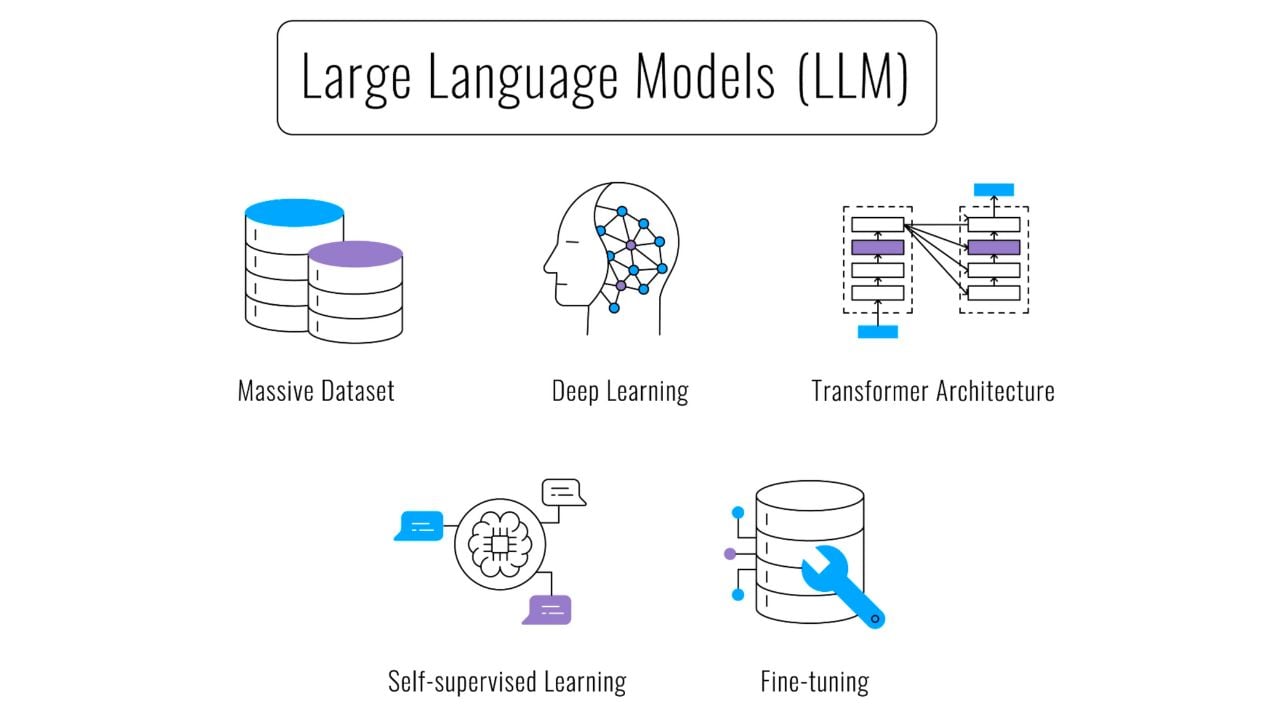
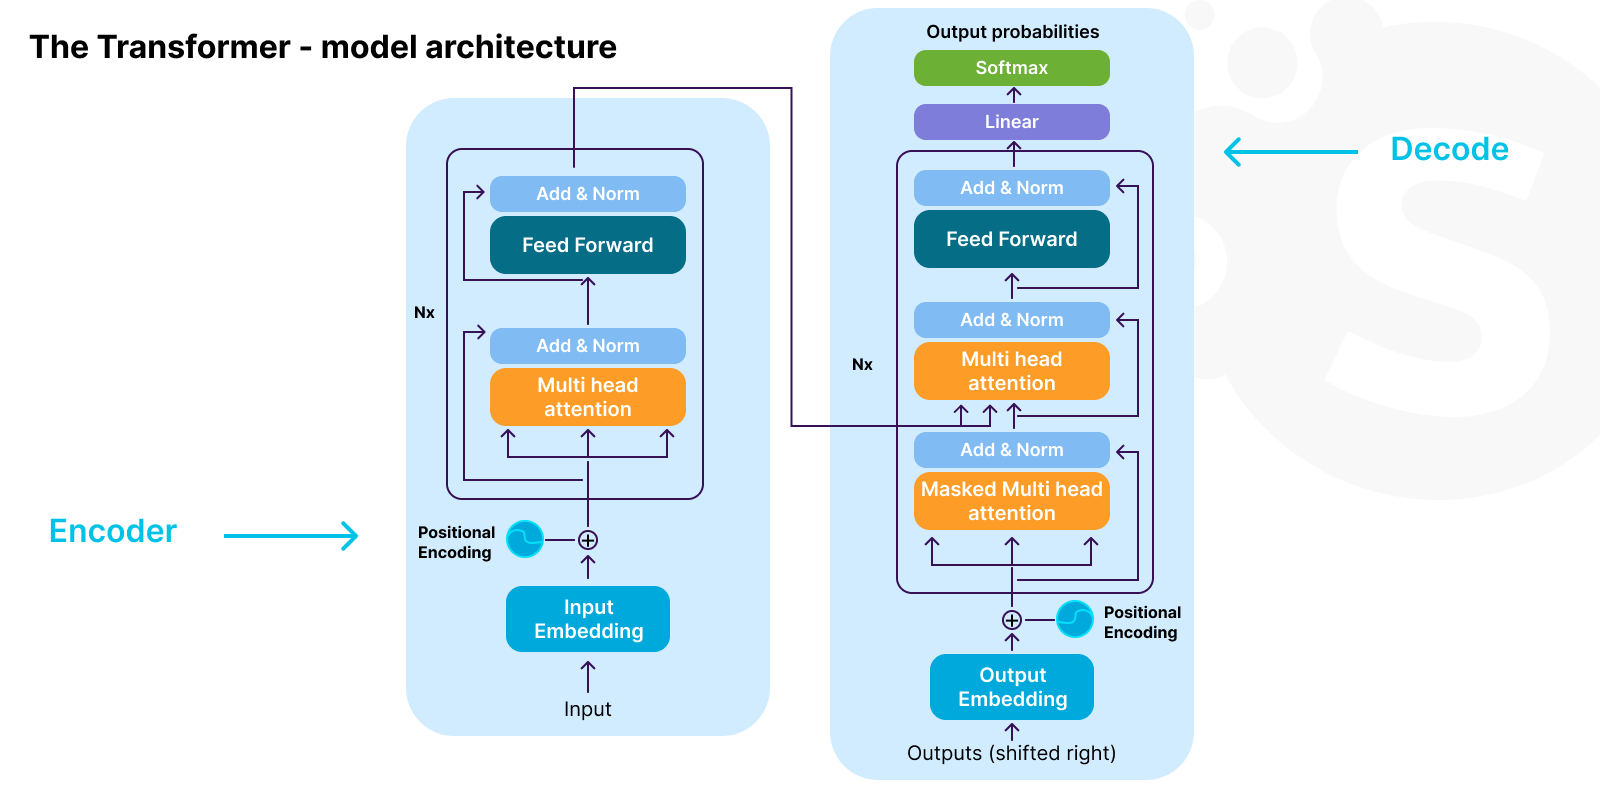
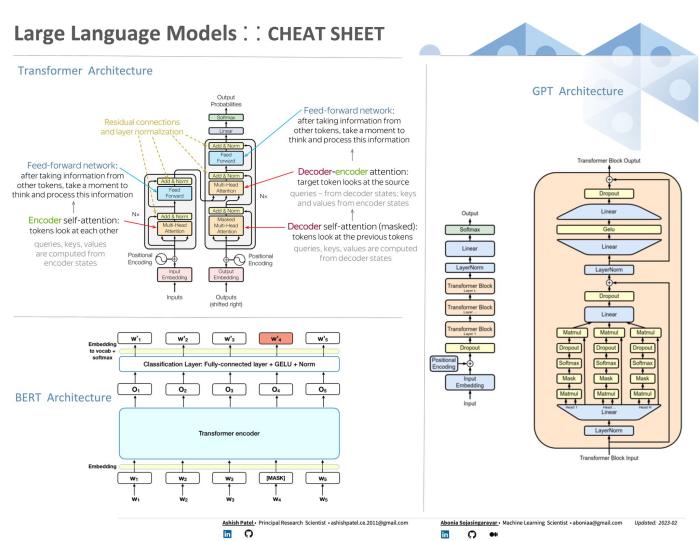
A large language model is a neural network trained to predict the next token in a sequence. That's the entire mechanism. Everything you see in practice — chat interfaces, API responses, code generation — comes from that same repeating pattern. The architecture behind most modern systems is the transformer, introduced in 2017, which replaced earlier recurrent approaches because it handles long-range dependencies without degrading over sequence length. The training process involves feeding trillions of tokens through billions or trillions of parameters, optimizing a cross-entropy loss function. After pretraining, models are typically aligned with human preferences using techniques like RLHF or DPO. That second stage is where models stop sounding like Wikipedia summaries and start sounding like assistants. The first thing people get wrong is assuming they need to fine-tune a model to do anything useful. In my experience, properly prompting a base model outperforms a poorly configured fine-tune every time. Start with something like Llama 3.1 8B or Mistral 7B. These are small enough to run on consumer hardware but capable enough for real work. Download weights from Hugging Face, then use an inference framework. Ollama is the simplest entry point — it handles quantization, KV cache management, and GPU offloading automatically. Run ollama pull llama3.1 and you'll have a local model serving requests within minutes. For more control, use llama.cpp or vLLM. llama.cpp runs efficiently on CPU with GGUF quantized weights. vLLM excels at high-throughput serving with continuous batching and PagedAttention. I switched from vLLM back to llama.cpp for a project generating structured JSON at scale because vLLM's overhead became noticeable when handling thousands of small concurrent requests rather than a few large ones. That was the tradeoff: throughput versus latency per request.
If you want to fine-tune instead of just prompt, LoRA adapters are the standard approach. They freeze the base model weights and train a small set of low-rank matrices. A typical LoRA fine-tune on a dataset of 500 examples takes about 2 hours on an RTX 4090. The full SFT process using tools like Axolotl or tatsu-lab/stanford-alpaca involves preparing your data in instruction format, launching the training script, and then merging the adapter back into the base model for inference. Don't skip the merge step. Running the adapter separately works but introduces latency and complicates deployment. The prompt format matters more than most tutorials acknowledge. Different models expect different chat templates. Llama 3 uses special tokens like
Common Pitfalls and What Actually Breaks
I ran into a specific issue last year that took me about three days to diagnose. I was building a pipeline that fed LLM outputs into a SQL query generator. The model kept generating queries with column names that existed in the schema documentation but not in the actual database. The training data for the model contained a slightly different schema version from six months prior. Standard fine-tuning on a newer schema snapshot didn't fully correct this because the base model's pretrained weights still carried strong priors from the older data. What actually fixed it was a combination of retrieval-augmented generation — injecting the live schema into each prompt — and a post-processing validation step that checked every column reference against a cached schema dictionary before execution. The RAG component alone reduced hallucinated column names from roughly 18% of queries down to under 3%. Another issue that rarely gets mentioned is context window exhaustion under load. When you chain multiple LLM calls together, the accumulated context grows linearly. A typical conversation with tool use and previous turn history can easily consume 80% of a 32K context window within five exchanges. The model's attention mechanism doesn't degrade gracefully in these situations — performance drops abruptly once you hit the limit, and tokens get truncated mid-sentence. The workaround is aggressive summarization between turns. Compress the conversation history into a bullet-point summary every three exchanges using a smaller model, then feed that summary along with the latest prompt. This keeps context usage under 40% and maintains response quality. Quantization is another area where people make assumptions that don't hold up. The common 4-bit quantizations like Q4_K_M preserve most capability, but certain tasks degrade faster than others. Code generation suffers more than conversational dialogue. I benchmarked a Q4 quantized Llama 3.1 70B against its BF16 counterpart on a code completion task and saw a 12-point drop in pass@1 score. The same model showed only a 3-point drop on general reasoning benchmarks. If your use case is code-heavy, stick to Q5 or Q6 quantization, or run the heaviest models in full precision on cloud infrastructure.
Get the Full Details
When LLMs Simply Won't Work
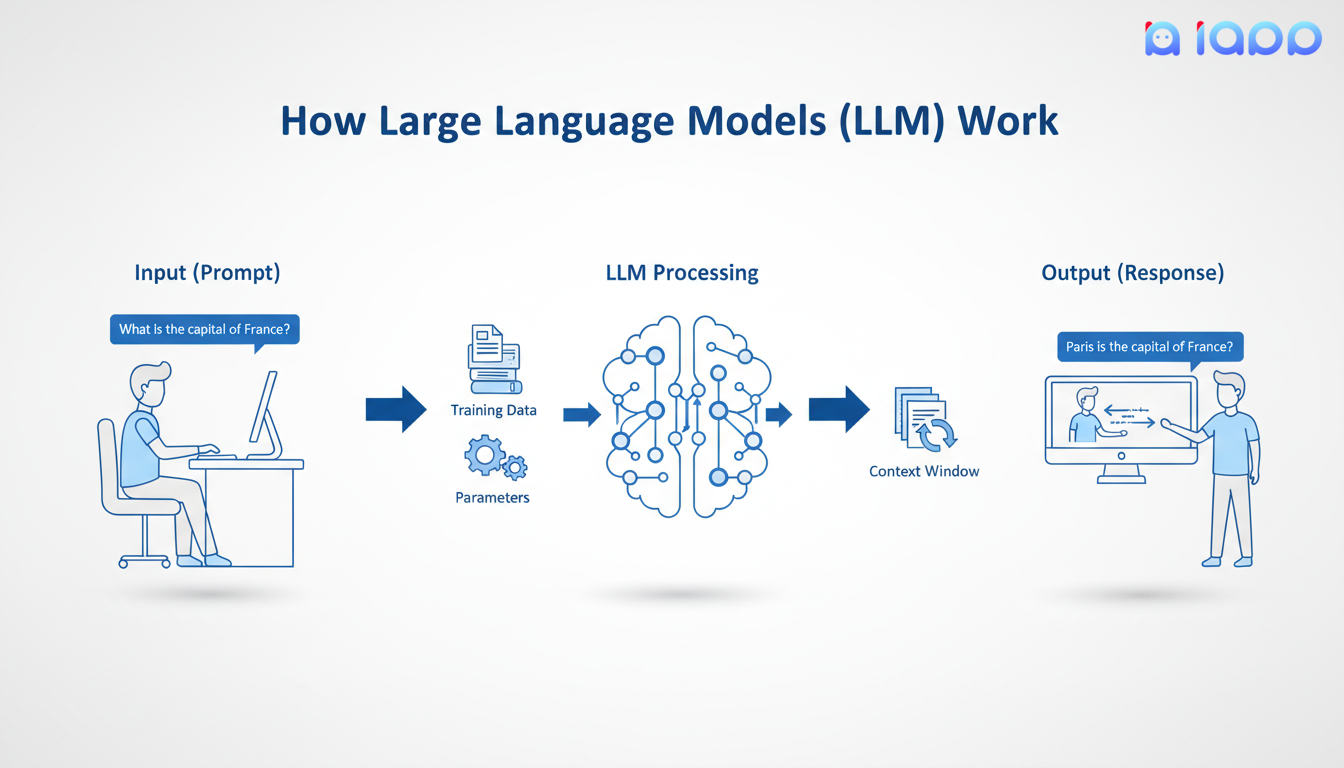
Here's what nobody tells you upfront: LLMs are unreliable for anything requiring precise numerical reasoning, strict logical constraints, or deterministic output. They generate text, not verified computations. If you need exact calculations, use a code interpreter or calculator alongside the model, not inside it. The model can write the code, but it shouldn't be trusted to execute or verify the math. Latency is another hard constraint. Even the fastest inference setups add 200 to 800 milliseconds of overhead per token. A 500-token response takes roughly 3 to 5 seconds on good hardware. That's unacceptable for real-time applications like live customer support where response time under 1 second matters. In those cases, a rule-based system or a small fine-tuned model on edge hardware is more appropriate. LLMs excel at tasks where accuracy tolerates some fuzziness and the value comes from language comprehension, not precision. The cost structure is also misleading. API pricing looks cheap per million tokens until you factor in the actual token count of your application. A modest productivity tool that generates 2,000 tokens per user request will hit thousands of dollars monthly at scale. Running locally eliminates API costs but requires upfront hardware investment and ongoing maintenance. There's no free option here, only different kinds of expense.
Where to Actually Start
If you're approaching this from scratch, install Ollama and work through the default models first. Prompt them, observe their failure modes, then experiment with temperature and top_p settings. Lower temperature (0.2 to 0.5) reduces randomness and produces more consistent outputs for structured tasks. Higher temperature (0.7 to 1.0) helps with creative generation but increases hallucination risk. Then move to API-based models like GPT-4o or Claude for comparison. Notice the differences in reasoning style and instruction following before investing in local deployment. Understanding what each model does well before committing to an architecture saves weeks of trial and error.