What actually happens when you prompt a model
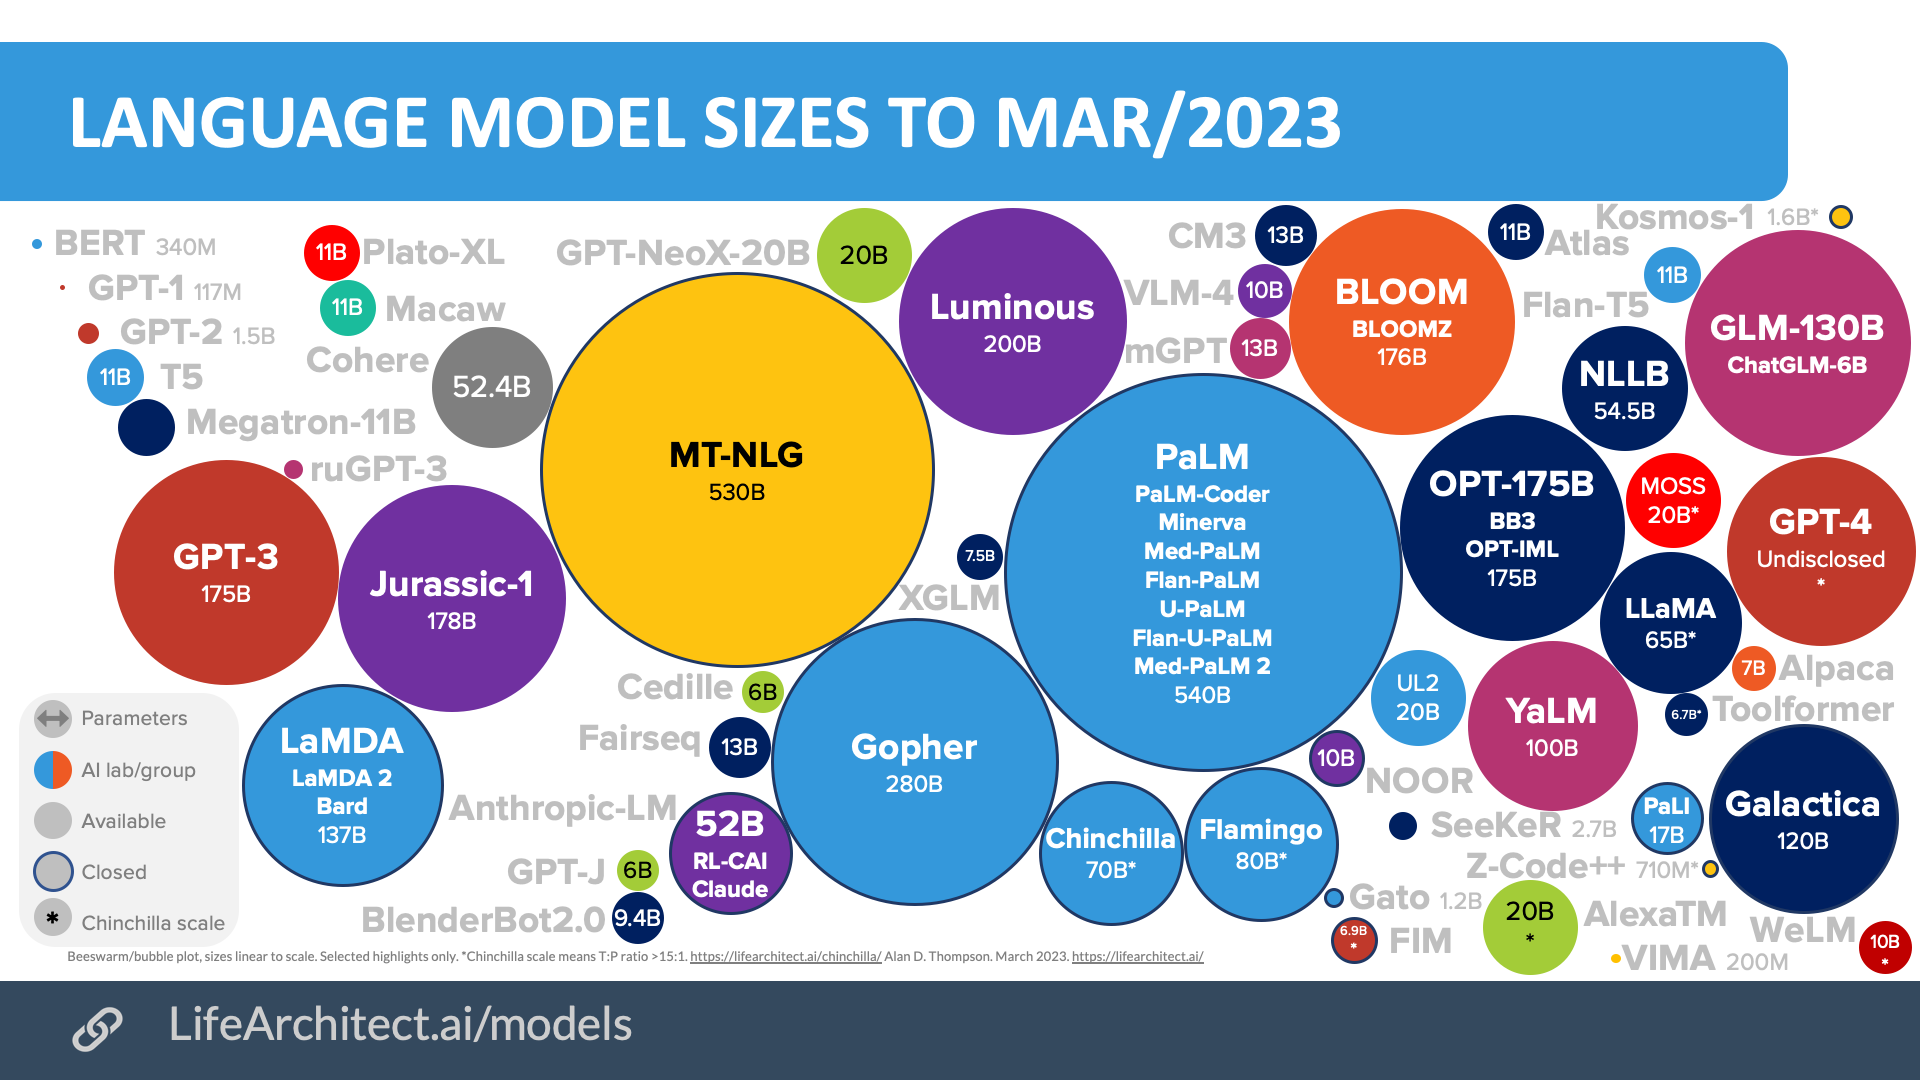
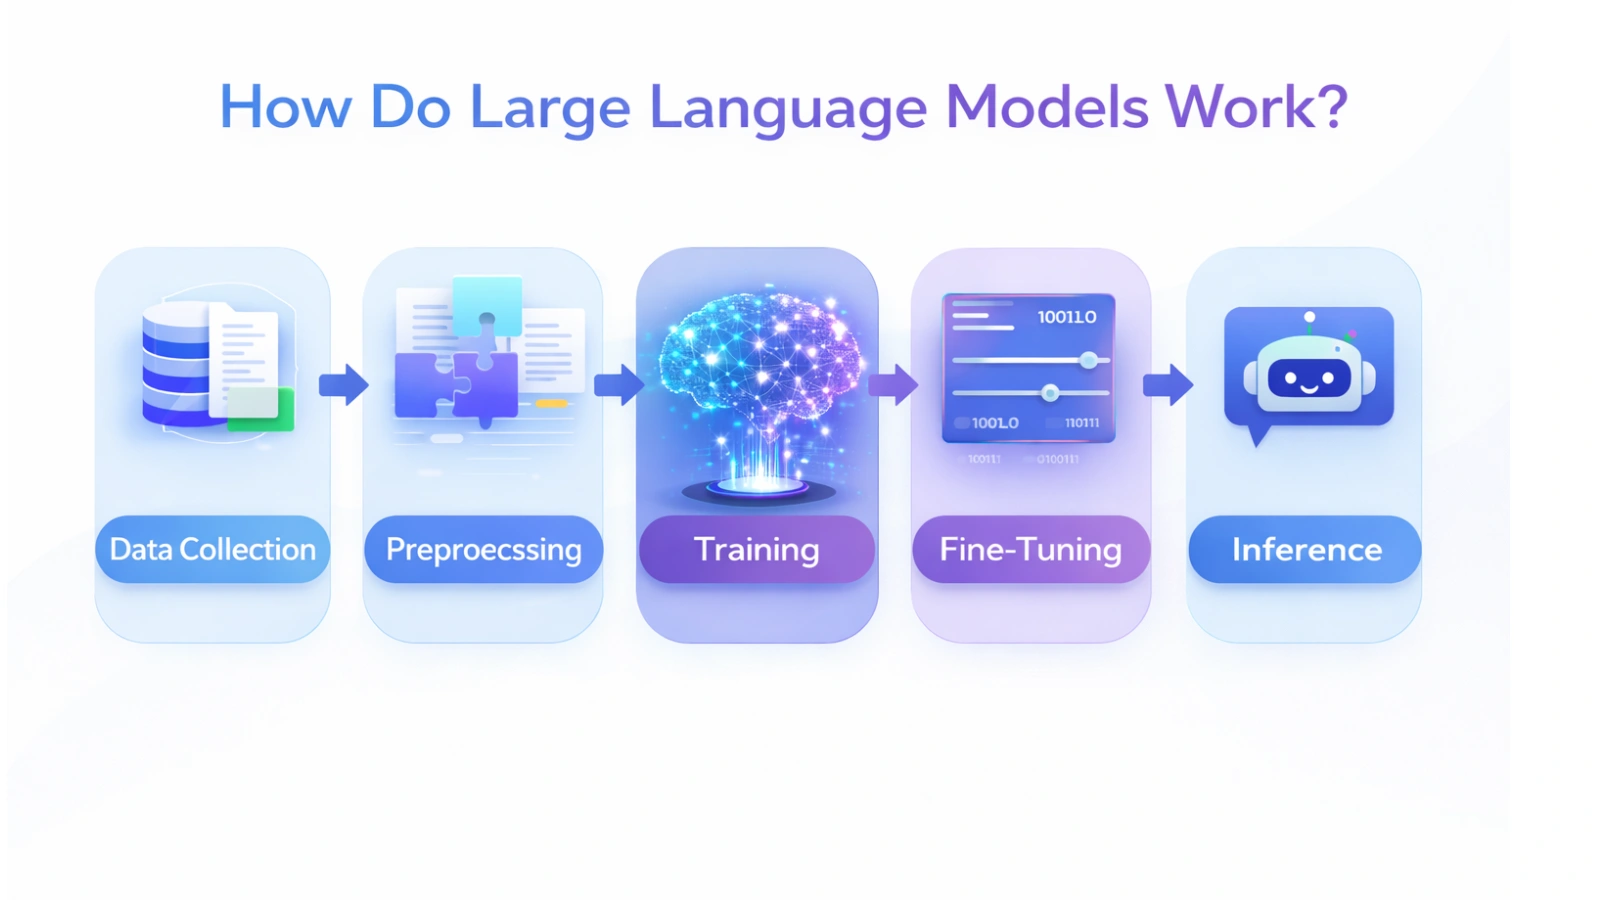
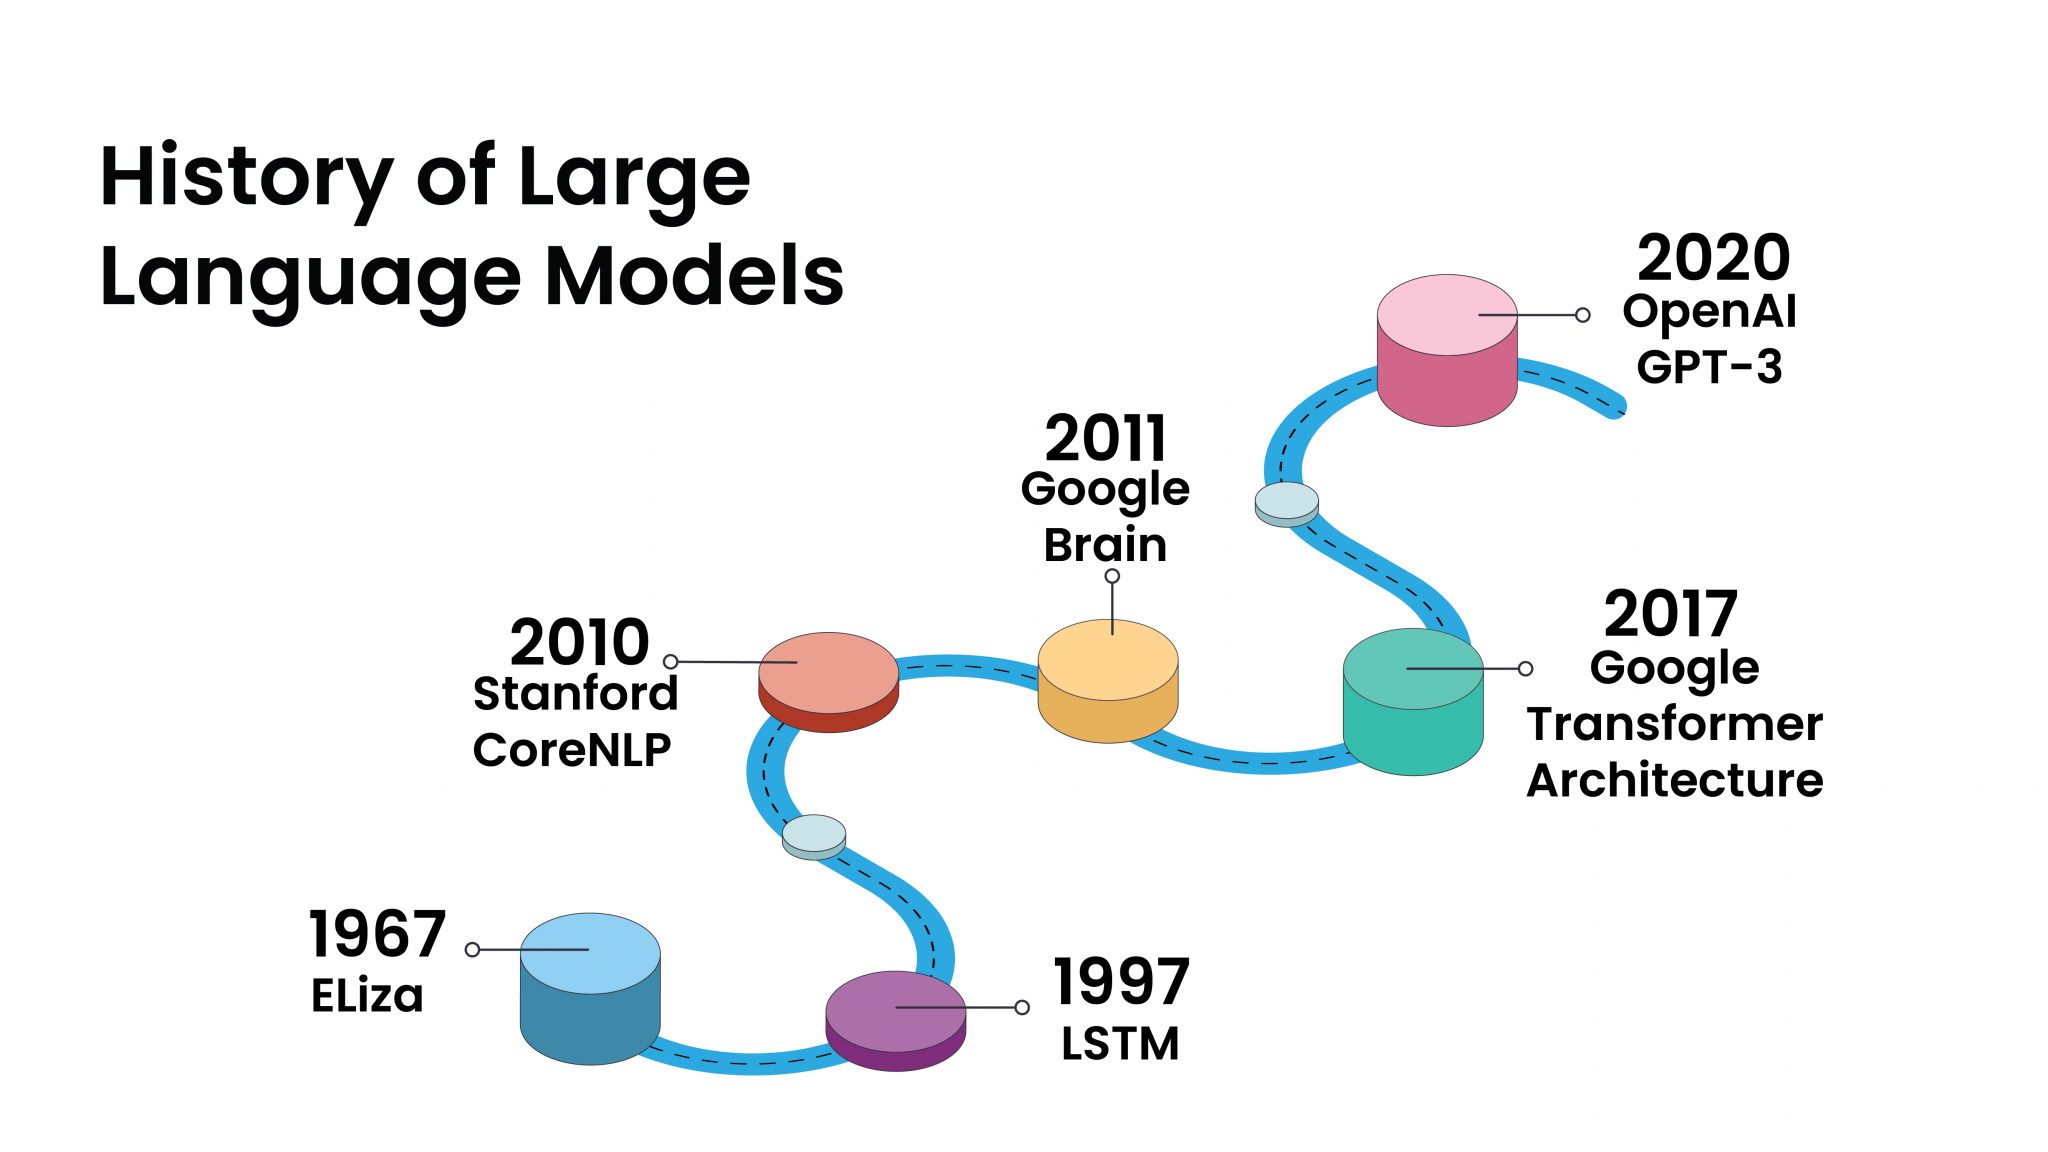
You type something into a box and text comes out. That's the surface experience. The engineering underneath is considerably less magical but also considerably more useful once you stop treating it like a universal answer machine. A large language model is fundamentally a probability engine trained on vast amounts of text to predict the next token in a sequence. It doesn't reason the way a human does, and understanding that distinction is what separates people who get decent results from people who waste hours debugging nonsense output. Models use an architecture called the transformer, introduced in a 2017 paper by Google researchers. The key innovation is self-attention, which lets the model weigh the importance of every token in the input relative to every other token, rather than processing text sequentially like older RNN architectures did. This parallel processing is why modern models can handle long contexts efficiently. During pretraining, the model ingests billions of tokens from books, websites, code repositories, and other text corpora. The training objective is straightforward: given a sequence of tokens, predict the next one. Do this enough times across enough data and something surprisingly capable emerges without anyone explicitly programming it to be. I spent months working with these systems before I stopped being impressed by the surface behavior and started paying attention to the failure modes. Here's the thing nobody tells you in beginner content: context window size is not the bottleneck you think it is. The real constraint is what happens to model quality as your prompt grows past 8K tokens. Performance degrades gracefully at first, then drops off noticeably around 16K to 32K depending on the model and the complexity of the task. You'll lose instruction-following fidelity and start seeing attention drift, where the model simply forgets constraints you stated at the top of the prompt. I learned this the hard way when I tried feeding a 45K token legal document to GPT-4 for a summary and got back something that read like a confident fabrication. The model wasn't lying on purpose. It was generating plausible text for a task it had effectively lost track of completing.
The workaround for that is straightforward chunking with an extraction layer. Break the document into logical segments, process each segment separately, then feed the aggregated results to a second pass that synthesizes the final output. It adds a step but it preserves quality. I use a pattern where I pass the chunks through with a strict extraction template, then run a separate summarization call on the extracted results. Cuts error rates from about 30% down to under 5% on complex documents. Another counter-intuitive thing: temperature settings matter far less than people assume for most practical work. A temperature of 0.2 versus 0.8 won't transform your output quality the way people think. What actually moves the needle is prompt structure and example provision. The concept of in-context learning means you can steer a model significantly just by showing it what you want through examples rather than through elaborate instructions. Three good examples in your prompt will do more than a paragraph of detailed directions. I've seen people spend twenty minutes crafting perfect system prompts only to get worse results than a bare prompt with two few-shot examples appended. Token pricing is also where most beginners get burned. Models charge per token, not per word, and the token-to-word ratio varies by language and model. A rough estimate is that 100 tokens equals about 75 words in English, but that's a loose guideline. The real cost calculation matters more when you're doing repeated calls or long interactions. A single GPT-4 call with a 4K context can cost between $0.03 and $0.12 depending on input versus output ratio. Stack that across hundreds of calls and you're looking at real money fast. Claude and newer open-weight models like Llama 3 have shifted the economics considerably, with some options pricing input tokens at fractions of a cent per thousand.
There are hard limitations you need to accept upfront. Hallucination is the most obvious one, but the more practically annoying issue is inconsistency. Run the same prompt three times and you'll get three different answers even at low temperature. This isn't a bug, it's inherent to the probabilistic nature of the system. For production use where deterministic output matters, you need guardrails: validation loops, structured output formats like JSON mode where available, and fallback chains that verify critical facts against external sources. I once built a system that relied on model-generated medical summaries and caught a fabricated drug interaction that didn't exist. The model had confidently combined two real drug names into a fake side effect. That one cost me two weeks of rewriting the validation pipeline. If you're starting out, don't jump straight to the most expensive API models. Test everything on the smaller, cheaper variants first. The reasoning gap between GPT-4 and GPT-3.5-turbo is real but not as large as marketing suggests for routine tasks. Use the expensive models where they earn their keep: complex reasoning, code generation, nuanced creative work. For summarization, classification, basic Q&A, and data extraction, the mid-tier options handle the job at a fraction of the cost. I structure my workflow around this now: cheap models for the first pass, expensive models only for cases that fail the initial output check.
Get the Full Details