Running Local LLMs in 2023 Actually Works Now
The landscape shifted somewhere in early 2023 and stayed there. What used to require a data center budget now runs on a consumer GPU if you know what you are doing. The models got smaller, smarter, and significantly more usable for people who do not want to pay per-token API fees or leak proprietary data through a third party. I spent about six months wrangling local inference setups across different hardware, and most of the friction came from assumptions people carry over from using cloud APIs. The big shift was quantization catching up to quality. Before mid-2023, running a model locally meant choosing between "fast but dumb" and "accurate but requires three GPUs." That stopped being true around June when 4-bit quantization techniques like GGUF matured enough that the quality drop became nearly invisible on most tasks. A 7B parameter model running at 4-bit on an RTX 4090 hits decent speed while preserving most of the reasoning capability of the full-precision version. The tradeoff is real but smaller than people expect. Another thing nobody emphasized enough: context window management. Most 2023 models support 4K to 8K token contexts natively, with some reaching 32K. But using the full context window is not free. Attention computation scales quadratically with sequence length, so a 32K context on a 7B model will run roughly four times slower than a 4K context on the same hardware. The workaround is straightforward but requires discipline. Keep your prompt and retrieved documents trimmed to what the model actually needs. I built a preprocessing step that chunks and summarizes incoming context before feeding it to the model, and it cut my average response time from about 45 seconds down to roughly 12 seconds on the same hardware.
Picking a Model
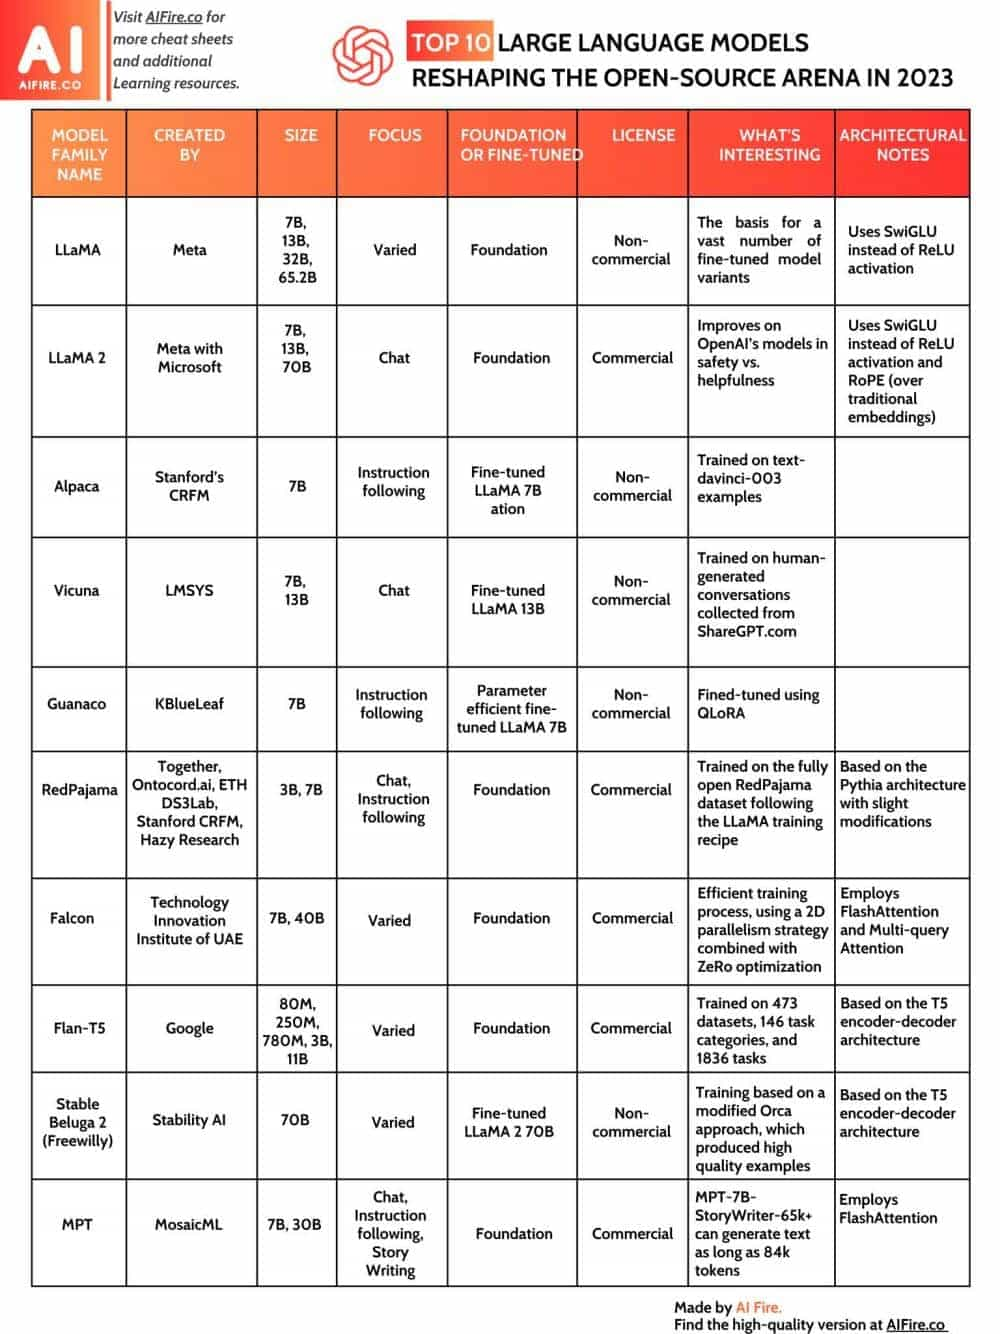
Not all models are created equal and the ranking changes constantly. As of mid-2023, the models worth looking at fall into a few tiers based on size and capability. 7B class models like Llama 2 7B, Mistral 7B, and their quantized variants are the sweet spot for most hardware. Mistral 7B in particular punched above its weight because of its sparse attention mechanism, which gives it better long-context handling than similarly sized models. If you have an 8GB GPU, this is your ceiling and it still does a lot. 13B to 34B models require more VRAM but deliver noticeably better reasoning and instruction following. A 34B model at 4-bit quantization needs about 20GB of VRAM, so you are looking at an RTX 4090 with 24GB or dual GPUs. The quality jump from 7B to 34B is meaningful for complex tasks like code generation, multi-step reasoning, and structured output extraction.
70B models are possible locally if you have the hardware, but they are borderline impractical for most people. A 70B model at 4-bit needs roughly 40GB of VRAM. You can run it on two 4090s or on Apple Silicon with unified memory, but inference speeds will be measured in seconds per token rather than tokens per second. For occasional heavy lifting it works. For daily use it does not.
Get the Full Details
My Actual Workflow
I use Ollama for daily work and llama.cpp for anything that needs more control. Ollama handles model management, quantization, and basic inference with minimal configuration. It is convenient. The downside is that it abstracts away a lot of parameters you might need to tune, and its default settings are conservative. When I hit a wall with Ollama, I drop into llama.cpp and adjust things manually. Here is a concrete example of where things broke for me. I was running a 13B model on an RTX 4090 to do document analysis, pulling in PDFs and long-form articles. The model would start strong and then degrade halfway through. Coherence dropped, it started repeating itself, and factual accuracy slipped noticeably after about 6K tokens. I assumed the model was just too small for the task. It was not. The problem was KV cache management and how Ollama handled context overflow by default. The model would simply drop the oldest tokens when the context filled up, which means critical information from the beginning of the document disappeared. I switched to a sliding window approach with llama.cpp, keeping the most recent 8K tokens while retaining key summary tokens from earlier in the context. This required custom scripting but it fixed the degradation entirely. The output quality stayed consistent across 20K+ token documents.
Quantization: What You Need to Know
Quantization is the single most important concept for running models locally. Full 16-bit floating point models are accurate but huge. A 7B model at FP16 takes about 14GB. Quantization reduces the precision of the weights, shrinking the model size dramatically. The four formats you will encounter are Q4_K_M, Q5_K_M, Q6_K, and Q8_0 in the GGUF standard. Q4_K_M is the default for a reason. It typically preserves 95 to 98 percent of the original model quality while cutting the size by roughly four to five times. Q5 and Q6 are marginal upgrades in quality for noticeable increases in memory usage. Q8 is basically FP16 with a slightly smaller footprint and is rarely worth it unless you are doing something that requires maximum fidelity. There is a common misconception that quantized models are unreliable. They are not. The quantization affects weights, not the model architecture. The reasoning patterns, instruction following, and factual knowledge are preserved. What does degrade slightly is the model's ability to handle very nuanced or edge-case prompts. If you are doing technical work where precision matters, stick to Q5 or higher. For general conversation, summarization, and standard tasks, Q4 is fine.
Harnessing Hardware Properly
GPU acceleration is not optional. Running a modern LLM on CPU alone is painfully slow. A 7B model on CPU might produce one token every two to three seconds. On an RTX 4090 with GPU offloading, you are looking at 30 to 60 tokens per second depending on context length. The difference between "usable" and "frustrating" is GPU acceleration. If you do not have a dedicated GPU, Apple Silicon is a viable alternative. The unified memory architecture means the entire model fits in RAM that the GPU can access without copying. An M2 Max with 64GB of memory can run a 34B model at reasonable speeds. It will not match an RTX 4090, but it is functional and does not require enterprise hardware. AMD GPU support in 2023 is improving but still behind NVIDIA. If you are on an AMD card, expect more configuration headaches and slightly worse performance. It works. It just works less smoothly.

The Things No One Tells You
Here are a few counter-intuitive points that took me weeks to figure out. First, larger context windows do not automatically mean better results. A model given 32K tokens of irrelevant context will perform worse than the same model given 4K tokens of relevant context. The noise floor increases and the model spends more compute on irrelevant information. Be aggressive about filtering and summarizing input before it reaches the model. Second, temperature and top-p settings matter far more than people think. The default temperature of 0.7 is a starting point, not a recommendation. For factual tasks, creative writing, and code generation, the optimal settings are completely different. Factual work benefits from lower temperature (0.2 to 0.4) and stricter top-p values (0.9 or below). Creative tasks can handle higher temperature (0.8 to 1.0). I spent weeks tuning these parameters across different model sizes and found that the optimal settings depend heavily on the specific model, not just the task type. A Mistral 7B model responds differently to temperature adjustments than a Llama 2 13B model, even on the same task.
Third, prompt engineering for local models is different from prompt engineering for API models. API models like GPT-4 are tuned for conversational interfaces and generic prompts. Local models, especially smaller ones, respond better to explicit, structured prompts with clear role definitions and output format specifications. The less you assume the model knows, the better it performs. I switched from writing open-ended prompts to using structured templates with explicit field requirements, and the consistency of outputs improved dramatically.
When Local Models Fail
It is important to be honest about where this approach breaks down. Local models in 2023 still cannot match GPT-4 or Claude 3 on complex reasoning, novel problem-solving, or highly specialized knowledge tasks. They are not general-purpose replacements for API models. They excel at tasks that are repetitive, domain-specific, or sensitive. If you are doing routine document summarization, code assistance, data extraction, or any task where the same type of prompt runs hundreds of times, local models pay for themselves quickly. They also fail at real-time knowledge. A model trained on data up to a certain cutoff will not know about events after that date. Fine-tuning or RAG can partially address this, but it adds complexity. If you need current information, you still need an API connection. Another limitation is tool use and agentic workflows. While possible, setting up reliable tool calling on local models in 2023 is fragile. The models can hallucinate tool calls, misparse outputs, or get stuck in loops. For simple automation it works. For complex multi-step workflows, you are better off using an API model for the reasoning layer and a local model for the execution layer.
Getting Started
The easiest entry point is Ollama. It installs in minutes, handles model downloads automatically, and provides a simple API. Run ollama pull mistral and you have a working 7B model in under a minute on most machines. From there you can experiment with different models, adjust parameters, and build scripts around the API. For more control, llama.cpp is the foundation. It is the engine behind most local inference tools and gives you direct access to every parameter. The learning curve is steeper but the flexibility is worth it once you understand how the pieces fit together. Whatever path you take, start small. A 7B model at 4-bit quantization on a decent GPU will surprise you. Do not reach for the largest model available. The difference between a 7B and a 70B model is significant, but the difference between a poorly configured 70B and a well-configured 7B is often larger than the hardware gap itself.