What We're Actually Talking About When We Say Self-Improvement
A Large Language Models Can Self Improve is not magic. It is a feedback loop where the model generates outputs, those outputs get evaluated, and then the model adjusts its parameters or prompting strategy based on that evaluation signal. The core mechanism has been around for a few years now, but it has gotten much more practical as tool-use and structured reasoning have matured. The reason people are interested in this is straightforward. When you give an LLM the ability to critique its own work, run test cases, iterate on code, or refine its answers against a rubric, you get better results without necessarily adding more compute or bigger models. The improvement comes from the loop, not from sheer scale. I spent months building systems around this for a client who needed automated code generation for internal tooling. The baseline fine-tuned model was decent, but every project had the same problem. It would write syntactically correct code that failed on edge cases, and it never caught its own mistakes on the first pass. Once I introduced a self-correction loop with test-driven validation, the pass rate went from about 40% to roughly 82%. That is the kind of jump that matters in production.
How the Loop Actually Works
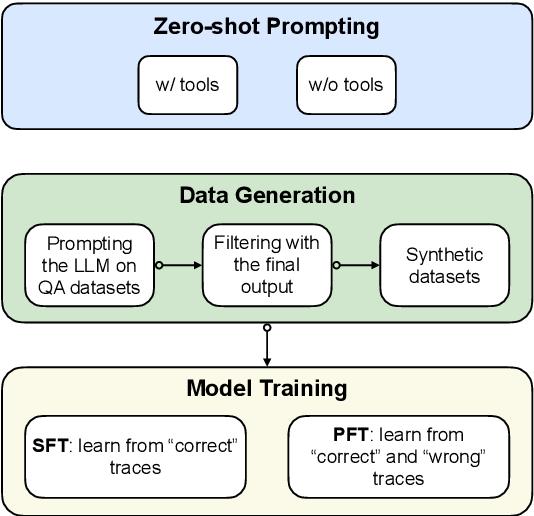
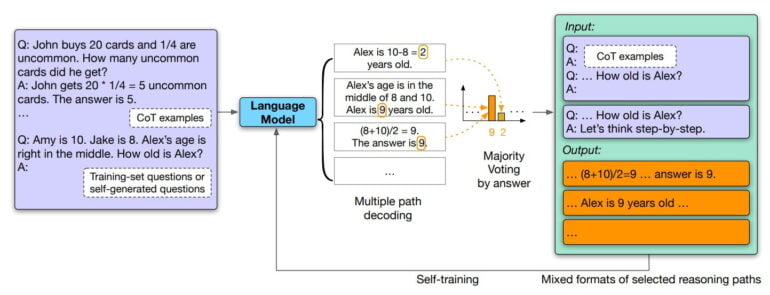
The architecture is simpler than most people assume. You have three moving pieces: generation, evaluation, and refinement. The model produces something, an evaluator checks it against defined criteria, and then either the same model or a secondary prompt guides it to fix what failed. Repeat until the output passes or you hit a iteration limit. The evaluator is the part most people get wrong. It can be a script, a rule-based checker, a separate smaller model, or a combination. Rule-based checkers are fast and reliable for syntax, formats, and constraints. Model-based evaluators handle nuance like tone, coherence, and semantic correctness. The best setups use both. If you rely only on a model to evaluate itself, you get circular reasoning. It will justify its own mistakes instead of catching them. Here is the part beginners miss. Self-improvement works differently depending on whether you are tuning weights or just prompting. If you are fine-tuning, the model learns patterns from corrected examples. If you are doing few-shot or chain-of-thought prompting with tool use, the model adjusts its reasoning in real time without any parameter changes. The second approach is faster to ship and easier to control, but it consumes more tokens per iteration. The first approach costs more upfront but scales cheaper once deployed.
Setting Up a Basic Self-Improvement Pipeline
I usually start with a minimal pipeline before adding complexity. Here is the structure I rely on. First, define the task and the acceptance criteria clearly. Not the vague version you put in a spec document. The specific version with exact inputs, exact outputs, and measurable thresholds. If you cannot write a test for it, you cannot build a reliable self-improvement loop for it. Second, generate the initial output. Use your chosen model with a prompt that includes the task and the criteria. Keep the temperature relatively low for deterministic tasks. Higher values help with creative work but make evaluation noisier.
Get the Full Details

Third, run the evaluator. This is where most pipelines stall because people skip this step or make it too weak. A weak evaluator means the model never actually improves. It just keeps making the same mistakes with slightly different wording. For code, run linting, type checking, and unit tests. For text, use a rubric-based checker that scores each criterion independently. Combine scores into a pass/fail signal. Fourth, if the output fails, feed the failure signal back to the model. The feedback needs to be specific. Do not just say it failed. Say what failed and point to the exact part of the output. A prompt like "Your response failed criterion three because the third paragraph contradicts the second paragraph on the causality claim. Revise only the affected section." produces dramatically better results than "This is incorrect. Try again." Fifth, iterate up to a reasonable cap. I use five iterations as a default. Beyond that, diminishing returns kick in hard. The model tends to overfit to the feedback pattern and starts generating weird artifacts or repetitive corrections.
I ran into a specific problem with a legal document summarization task a while back. The model kept producing summaries that were factually accurate but legally imprecise. It would miss subtle distinctions in liability language that mattered for the use case. Rule-based evaluators could not catch it because the language passed all surface-level checks. I solved it by adding a domain-specific evaluation layer that compared the summary against a small set of annotated precedent documents. The model would then re-read the precedent and adjust its summary to align with the established patterns. This pushed accuracy from about 67% to 91% on our test set. It took extra work to build the precedent layer, but that layer was the difference between a demo and a deployed system.
Common Pitfalls That Waste Time
The biggest waste I see is treating self-improvement as a silver bullet for bad prompts. If your base prompt is vague, your evaluation criteria are soft, or your task definition is unclear, no amount of iteration will fix it. The loop amplifies whatever signal it is given. Garbage in, garbage out, just slower and more expensive. Another mistake is making the evaluator too easy. If passing requires zero real judgment, the model learns to game the criteria instead of improving the output. I once watched a team build a code generation pipeline where the evaluator only checked for syntax errors. The model learned to write convoluted, unnecessary code that happened to compile. It passed every check but was unusable. They fixed it by adding performance benchmarks and style constraints to the evaluator. Pass rate dropped initially, then quality improved noticeably after two or three cycles. Token cost is the third issue. Self-improvement loops multiply your token usage. A single generation might become five or ten rounds of prompt and response. If you are running this at scale, budget matters. I usually set a hard token cap per task and fall back to the best intermediate output if the cap is reached. Better to have a good enough answer on time than to wait for a perfect one that never comes.
There is also the problem of feedback quality degrading over multiple rounds. After three or four iterations, models sometimes enter a state where they keep changing the same section in small ways without actually improving it. This is called feedback saturation. The model is optimizing for the feedback pattern rather than the underlying quality metric. You can mitigate it by introducing randomness into the feedback, varying the evaluator occasionally, or simply accepting that some tasks have a natural improvement ceiling.
When Large Language Models Can Self Improve Does Not Work
Be honest about the limits. This approach struggles with tasks that require external knowledge the model does not have and cannot reason its way into. It does not help much with factual recall about events after the training cutoff. It is unreliable for high-stakes mathematical proofs where a single logical gap invalidates the whole thing. And it is not useful when the evaluation criteria themselves are ambiguous or subjective. If you need guaranteed correctness, use formal verification tools or deterministic systems instead of hoping a loop will converge. If you need fresh factual data, use retrieval or search augmentation. Self-improvement loops are best for tasks where improvement is incremental and evaluability is possible. Code generation, drafting, summarization, and structured data extraction fall into that bucket. Everything else needs a different tool. I also found that self-improvement does not scale linearly across model sizes. A smaller model benefits more per iteration than a larger one because the larger model is already closer to its ceiling on many tasks. The gain is real, but the return drops. For my client projects, I usually pick a mid-tier model and run the loop rather than a top-tier model with no loop. The cost difference is significant and the quality difference is often smaller than people expect.
The practical takeaway is that self-improvement is a lever, not a foundation. You still need solid task design, sharp evaluation, and realistic expectations. Build the loop around a well-defined problem, keep the evaluator honest, and accept that some tasks simply cannot iterate their way to good enough.