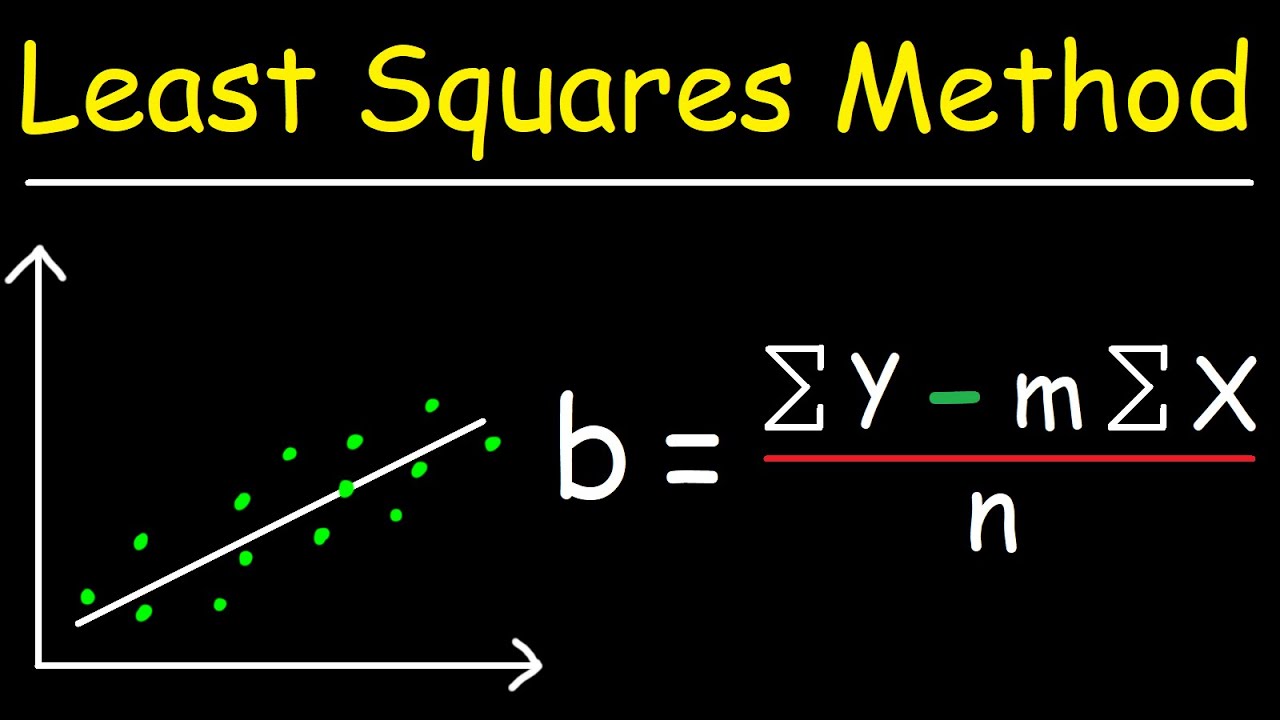
How the math actually works before you code it
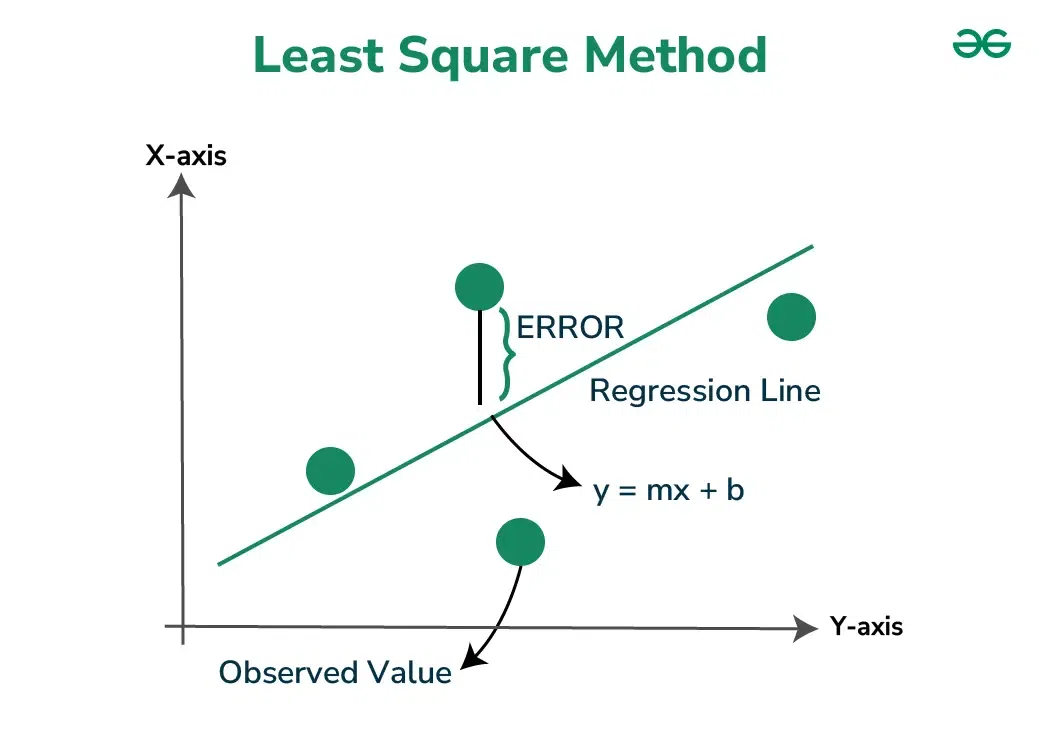
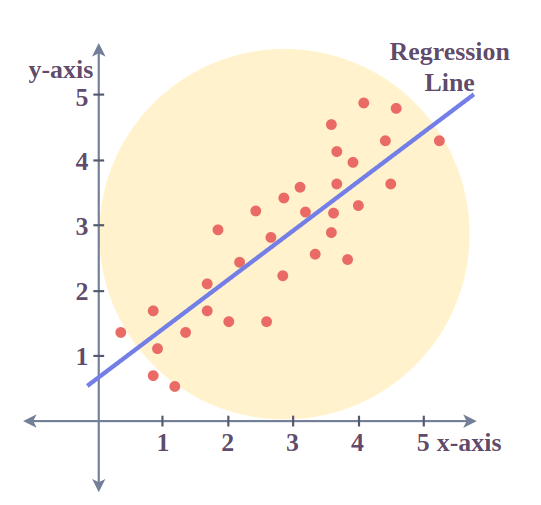
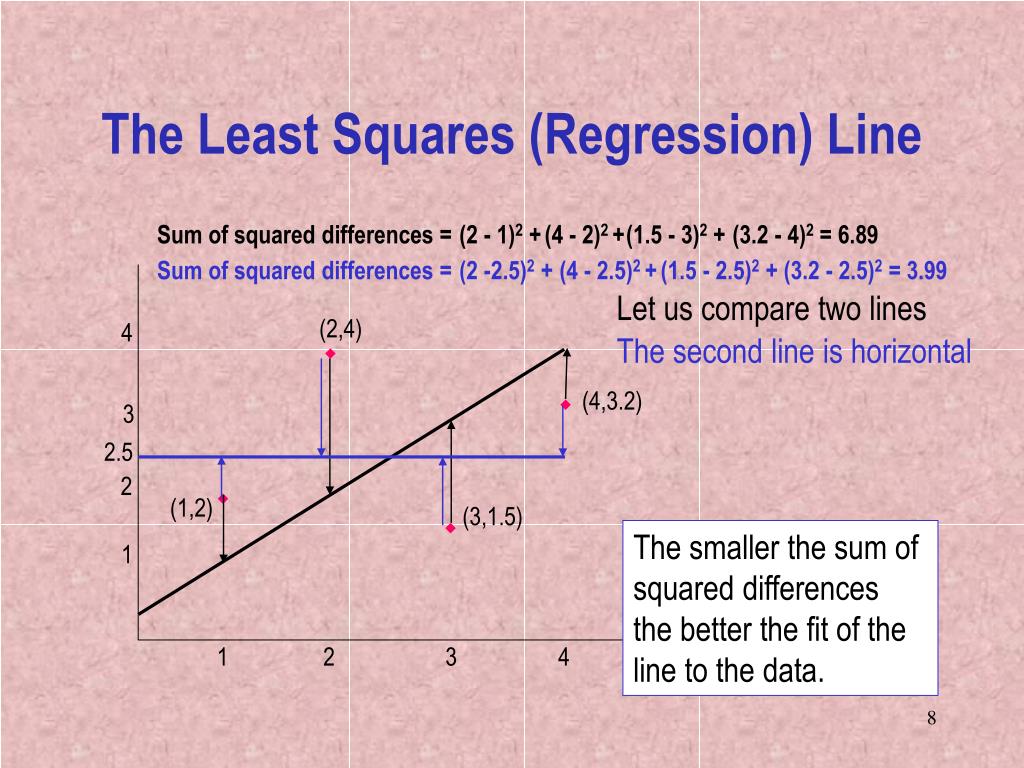
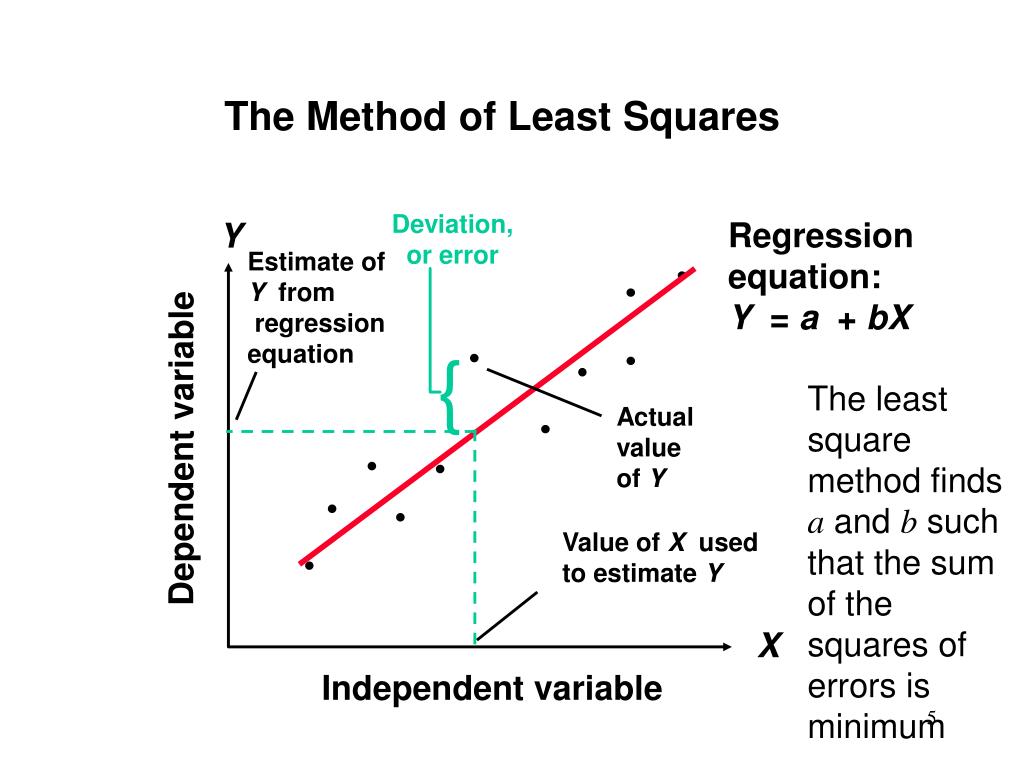
Most people learn least squares by memorizing normal equations, then write code that fails silently when data gets messy. I learned it the hard way when my model suddenly started predicting negative house prices because one outlier had a missing value that silently became zero in my dataset. The core idea is straightforward: you have a bunch of points on a scatter plot and you want a line that tries its best to go through them. Best is defined mathematically as minimizing the sum of squared vertical distances from each point to the line. Squared distance matters because if you just summed raw residuals, positive and negative offsets cancel each other out and you end up with a line in the middle of nowhere instead of a meaningful fit.
Fitting a Least Squares Linear Regression Line
Here is the actual computation, not the tidy textbook version. You need two sums from your data: the sum of x values, the sum of y values, the sum of x times y, and the sum of x squared. From those four numbers you derive slope and intercept. Slope equals n times the sum of xy minus the product of sum of x and sum of y, all divided by n times the sum of x squared minus the square of sum of x. The intercept is the mean of y minus slope times the mean of x. That is it. The whole thing comes down to arithmetic on your dataset. In practice I almost never compute this by hand anymore. I use numpy's polyfit function or sklearn's LinearRegression, both of which give you essentially the same result. The difference is that numpy returns coefficients in descending order of power while sklearn gives you a .coef_ attribute and a .intercept_ attribute. Pick whichever interface your project already uses and stop second guessing yourself over it.
One thing beginners consistently get wrong is assuming that fitting a line means the relationship is actually linear. It does not. A least squares fit will give you a line regardless of whether the underlying relationship is curved, exponential, or completely unrelated. The method does not care. It will happily minimize squared errors for garbage data and hand you a clean R-squared value that looks impressive until you look at the residual plot.
Get the Full Details
When the method breaks and what to do instead
I ran into a real problem once where I was regressing salary against years of experience using data pulled from LinkedIn profiles. The data was heavily right-skewed with a long tail of outliers at the high end. The least squares line was getting dragged upward by a handful of people making two hundred thousand dollars, and the fit looked reasonable overall but was useless for predicting actual salaries in the median range. The residuals showed clear heteroscedasticity: variance increased with predicted value, which violates an assumption the method quietly depends on. The workaround was simple enough. I logged both the dependent and independent variables, re-ran the regression on the transformed data, and then interpreted the coefficients on the original scale using the log transformation properties. This compressed the outlier influence and stabilized the variance. The adjusted R-squared improved from 0.31 to 0.58, and the residual plot finally looked like random noise instead of a fan shape. Another edge case that will trip you up is perfect multicollinearity. If you have two predictor variables that are identical or nearly identical, the matrix inversion inside the least squares calculation becomes numerically unstable. numpy raises a LinAlgError or returns garbage coefficients depending on how close to singular your design matrix is. The fix is usually to remove one of the collinear variables or apply ridge regression, which adds a small penalty term that stabilizes the inversion without fundamentally changing the interpretation.
There is also the matter of leverage points. A single observation with an extreme x value can exert enormous influence on the fitted line without having a large residual. The point sits far away horizontally and the line bends toward it, making the fit look good locally while destroying predictive accuracy elsewhere. Cook's distance is the standard metric for detecting these. Anything above 1 is worth investigating, though there is no universal threshold that applies everywhere. When you have more predictors than observations, ordinary least squares is mathematically undefined because you cannot invert a matrix that is not square. Regularization becomes mandatory here. Lasso regression adds an L1 penalty that drives some coefficients exactly to zero, which also performs variable selection. Ridge regression adds an L2 penalty that shrinks coefficients without eliminating them. Elastic net combines both approaches. These are not alternatives you consider after trying least squares and failing. They are the default when your feature count approaches your sample size.
Practical implementation notes
If you are working in Python, here is the quickest reliable path. Import numpy and use polyfit with deg=1 for a simple line, or use sklearn's LinearRegression for multiple predictors. Both are vectorized and handle the matrix algebra internally. The polyfit route gives you coefficients directly. The sklearn route gives you a fitted object with predict, score, coef_, and intercept_ attributes that integrates cleanly into a pipeline. I usually wrap my regression call in a small validation step that checks the condition number of the design matrix. If it exceeds 10^12, something is wrong: either you have exact multicollinearity, near-perfect multicollinearity, or your data has been improperly standardized. A high condition number means small rounding errors in floating point arithmetic will produce large errors in your coefficients, and your results will be numerically unreliable even though they look perfectly fine on the surface. Standardization matters more than people admit. When predictor variables are on different scales, the least squares solution itself is still mathematically correct, but interpreting coefficients becomes misleading. A one-unit change in a variable measured in millimeters means something entirely different from a one-unit change in a variable measured in kilometers. Scaling variables to zero mean and unit variance makes coefficients comparable and improves numerical stability for any regularization method you might add later.
Another detail that rarely gets mentioned: least squares assumes your errors are normally distributed with constant variance and no autocorrelation. In time series data this assumption is routinely violated. If you run least squares on temporal data without checking for autocorrelated residuals, your standard errors will be biased downward and your confidence intervals will be artificially narrow. Durbin-Watson statistic catches the most common form of this, and the fix involves either adding lagged terms as predictors or switching to a time series model like ARIMA or state space methods. For a pure Least Squares Linear Regression Line on bivariate data without complications, the process from raw data to fitted line usually takes under thirty seconds in a Jupyter notebook. The time spent debugging comes from ignoring diagnostic checks, not from the computation itself. Fit the model, plot the residuals, check the condition number, verify no single point dominates the fit. If all four pass, the result is trustworthy. If any fail, the model is still computed correctly, but its conclusions may not be.