Picking The Right Model For Your Data
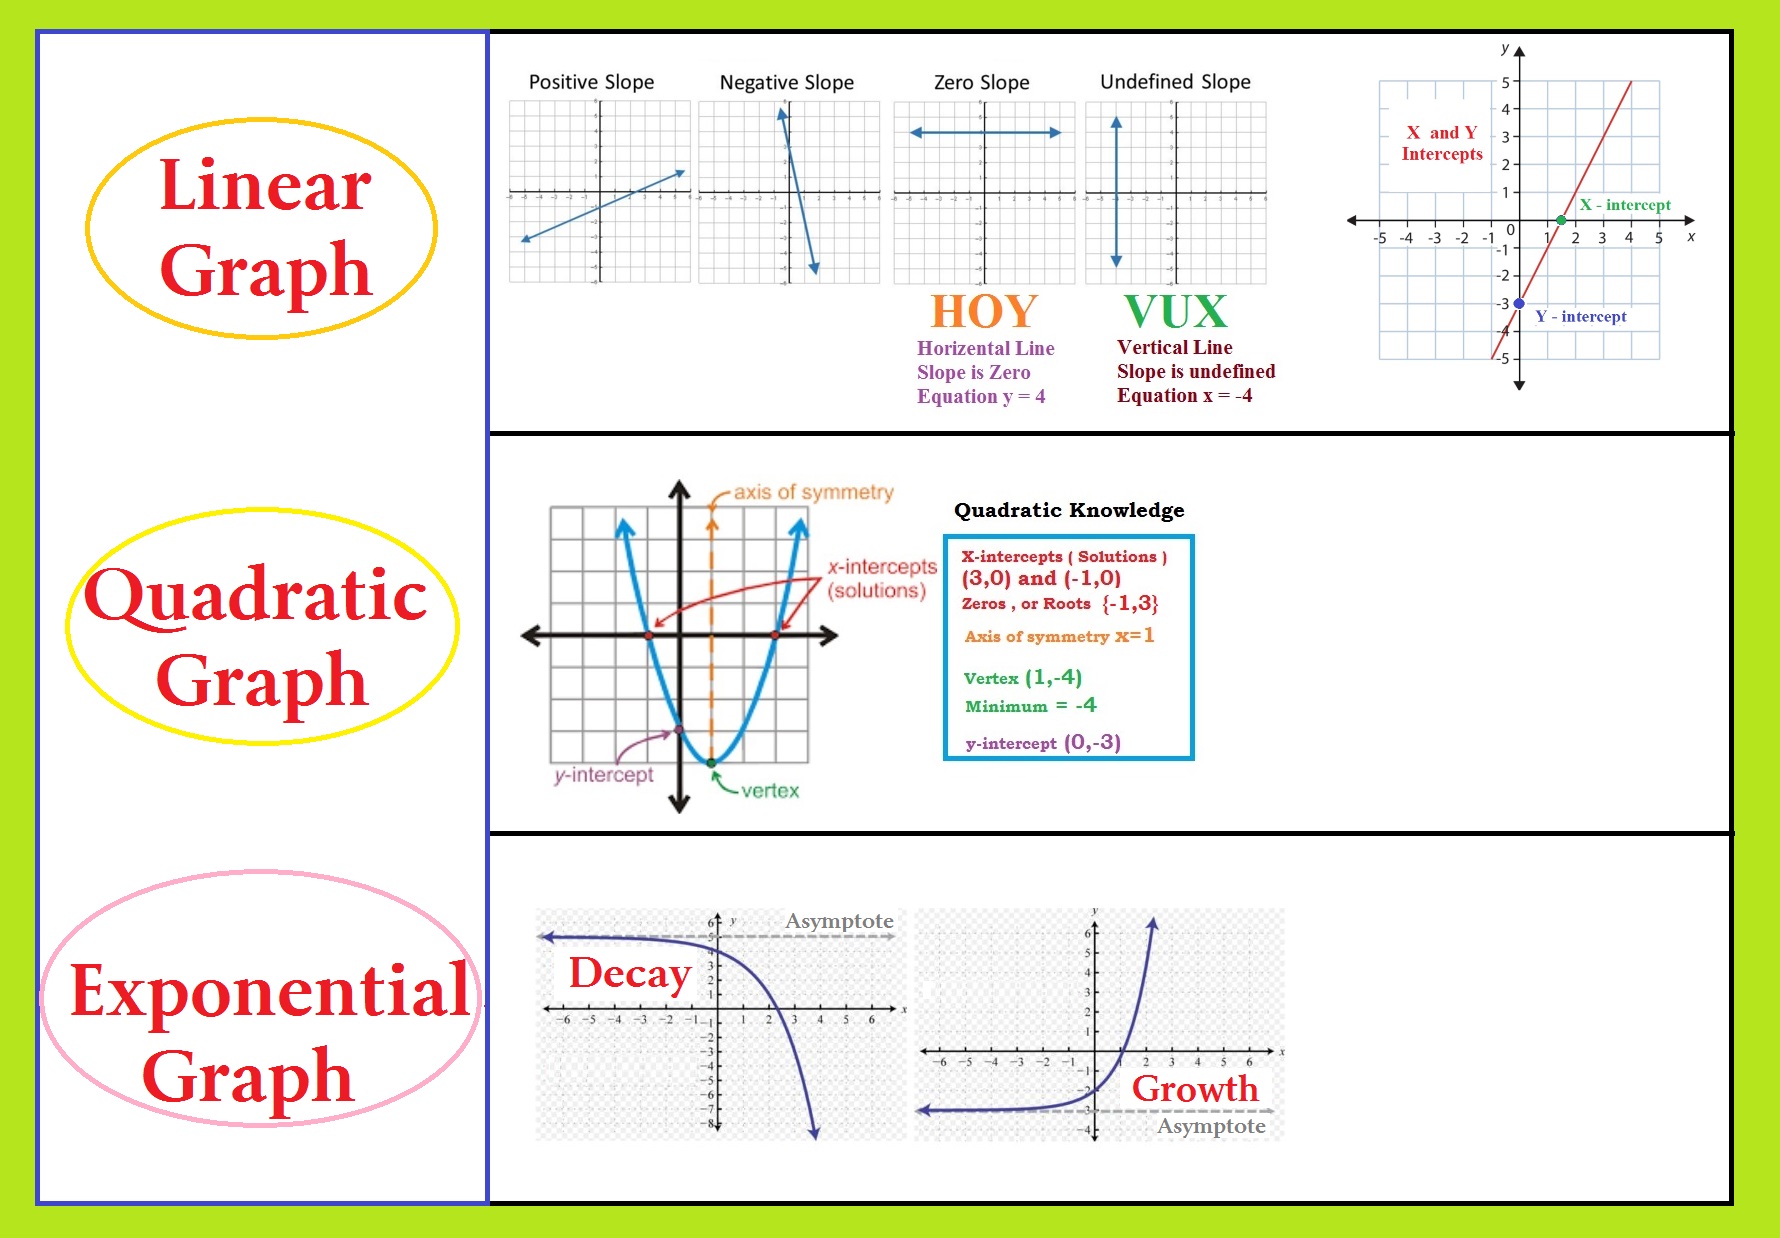
If you're given a set of points and asked which function type fits best, the fastest way to tell is by looking at differences and ratios. A linear relationship means the first differences of y are roughly constant as x increases by equal steps. A quadratic has constant second differences. An exponential has roughly constant ratios between consecutive y-values. That's the quick diagnostic. In practice, nobody works by hand anymore unless the dataset is tiny, so most people run a regression and compare residuals. The math behind each is straightforward, but the pitfalls are where things get messy. Linear functions take the form f(x) = mx + b. The slope m is the rate of change. If m is positive, the function rises steadily. If it's negative, it falls. The intercept b is where the line crosses the y-axis. Fitting a line is just minimizing the sum of squared vertical distances from each point to the line. You can do this with least squares by solving the normal equations, or you can use a built-in calculator function like LinReg on a TI-84 or numpy.polyfit in Python with degree 1. It's fast, it's stable, and it rarely surprises you unless your data is genuinely nonlinear. Quadratic functions are f(x) = ax² + bx + c. They describe acceleration. The vertex sits at x = -b/(2a), and the parabola opens upward if a is positive and downward if a is negative. Fitting a quadratic uses the same least squares principle but now you're solving for three parameters instead of two. The normal equations involve a 3x3 system. On a calculator, that's QuadReg. In code, it's another call to polyfit with degree 2. The main thing to watch is that your x-values shouldn't be wildly spread without centering, because the design matrix can become poorly conditioned and small rounding errors get amplified in the coefficients.
Exponential functions look like f(x) = a · e^(bx) or equivalently f(x) = a · b^x. The key difference from linear and quadratic is that the rate of change is proportional to the current value. This means the function can grow or decay incredibly fast. Fitting one by ordinary least squares directly on the raw y-values is actually the harder problem because the error surface is not convex in the parameters. The standard workaround is to take logarithms of y and fit a line to log(y) versus x. This converts the model into log(y) = log(a) + bx, which is linear in the transformed space. You then exponentiate the intercept to recover a. This log-linear approach works well when the errors are multiplicative and roughly log-normal, but it does change what you're actually minimizing. If your data has additive noise on the original scale, the log transform biases the fit toward smaller values because it shrinks large residuals and expands small ones. I ran into a real case last year where a client gave me sensor readings from a thermal degradation test. The data looked exponential at first glance, so I ran ExpReg and got a clean curve. The residuals plot told a different story though. There was a systematic hump in the middle section, meaning the exponential model was missing something. I switched to a quadratic fit and the residuals flattened out. The underlying process wasn't pure exponential decay. It had a slight inflection from a secondary reaction that kicked in partway through. The lesson was simple: always plot residuals before you commit to a model. A pretty-looking fit with patterned residuals is worse than useless because it gives you false confidence. Here's a less obvious issue with exponentials. When the base is between 0 and 1, you're modeling decay. The function asymptotically approaches zero but never reaches it. In real data, you'll hit measurement floor noise long before the theoretical asymptote. If you include those near-zero values in a log transform, you get negative infinity or NaNs and the whole fit breaks. I worked around this by adding a small constant to all y-values before logging, then adjusting the interpretation of the intercept accordingly. The constant had to be smaller than the smallest nonzero measurement but large enough to avoid numerical issues. It's a fiddly boundary condition that textbook examples never mention.
Quadratics have their own nuisance. When the x-range is wide and the vertex is far outside the data window, the parabola can look almost linear locally. Fitting a quadratic to data that is nearly linear will give you a tiny a coefficient with a large standard error. The model isn't wrong per se, but it's unstable. I learned this the hard way when fitting a calibration curve. The quadratic term was statistically indistinguishable from zero, yet the regression output still reported a coefficient. Dropping back to a linear model made the confidence intervals tighten dramatically. Always check whether the quadratic term is actually significant before using the full model. For quick reference, here's how fitting typically works across tools:
Get the Full Details

- TI-84: STAT CALC LinReg, QuadReg, ExpReg. Input your lists and you get the equation and R² values.
- Python with numpy: numpy.polyfit(x, y, deg) where deg is 1 for linear and 2 for quadratic. For exponential, transform y with np.log and use polyfit on the logged values.
- Python with scipy: scipy.optimize.curve_fit lets you define a custom exponential function and fit it directly without log transformation, which is more accurate when errors are additive.
- Excel: Use the TREND function for linear, the LOGEST function for exponential, or add a trendline and display the equation for a quick visual fit.
R-squared is useful but it's easy to misread. A high R² doesn't mean the model is correct. It only means the model explains a large fraction of the variance in y. You can get a high R² from a polynomial of sufficiently high degree fitted to noisy data, and that's overfitting. Cross-validation or holding out a test set is the actual check. Fit on one portion, predict the other, and see how the error behaves. If the training error is tiny and the test error is huge, your model is memorizing noise. Another thing beginners miss: the domain matters. A linear model fitted to data between x = 0 and x = 10 is only trustworthy in that range. Extrapolating to x = 50 with a linear model assumes the slope never changes, which is rarely true for physical or biological processes. Quadratic extrapolation is even riskier because the parabola eventually turns around. Exponential extrapolation can explode or collapse depending on the sign of b. I once saw a forecast model project exponential growth three years into the future and produce a number that was physically impossible for the system being modeled. The model was mathematically sound within the observed range. The assumption of continued exponential growth was the mistake. When you're choosing between these three function types and the data is ambiguous, look at the residual structure. Linear residuals should show no pattern. Quadratic residuals should also be random if the quadratic term captures the curvature. If residuals from a linear fit show a clear U-shape, that's evidence the true relationship is curved and a quadratic might be better. If residuals from a quadratic fit show an exponential-like curve, you may need the exponential model instead. Sometimes none of the three are adequate and you need something else entirely, like a power law or a logarithmic model.
The one area where linear models dominate is interpretability. The slope has a direct meaning: for each unit increase in x, y changes by m units. In a quadratic, the slope itself changes with x, so the effect is not constant. In an exponential, the percentage change per unit x is constant, which is intuitive for growth and decay but less intuitive for absolute change. If someone asks you what a coefficient means, the linear model gives you the clearest answer. For homework or exam problems, the typical workflow is: plot the scatter, compute first differences, compute second differences if needed, check ratios, pick the model that gives the most constant measure, then find the equation using the appropriate method. In real work, you skip the hand calculations and let the software do the regression, but you still do the residual check because software will happily fit any model you ask for, even the wrong one.