Why Your Matrix Keeps Failing Rank Checks
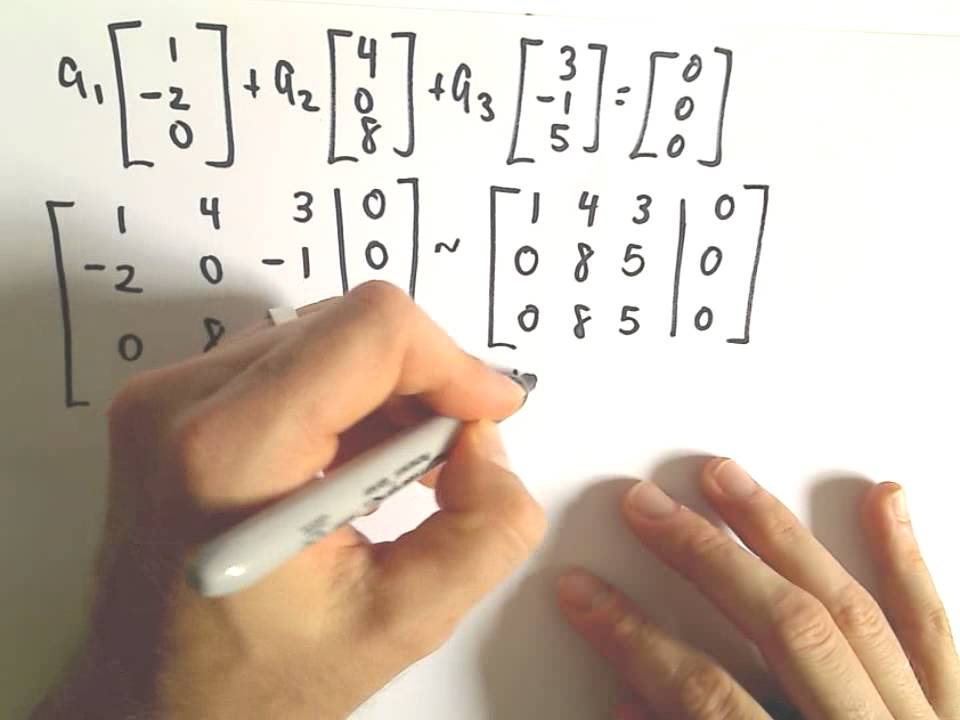
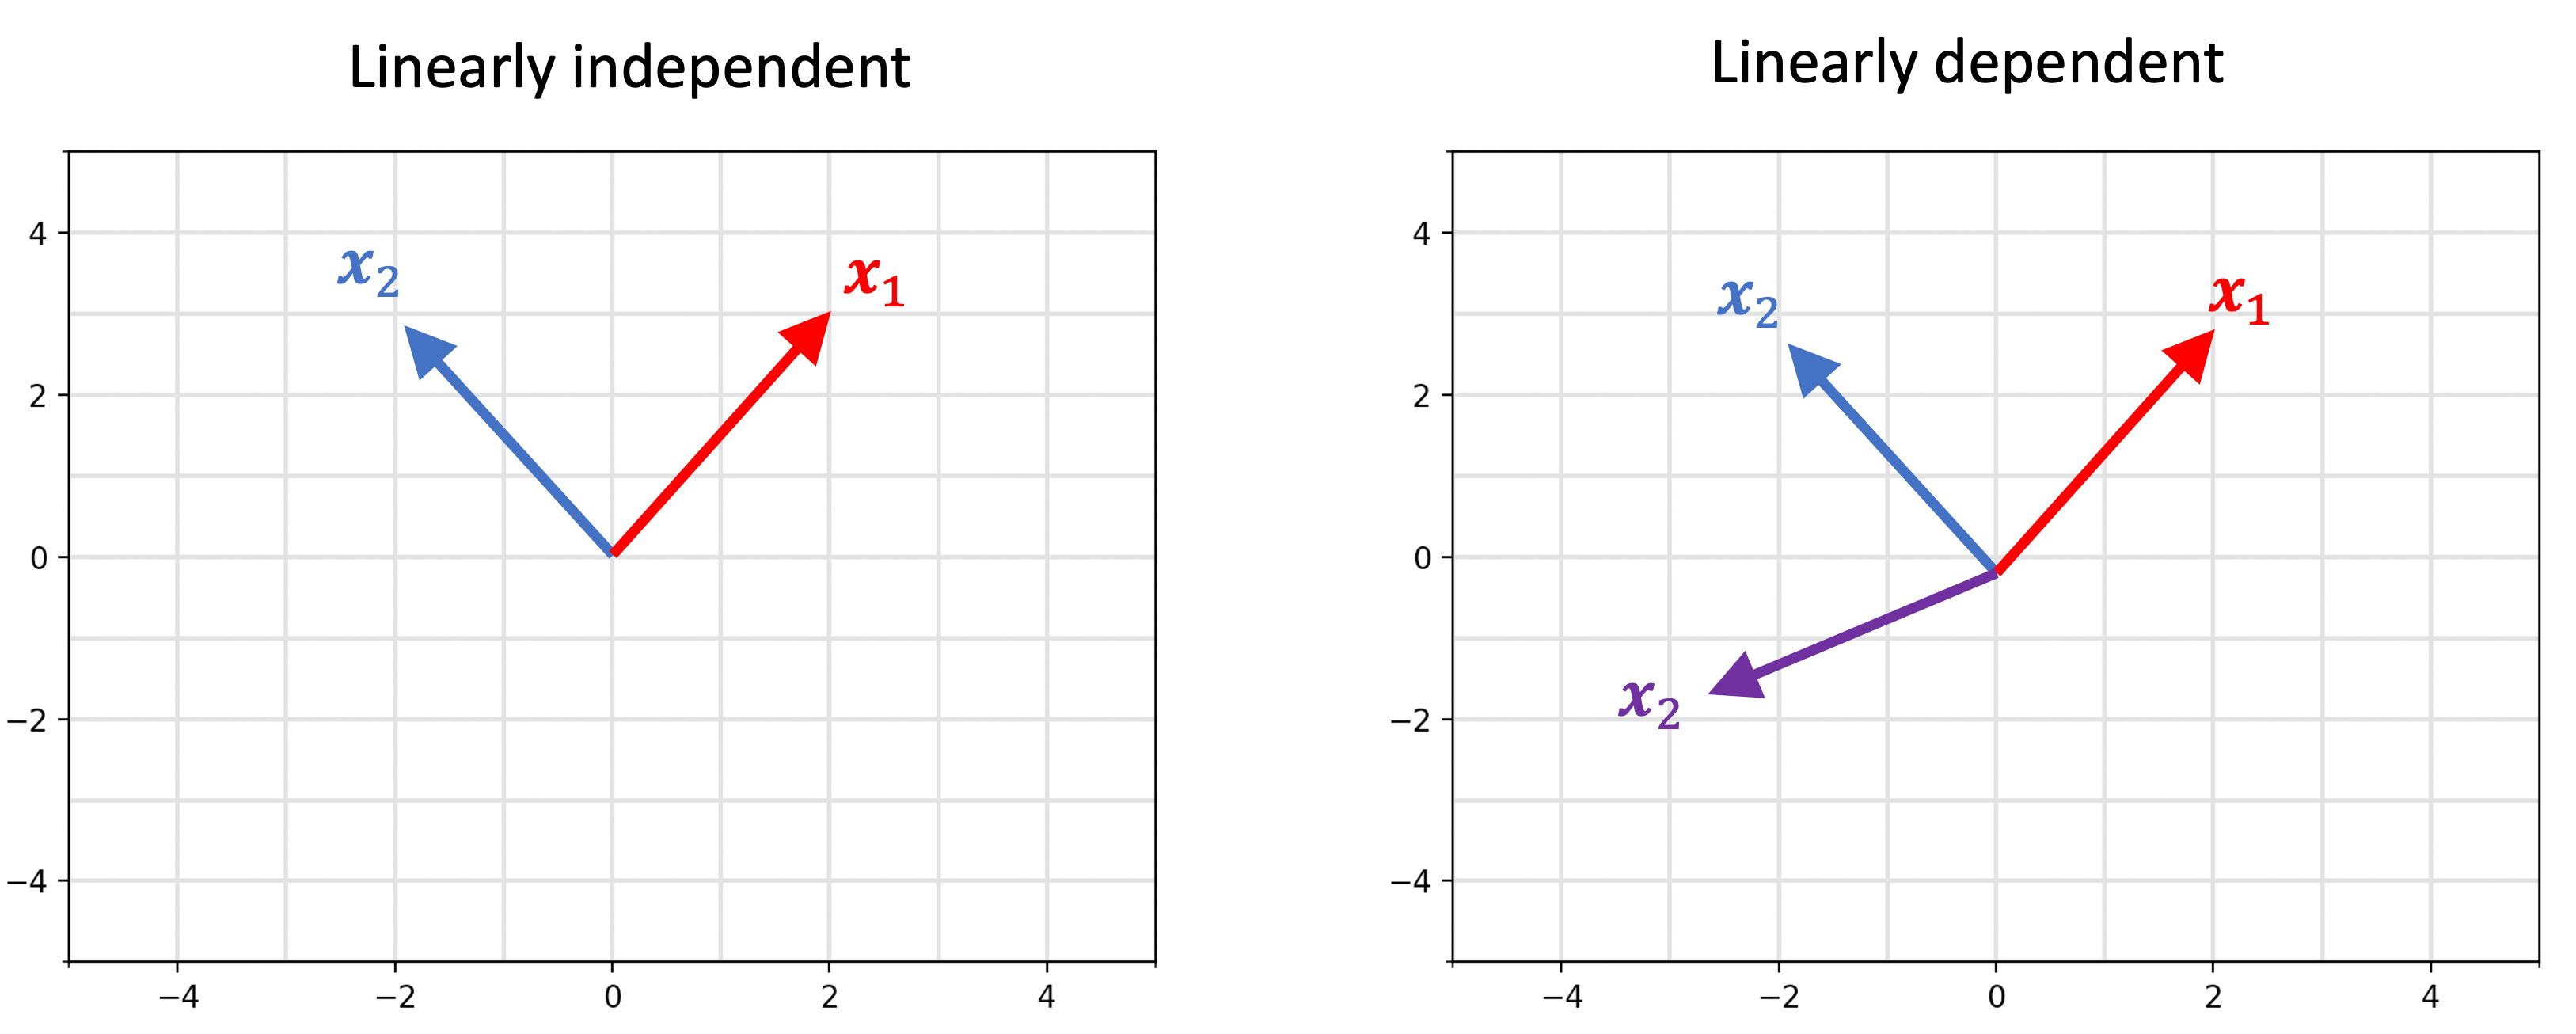
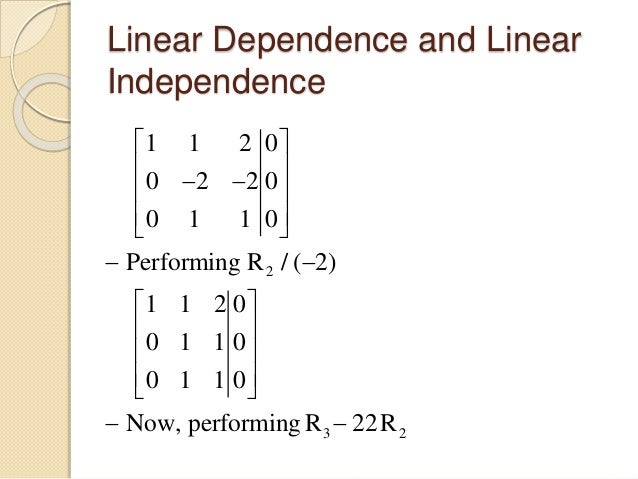
I was debugging a sensor fusion pipeline last year where three accelerometer readings produced a singular covariance matrix, and it took me four hours to realize two of the axes were collinear because the platform had shared mounting vibration. That's what linear dependence does quietly. You put vectors into an algorithm expecting full rank and watch it crash or return garbage eigenvalues. Linearly Dependent And Linearly Independent describes whether any vector in a set can be written as a weighted combination of the others. If yes, they are dependent. If no, they are independent. That is the whole definition, and it is also almost never how people actually use it in practice. The method I reach for first is row reduction to echelon form. Take your vectors as columns in a matrix, reduce it, and count the pivot positions. The number of pivots equals the rank, and any column without a pivot is a linear combination of the ones before it. For a 3x3 matrix on a laptop, this takes about ten seconds by hand or three seconds in NumPy. A singular value decomposition is more reliable when your numbers are noisy, which is most real-world cases, and it runs in roughly the same time on modern hardware.
One counter-intuitive thing nobody teaches: a set of vectors can be linearly independent in R^n only if the count of vectors is at most n. Four vectors in R^3 are always dependent, regardless of how carefully you constructed them. Another pitfall is floating-point near-dependence. Two columns might look independent numerically but have a condition number in the millions, which means your downstream solver will amplify rounding errors badly. I check the ratio between the smallest and largest singular values. If it drops below 1e-6, I treat the system as effectively rank-deficient and drop the weakest column rather than pushing forward.
How to check Linearly Dependent And Linearly Independent in a real dataset
Build the matrix from your feature vectors, run a rank-revealing QR or SVD, and inspect the pivot tolerance. The default tolerance in most libraries is machine epsilon times the largest singular value, which is usually fine but can be too aggressive for ill-conditioned data. I set mine to 1e-10 explicitly instead of trusting the default. If a column gets dropped, note which original variable it corresponded to and decide whether that variable is genuinely redundant or just correlated due to a collection artifact. In my sensor case, the redundant axis was real hardware coupling, so I removed it from the pipeline entirely and recalibrated the mount rather than trying to regularize around it. This approach cuts my validation time from a couple of hours down to maybe fifteen minutes per dataset. The downside is that rank determination is sensitive to scaling. If your vectors come from different measurement ranges, normalize them first or the rank test will be biased toward the larger-scale features. There is no perfect threshold, and you will occasionally need to look at the actual singular value spectrum rather than relying on a single cutoff number.