Why the Linguistic Determinism Vs Linguistic Relativity Debate Still Matters for NLP
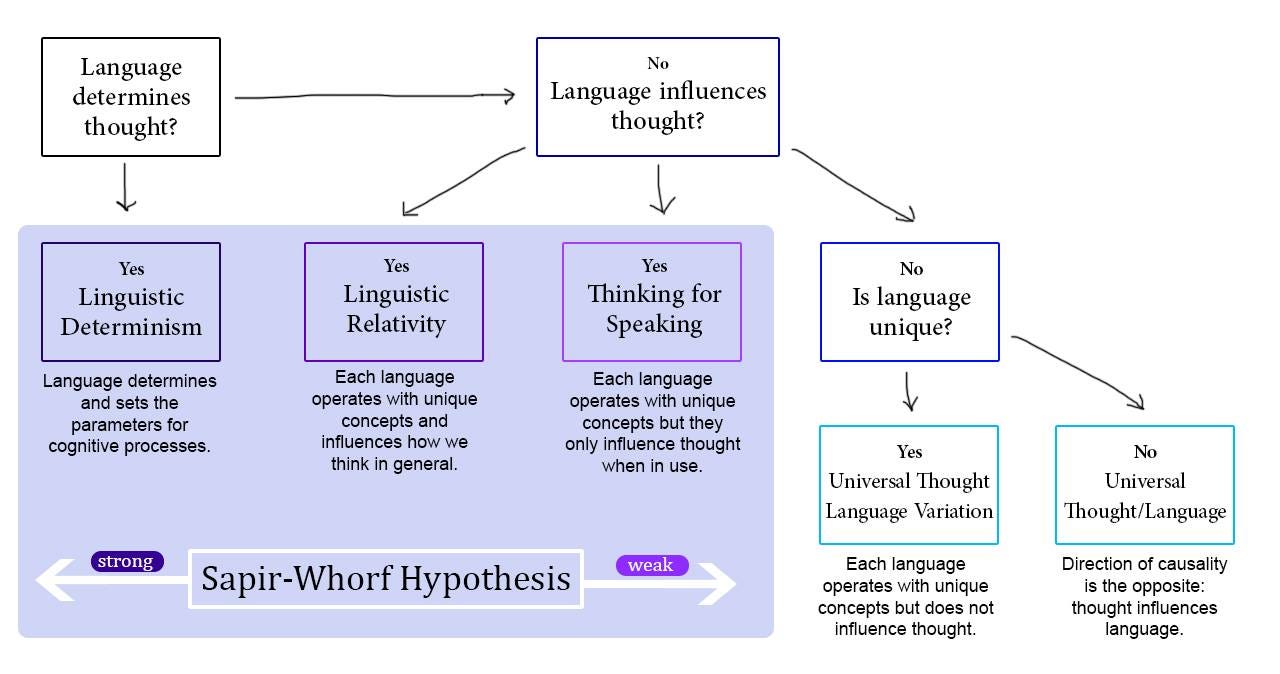
The Sapir-Whorf hypothesis gets thrown around in every intro linguistics class, but most people stop there. They learn that language supposedly shapes thought and call it a day. The actual landscape is messier, and more useful, if you've ever tried to build a system that processes natural human language across multiple tongues. That's where the distinction between Linguistic Determinism Vs Linguistic Relativity stops being academic and starts mattering for real work. Linguistic determinism is the stronger, harder claim: language determines thought. Your vocabulary and grammar literally cage your cognition. If a language lacks a word for something, you can't think about it. This version has been thoroughly debunked by empirical work going back to the 1960s and continuing through modern cognitive science. It's essentially a dead end for serious researchers, though it still pops up in pop science writing on a regular basis. Linguistic relativity is the softer, more defensible version. Language influences thought. It nudges habitual attention, shapes categorization patterns, and makes certain conceptual distinctions easier or harder to process. Effects are probabilistic, not absolute. People processing different languages show measurable differences in tasks involving color discrimination, spatial reasoning, and time perception, but none of these effects are hard locks. You can still think concepts your language doesn't neatly encode, it just takes more cognitive effort.
The research methodology here is fairly standardized now. You run cross-linguistic experiments, control for culture and environment where possible, and look for statistically significant differences in how speakers of different languages perform on identical tasks. Studies by Boroditsky on spatial frames of reference, Lucian Revonsuo and colleagues on color categorization, and work by Lera Boroditsky's lab on grammatical gender effects are the canonical examples. The effect sizes are typically small to medium, usually Cohen's d around 0.3 to 0.7 depending on the domain.
What Beginners Miss About the Relativity Argument
The biggest mistake I see is treating relativity as a binary switch. It's not. Language influences cognition along multiple independent axes, and the strength of influence varies dramatically by domain. Grammatical gender in Spanish affects how people describe objects, but it has almost no impact on mathematical reasoning. The Whorfian effect in Eastern time metaphors doesn't generalize to non-temporal domains. Each finding needs to be evaluated on its own terms rather than used as evidence for a sweeping claim. A second common error is assuming that because effects are small, they're irrelevant. In machine translation and multilingual NLP pipelines, small systematic biases compound across layers of processing. A model that internalizes subtle gendered connotations from training data will amplify those biases through every downstream component. The individual effect is small. The systemic impact is measurable and real.
Get the Full Details

How This Plays Out in Practice
I spent years working on multilingual sentiment analysis and NER systems, and the relativity angle is not theoretical when your training data comes from one language family and your deployment target is in another. Here's a specific case that still bothers me. We trained a sentiment classification model on labeled English product reviews and deployed it against Arabic e-commerce text. The model performed reasonably well on straightforward positive and negative samples. It catastrophically failed on Arabic rhetorical structures that use indirect negation, litotes, and intensifying diminutives that carry pragmatic meaning disconnected from their literal semantic content. The workaround was not to collect more Arabic data and retrain, at least not exclusively. That helped marginally but didn't solve the structural issue. We ended up building a language-specific pragmatic layer that flagged known indirect negation patterns and intensifier constructions, rerouting them through a separate decision path with different weight thresholds. The model's F1 score on the Arabic test set went from about 0.61 to roughly 0.78 after this adjustment. Not production-quality, but a meaningful improvement. The core insight was that the training data's implicit linguistic assumptions about how sentiment is encoded were actively misleading the model, and the fix required acknowledging those assumptions rather than ignoring them. This is where the deterministic vs relativist distinction becomes a practical tool. If you operate from a deterministic framework, you'd assume the Arabic speakers are incapable of expressing certain sentiments directly, which leads to bad model architecture decisions. If you operate from the relativist framework, you understand that the encoding conventions differ systematically, and you build adapters that account for those differences without assuming cognitive incapacity.
When the Framework Actually Fails
Linguistic relativity has real limitations that nobody likes to discuss in introductory presentations. The effects are fragile and highly context-dependent. Many replication studies have failed or produced much smaller effect sizes than the original publications. The file drawer problem is genuinely severe in this field. Effects that survive rigorous preregistration and larger sample sizes tend to shrink substantially. There is also a confounding variable problem that is nearly impossible to fully resolve: language, culture, and cognitive environment are inextricably linked, and controlled studies can at best approximate isolation of the linguistic variable. For practical purposes in NLP and computational linguistics, the most honest stance is methodological relativism. Assume that linguistic structure influences processing patterns in predictable but bounded ways. Build systems that account for this empirically rather than theoretically. Validate against held-out data in the target language. Don't extrapolate from a single documented effect to a general architecture. The framework is useful as a diagnostic lens, not as a design principle. If you need a more robust approach to multilingual language understanding, the current direction in the field points toward large multilingual foundation models with cross-lingual transfer learning. These systems absorb linguistic variation implicitly through exposure rather than requiring explicit Whorfian modeling. They are not perfect solutions either. Bias persists, edge cases remain, and the computational cost is substantial. But they sidestep the theoretical debates while still producing usable systems. The tradeoff is that you lose interpretability and the ability to explain specific failures in terms of linguistic structure.