
Getting Your Head Around Linkage
Linkage just means two genetic variants tend to be inherited together because they live close to each other on the same chromosome. During meiosis, recombination can shuffle them apart, but the closer they are, the less likely that shuffling actually happens. If you're doing any kind of association study, this matters immediately, and I've lost count of the times someone's GWAS signal traced back to a perfectly fine tag SNP just because the recombination rate in that region was unusually low. Linkage disequilibrium (LD) quantifies exactly how non-random that association is. You'll see it as D', r², and sometimes raw D, each capturing something slightly different. D' measures whether historical recombination has ever separated two alleles, hitting 1 when there's no evidence of a recombination event between them. r² tells you how well one variant predicts the other, which is why it matters more for imputation and tag SNP selection. D is the raw covariance, but it depends heavily on allele frequencies, so nobody really uses it directly except for the math underneath everything else. The practical takeaway is that r² and D' will disagree often, and assuming they convey the same information gets people into trouble. A block can show D' near 1 while r² sits at 0.3, meaning the alleles are inherited together but neither variant is a strong predictor of the other. That usually happens when allele frequencies are very different between the two sites.
Practical Linkage And Linkage Disequilibrium Calculations
To compute LD from a VCF, PLINK is still the default for most people. The command structure is straightforward: plink2 --vcf mydata.vcf.gz --r2 --ld-window 99999 --ld-window-r2 0 --out my_ld_matrix That flag for window size in base pairs just tells PLINK how far out to look for correlations. Setting it to 99999 effectively means no hard distance cap, which is usually what you want when you're building a full LD matrix. The --ld-window-r2 flag controls whether variants below a certain r² threshold get dropped from the output. Most people skip it entirely because they want the whole picture.
If you're working with large biobank-scale data, running that single PLINK command will eat through available memory. I've had it spike to 120GB on a dataset with 500,000 samples. The workaround is to use the --memory flag to set an explicit ceiling and let PLINK chunk the computation. It takes longer, but it won't crash your server in the middle of the night.
Get the Full Details
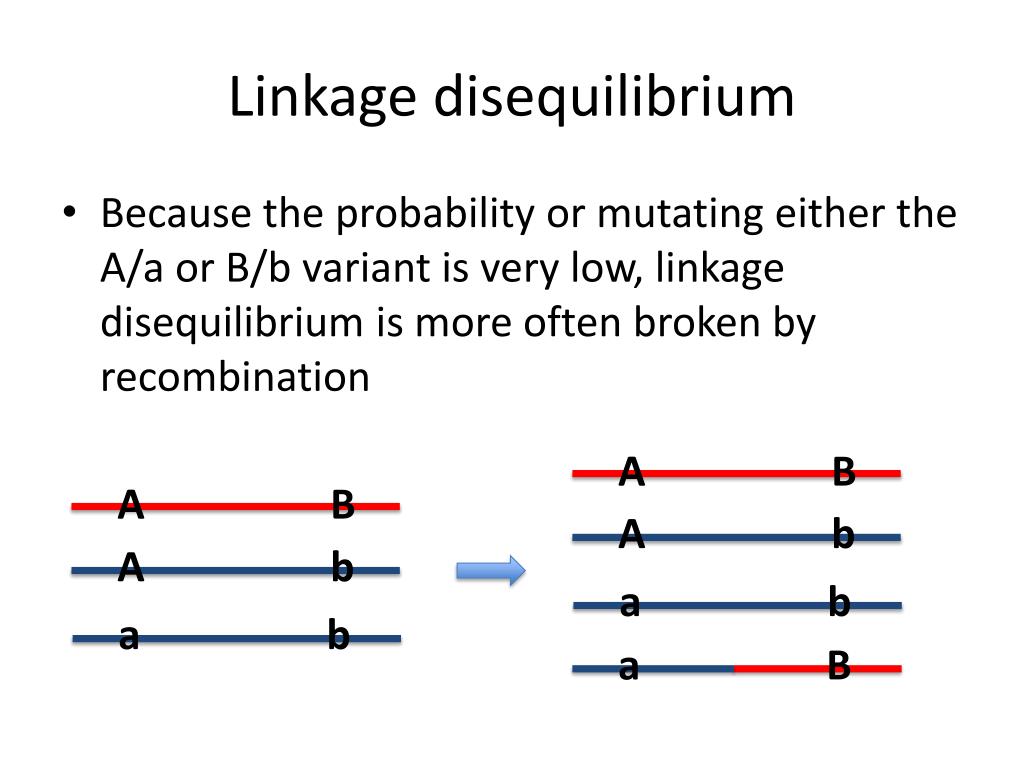
Why the Definition of LD Blocks Changes Everything
The classic Gabriel method defines an LD block based on confidence intervals around D', which creates hard boundaries that are easy to visualize but often biologically meaningless. A variant at the edge of one block might sit in perfect LD with a variant five positions away in the next block, which is annoying when you're doing fine-mapping. The solid spine of LD method from Shimamura et al. is more practical for many applications because it uses pairwise r² thresholds directly rather than relying on D' confidence intervals. You set an r² cutoff, like 0.8, and the algorithm chains together variants that exceed that threshold. The result is usually fewer, larger blocks that overlap with known recombination hotspots better than the Gabriel definition does. Here's the thing most guides don't mention: LD decay is not uniform across the genome or across populations. In European populations, r² typically drops below 0.2 within 10 to 50 kilobases depending on the region. In African populations, which have greater genetic diversity and more historical recombination events, that drop happens much faster, often within a few kilobases. If you're using a European LD reference panel for a variant calling pipeline on African ancestry samples, your imputation accuracy will suffer noticeably, and you'll blame your sequencer when the real problem is the reference panel mismatch.
A Specific Problem I Encountered
Last year I was working with a dense genotyping array that had been used in a previous study without issues, and when I tried to use it for imputation into a new cohort, the imputation quality scores tanked in a region I'd expected to be straightforward. The variants were well-covered on the array, the MAF was reasonable, and the reference panel had good coverage for that locus. Nothing in the QC plots looked wrong. It turned out the genotyping batch had a subtle cluster separation problem in that specific genomic region, probably due to a nearby structural variant that was affecting probe binding. The variants passed all standard QC filters because the call rate and HWE p-values looked fine at the aggregate level. But the LD structure was quietly broken. The array was producing mostly heterozygous calls where the reference panel expected a particular haplotype, so the imputation algorithm couldn't anchor the local LD pattern correctly. The fix was to pull the raw intensity data, call the genotypes de novo with a different clustering algorithm, and then re-run the imputation. It added about two days of work to the pipeline, but it was faster than troubleshooting why the imputed dosage values made no biological sense. After that, I started running local cluster QC metrics by genomic region instead of just global call rates, which catches this kind of thing early.
Counter-Intuitive Things Beginners Miss
First, high LD does not mean a variant is causal. It means the variant is correlated with the causal one. This distinction is especially important in regions of extended LD, like the MHC locus, where the correlation spans hundreds of kilobases and multiple genes. A lead SNP from an association study in that region could be linked to any of a dozen functional variants. Treating the lead SNP as the answer without finer mapping is just expensive coincidence hunting. Second, LD between two variants can exist even when they are far apart if there is population structure involved. That's the difference between true linkage, which is a physical phenomenon, and linkage disequilibrium caused by admixture or stratification, which is a demographic artifact. If you correct for population stratification using principal components and the LD between two distantly located variants disappears, it was never real LD to begin with. You're just measuring shared ancestry, not recombination history.

When LD-Based Methods Fail Completely
LD-based imputation and tag SNP selection both break down in populations that are underrepresented in reference panels. The TOPMed reference panel is much better than 1000 Genomes for diverse populations, but it still has gaps, especially for Indigenous American and some Oceanic populations. If you try to impute variants with MAF below 1 percent in those groups using any existing panel, the accuracy drops sharply, and no amount of LD pruning will fix it. Another failure mode is in regions with recent structural variation. Inversions suppress recombination locally, which creates long-range LD that looks like a single haplotype block but actually contains rearranged sequences. Standard imputation pipelines don't handle inversions well because the reference haplotypes don't reflect the inverted arrangement. You'll get decent imputation statistics, but the phased haplotypes will be wrong, and downstream analyses like polygenic risk scores built on top of that will inherit the errors silently. For structural variants, the workaround is to use a pipeline specifically designed to call and phase structural variants from long-read data or from specialized short-read tools like SVIM or Sniffles. Short-read imputation should never be your first assumption when the signal looks too clean across an unusually large region.
Practical Tag SNP Selection Strategy
If you're designing a custom genotyping array or selecting tag SNPs from a larger set, the goal is to capture the maximum amount of variation with the minimum number of markers. PLINK can do this directly: plink2 --vcf mydata.vcf.gz --indep-pairwise 50kb 5 0.2 --out tags The 50kb window defines how far the algorithm looks for correlated SNPs. The step size of 5 means it moves along the genome in increments of 5 SNPs rather than checking every possible combination. The r² threshold of 0.2 means any SNP with r² above 0.2 to a retained tag SNP gets filtered out. The result is a set of tag SNPs that captures common variation reasonably well in the population you used to build it.
The catch is that these tags are population-specific. A set selected from a European sample will capture European LD structure efficiently but will perform poorly in other populations. The number of tag SNPs needed increases substantially in African populations because the shorter LD blocks mean more independent haplotypes to represent. If budget is a constraint, you need to decide upfront whether you're optimizing for one population or building a cross-population panel, and the second option requires significantly more markers.
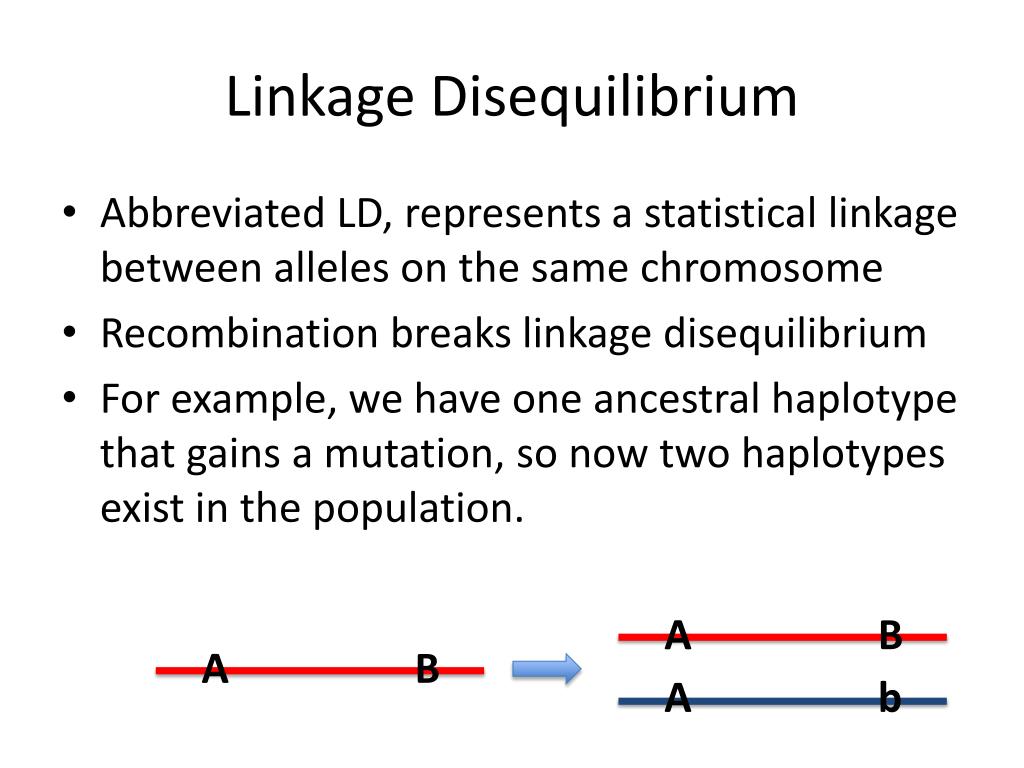
Reading LD Plots Without Misinterpreting Them
LD heatmaps are everywhere in the literature, and they look informative until you realize most people read them wrong. The color scale usually represents r², but some software defaults to D'. These produce very different visual patterns. A D' heatmap will show large red blocks across regions where recombination has occurred but allele frequencies happen to align in a way that preserves the maximal possible D'. An r² heatmap will show those same regions fading to white because the predictive power is low even when the inheritance pattern is non-random. Always check what metric the figure legend specifies. If it doesn't say, assume it's r², because that's the more conservative and more commonly used standard in contemporary papers. If you're generating your own plots, LocusZoom is the most widely used tool, and it defaults to r² for the color scale. It also lets you overlay functional annotations, recombination rate maps, and gene boundaries, which saves time compared to stitching together multiple tools.
A Final Note on Sample Size
LD estimates are sample-size-dependent. With small samples, the sampling variance inflates, and you'll see spurious LD between unlinked variants purely by chance. The rule of thumb is that you need at least 100 samples per population branch for stable r² estimates, though anything below 500 samples starts showing noticeable noise in the tail of the distribution. If your effective sample size after quality filtering drops below 200, treat any r² value above 0.8 with skepticism unless it's been replicated in an independent cohort.


