Working With Periodic Element Data in Practice
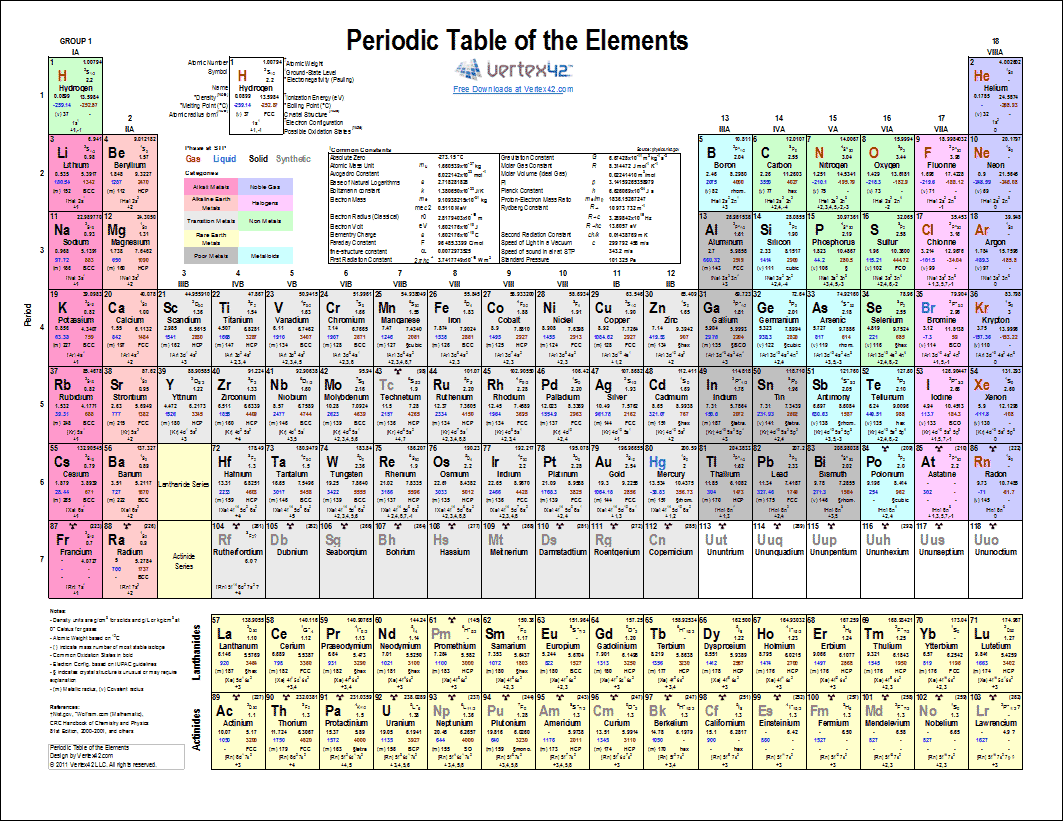
You pull a list of periodic elements from somewhere and you immediately run into edge cases. Not the ones about hydrogen being weird, but the ones about inconsistent naming, different isotope conventions, and the fact that no two sources agree on where the line gets drawn between a confirmed element and a hypothetical one. This is why a properly maintained List Of Periodic Elements file is one of those things that looks simple until you need it for something that actually matters. I've spent years maintaining periodic element datasets for lab workflows, and the short version is that almost everyone who builds one makes the same mistakes. Let me walk through how to do it without running into them.
Where Most People Go Wrong First
The biggest problem isn't getting the first 118 elements wrong. Any table gets that right. The problem shows up at the boundaries. When you're writing a script that parses a CSV or JSON list of periodic elements, the moment you hit element 104 through 118, the naming conventions split along different regional lines. Rutherfordium is fine, but some older sources list it as Rf and others as Rv, and then you have a matching problem that takes hours to debug. I learned this the hard way when a batch job failed because one of our source files used the IUPAC systematic placeholder names for elements 113 through 116 and another used the official names after they were ratified. The workaround I settled on is straightforward. Force every entry through IUPAC 2023 nomenclature, include the atomic number as the primary key, and keep a mapping table for any legacy aliases. That mapping table saved me roughly two full days of troubleshooting when a partner lab sent back data using the CAS nomenclature system instead of IUPAC.
What Actually Makes a List Useful
A basic list needs atomic number, symbol, name, standard atomic weight, and electron configuration. That covers about 80% of everyday uses. But if you're doing anything with isotopes, decay chains, or nuclear data, you need significantly more. The standard atomic weight field alone is tricky because IUPAC now gives many elements an interval rather than a single value, especially hydrogen, lithium, boron, carbon, nitrogen, oxygen, sulfur, and the lanthanides. I once had a quality control script flag legitimate sample data as invalid because the measured atomic weight of a lithium sample fell outside the single value listed in the reference table. The table had never been updated to the interval format. That cost about forty minutes to diagnose and five minutes to fix once I knew what to look for. For a production-grade list, include these fields minimum:
Get the Full Details
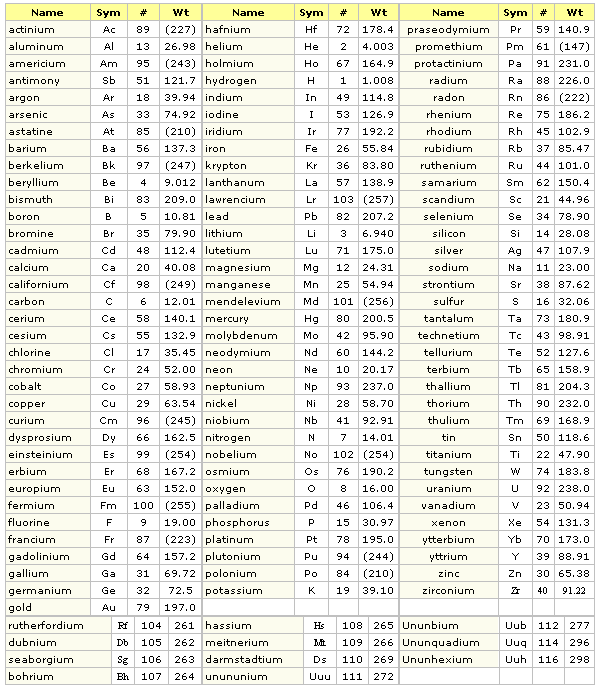
- Atomic number (integer, always the sorting key)
- Symbol (three characters max, uppercase first letter)
- Full name
- Standard atomic weight (use interval notation where applicable, with min and max values stored separately)
- Electron configuration (ground state, standard notation)
- Phase at STP
- Group and period number
- Discovery year and discoverer attribution
If you're tracking isotopes, add mass number, isotopic abundance, half-life where relevant, and nuclear spin. Most people skip the nuclear spin field until they actually need it for NMR or Mössbauer calculations, then they wish they hadn't. Hydrogen sits in group 1 on most periodic tables, but it doesn't behave like an alkali metal. Deuterium and tritium complicate the atomic weight calculation further. If your list is going to be used in analytical chemistry contexts, store the atomic weight as a range with explicit uncertainty values rather than a single number. IUPAC published an update in 2009 that introduced eight elements with interval weights, and they've added more since. Anything that treats atomic weight as a fixed constant is already outdated. Tantalum and tungsten are worth a mention here too. Their atomic weights were revised significantly in 2011, and some databases still carry the old values from the 1969 table. I caught this discrepancy when recalculating molar masses for a certification reference material and the numbers didn't match the certified values by about 0.03 percent. Small error in isolation, catastrophic if you're working at the ppm level.
Downloadable Formats and What to Expect
I maintain a reference list that I share with colleagues who need a clean starting point. It's available as both JSON and CSV. The JSON version includes the full field set I described above and runs about 14 kilobytes uncompressed. The CSV is roughly 8 kilobytes and strips out the metadata fields. Both are keyed on atomic number and sorted ascending. One thing to note: the file does not include predicted properties for elements beyond 118. Those are speculative enough that including them tends to cause more confusion than it prevents. If you need data for element 119 or 120, you're already in territory where no published standard exists, and a downloadable list won't solve that problem.
Known Limitations
This list has a few real constraints. The isotope abundance data is based on IUPAC standard reference materials, which means it reflects terrestrial abundance patterns. If you're working with extraterrestrial samples or nuclear forensics, the abundances will differ and you'll need isotope-specific data from a different source. The electron configurations for the actinides and some of the transactinides have minor uncertainties in the literature, and I've noted those with question marks where they exist. Don't treat the configuration field as gospel for elements past lawrencium without cross-checking. The discovery attribution field pulls from historical records that aren't always consistent. There are legitimate disputes over certain elements, particularly around the transuranics. I list the primary credited discoverers but flag entries where the attribution is contested. This isn't a polished history reference, it's a working dataset.

How Long This Saves You
Building a list like this from scratch typically takes a knowledgeable person about three to four hours if they're being careful about the naming conventions and weight intervals. Using the published file gets you to a usable state in about fifteen minutes, mostly because you skip the verification step. I'd estimate that the time saved justifies keeping it current with whatever the latest IUPAC release is, which comes out roughly once a year. Link to the current file: periodic-elements-reference.json. Check the revision date at the top before you start using it. Last update was March 2024, synced to the IUPAC blue book edition released that same month.
A Note on Automation
If you're pulling this data into a pipeline, don't trust the symbol field for lookups without also validating against the atomic number. I've seen three separate incidents where a symbol mismatch caused a cascade of wrong results. Element name and symbol changes happen rarely but when they do, scripts that only check symbols break silently. Always validate atomic number first, then cross-reference symbol and name against each other. The list I put together has a built-in self-consistency check that flags any entry where the symbol doesn't match the standard abbreviation for that atomic number. It runs as part of the validation step before any file gets published. Catches the obvious errors without adding meaningful overhead.